 Text to video
Tool
Seedance 2.5 Draft Mode Arrives in ComfyUIDraft mode previews a Seedance 2.5 clip at 480p and renders the 1080p final from the same draft. ComfyUI adds a Draft model option, a Draft to Final node and three templates.
API-Only
ComfyUI ecosystem updates — open-source model releases, custom nodes, workflows, and tools for image, video, and audio generation.
Text to videoDraft mode previews a Seedance 2.5 clip at 480p and renders the 1080p final from the same draft. ComfyUI adds a Draft model option, a Draft to Final node and three templates.
API-Only
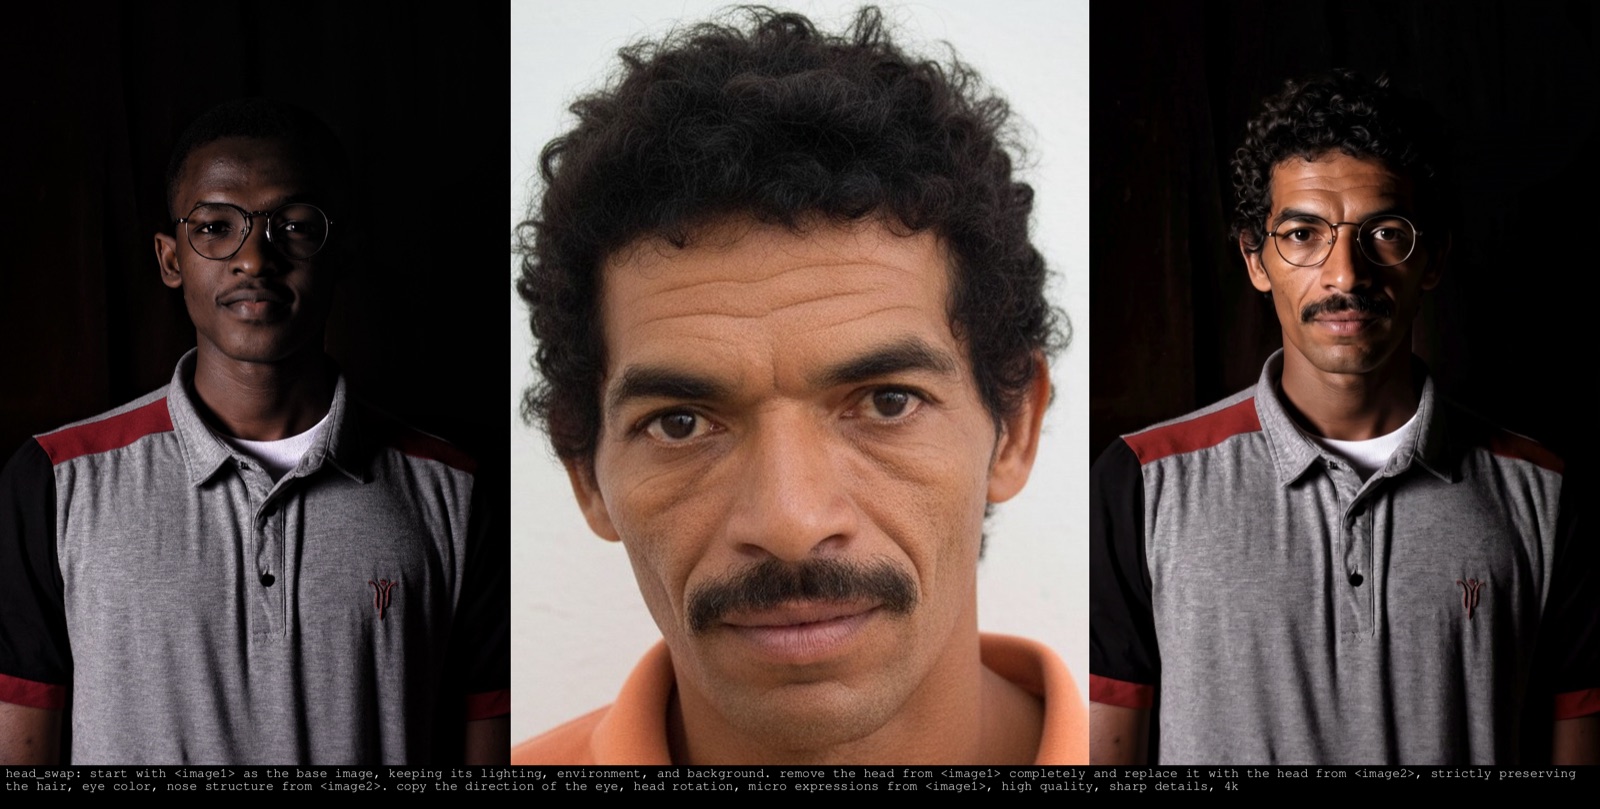 Image editing
BFS Best Face Swap ships a Qwen-Image 2.1 head-swap LoRA with a ready ComfyUI workflow, plus experimental LTX-2 in-context head-swap weights.
MIT
 Text to image
Alibaba PAI distills Qwen-Image 2.1 to 4 steps with a 346 MB PDD LoRA that covers text-to-image and instruction editing, with its own sigma schedule.
qwen-research
 Text to image
ByteDance's Seedream 5.0 Flash adds a speed-focused tier to ComfyUI's ByteDance image nodes, with text-to-image and image edit templates at up to 2K.
API-Only
 Text to image
Alibaba PAI's ControlNet Union for Qwen-Image 2.1 packs eight structural controls and inpainting into one 7.5 GB branch, with ComfyUI support landing.
qwen-research
 Text to image
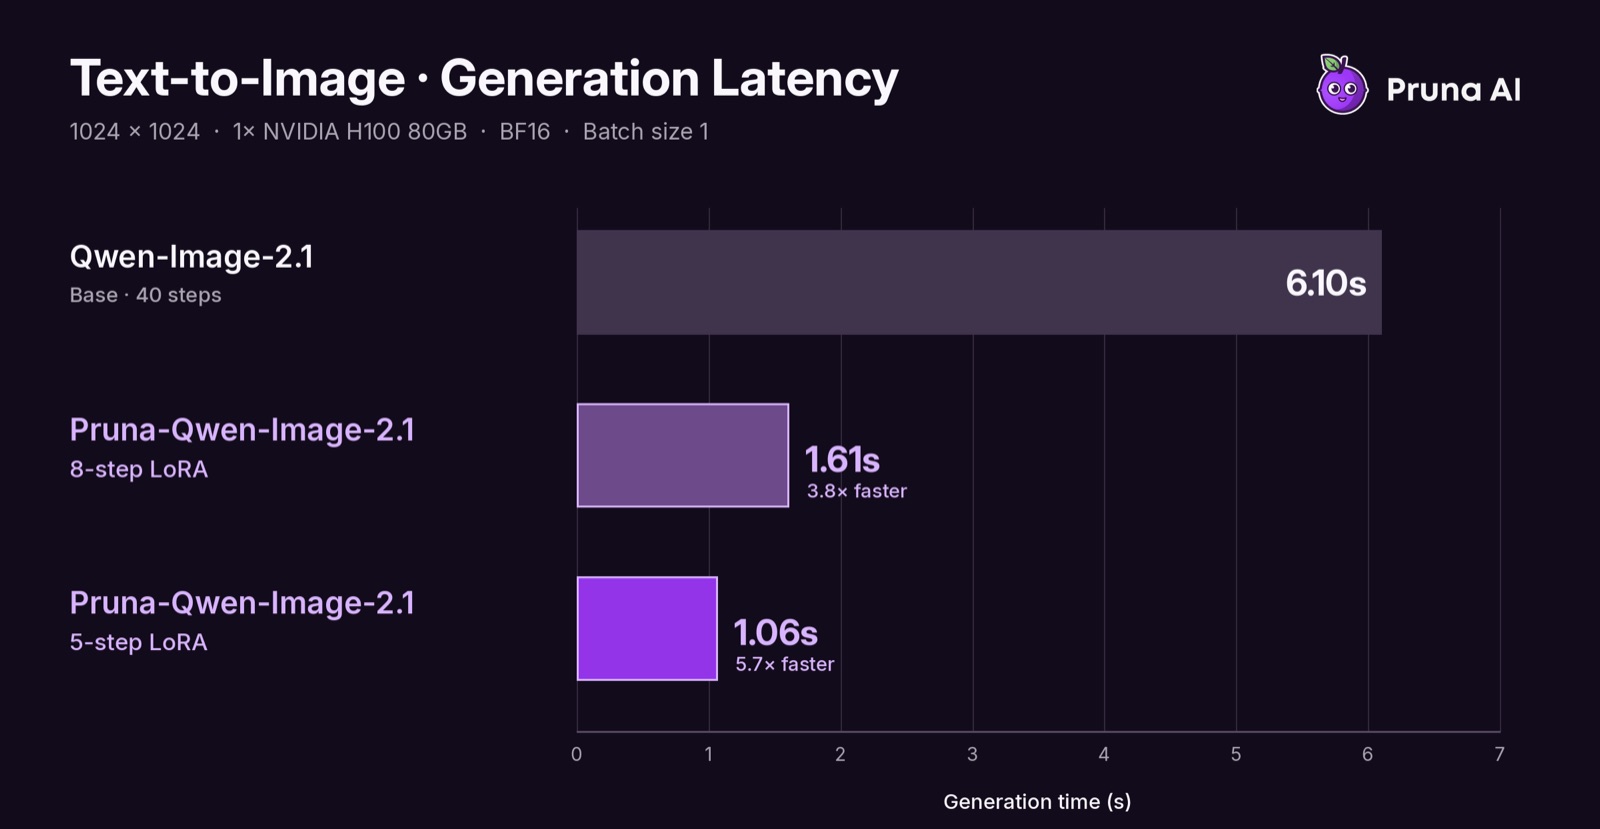
PrunaAI's Pruna-Qwen-Image-2.1 LoRAs cut Qwen-Image 2.1 generation and editing to 5 or 8 steps with no CFG, with community ComfyUI conversions and per-step sigma schedules.
Qwen Research License
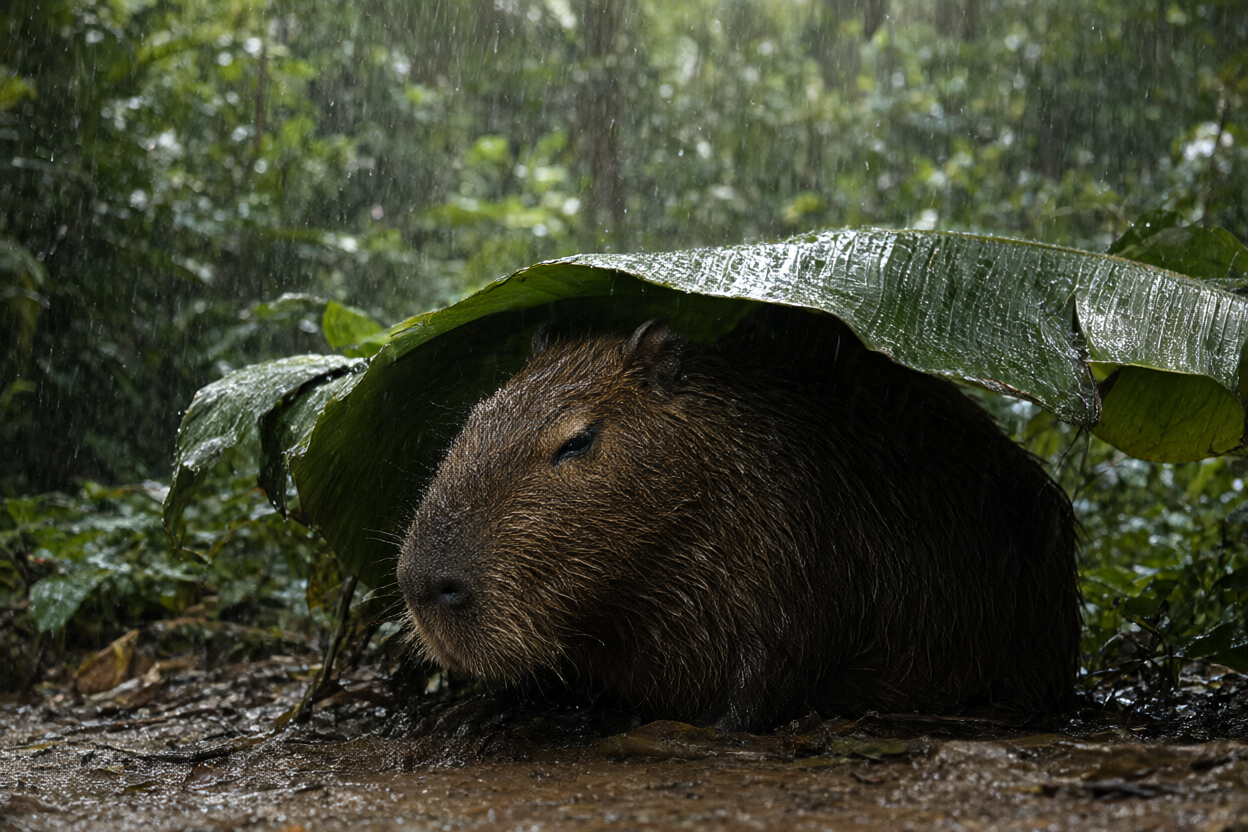 Text to image
Viggle's v0.2 DMD distillation of Qwen-Image 2.1 cuts generation to 5 steps with no CFG, shipping as a rank-256 LoRA with community ComfyUI conversions.
Qwen Research License
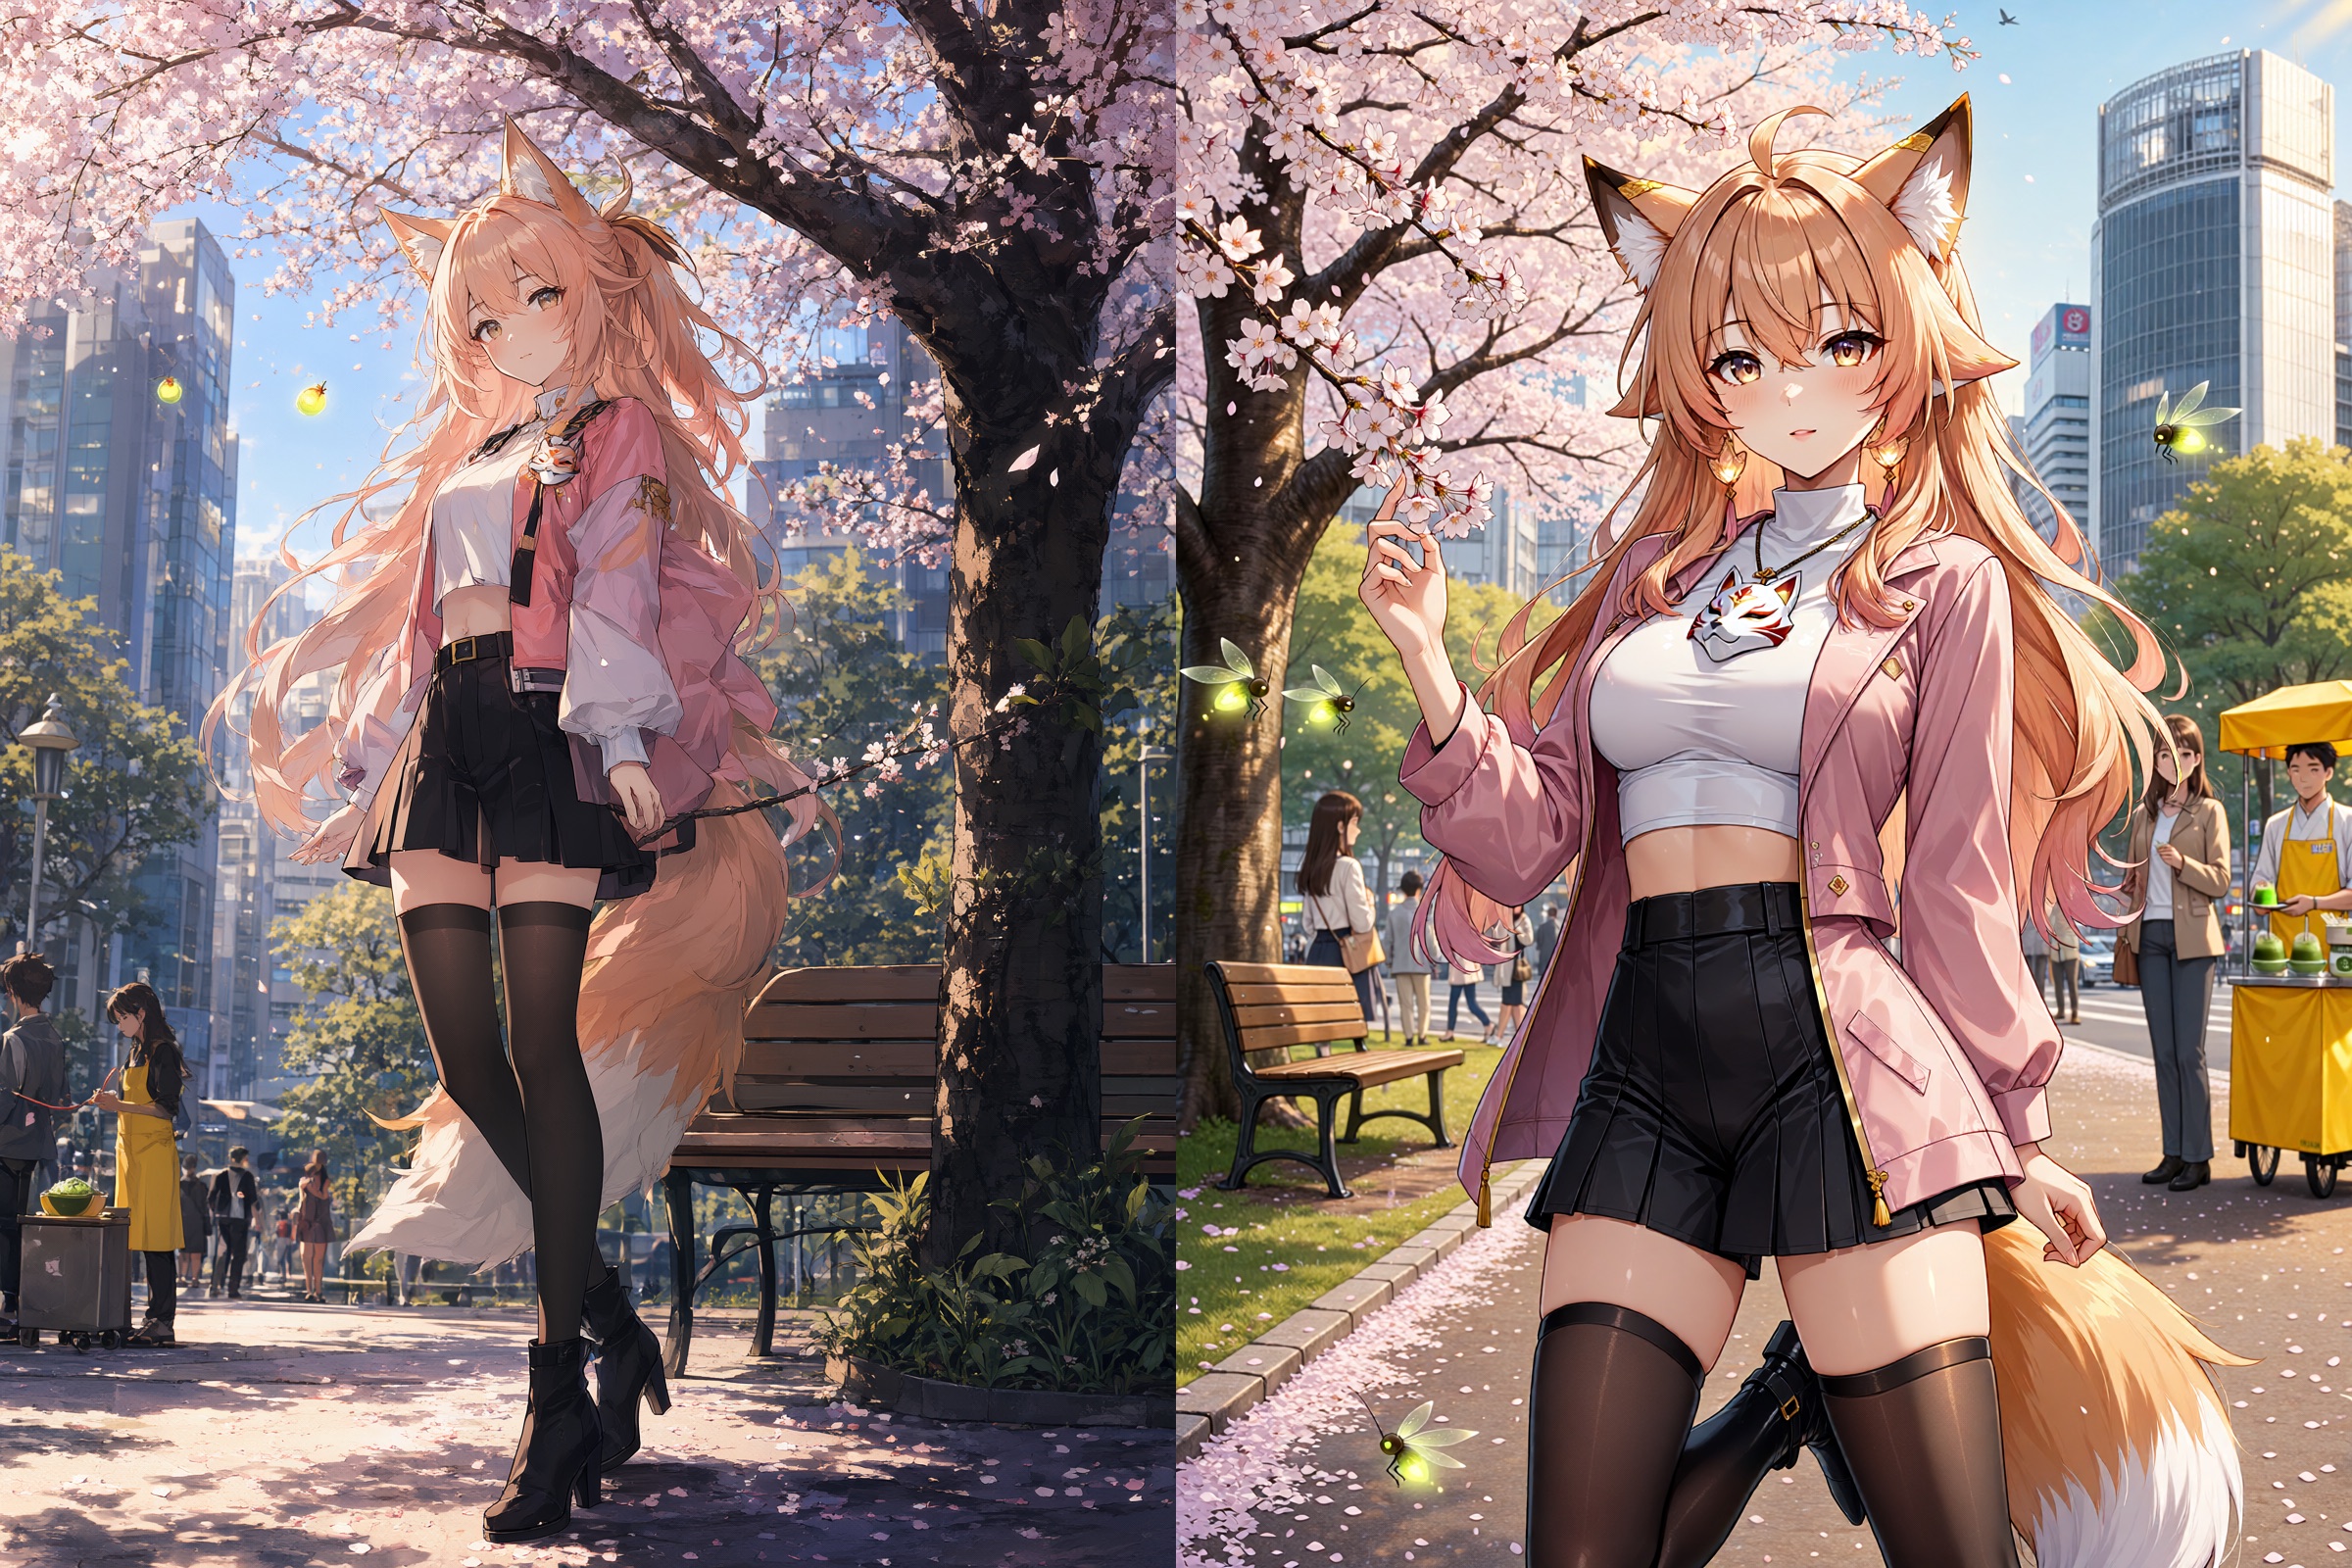 Text to image
Qwen-Image 2.1 Fix is a community LoRA with a companion 20-step ComfyUI workflow, aimed at the model's washed-out colors and broken fine texture.
Qwen Research License
 Text to image
Tencent's HY Image 3.5 Preview adds text-to-image, reference-image and multi-turn editing to the Hunyuan image API, with new ComfyUI text-to-image and edit nodes.
API-Only
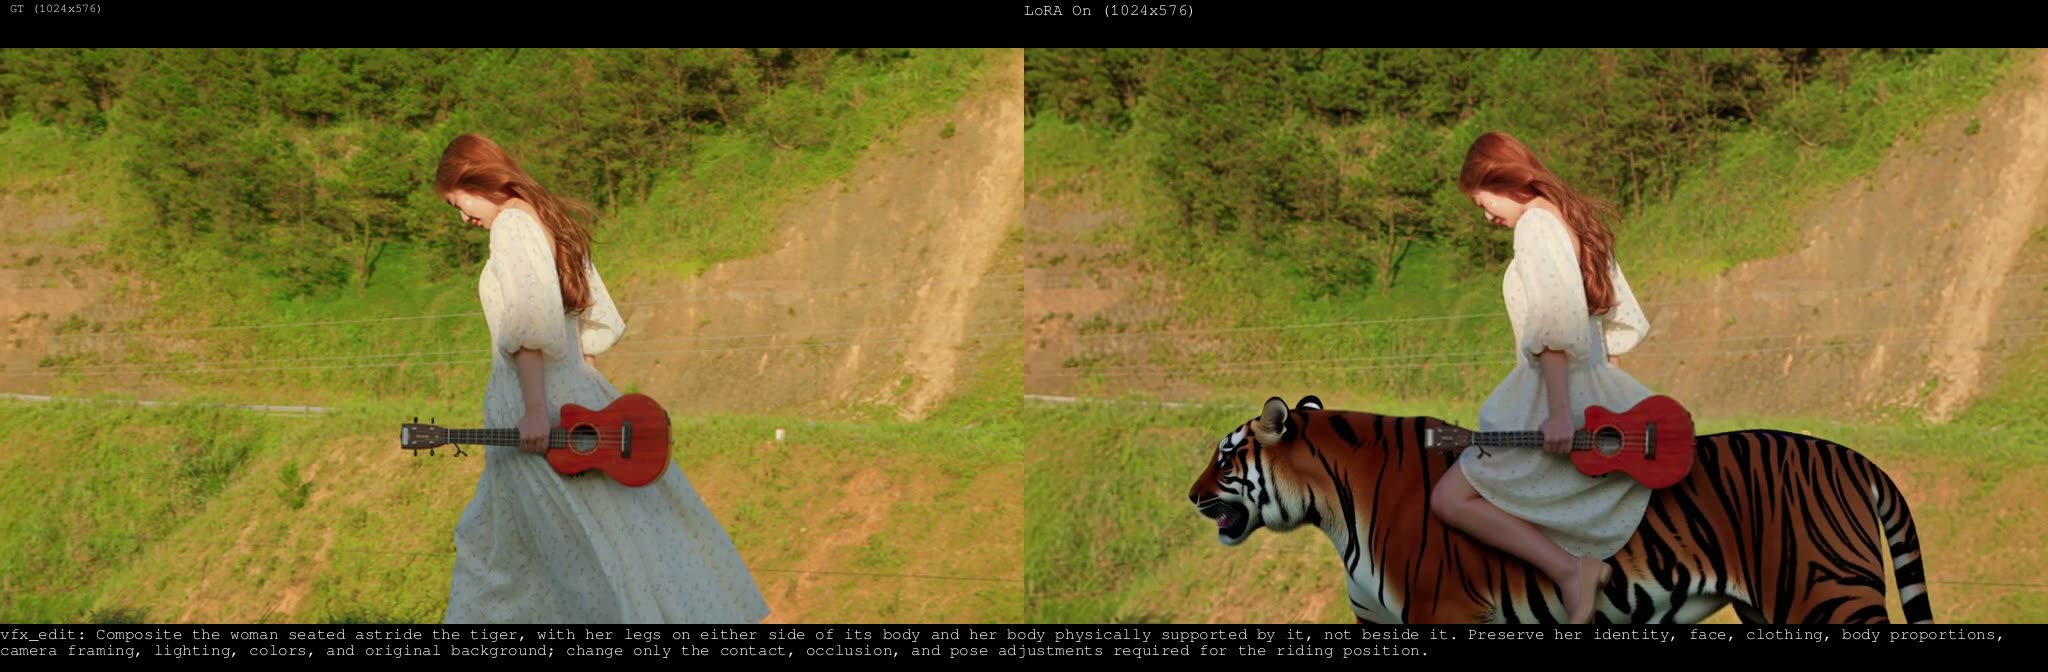 Video editing
Alissonerdx's MiniMax H3 LoRA pack adds prompt-directed VFX Edit plus documented Style Transfer and Head Swap adapters, with ComfyUI workflows and example clips.
Apache-2.0
 Inpainting
Alibaba PAI's ControlNet Union 2.0 for MiniMax H3 adds Scribble, Layout and Gray control and doubles the injection blocks, with same-day ComfyUI support.
minimax-h3-community-license-agreement
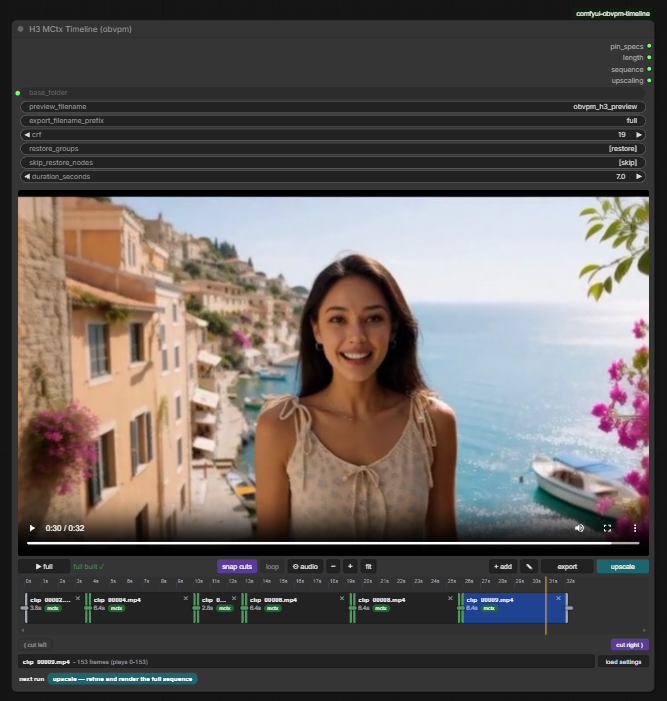 Video editing
comfyui-obvpm-timeline adds a mini video editor to ComfyUI for MiniMax H3: extend, prepend, bridge and loop clips with latent-grade joins and a one-pass upscale.
GPL-3.0
 Text to image
SupraLabs releases Supra2-IMG, a 105M-parameter DiT text-to-image model trained from scratch in 10 hours on one H100, with samples at 256x256.
Apache-2.0
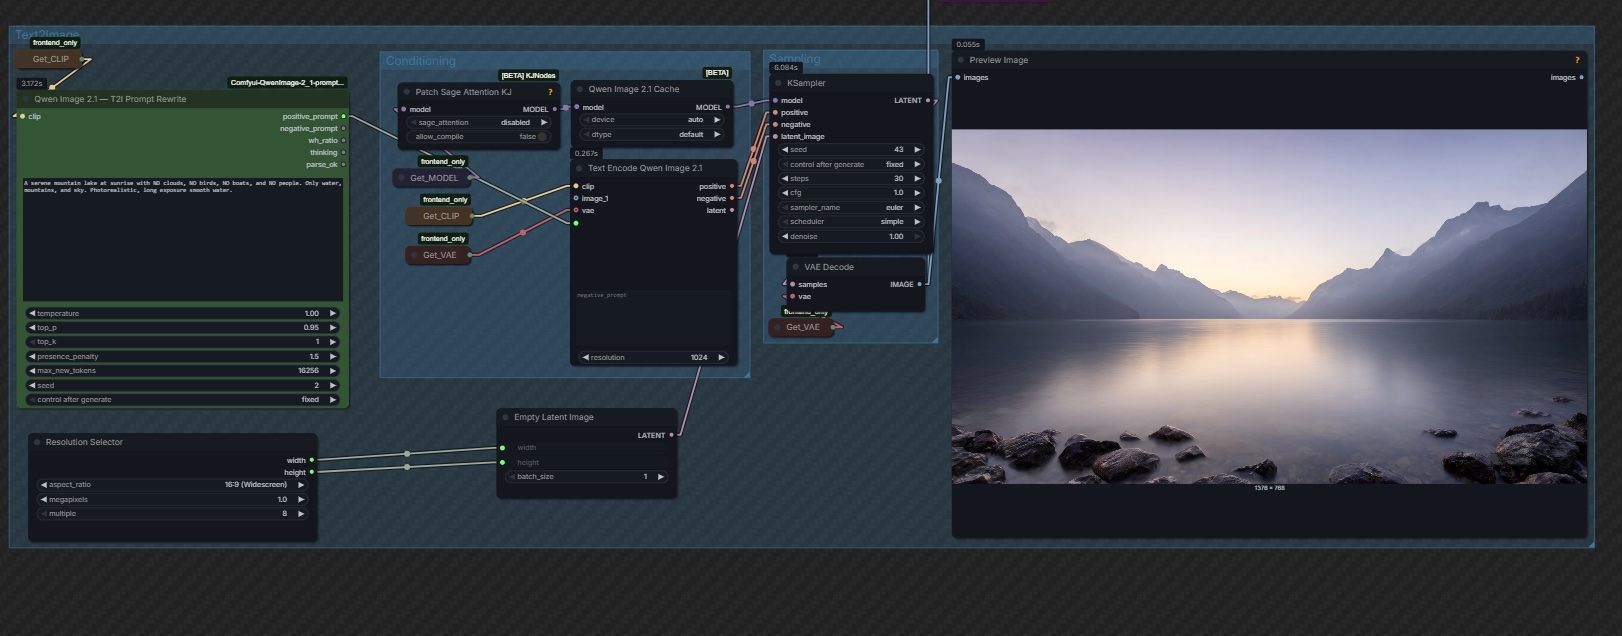 Text to image
Qwen's PE-T2I and PE-I2I prompt rewriting models expand short requests and edit instructions, and a community node pack runs both in ComfyUI through Load CLIP.
 Ecosystem
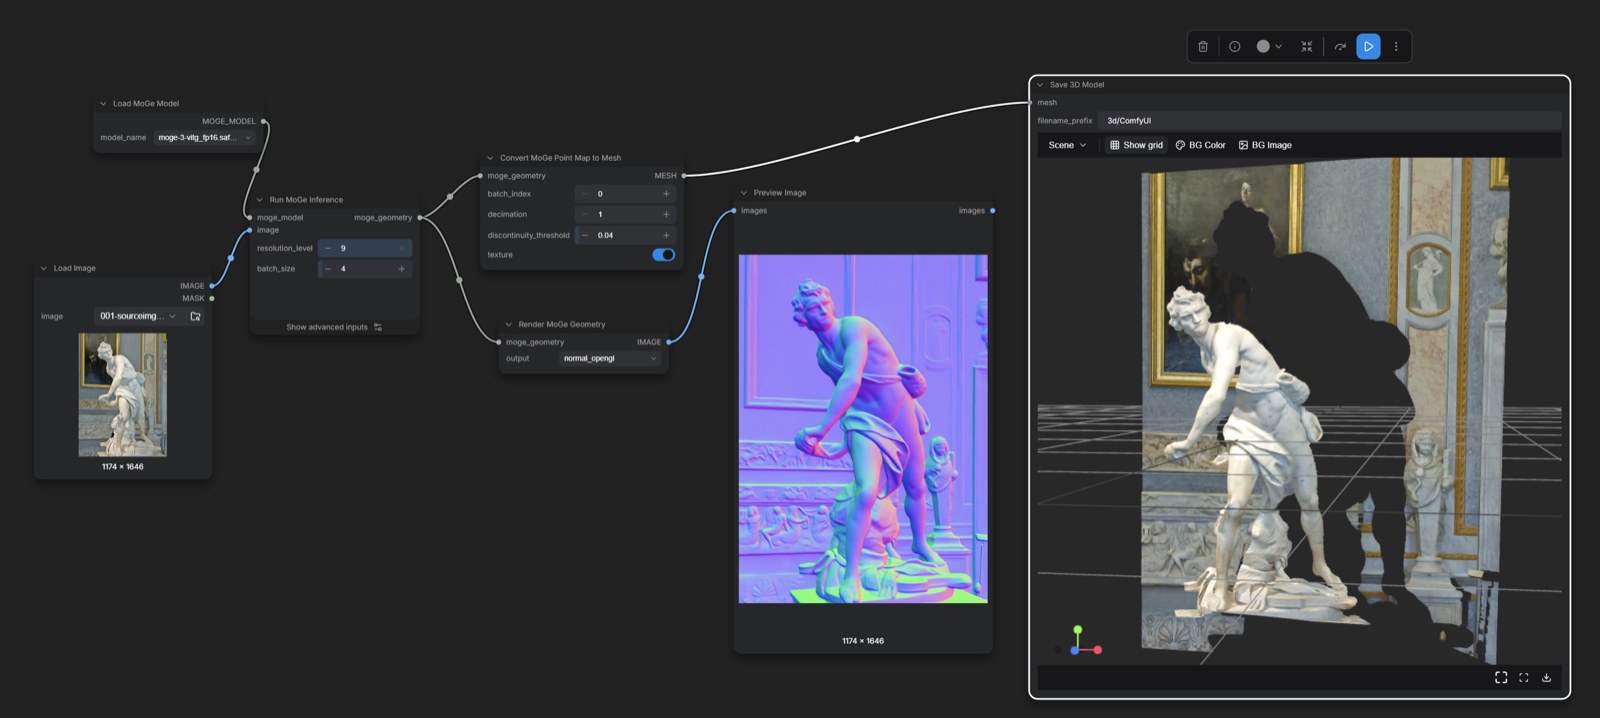
Cseti ports CrossView-Warp to MiniMax H3: a Ref2VA LoRA plus a ComfyUI node that re-renders existing footage from a new camera angle using a MoGe depth warp.
MiniMax-H3-Community
 Ecosystem
ComfyUI v0.37.0 adds native Qwen-Image 2.1 support with three official templates, MoGe 3 geometry estimation, faster Qwen3.8 text encoders and automatic fast disk loading.
 Text to video
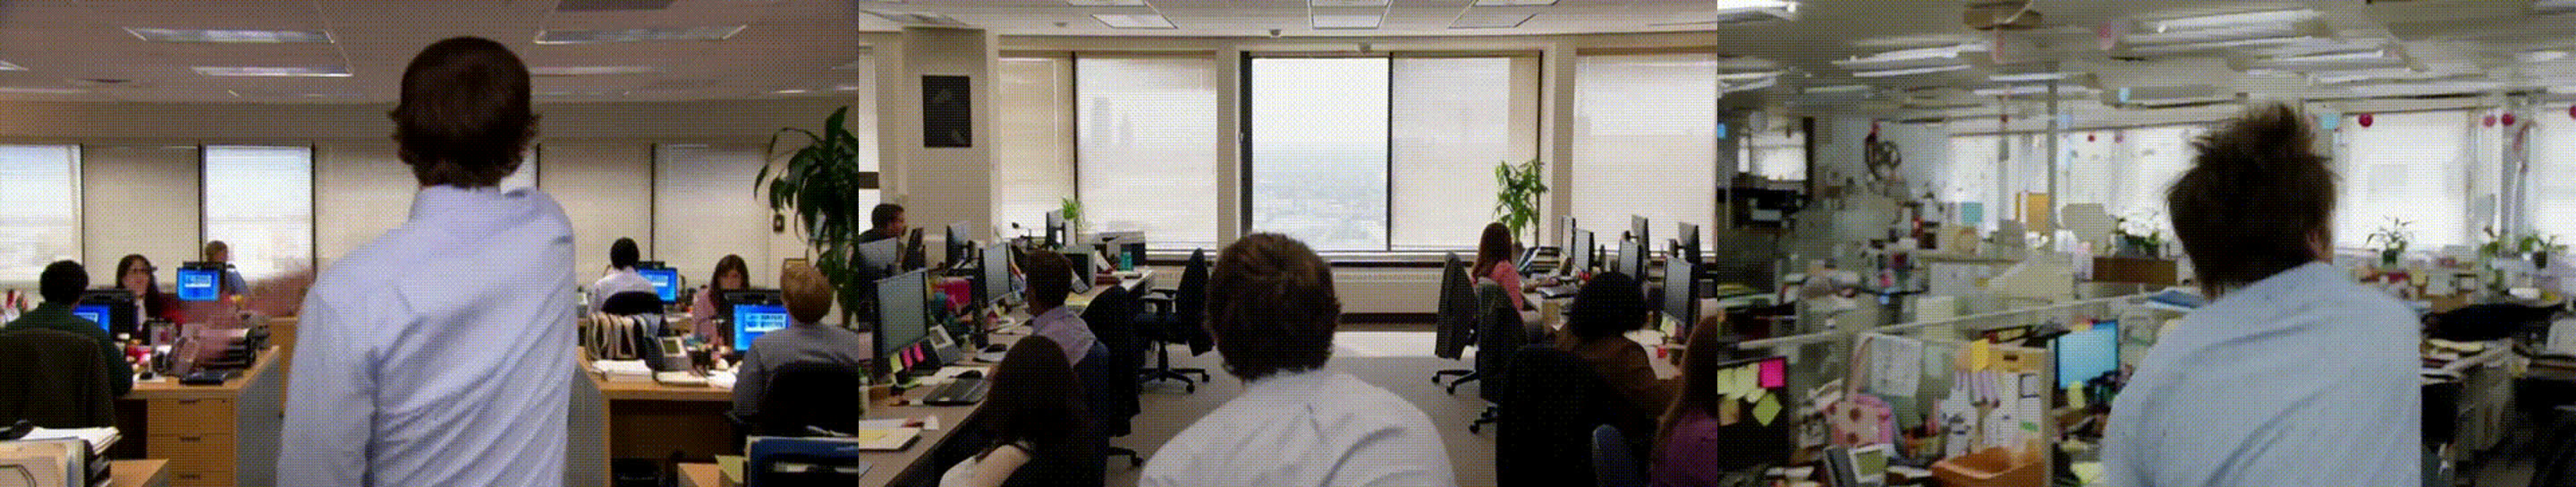
ComfyUI-MiniMax-H3-SPEED V2 supports Euler, Heun, DPM2 and RES Multistep, adds a sampler-aware Sigma Harvest, and fixes I2V keyframe resizing.
 Text to image
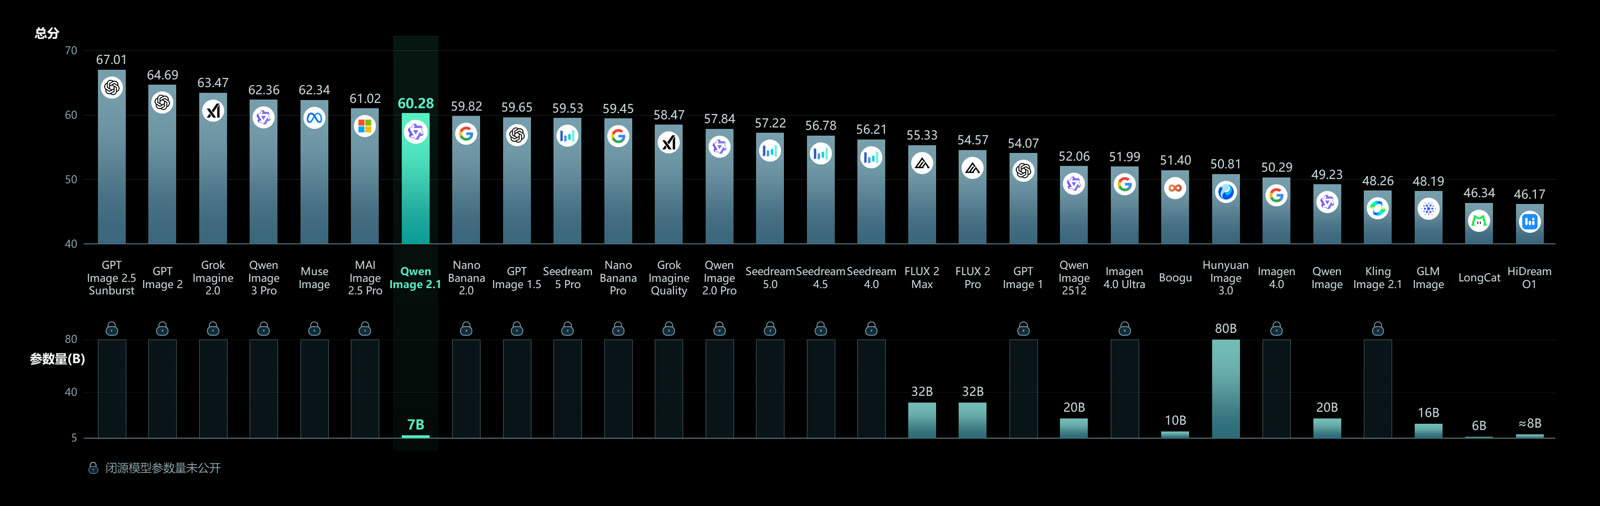
Download Qwen-Image 2.1 for ComfyUI: qwen_image_2.1_bf16 and int8_convrot safetensors, qwen3vl_8b encoder and official 2K text-to-image, edit and background removal workflows.
Qwen Research License
 Text to image
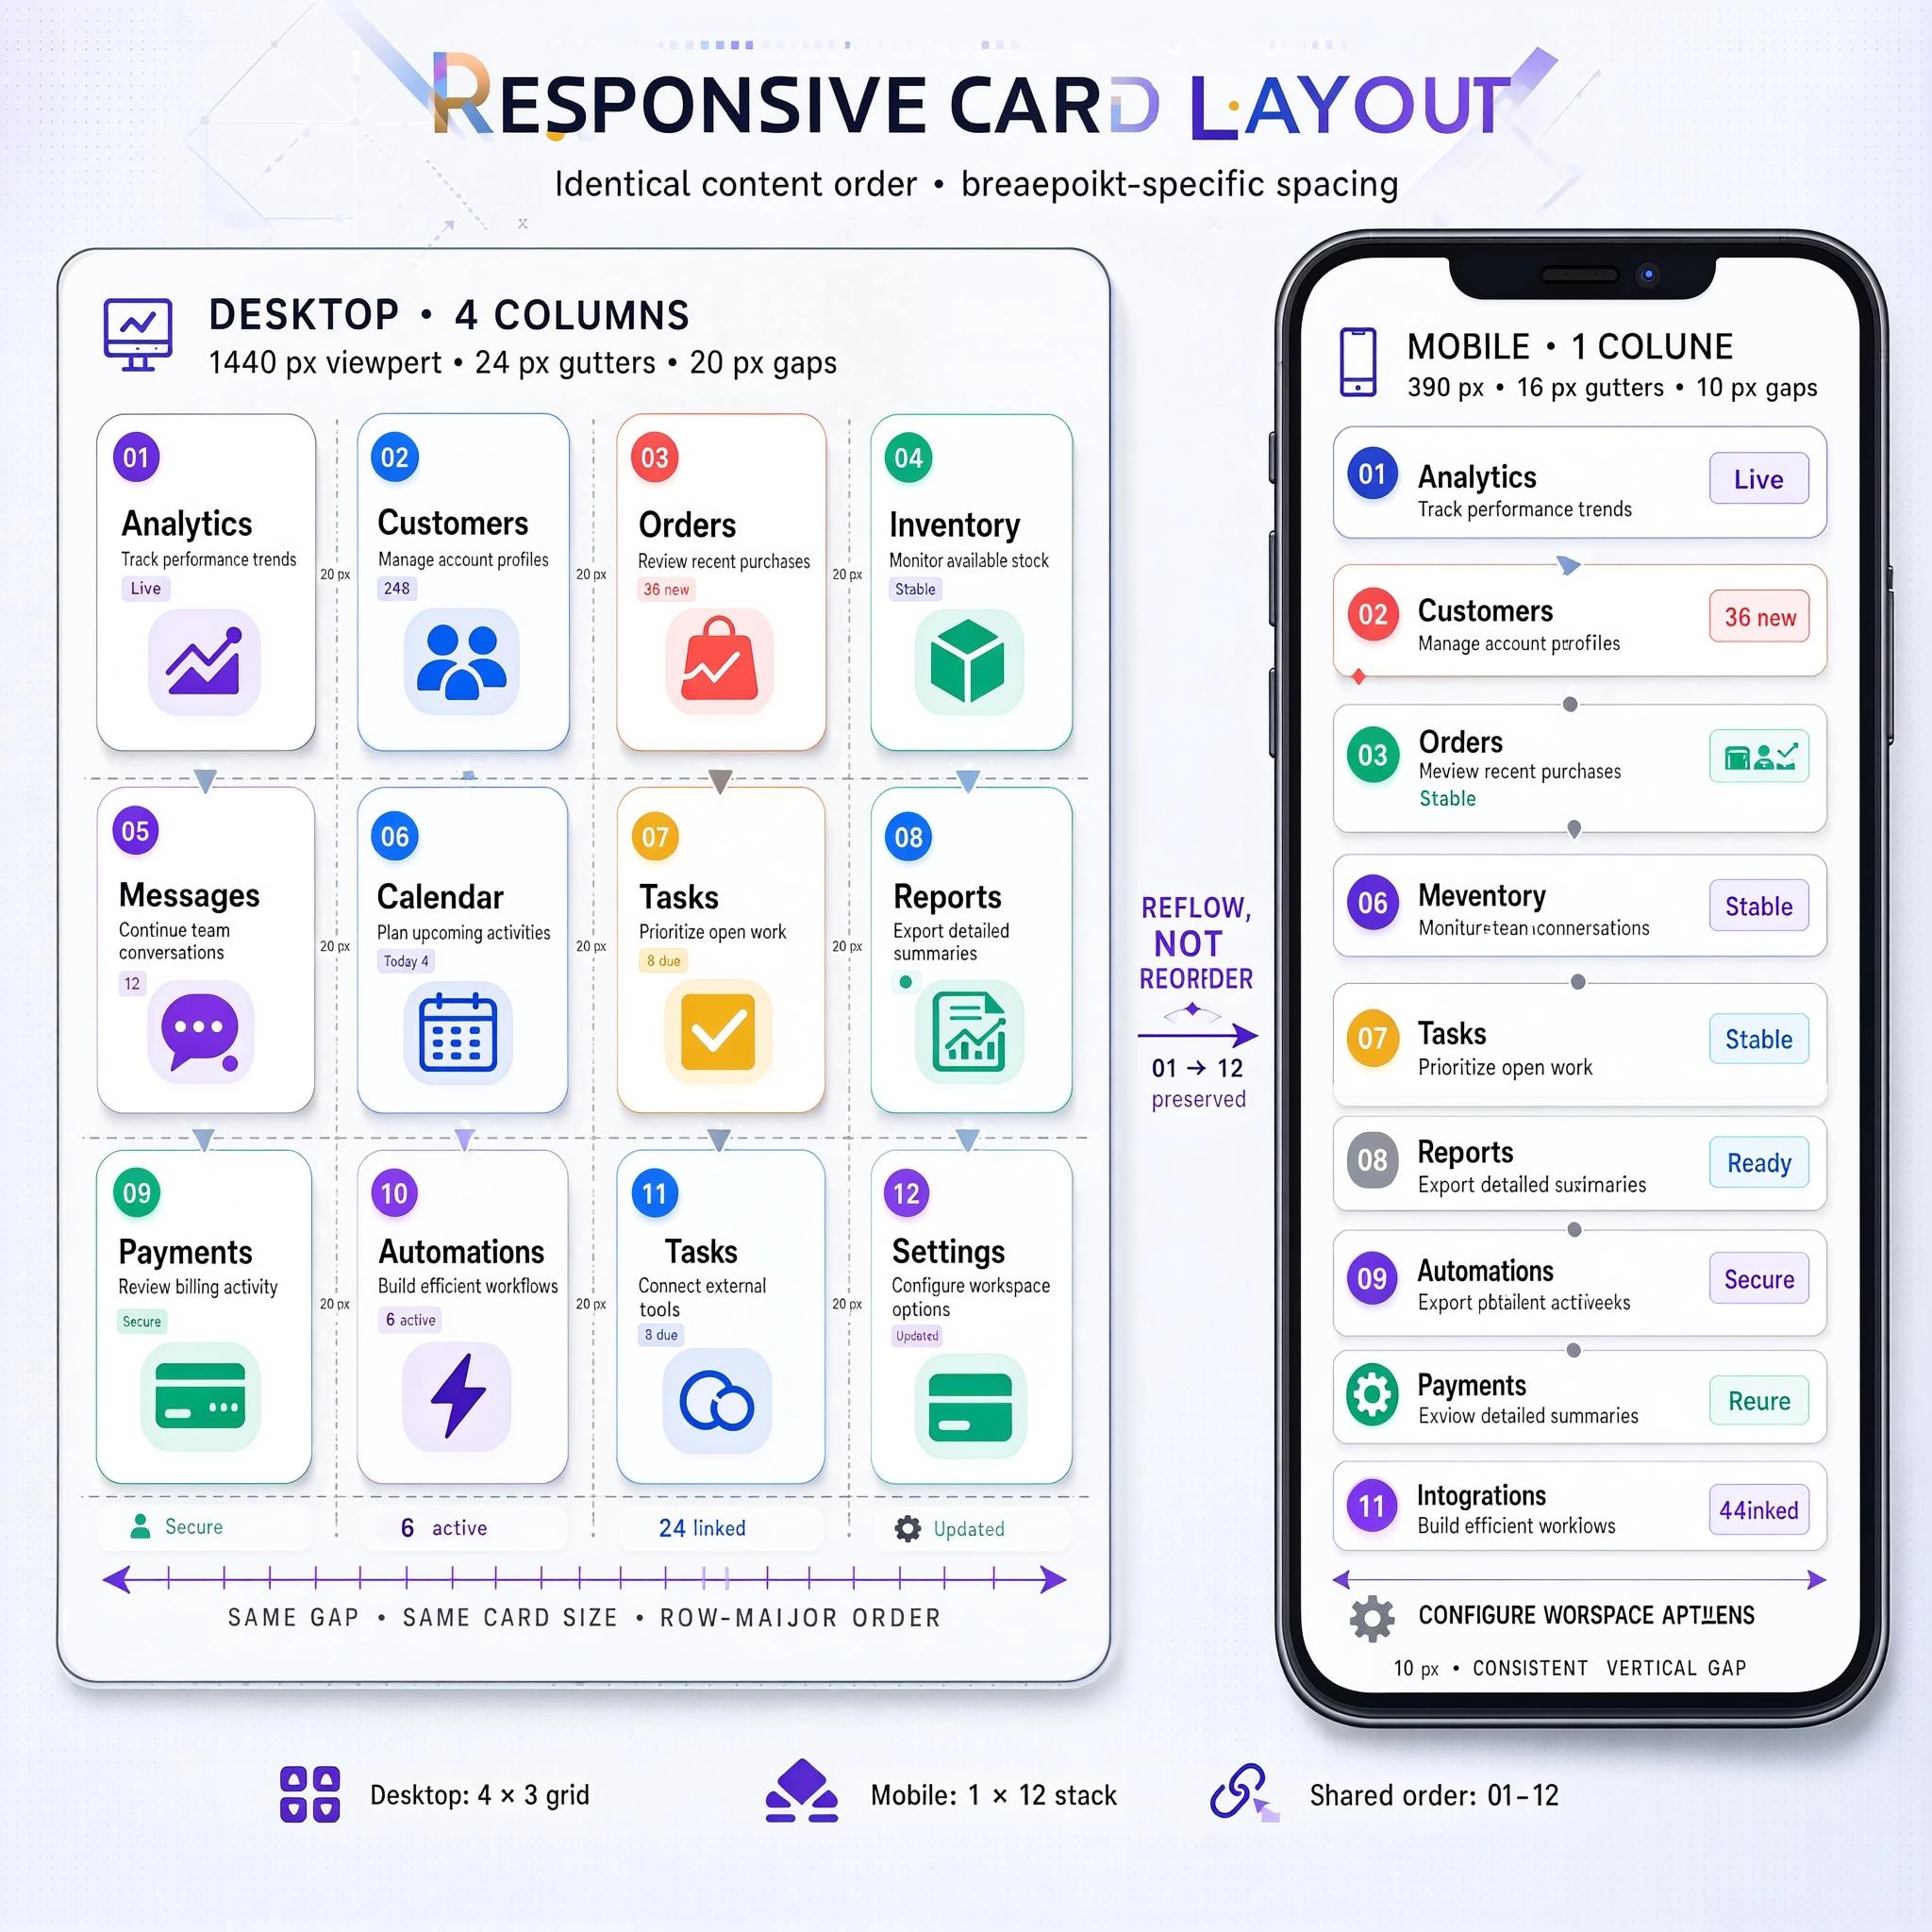
Ming-Image 0.1 Design is inclusionAI's 6B text-to-image model for UI, infographics and text-heavy posters, with RGBA transparency and work-in-progress ComfyUI support.
MIT
 Text to video
Video Rebirth's HyperFlow cuts MiniMax H3 sampling from 49 transformer forwards to 8 with a data-free self-distillation LoRA; two ComfyUI ports followed.
minimax-h3-community-license-agreement