 Image editing
Tool
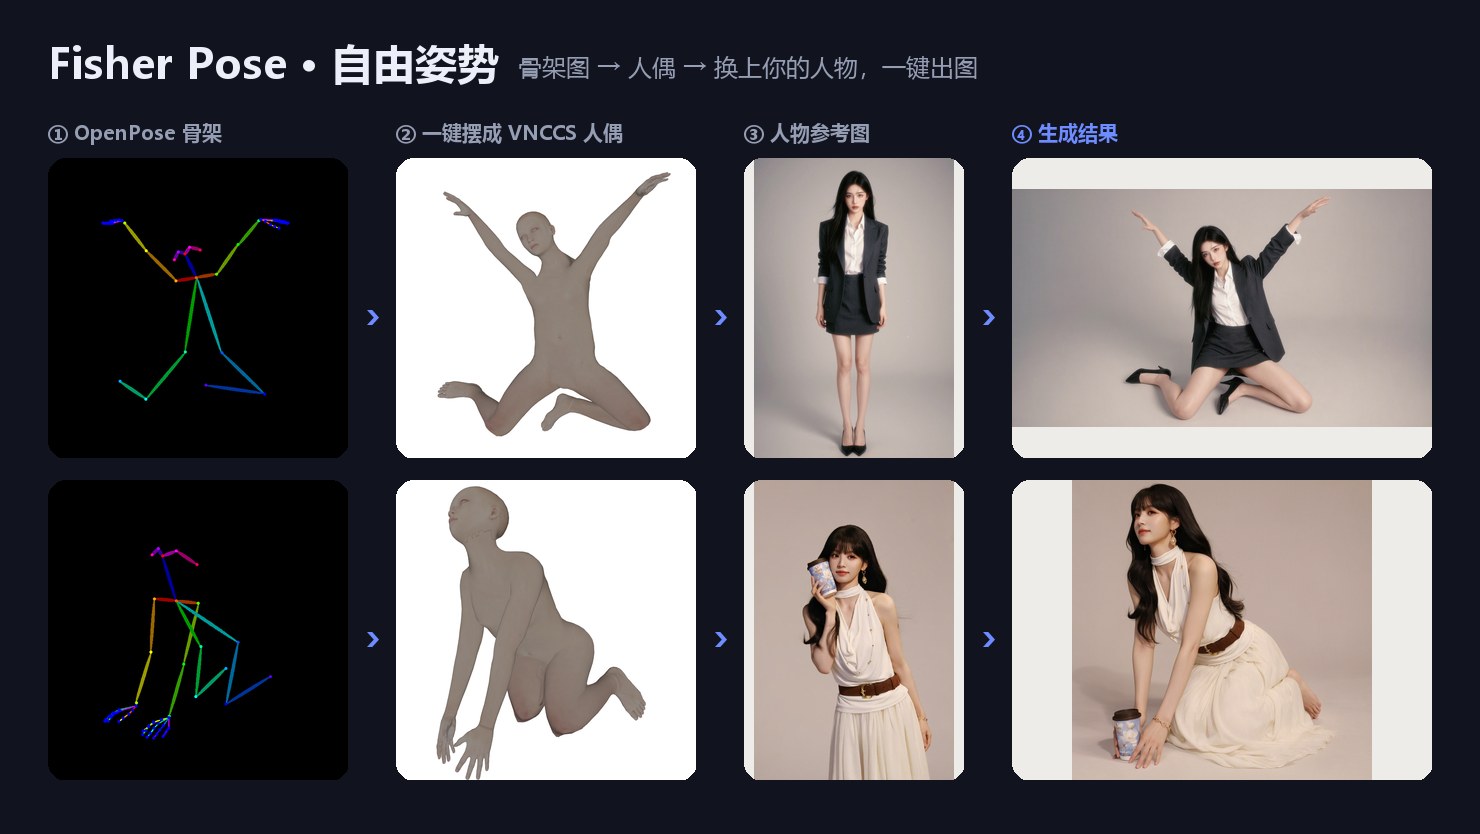
Fisher Pose: Pose and Camera Editor for Qwen-Image 2.1Fisher Pose is a ComfyUI node that redraws a character in a new pose or camera angle for Qwen-Image 2.1, using a 3D mannequin, 209 OpenPose skeletons and a matching LoRA.
ComfyUI ecosystem updates — open-source model releases, custom nodes, workflows, and tools for image, video, and audio generation.
Image editingFisher Pose is a ComfyUI node that redraws a character in a new pose or camera angle for Qwen-Image 2.1, using a 3D mannequin, 209 OpenPose skeletons and a matching LoRA.
 Text to image
madebyollin's Texture-Fix-VAE retrains the Qwen-Image 2.1 VAE decoder to remove checkerboard texture artifacts. Drop the file into ComfyUI/models/vae and load it as usual.
qwen-research
 Text to image
Alibaba PAI distills Qwen-Image 2.1 to 4 steps with a 346 MB PDD LoRA that covers text-to-image and instruction editing, with its own sigma schedule.
qwen-research
 Text to image
ByteDance's Seedream 5.0 Flash adds a speed-focused tier to ComfyUI's ByteDance image nodes, with text-to-image and image edit templates at up to 2K.
API-Only
 Text to image
Alibaba PAI's ControlNet Union for Qwen-Image 2.1 packs eight structural controls and inpainting into one 7.5 GB branch, now with merged ComfyUI support.
qwen-research
 Text to image
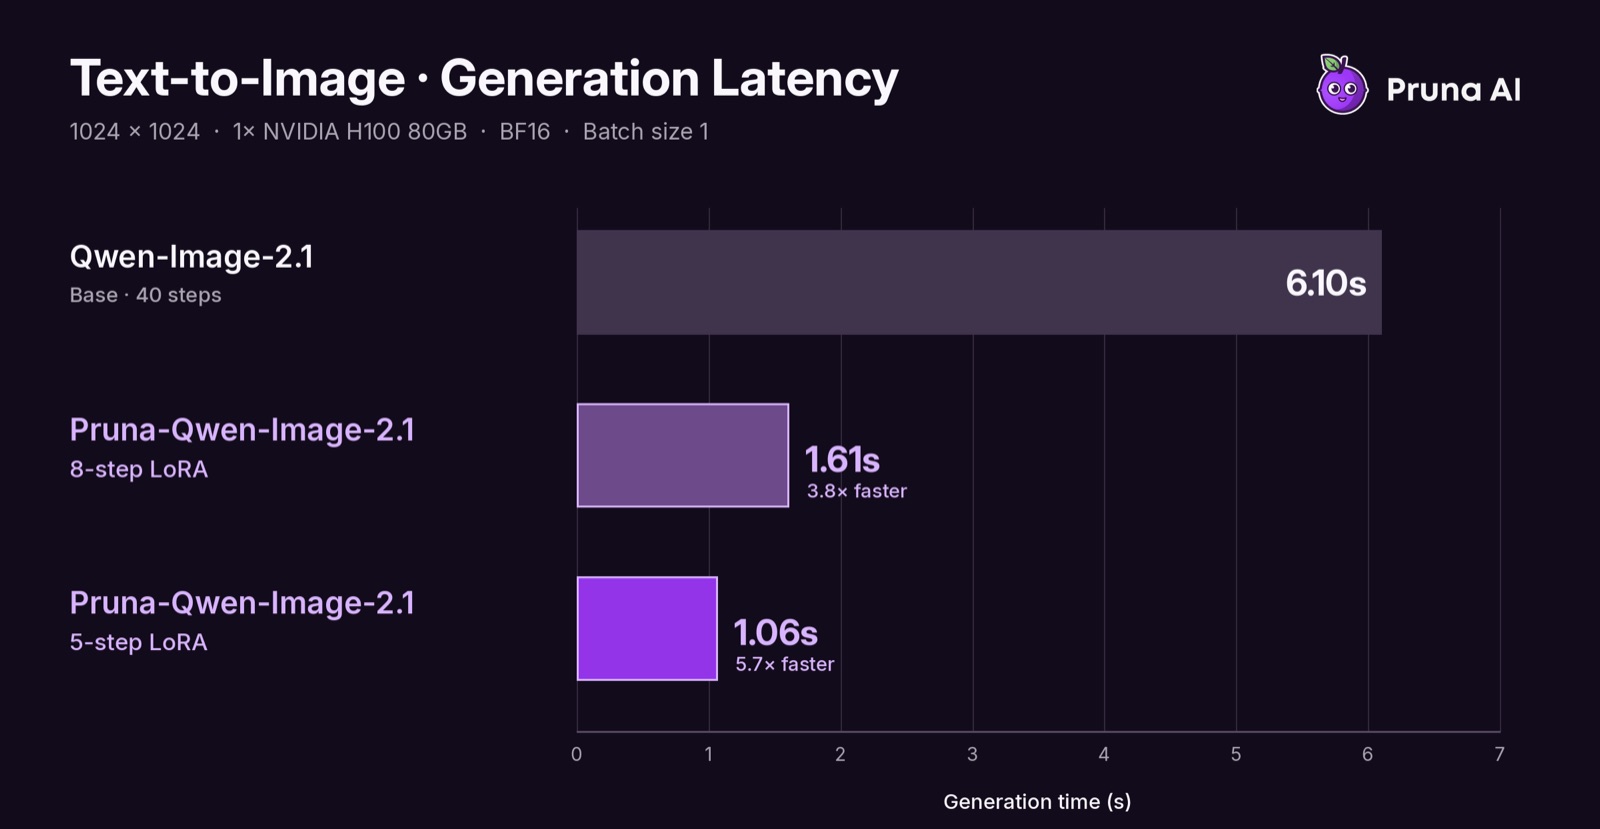
PrunaAI's Pruna-Qwen-Image-2.1 LoRAs cut Qwen-Image 2.1 generation and editing to 5 or 8 steps with no CFG, with community ComfyUI conversions and per-step sigma schedules.
Qwen Research License
 Text to image
Viggle's v0.2 DMD distillation of Qwen-Image 2.1 cuts generation to 5 steps with no CFG, shipping as a rank-256 LoRA with community ComfyUI conversions.
Qwen Research License
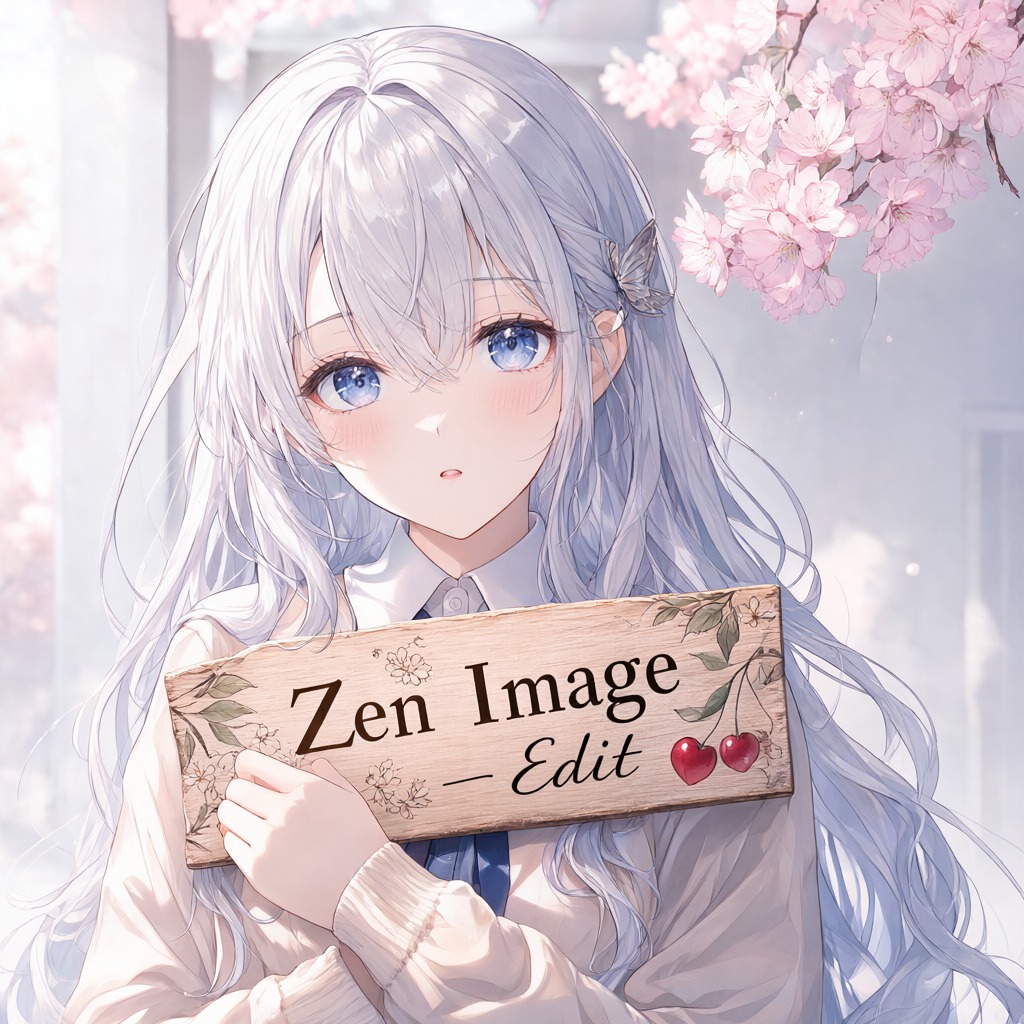 Text to image
Zen Image Edit runs Qwen-Image 2.1 on a Qwen3.5-0.8B text encoder plus a 158M fusion adapter, cutting the encoder from 17.5 GB to 1.7 GB, with two ComfyUI routes.
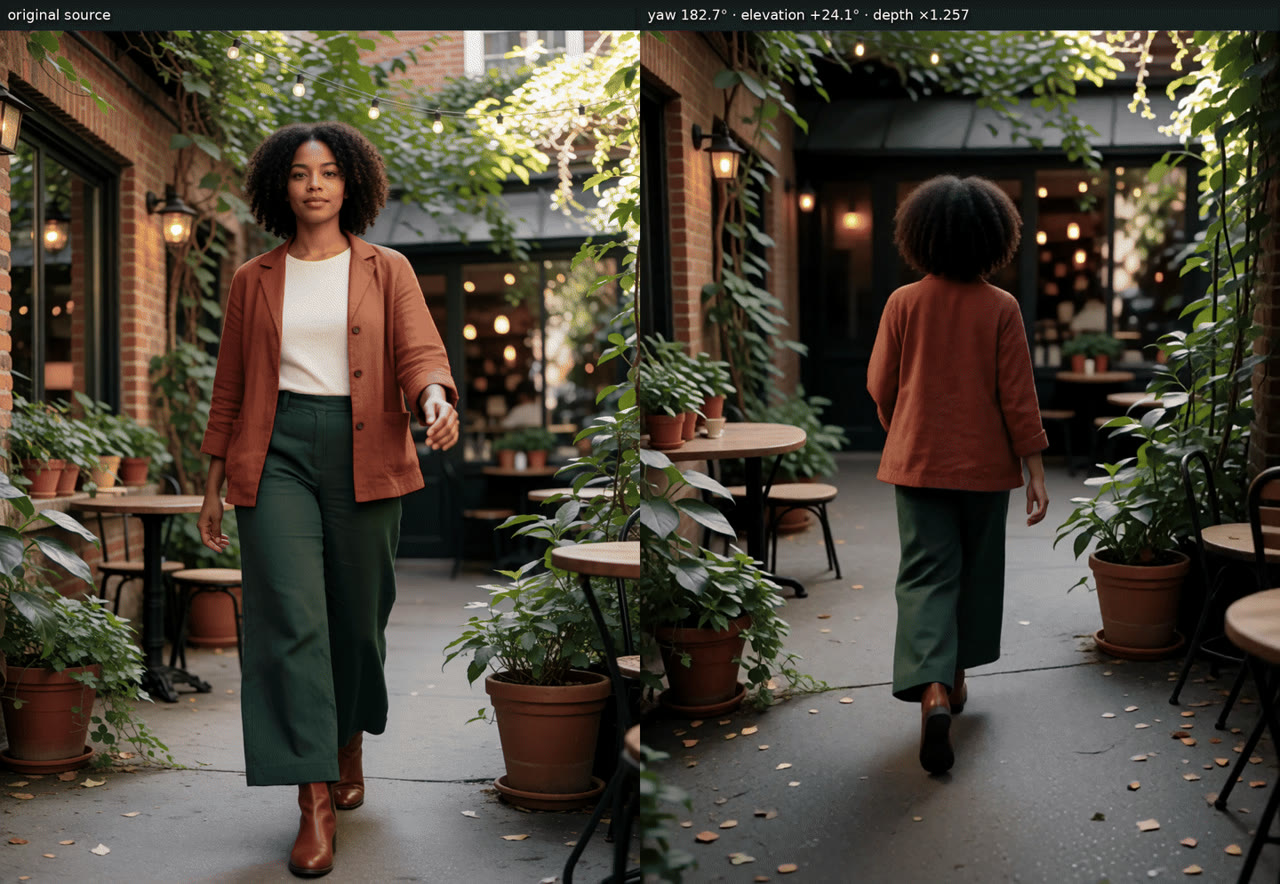 Image to image
Krea 2 Anygles turns one photo of a person into a new camera view with a 3D human normal LoRA, plus ComfyUI nodes and a workflow for orbit, elevation and distance.
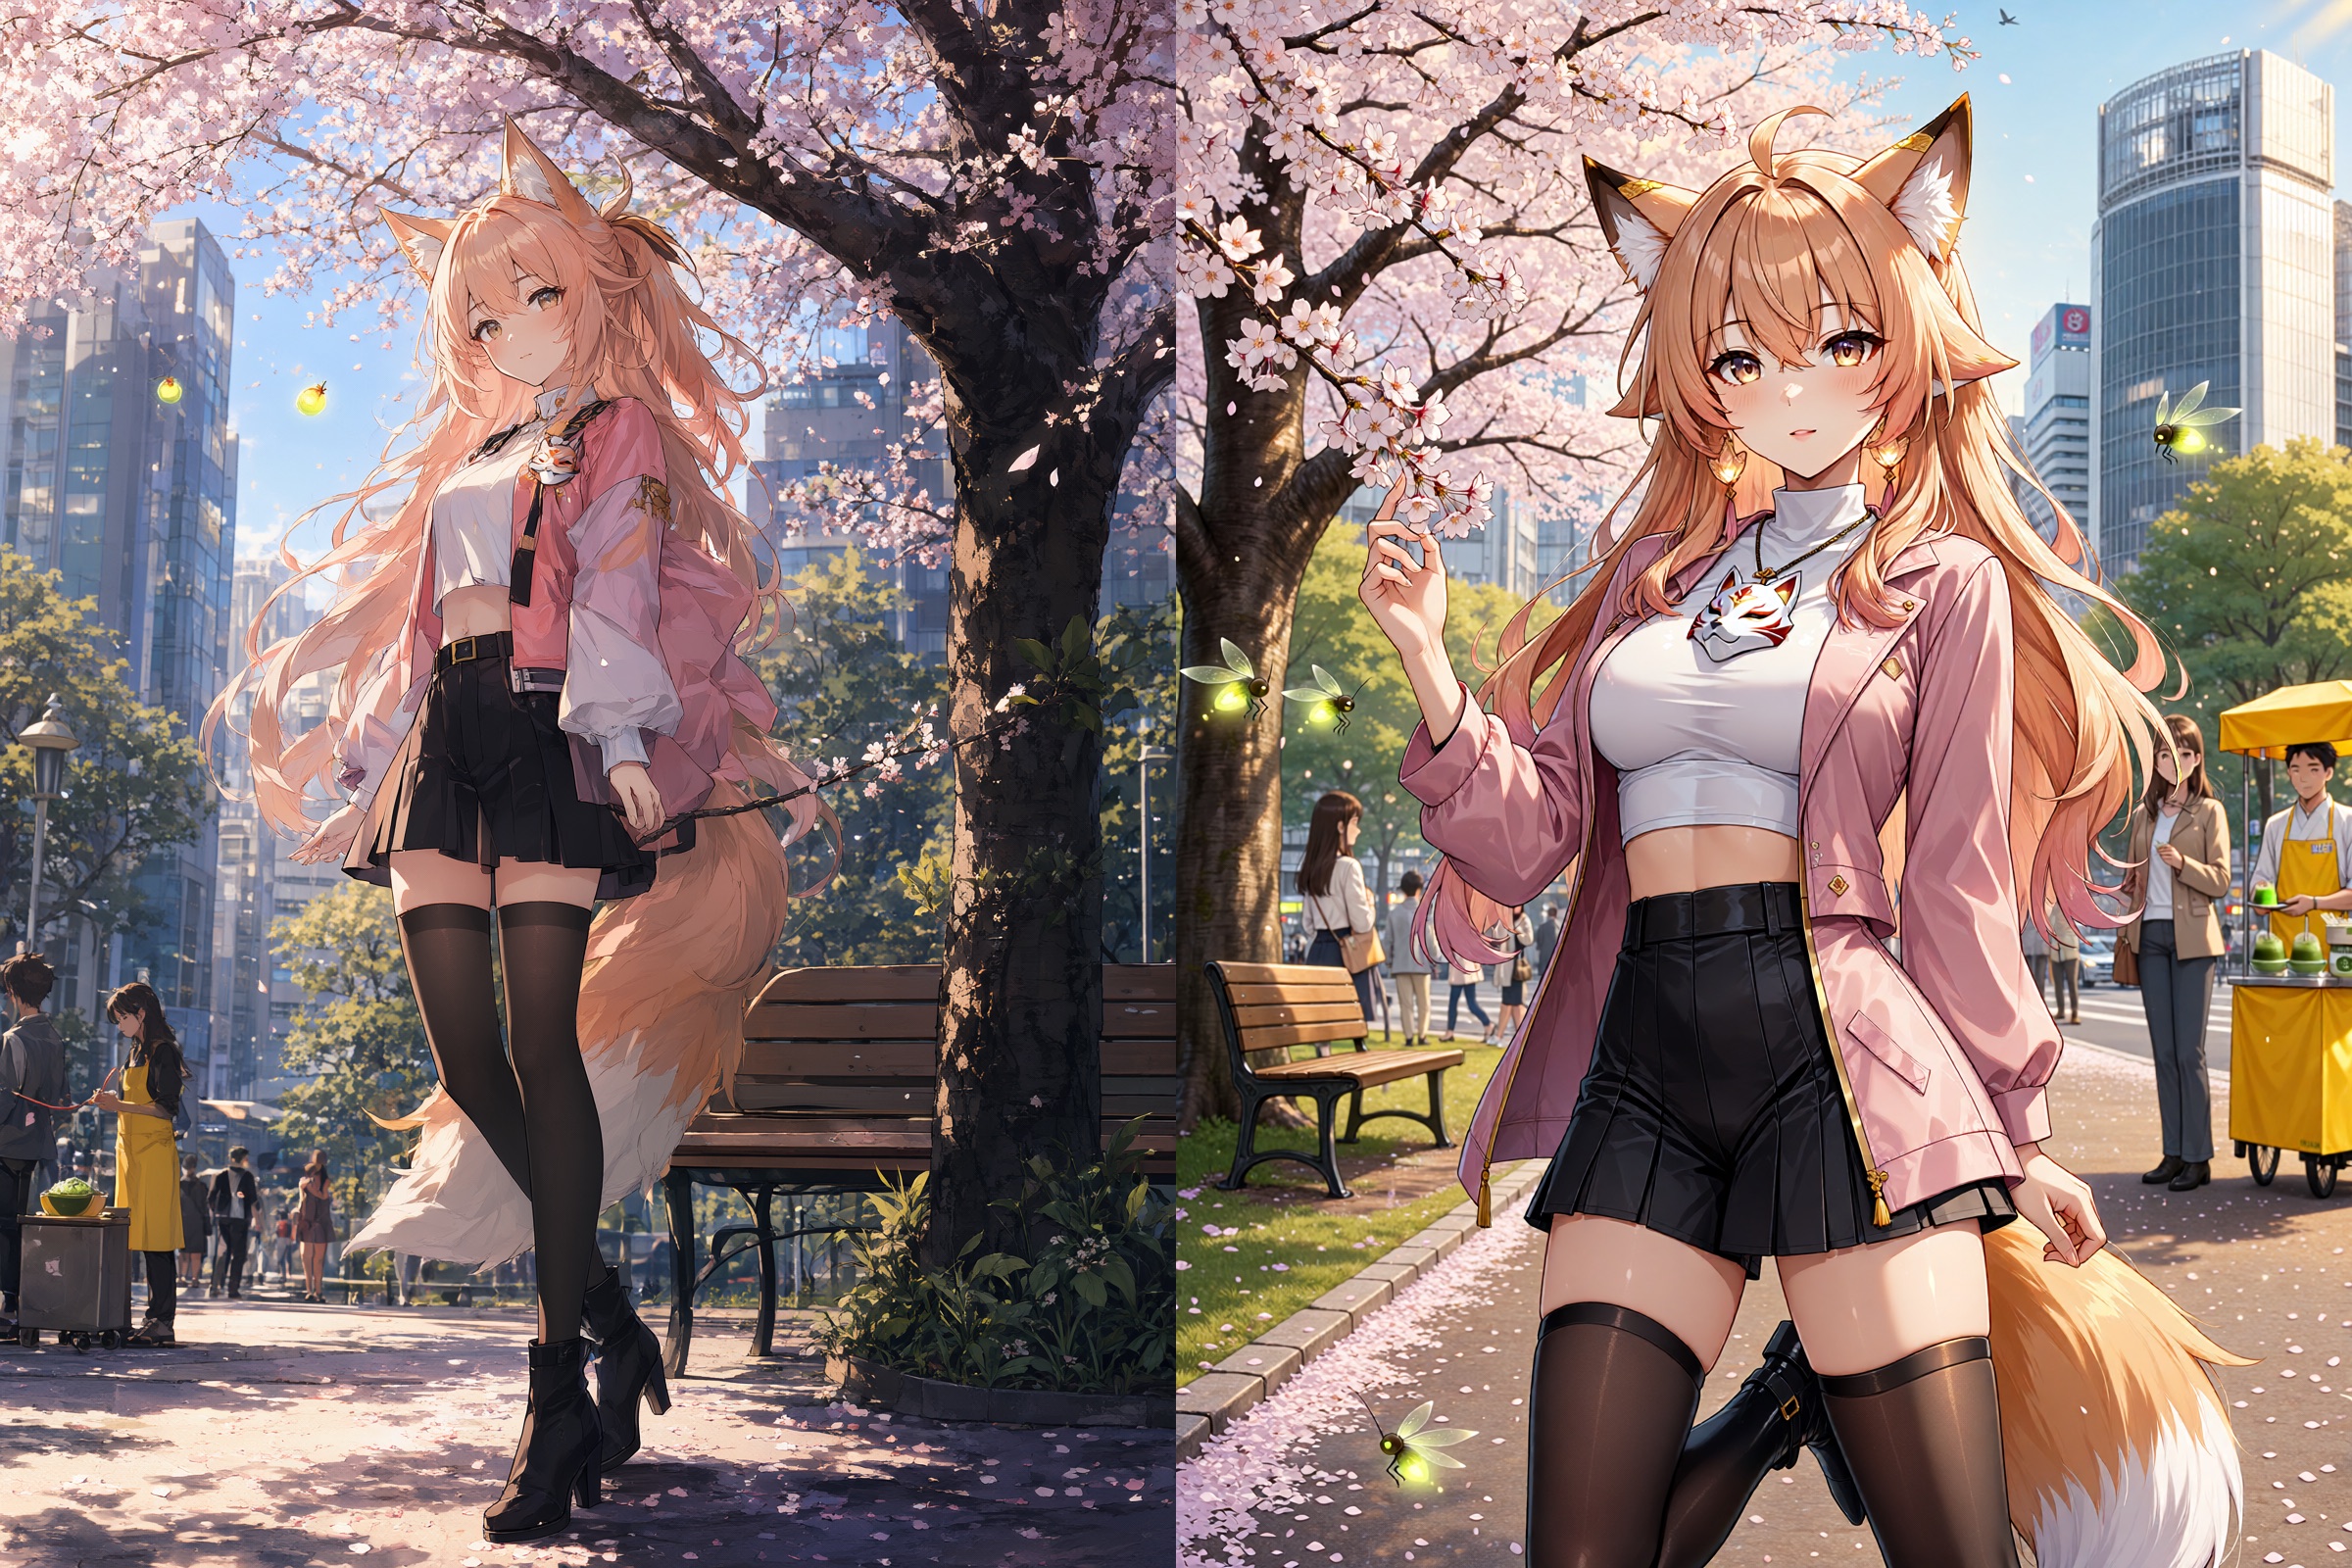 Text to image
Qwen-Image 2.1 Fix is a community LoRA with a companion 20-step ComfyUI workflow, aimed at the model's washed-out colors and broken fine texture.
Qwen Research License
 Text to image
Tencent's HY Image 3.5 Preview adds text-to-image, reference-image and multi-turn editing to the Hunyuan image API, with new ComfyUI text-to-image and edit nodes.
API-Only
 Video editing
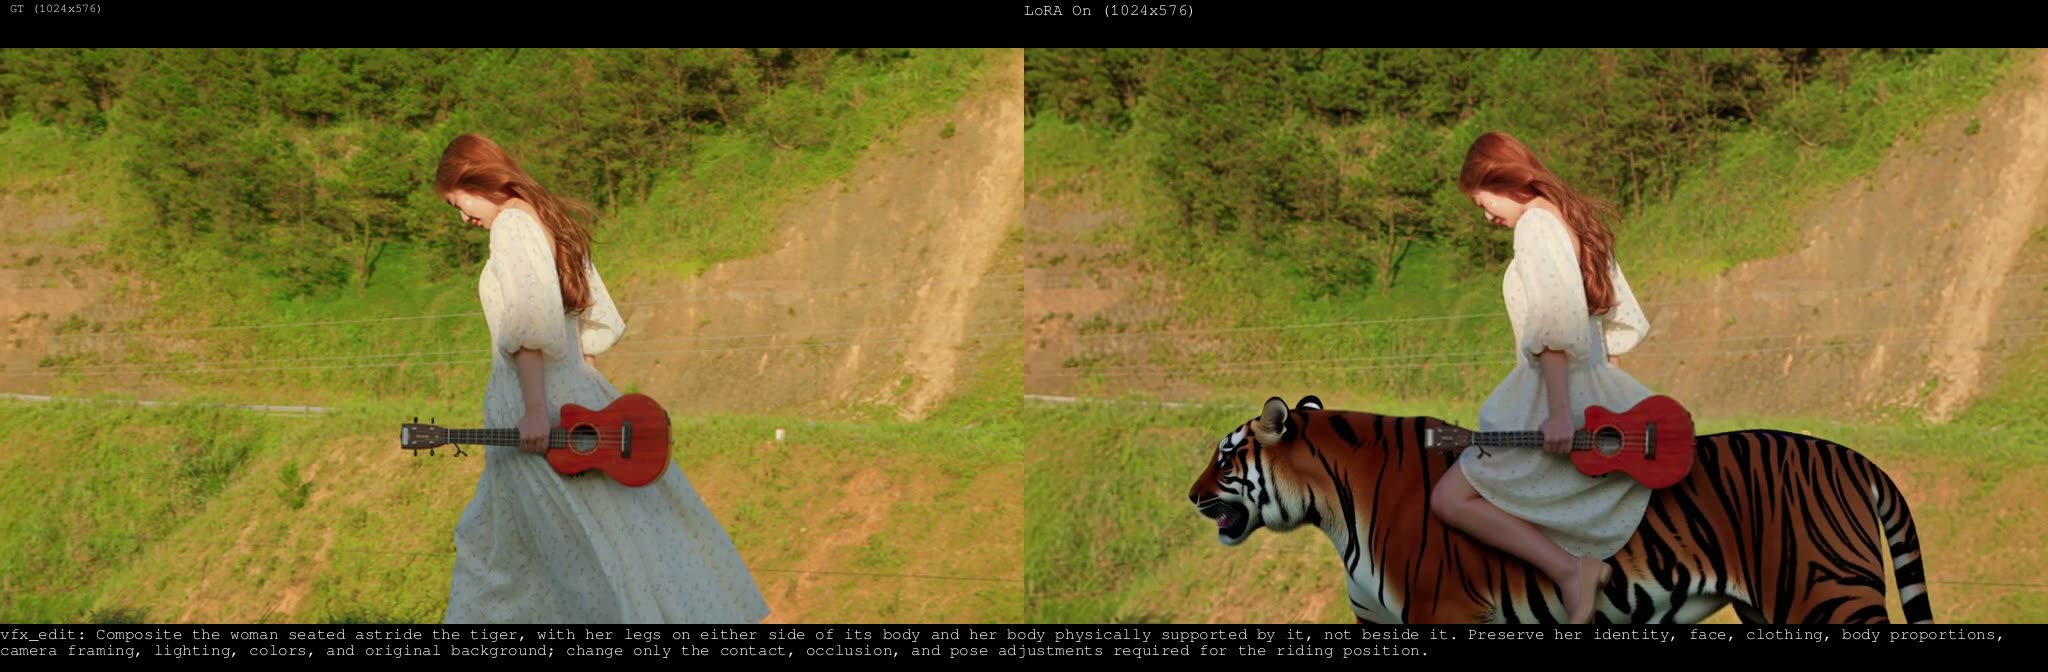
Alissonerdx's MiniMax H3 LoRA pack adds prompt-directed VFX Edit plus documented Style Transfer and Head Swap adapters, with ComfyUI workflows and example clips.
Apache-2.0
 Inpainting
Alibaba PAI's ControlNet Union 2.0 for MiniMax H3 adds Scribble, Layout and Gray control and doubles the injection blocks, with same-day ComfyUI support.
minimax-h3-community-license-agreement
 Video editing
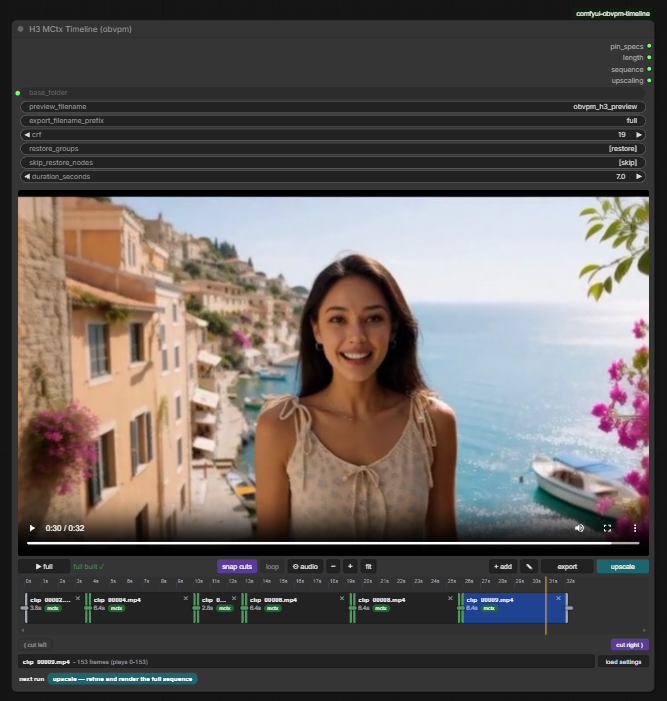
comfyui-obvpm-timeline adds a mini video editor to ComfyUI for MiniMax H3: extend, prepend, bridge and loop clips with latent-grade joins and a one-pass upscale.
GPL-3.0
 Text to image
SupraLabs releases Supra2-IMG, a 105M-parameter DiT text-to-image model trained from scratch in 10 hours on one H100, with samples at 256x256.
Apache-2.0
 Text to image
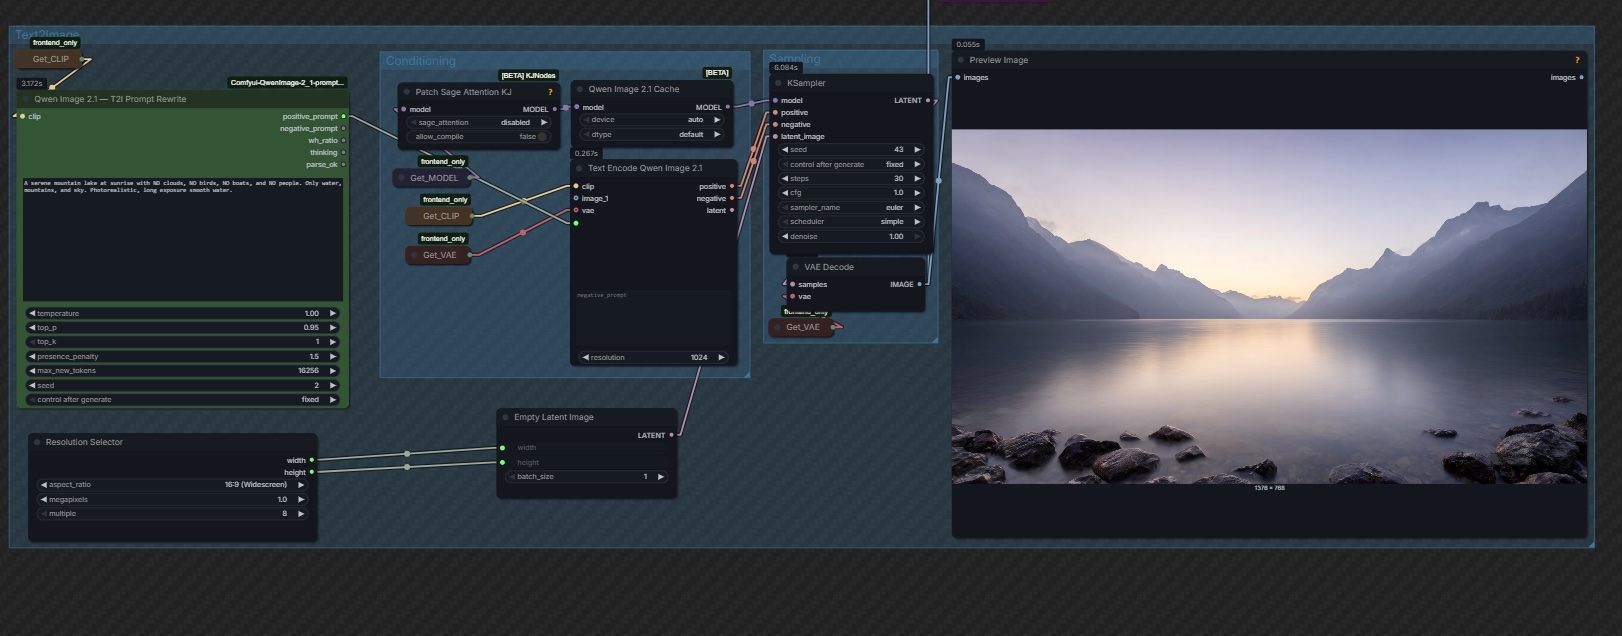
Qwen's PE-T2I and PE-I2I prompt rewriting models expand short requests and edit instructions, and a community node pack runs both in ComfyUI through Load CLIP.
 Ecosystem
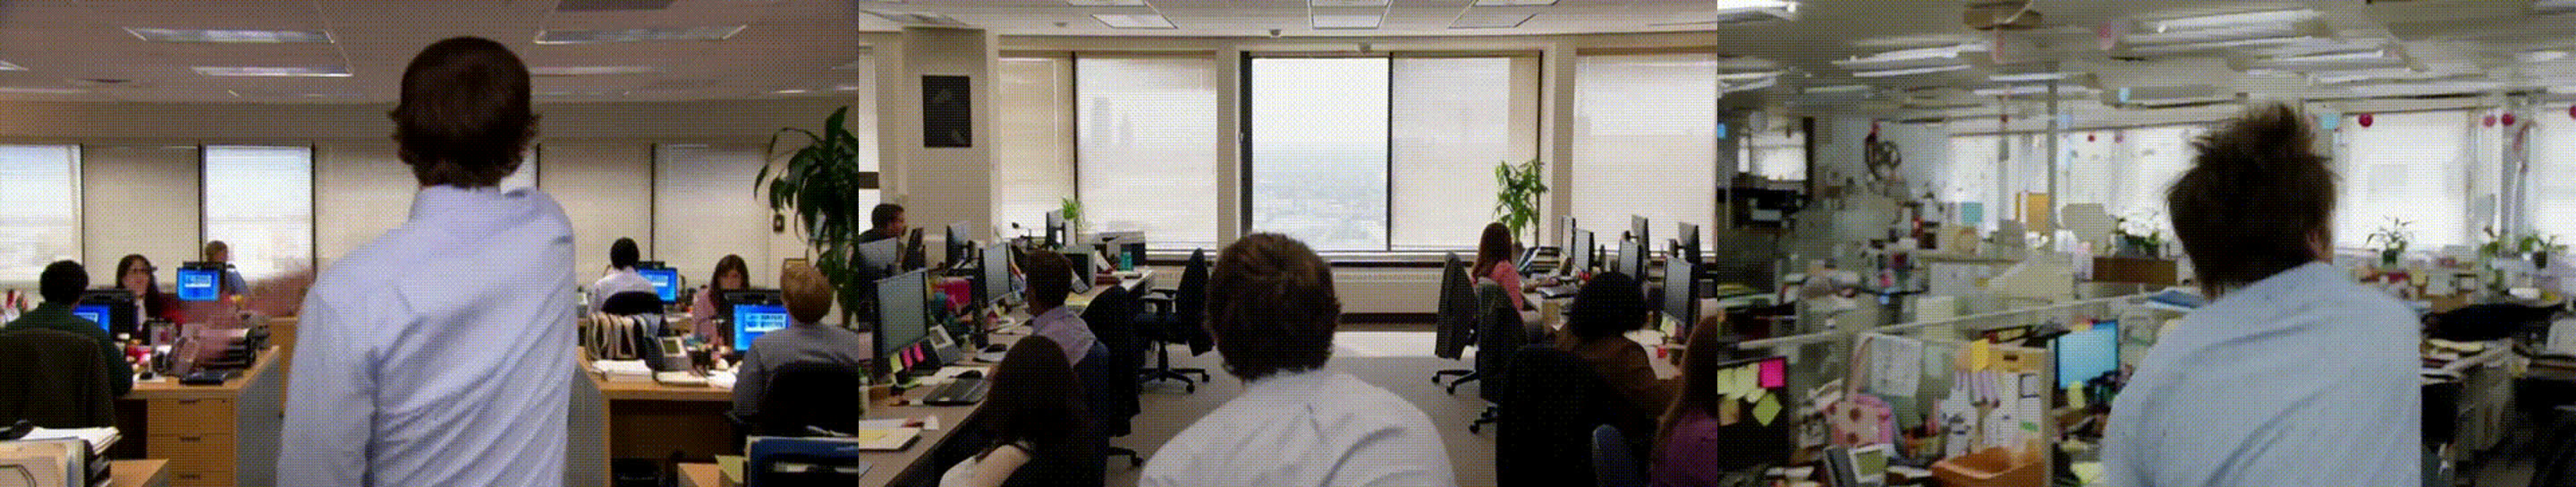
Cseti ports CrossView-Warp to MiniMax H3: a Ref2VA LoRA plus a ComfyUI node that re-renders existing footage from a new camera angle using a MoGe depth warp.
MiniMax-H3-Community
 Ecosystem
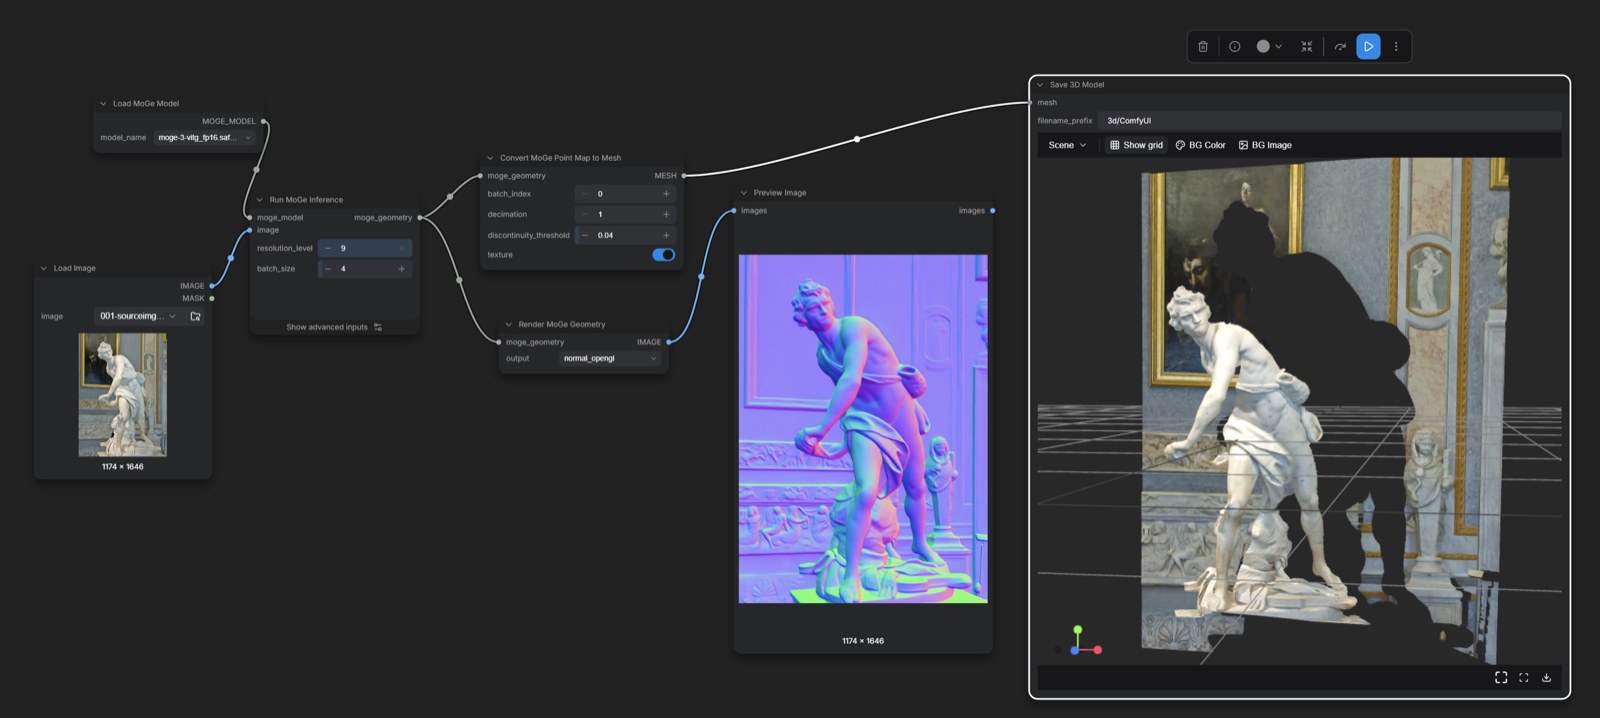
ComfyUI v0.37.0 adds native Qwen-Image 2.1 support with three official templates, MoGe 3 geometry estimation, faster Qwen3.8 text encoders and automatic fast disk loading.
 Text to video
ComfyUI-MiniMax-H3-SPEED V2 supports Euler, Heun, DPM2 and RES Multistep, adds a sampler-aware Sigma Harvest, and fixes I2V keyframe resizing.
 Text to image
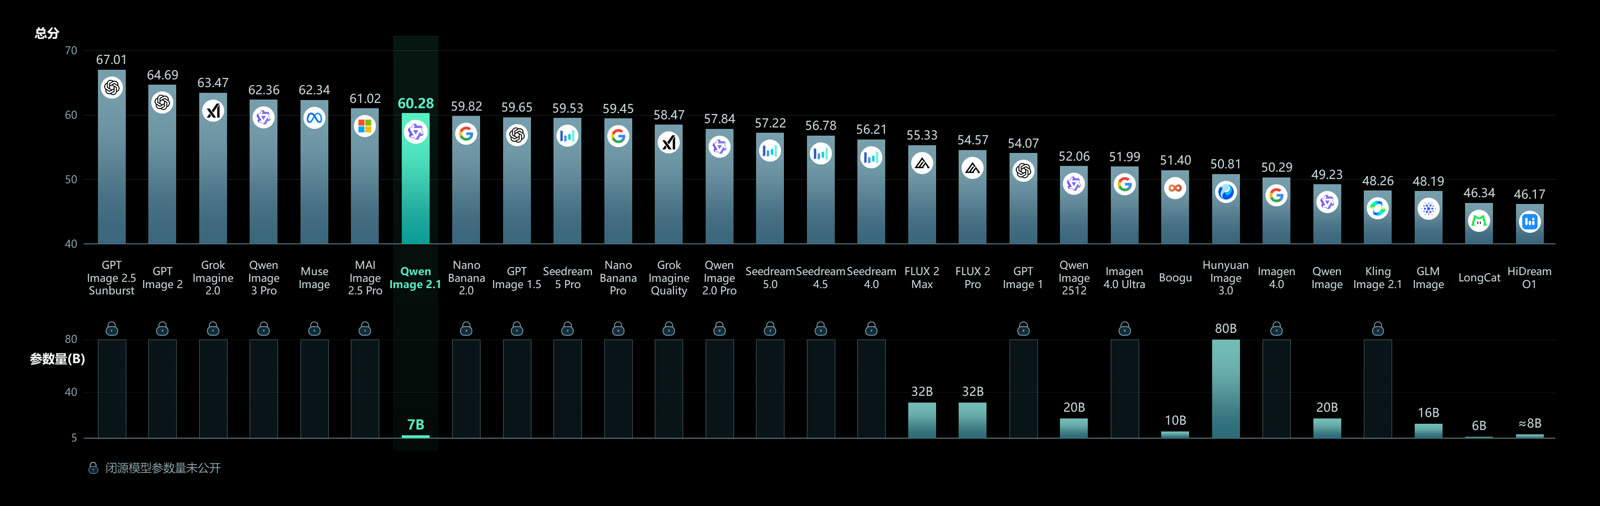
Download Qwen-Image 2.1 for ComfyUI: qwen_image_2.1_bf16 and int8_convrot safetensors, qwen3vl_8b encoder and official 2K text-to-image, edit and background removal workflows.
Qwen Research License