Texture-Fix-VAE: A Cleaner VAE Decoder for Qwen-Image 2.1
madebyollin's Texture-Fix-VAE retrains the Qwen-Image 2.1 VAE decoder to remove checkerboard texture artifacts. Drop the file into ComfyUI/models/vae and load it as usual.
ComfyUI/models/vae/ and select it in the Load VAE node.
Qwen-Image 2.1 denoises in a compressed latent space, and the VAE decoder is the last step that turns that latent back into pixels. Whatever the decoder cannot reconstruct cleanly is baked into the finished image, no matter how good the sampling was. Users have been describing the symptom since launch: a faint two-pixel grid and a slightly dithery look in busy areas such as foliage, hair and fabric.
Texture-Fix-VAE attacks that step specifically. The encoder is untouched, so the latent format, the sampling schedule and every LoRA or quantized checkpoint keep working unchanged.
Before and after
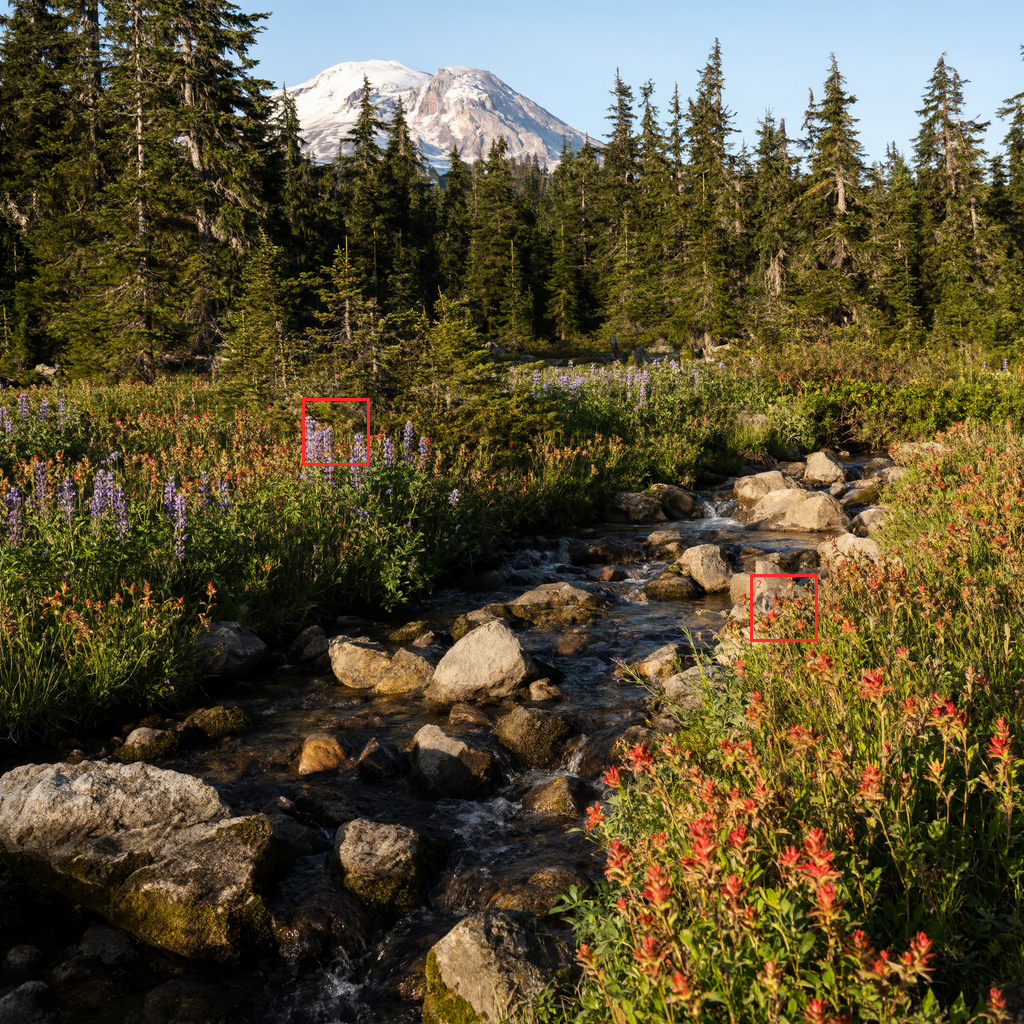
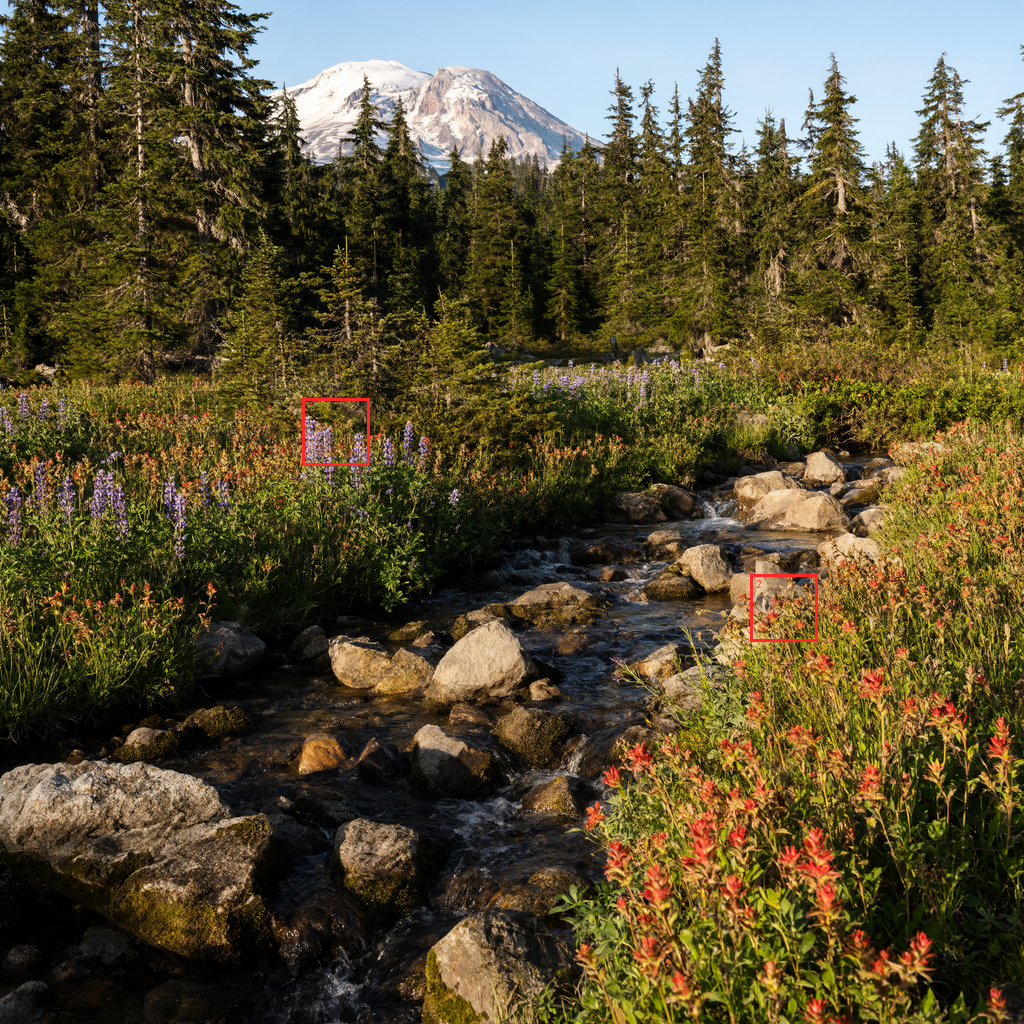
The author generated the latents for the comparison below with Qwen-Image 2.1 from a photo-style prompt full of fine texture:
Landscape photograph of a subalpine wildflower meadow in the Pacific Northwest in midsummer: a clear mountain stream winding over mossy boulders through purple lupine and red paintbrush, dense old-growth Douglas fir and western red cedar forest behind, a snow-capped volcano in the distance, golden late-afternoon light, highly detailed
Both columns decode the same latents, so any difference is the decoder alone.
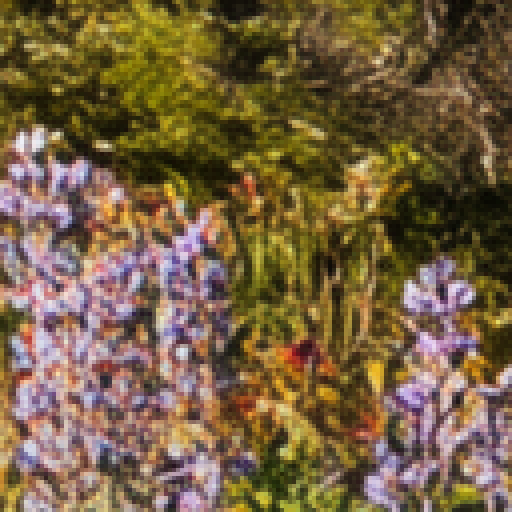 | 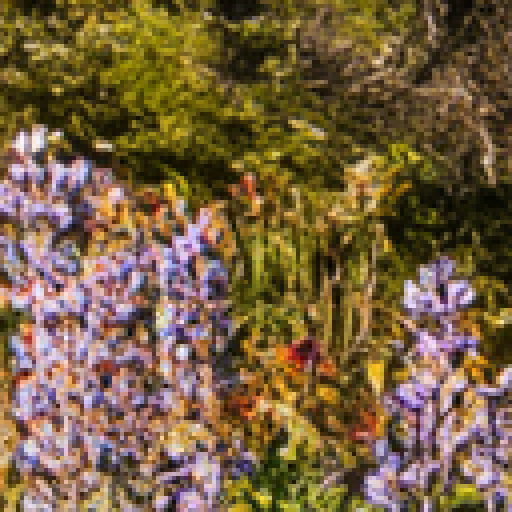 |
|---|---|
| Stock VAE, zoomed crop | Texture-Fix-VAE, same crop |
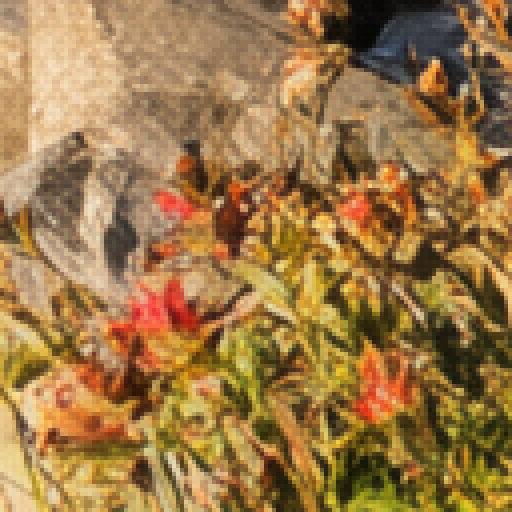 | 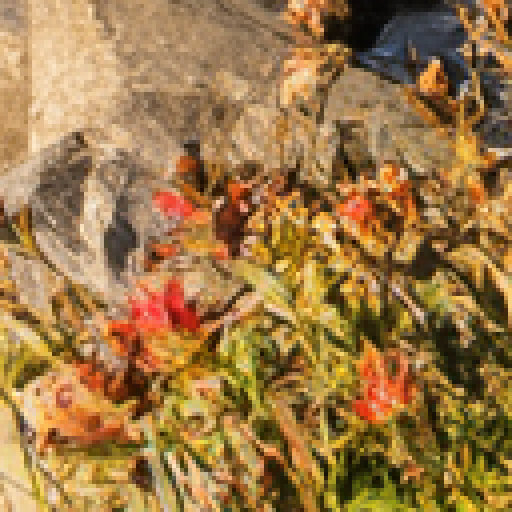 |
|---|---|
| Stock VAE, second zoomed crop | Texture-Fix-VAE, same crop |
 |  |
|---|---|
| Stock VAE, full 1024 x 1024 decode | Texture-Fix-VAE, full decode |
What changed inside
Only the decoder was finetuned, for roughly 5,000 steps at a learning rate of 3e-5. The two highest-resolution decoder stages and the output head were left unfrozen, which comes to about 7.5M trainable parameters, and training used the recipe the author developed for TAESD.
That recipe mixes three loss families, and each one pushes reconstruction in a different direction:
| Loss | What it rewards |
|---|---|
| MSE / MAE (PSNR-focused) | Safe averaging, which blurs detail it cannot place |
| LPIPS | Perceptual plausibility, which for fine texture shows up as blurring plus checkerboarding |
| Adversarial (GAN) | Sharp, plausible detail that looks real instead of obviously synthetic |
The adversarial term is what makes the difference here. The author's read is that the original Qwen-Image 2.1 VAE was trained without a working adversarial loss term, which would explain the grid: the perceptual term was free to push toward checkerboarding because nothing was penalising obviously fake structure.
Metrics
| Metric | Qwen-Image 2.1 VAE | Texture-Fix-VAE |
|---|---|---|
| rFID, lower is better (COCO val2017, 5000 images at 256²) | 3.37 | 2.08 |
| PSNR, higher is better (COCO val2017 at 256²) | 33.30 | 32.86 |
| LPIPS, lower is better (COCO val2017 at 256²) | 0.0357 | 0.0373 |
| PSNR, higher is better (DIV2K valid, native 1024² crops) | 32.86 | 32.46 |
| LPIPS, lower is better (DIV2K valid, native 1024² crops) | 0.0460 | 0.0480 |
This is the usual trade for a GAN-style decoder: perceptual quality (rFID) improves by roughly a third while reconstruction accuracy (PSNR and LPIPS) slips very slightly. The author notes the improvement is most visible on detailed, photo-style images rather than flat illustrations.
Using it in ComfyUI
Download texture_fix_vae_for_qwen_image_2.1_bf16.safetensors into ComfyUI/models/vae/, then pick it in the Load VAE node in place of qwen_image_2.1_vae_bf16.safetensors. No node, workflow or sampler change is needed, and the file can be swapped back at any time.
Outside ComfyUI the same weights load as a normal diffusers VAE:
import torch
from diffusers import QwenImage21Pipeline, AutoencoderKLQwenImage21

vae = AutoencoderKLQwenImage21.from_pretrained(
    "madebyollin/texture-fix-vae-for-qwen-image-2.1", torch_dtype=torch.bfloat16
)
pipe = QwenImage21Pipeline.from_pretrained(
    "Qwen/Qwen-Image-2.1", vae=vae, torch_dtype=torch.bfloat16
).to("cuda")
Availability
Weights: madebyollin/texture-fix-vae-for-qwen-image-2.1
ComfyUI file: texture_fix_vae_for_qwen_image_2.1_bf16.safetensors
Base model: Qwen/Qwen-Image-2.1
Author's earlier work: TAESD, sdxl-vae-fp16-fix
Comments
Sign in with GitHub to join the discussion.