Qwen-Image 2.1 Fun ControlNet Union: 8 Controls in One File
Alibaba PAI's ControlNet Union for Qwen-Image 2.1 packs eight structural controls and inpainting into one 7.5 GB branch, now with merged ComfyUI support.
Qwen-Image 2.1 landed on September 20, 2026 as a 7B single-stream DiT that generates and edits with the same weights and writes real RGBA alpha. The ControlNet-Union branch follows the same path Alibaba PAI took for MiniMax H3: a single control checkpoint that covers every condition, so no per-condition weight switching is needed.
One branch, eight conditions
The released file holds only the control branch (control_img_in plus 16 control_blocks, about 7.0 GB per the model card, 7.55 GB on disk). It is loaded with strict=False on top of the base Qwen-Image 2.1 transformer, which stays frozen, so the base weights are reused exactly as they are.
| Control conditions | Canny, Depth, Grayscale, HED, Lineart, MLSD, Pose, Scribble |
| Control branch depth | 16 blocks, one skip on every 2nd of the 32 transformer blocks (control_layers = [0, 2, 4, ..., 30]) |
| Control input width | control_in_dim = 129: control latents (64) + mask (1) + masked-image latents (64) |
| Injection | zero-gated before_proj / after_proj on each control block, added back into the main branch |
| Sampling | CFG-distilled, example scripts run at guidance_scale = 1.0 (one forward pass per step) |
| Text encoder / VAE | Qwen3-VL processor for prompt and condition image, VAE decodes RGBA so previews save as PNG |
control_context_scale scales every control skip before it is added to the main branch: 1.0 is the strongest setting used for all published results, lower values weaken the guidance, and 0.0 switches the control branch off.
Control conditions
| Condition | Control signal |
|---|---|
| Canny | Canny edge map |
| Depth | Monocular depth map |
| Grayscale | Grayscale (luminance) image |
| HED | HED edge detection map |
| Lineart | Line-art extraction |
| MLSD | Line-segment detection map |
| Pose | DWPose skeleton |
| Scribble | Free-hand or sketch lines |
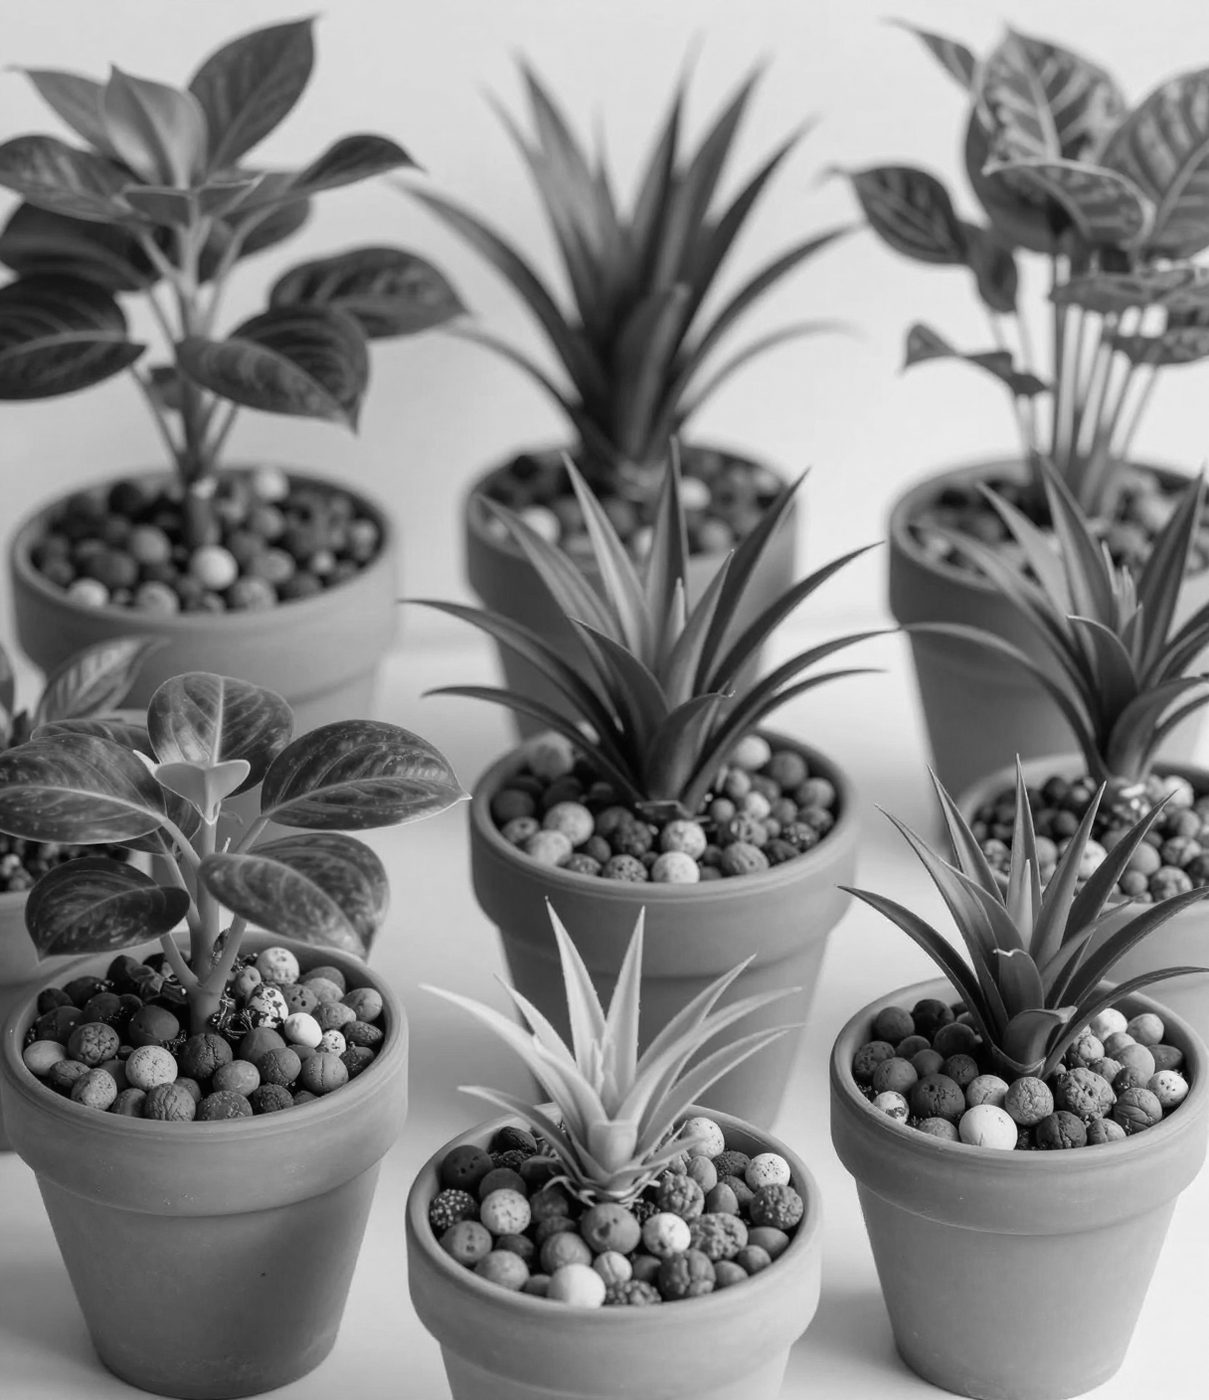
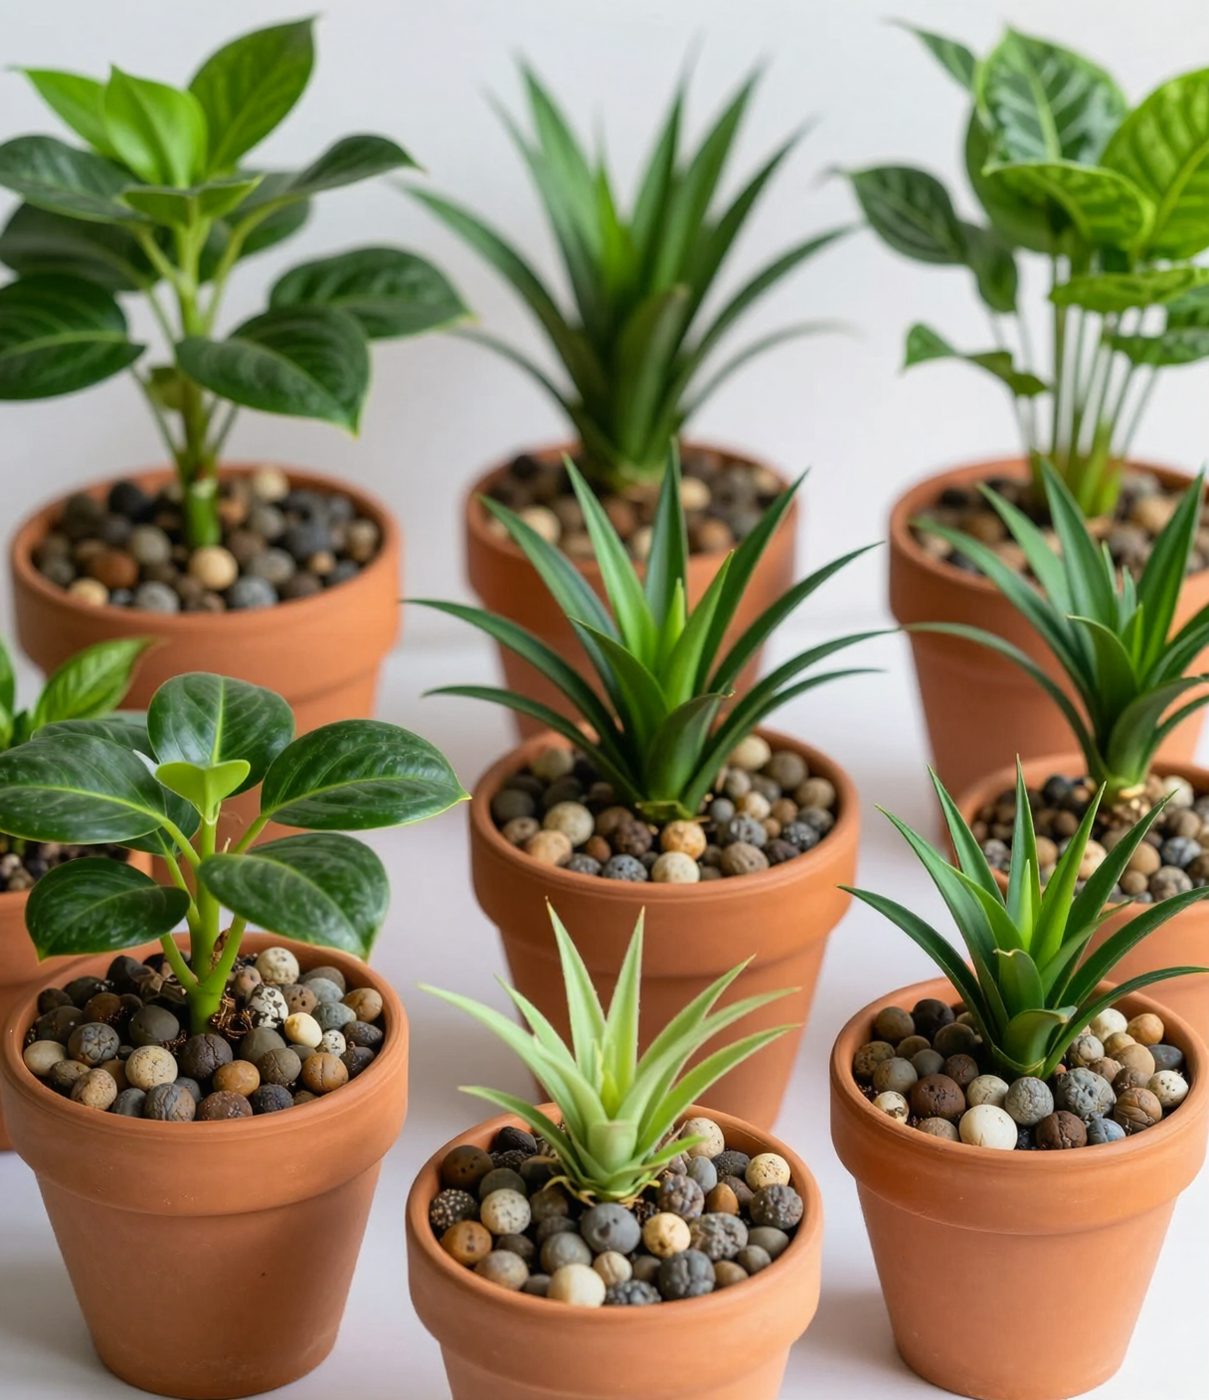
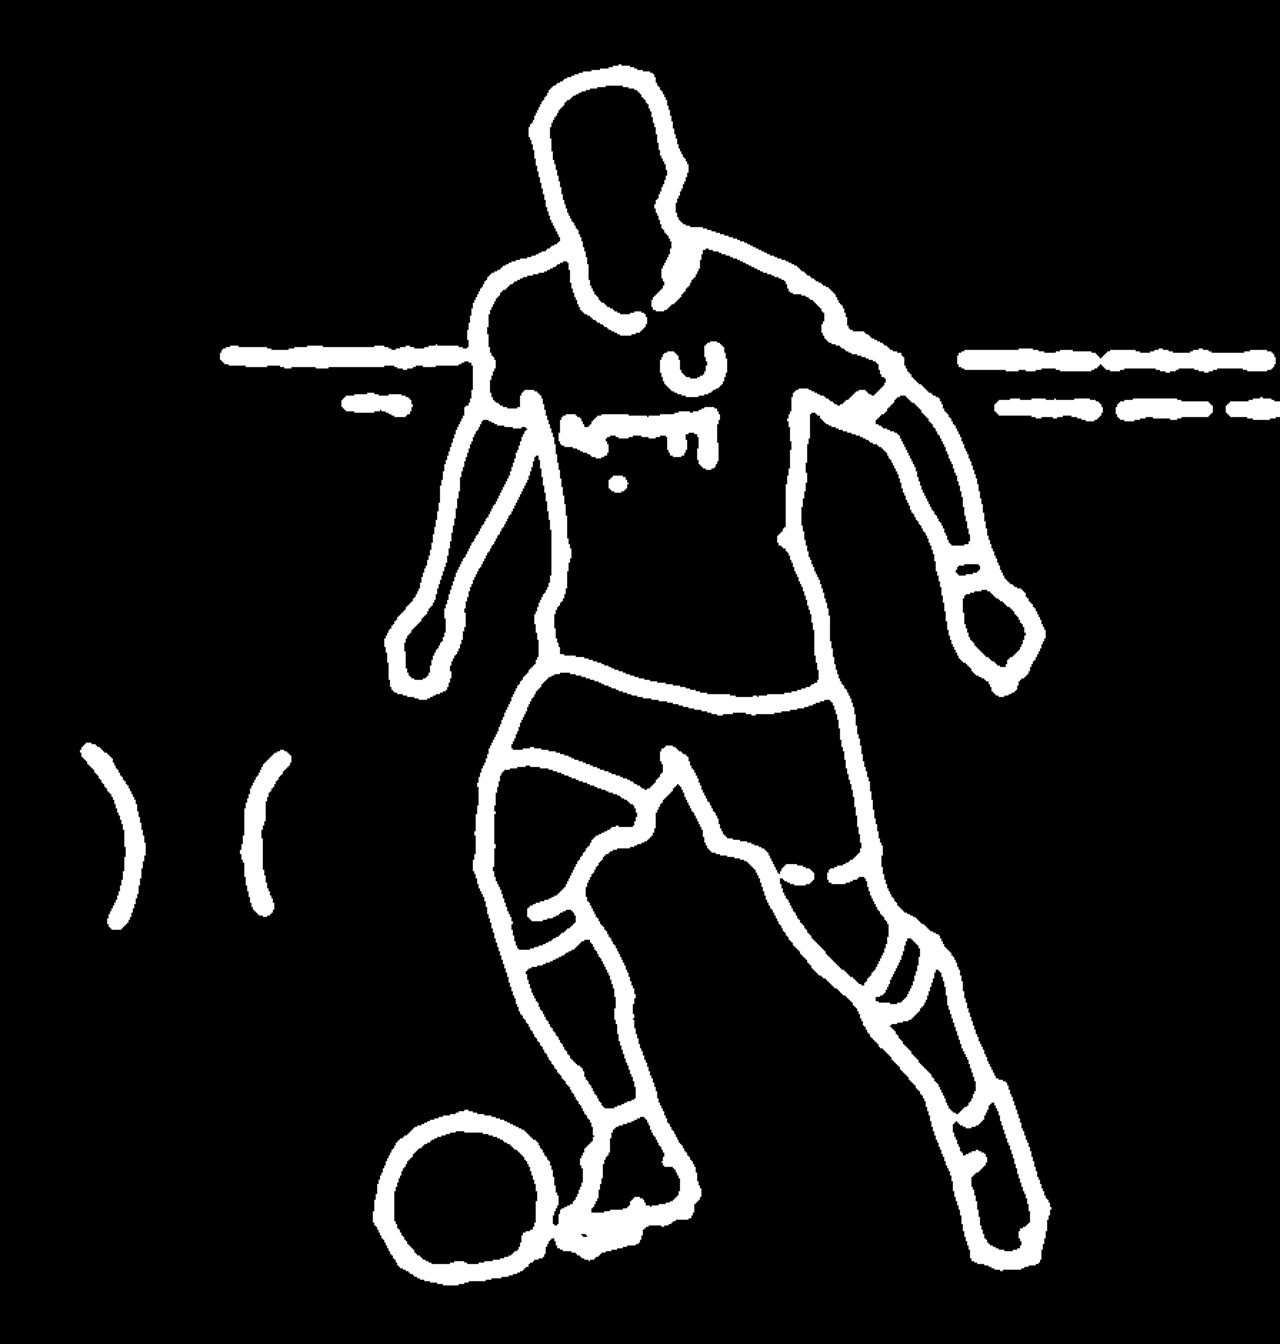
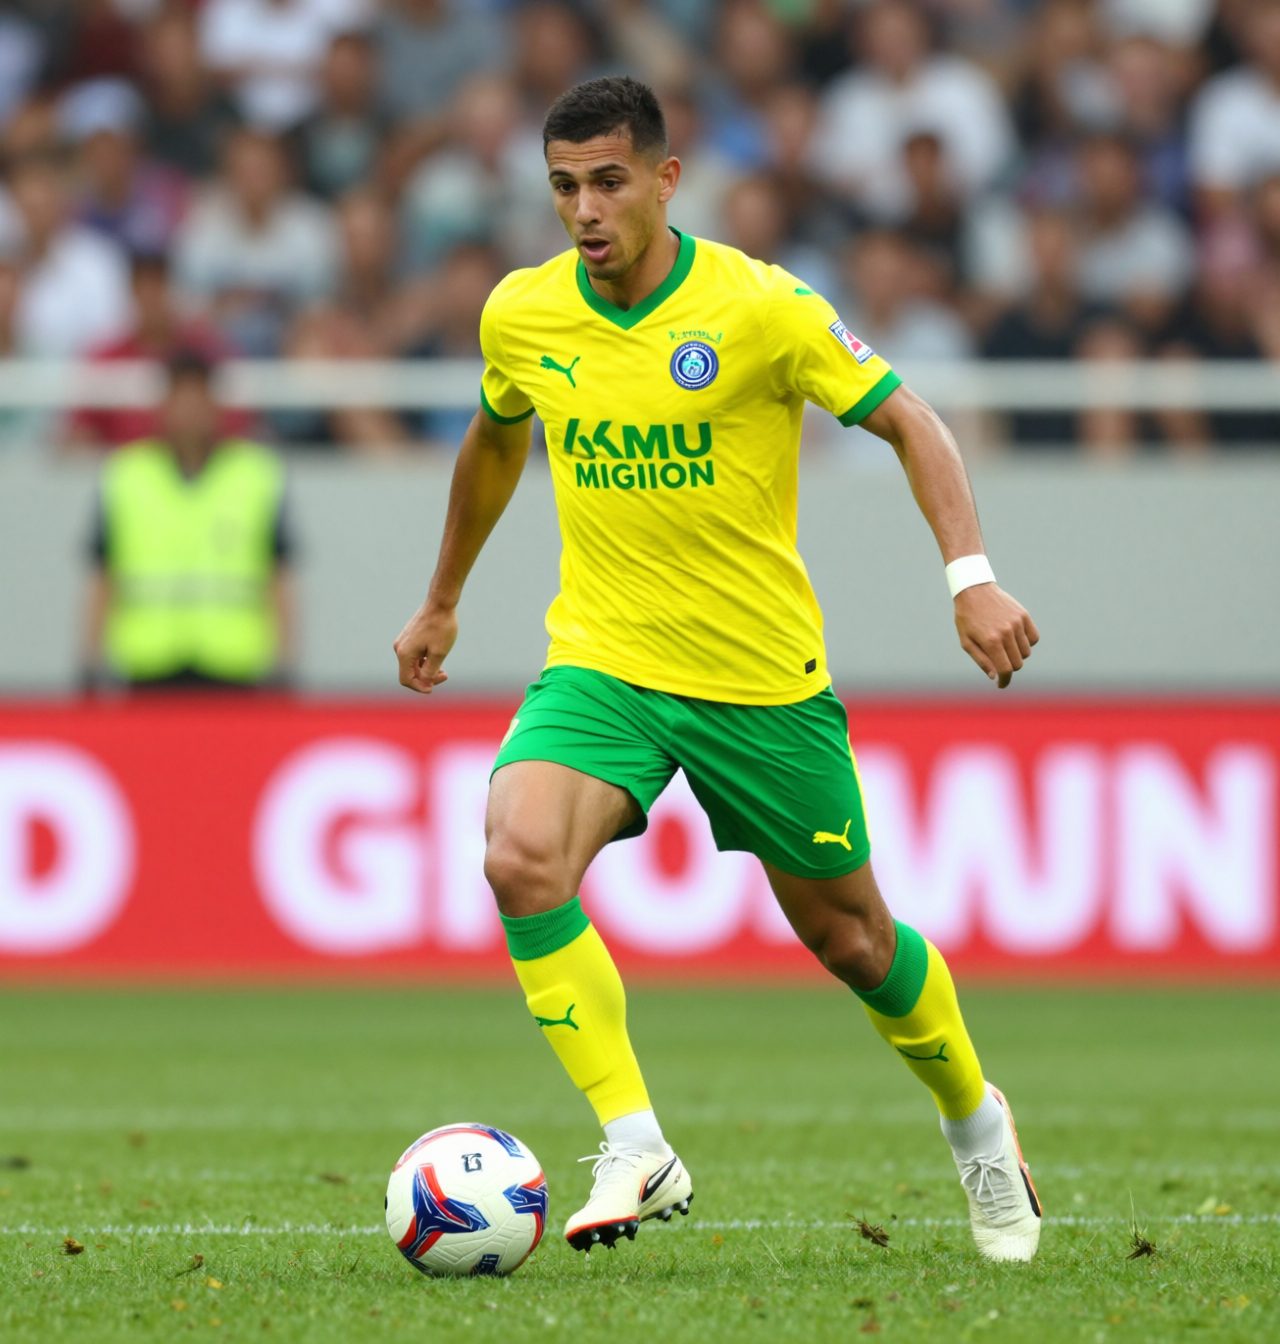
Any ordinary RGB control image at the target canvas works: the model card notes it tolerates different line thickness, thresholds and crops. All samples below come from the model card at 40 inference steps, control_context_scale = 1.0 and seed 43, with the control signal on the left and the generation on the right.
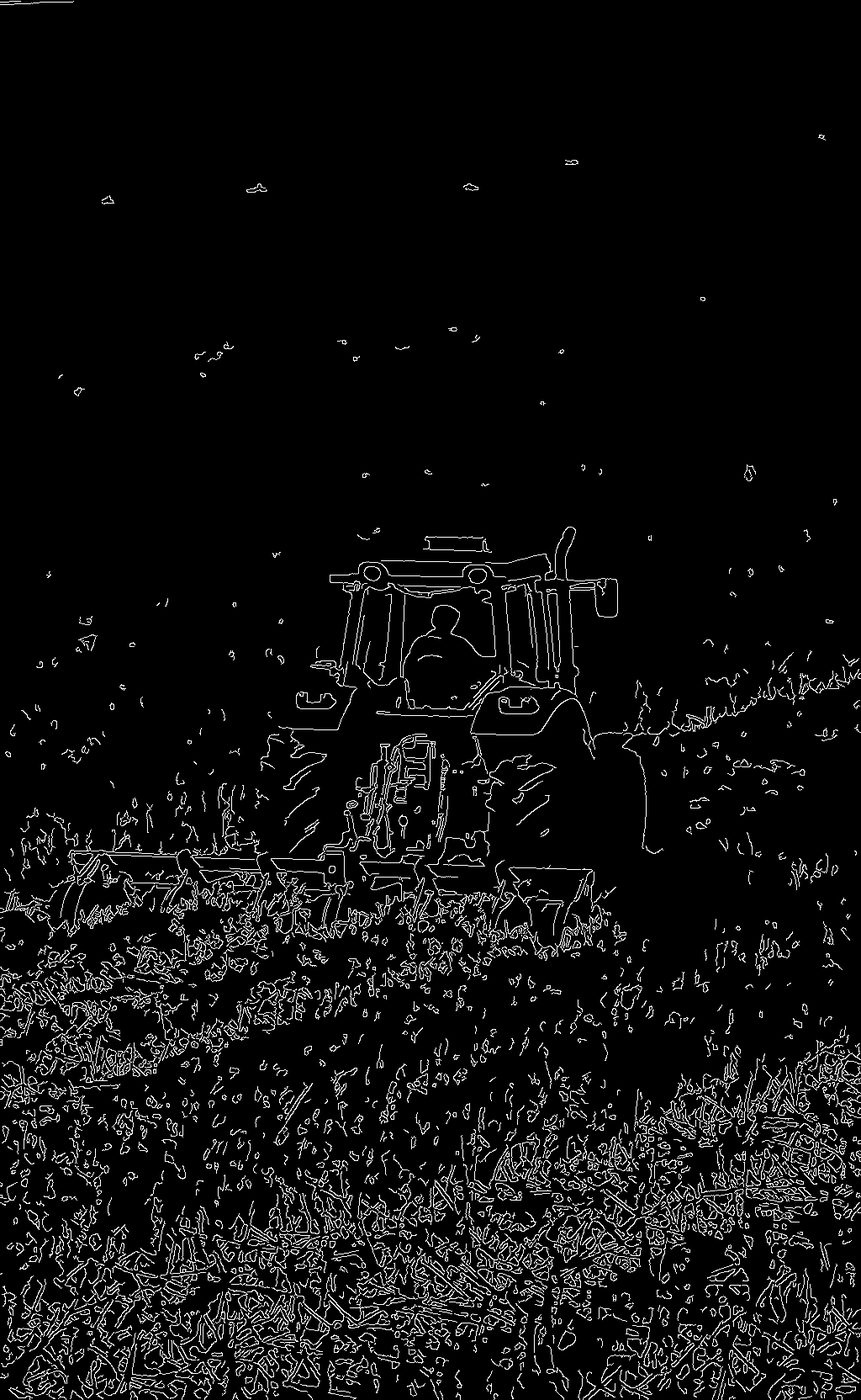 | 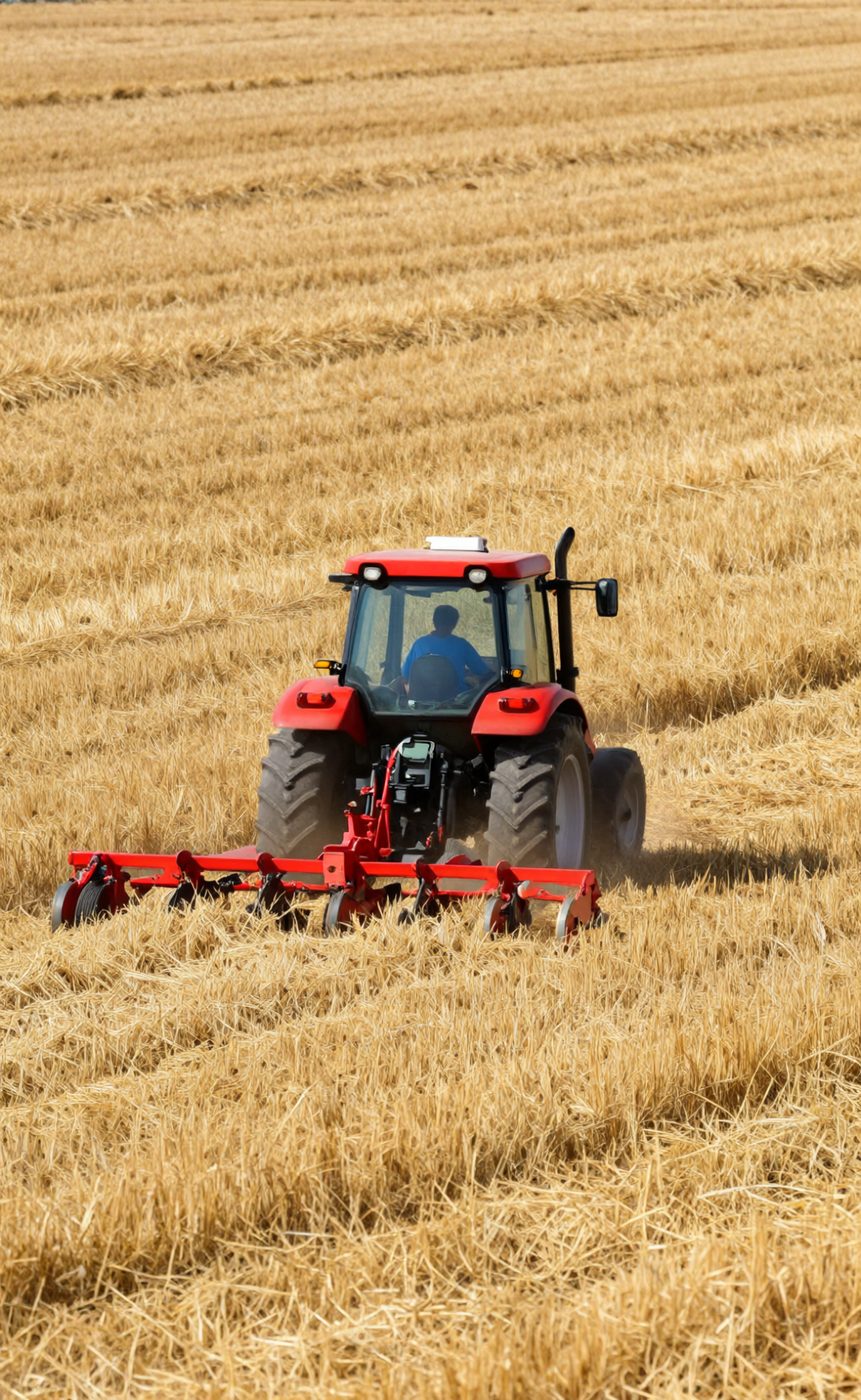 |
|---|---|
| Canny edge map | Generated output |
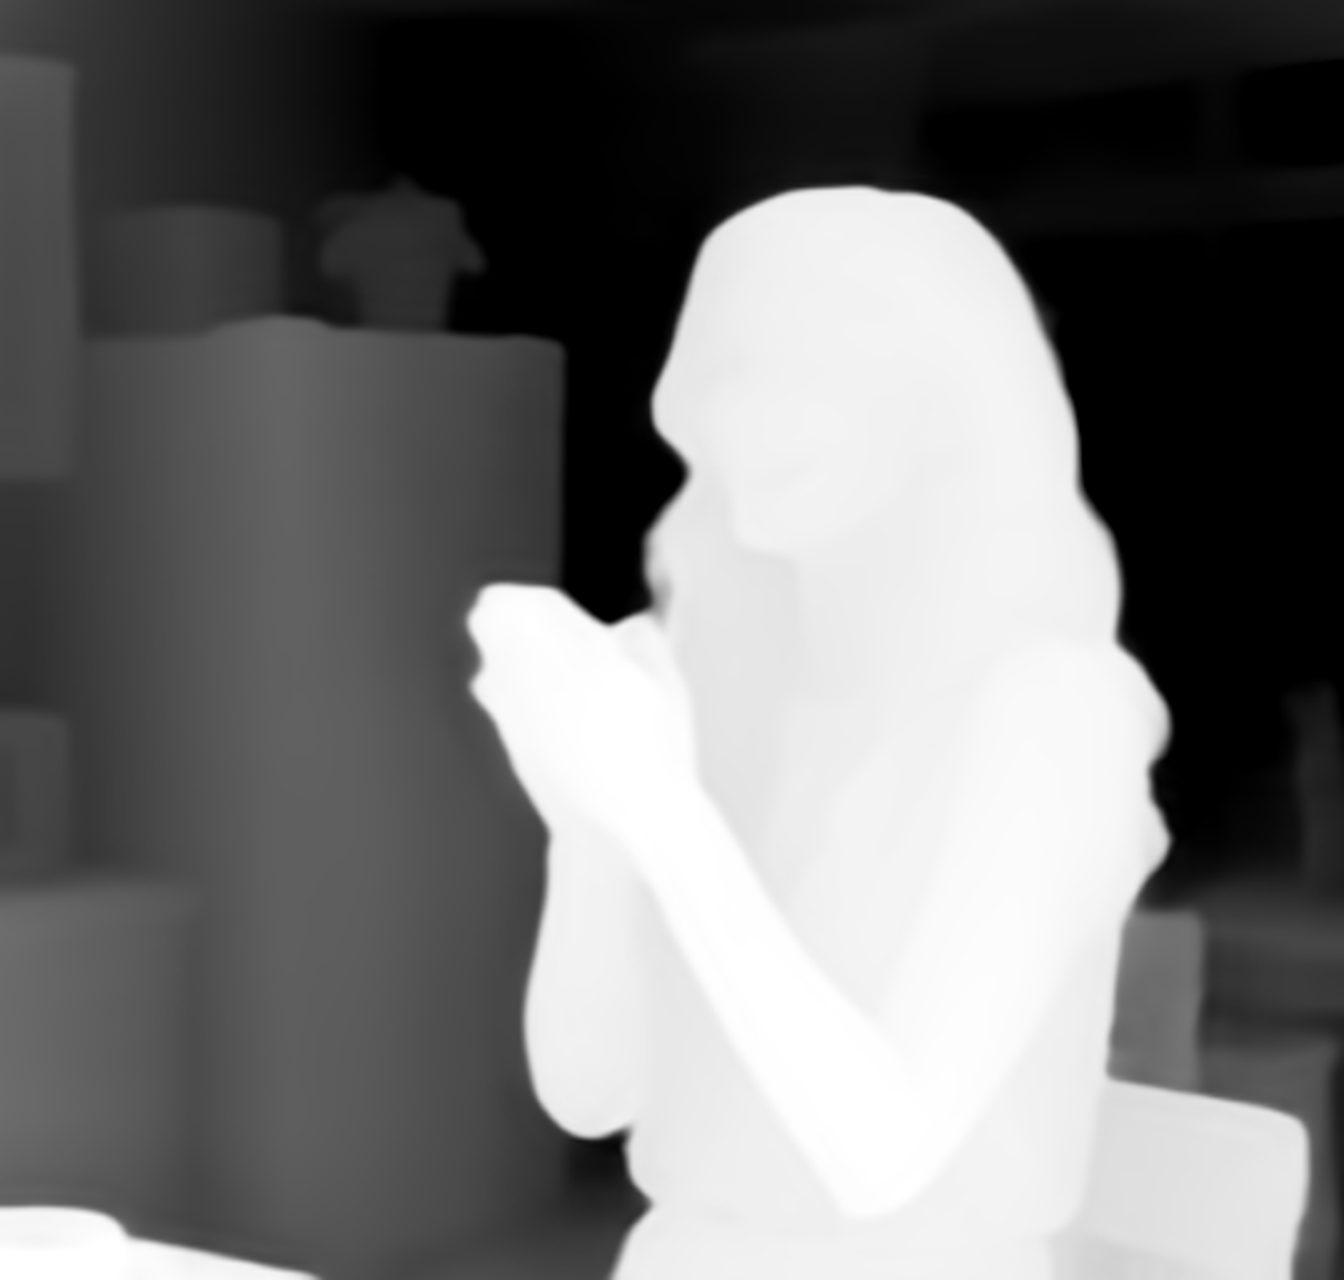 | 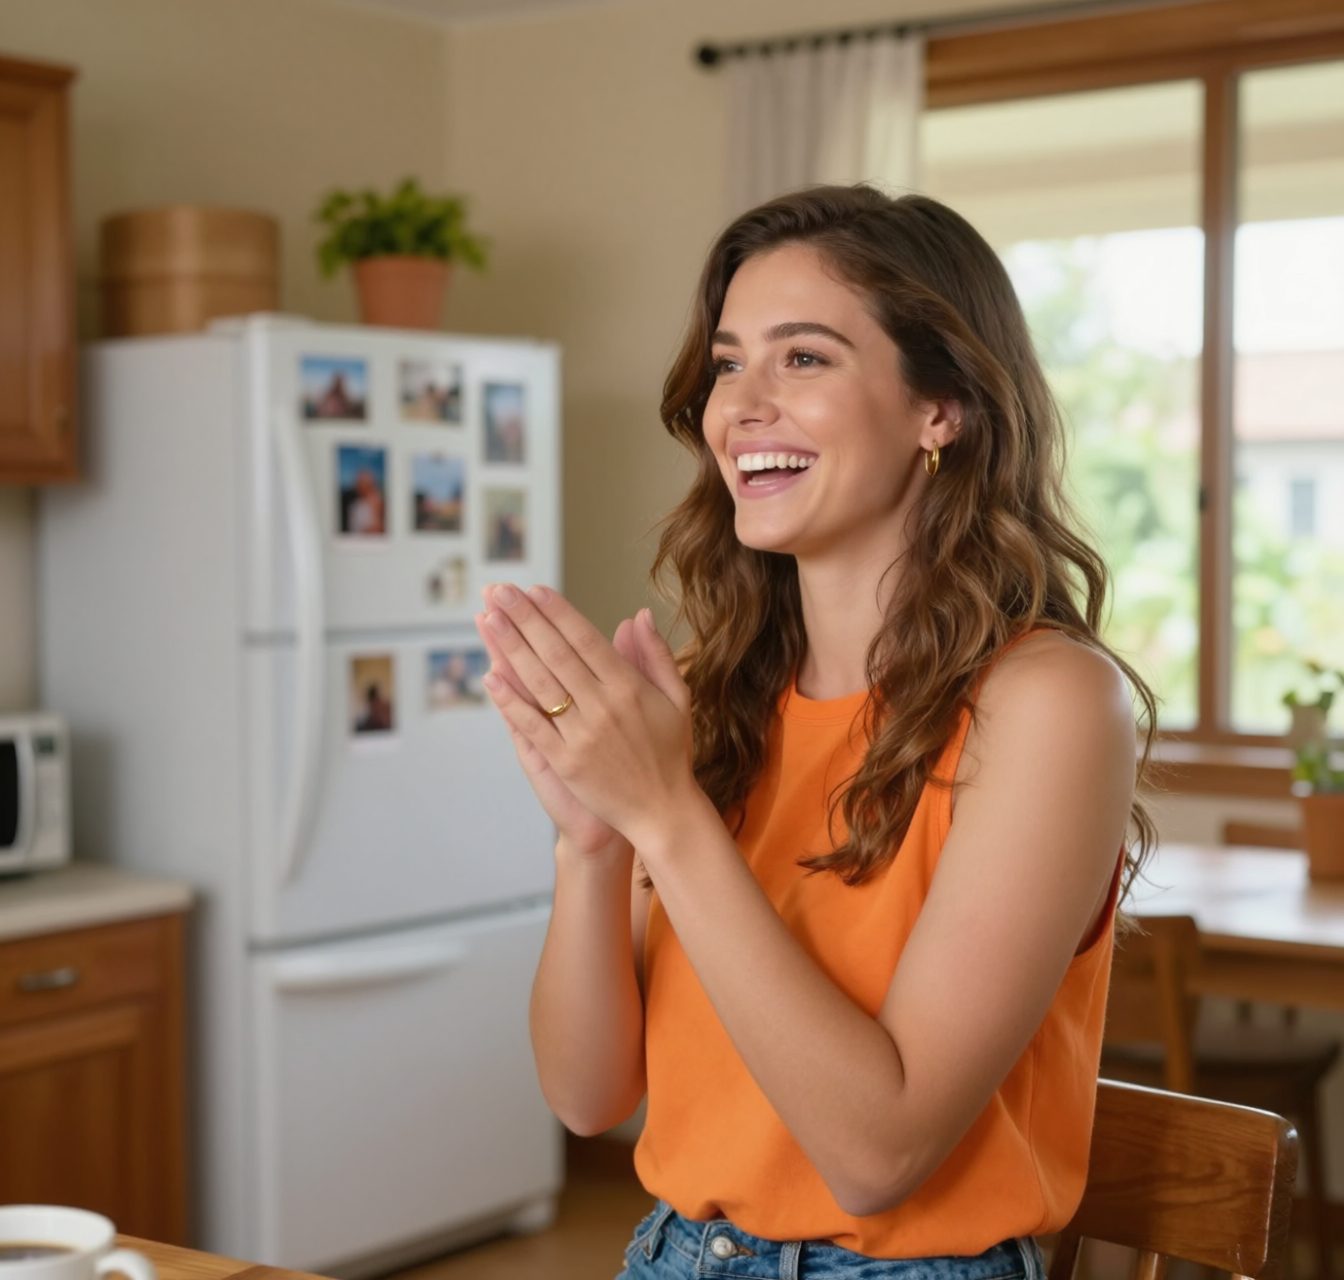 |
|---|---|
| Depth map | Generated output |
 |  |
|---|---|
| Grayscale image | Generated output |
 |  |
|---|---|
| Scribble sketch | Generated output |
The remaining conditions (HED, Lineart, MLSD, Pose) follow the same pattern on the model page.
Inpainting shares the same branch
The control input is widened to 129 channels precisely so one branch can do both jobs: control latents, a keep-mask and masked-image latents are concatenated before they enter the branch. For pure control the mask and masked-image channels are zero-padded, so the same checkpoint still runs plain Canny or Depth. For inpainting the masked region is re-drawn from the prompt while the rest of the frame is preserved, and the two can be combined: feed a control image together with a mask and the re-drawn region follows both the prompt and the given structure.
The mask is white where content should be regenerated and black where it should be kept. Regenerated pixels are encoded at mid-gray, the zero of the VAE's [-1, 1] input range, so untouched areas survive the round trip.
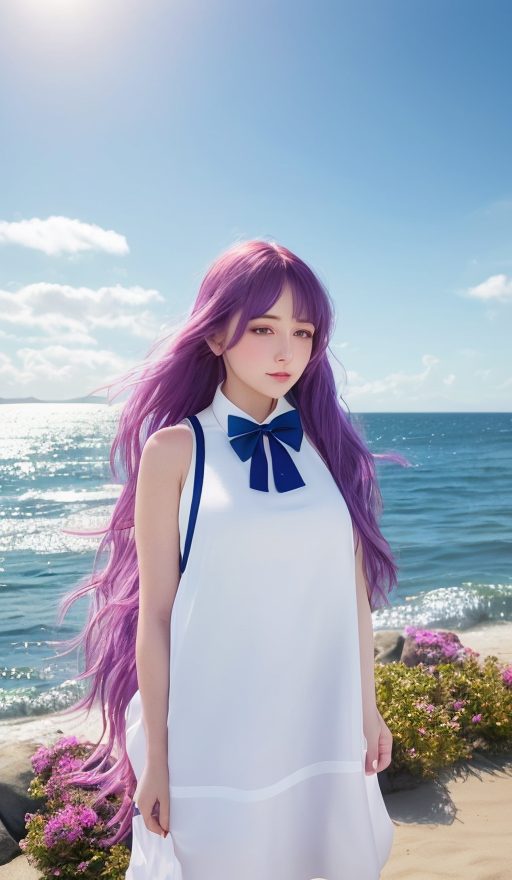 | 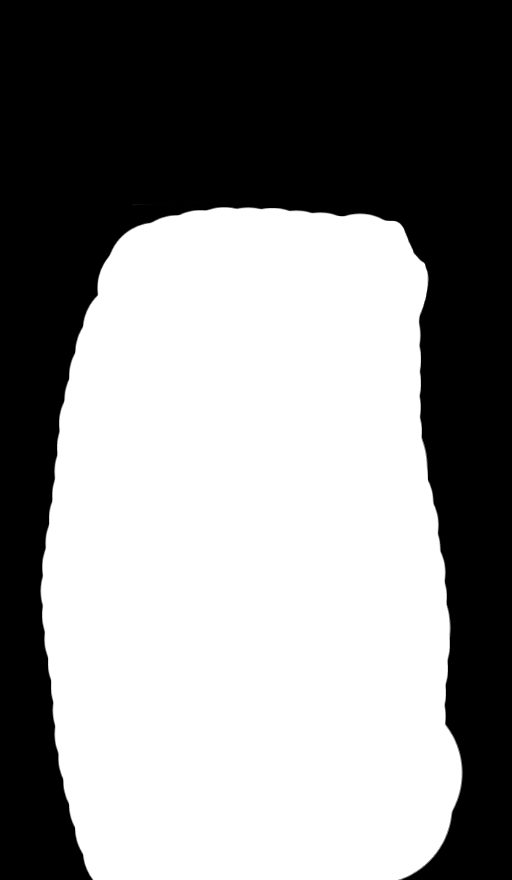 | 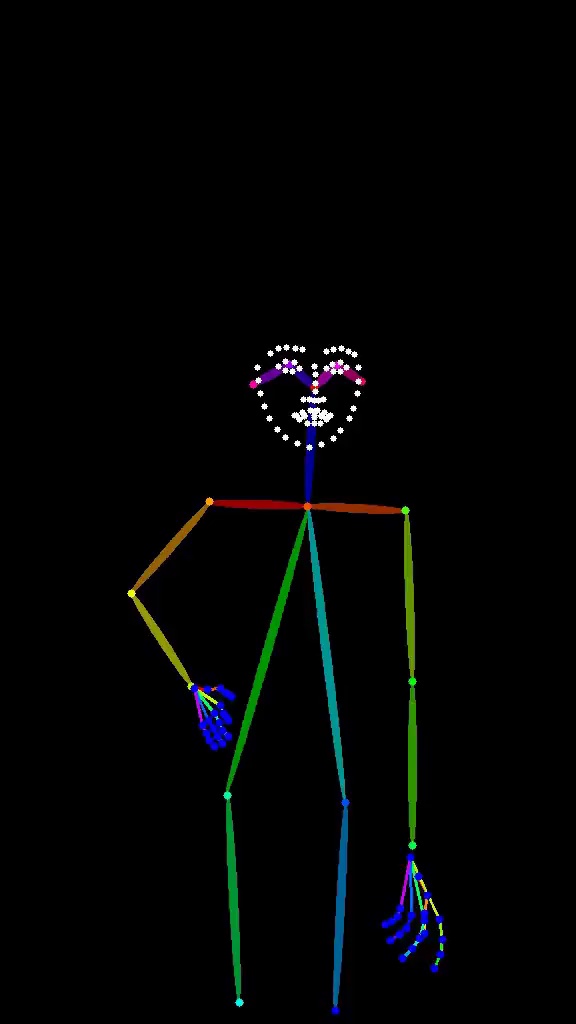 | 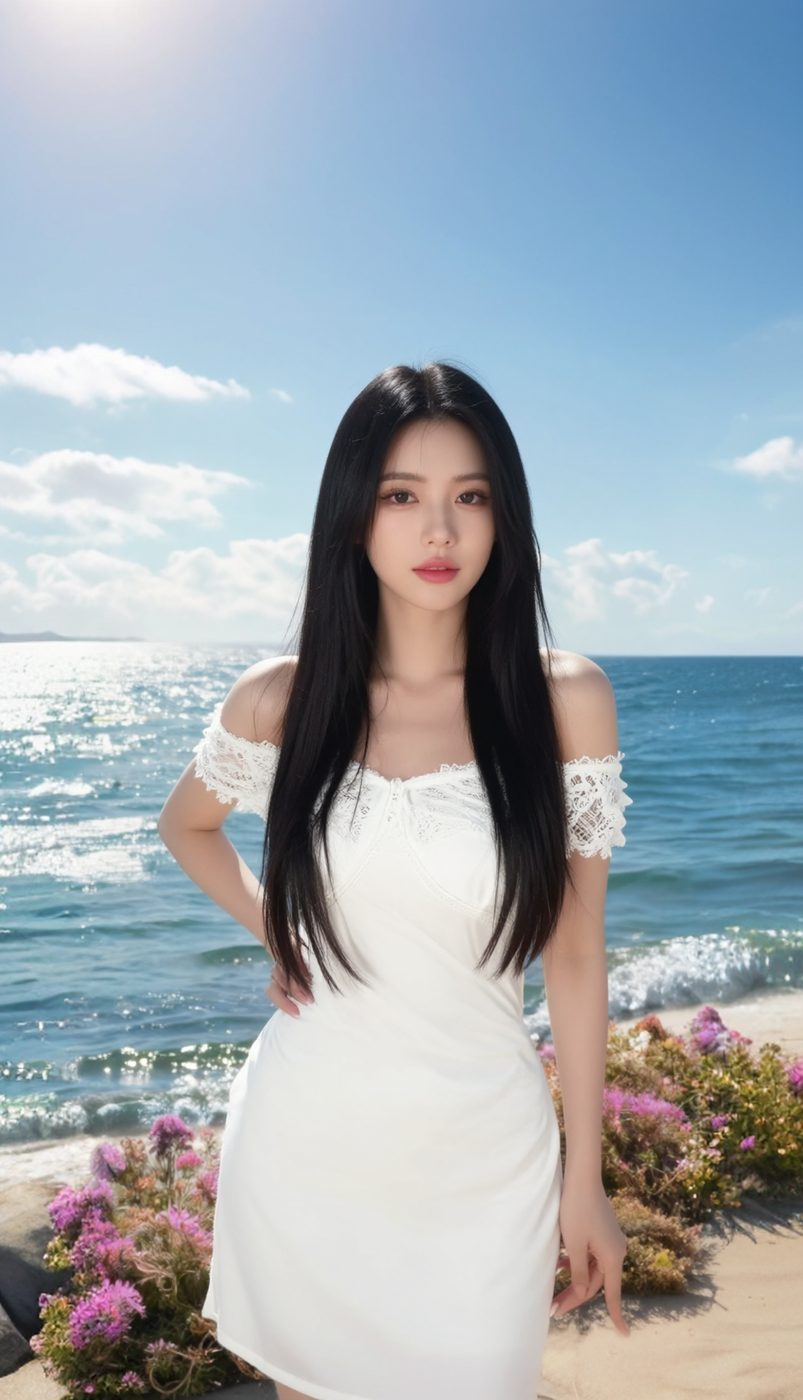 |
|---|---|---|---|
| Source image | Mask | Pose control | Inpaint output |
ComfyUI support
ComfyUI support merged into core on September 28, 2026 in PR #16519 ("Support Qwen-Image 2.1 union fun controlnet"), so the checkpoint loads in an unmodified install. The merged patch touches three files:
comfy/ldm/qwen_image21/model.pyaddsQwenImage21FunControlandQwenImage21FunControlBlock, a VACE-style branch that seeds the control latents into the target rows and adds each block'safter_projskip back after one base block.comfy_extras/nodes_model_patch.pyteaches ModelPatchLoader the layout: it detects the checkpoint bycontrol_img_inpluscontrol_blocks.0.img_mlp.out.weightand derives block count,control_in_dim, head dim and MLP ratio from the state dict, so one loader fits this checkpoint family. Quantized files load with mixed-precision ops, keeping the layers quantized with bf16 compute. The same file addsQwenImage21FunControlPatch, which installs a per-block replacement so the control skips are added back at the right single-blocks.comfy/controlnet.pytightens the Qwen Fun loader detection so the new checkpoint is not mistaken for an older ControlNet layout.
No new node class was added. The existing Apply Qwen Image DiffSynth ControlNet node (QwenImageDiffsynthControlnet) learned the Qwen-Image 2.1 path, so the graph is Load Model Patch then Apply Qwen Image DiffSynth ControlNet then the sampler, with required model, model_patch, vae, image and strength, plus optional mask, start_percent and end_percent.
Converted ComfyUI patches are published by Kijai:
- qwen_image_2.1_fun_controlnet_union_bf16.safetensors
- qwen_image_2.1_fun_controlnet_union_int8_convrot.safetensors
There is still no official workflow template for it in Comfy-Org/workflow_templates, so the previous Qwen-Image templates (image_qwen_image_controlnet_patch, image_qwen_image_instantx_inpainting_controlnet) are for older models and do not apply here.
Availability
Outside ComfyUI the checkpoint runs through VideoX-Fun: clone VideoX-Fun, put the base Qwen-Image 2.1 model and the control checkpoint under models/Diffusion_Transformer/, and run examples/qwenimage21_fun/predict_t2i_control.py (or predict_i2i_inpaint.py for inpainting). The branch was added there in the commit "Update Qwen Image 2.1 Control and Flex Forcing".
Four notes from the model card are worth keeping:
config_pathmust beconfig/qwenimage21/qwenimage21_control.yaml. It builds the control branch exactly as the checkpoint expects (control_layers: [0, 2, 4, ..., 30],control_in_dim: 129), and any other config silently drops or misplaces control weights and produces wrong output.sample_sizesets the output canvas. Keep both sides as multiples of 16 so the control map is not distorted.use_kv_cache = Truecaches text and condition-image keys after the first denoising step, which speeds up generation at a fixed resolution.- Memory: the transformer plus the Qwen3-VL text encoder do not fit a single consumer GPU fully loaded. The model card recommends
model_group_offloadas the fastest option, ormodel_cpu_offload_and_qfloat8on a single high-memory GPU.
Comments
Sign in with GitHub to join the discussion.