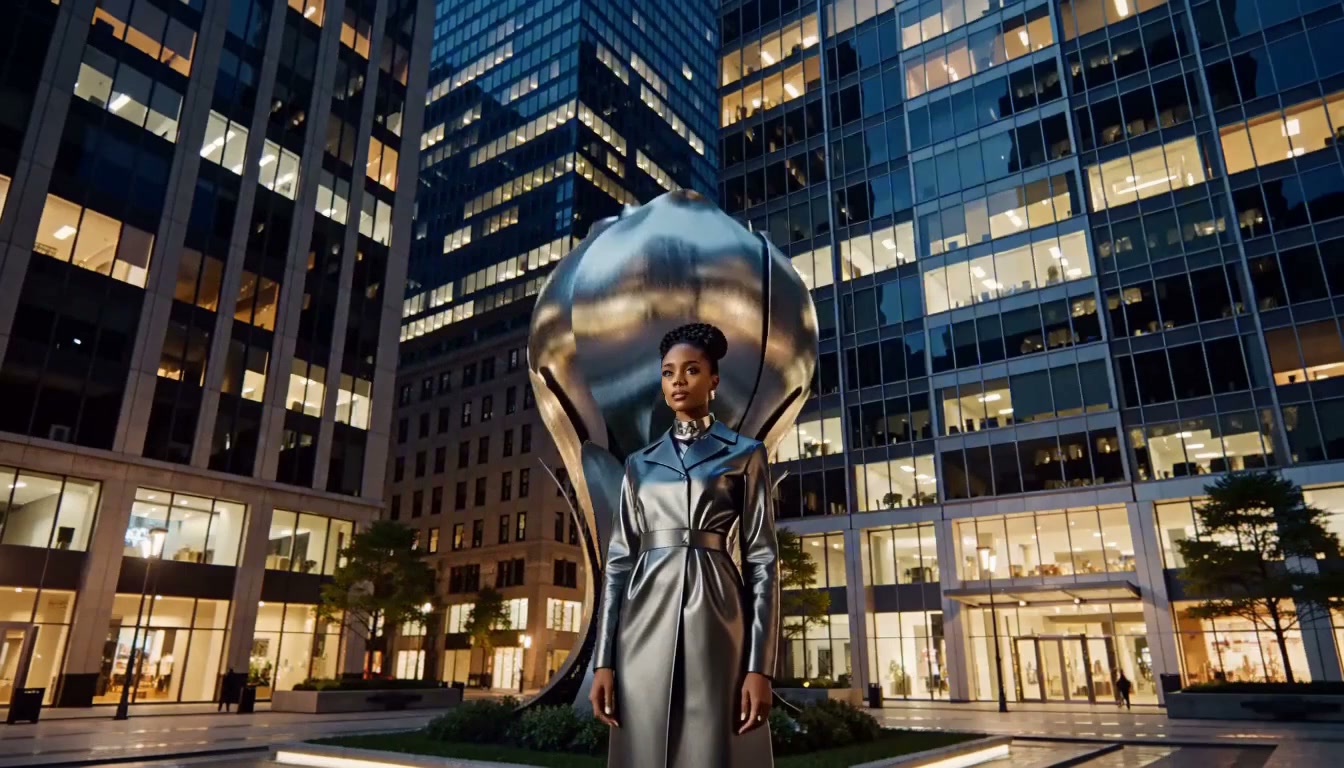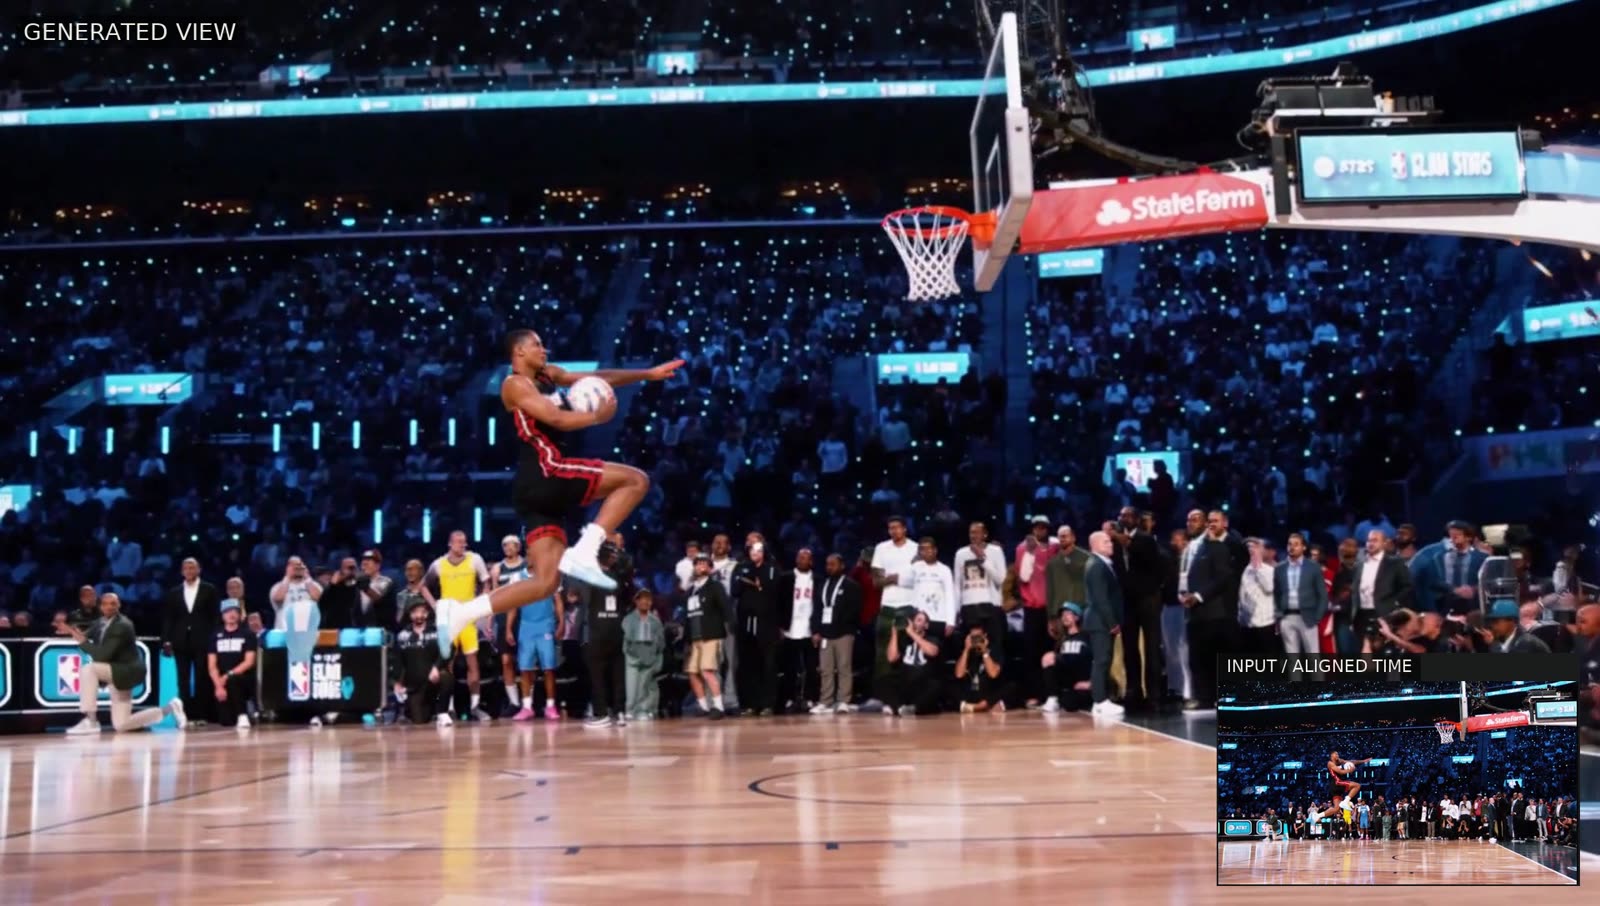
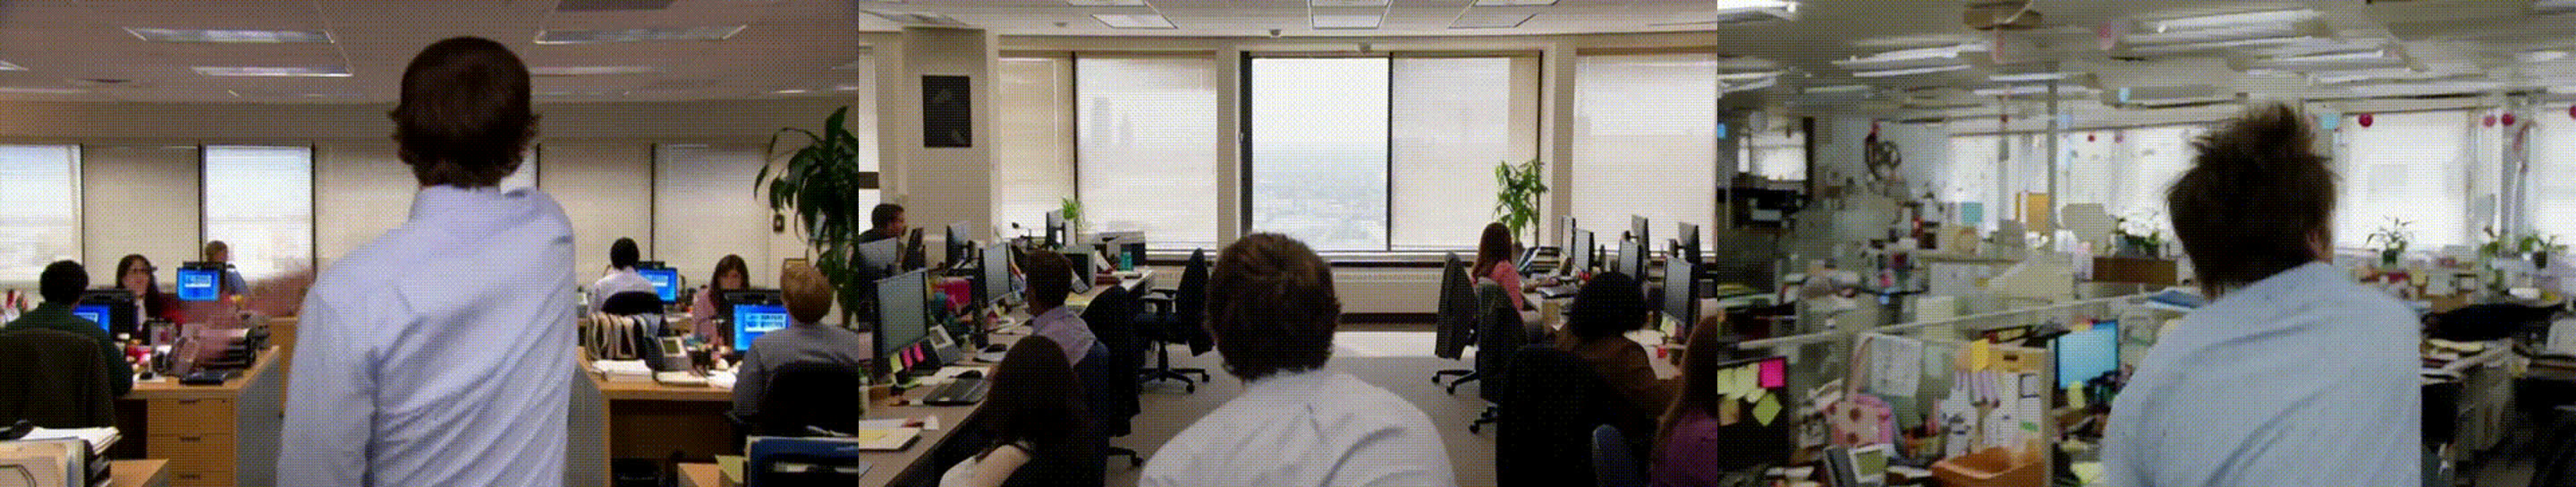
EcosystemCseti ports CrossView-Warp to MiniMax H3: a Ref2VA LoRA plus a ComfyUI node that re-renders existing footage from a new camera angle using a MoGe depth warp.
MiniMax-H3-Community
ComfyUI ecosystem updates — open-source model releases, custom nodes, workflows, and tools for image, video, and audio generation.
EcosystemCseti ports CrossView-Warp to MiniMax H3: a Ref2VA LoRA plus a ComfyUI node that re-renders existing footage from a new camera angle using a MoGe depth warp.
MiniMax-H3-Community
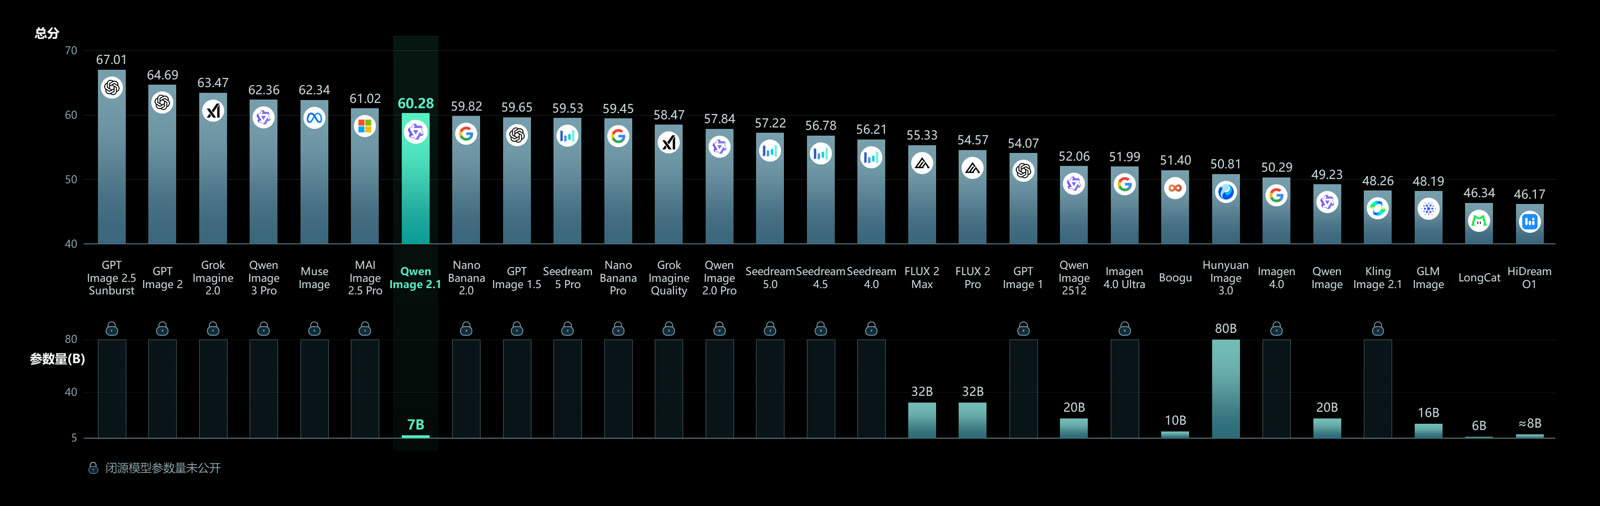
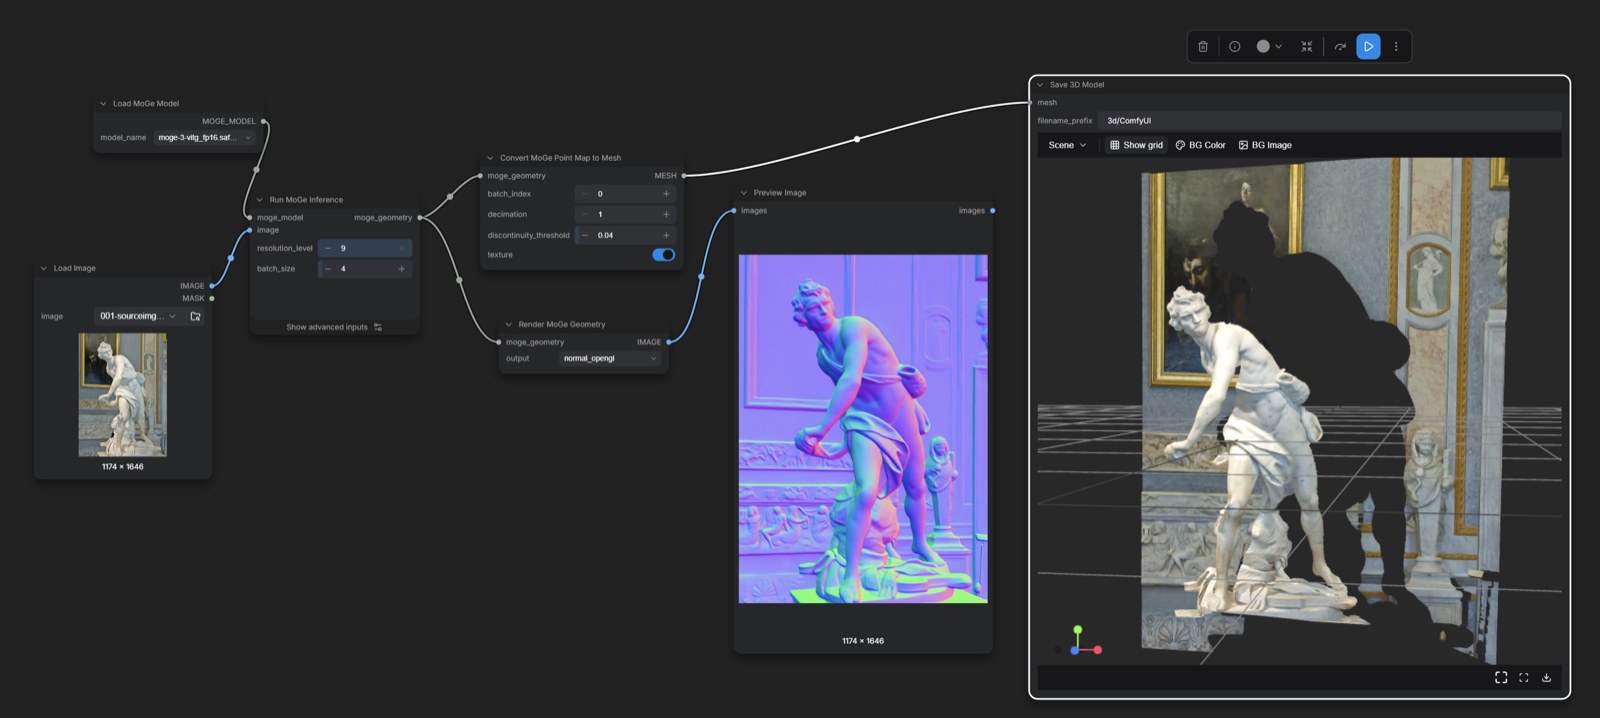
EcosystemComfyUI v0.37.0 adds native Qwen-Image 2.1 support with three official templates, MoGe 3 geometry estimation, faster Qwen3.8 text encoders and automatic fast disk loading.
Text to videoComfyUI-MiniMax-H3-SPEED V2 supports Euler, Heun, DPM2 and RES Multistep, adds a sampler-aware Sigma Harvest, and fixes I2V keyframe resizing.
Text to imageDownload Qwen-Image 2.1 for ComfyUI: qwen_image_2.1_bf16 and int8_convrot safetensors, qwen3vl_8b encoder and official 2K text-to-image, edit and background removal workflows.
Qwen Research License
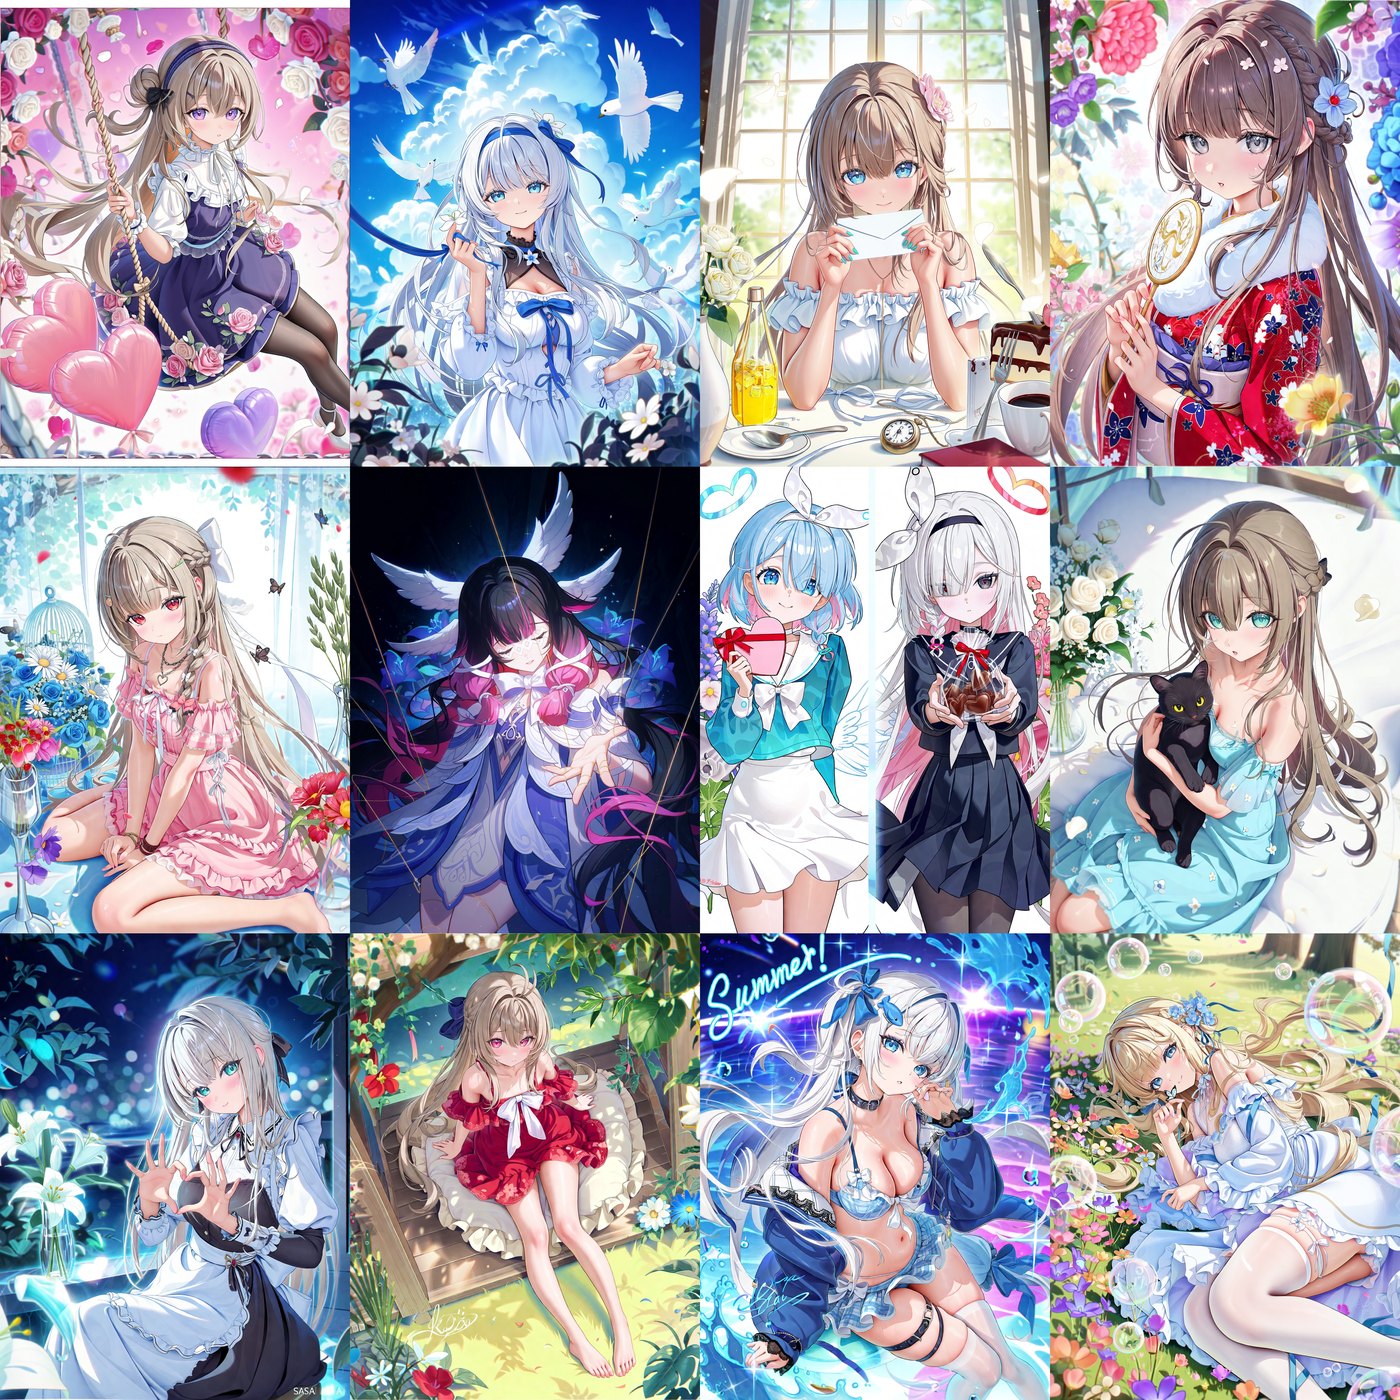
Text to imageAnima-Light-Lavender is a post-train of Anima-Base v1.0 that reads 512-token natural-language captions, ships BF16 and MXFP8 weights and drops into ComfyUI unchanged.
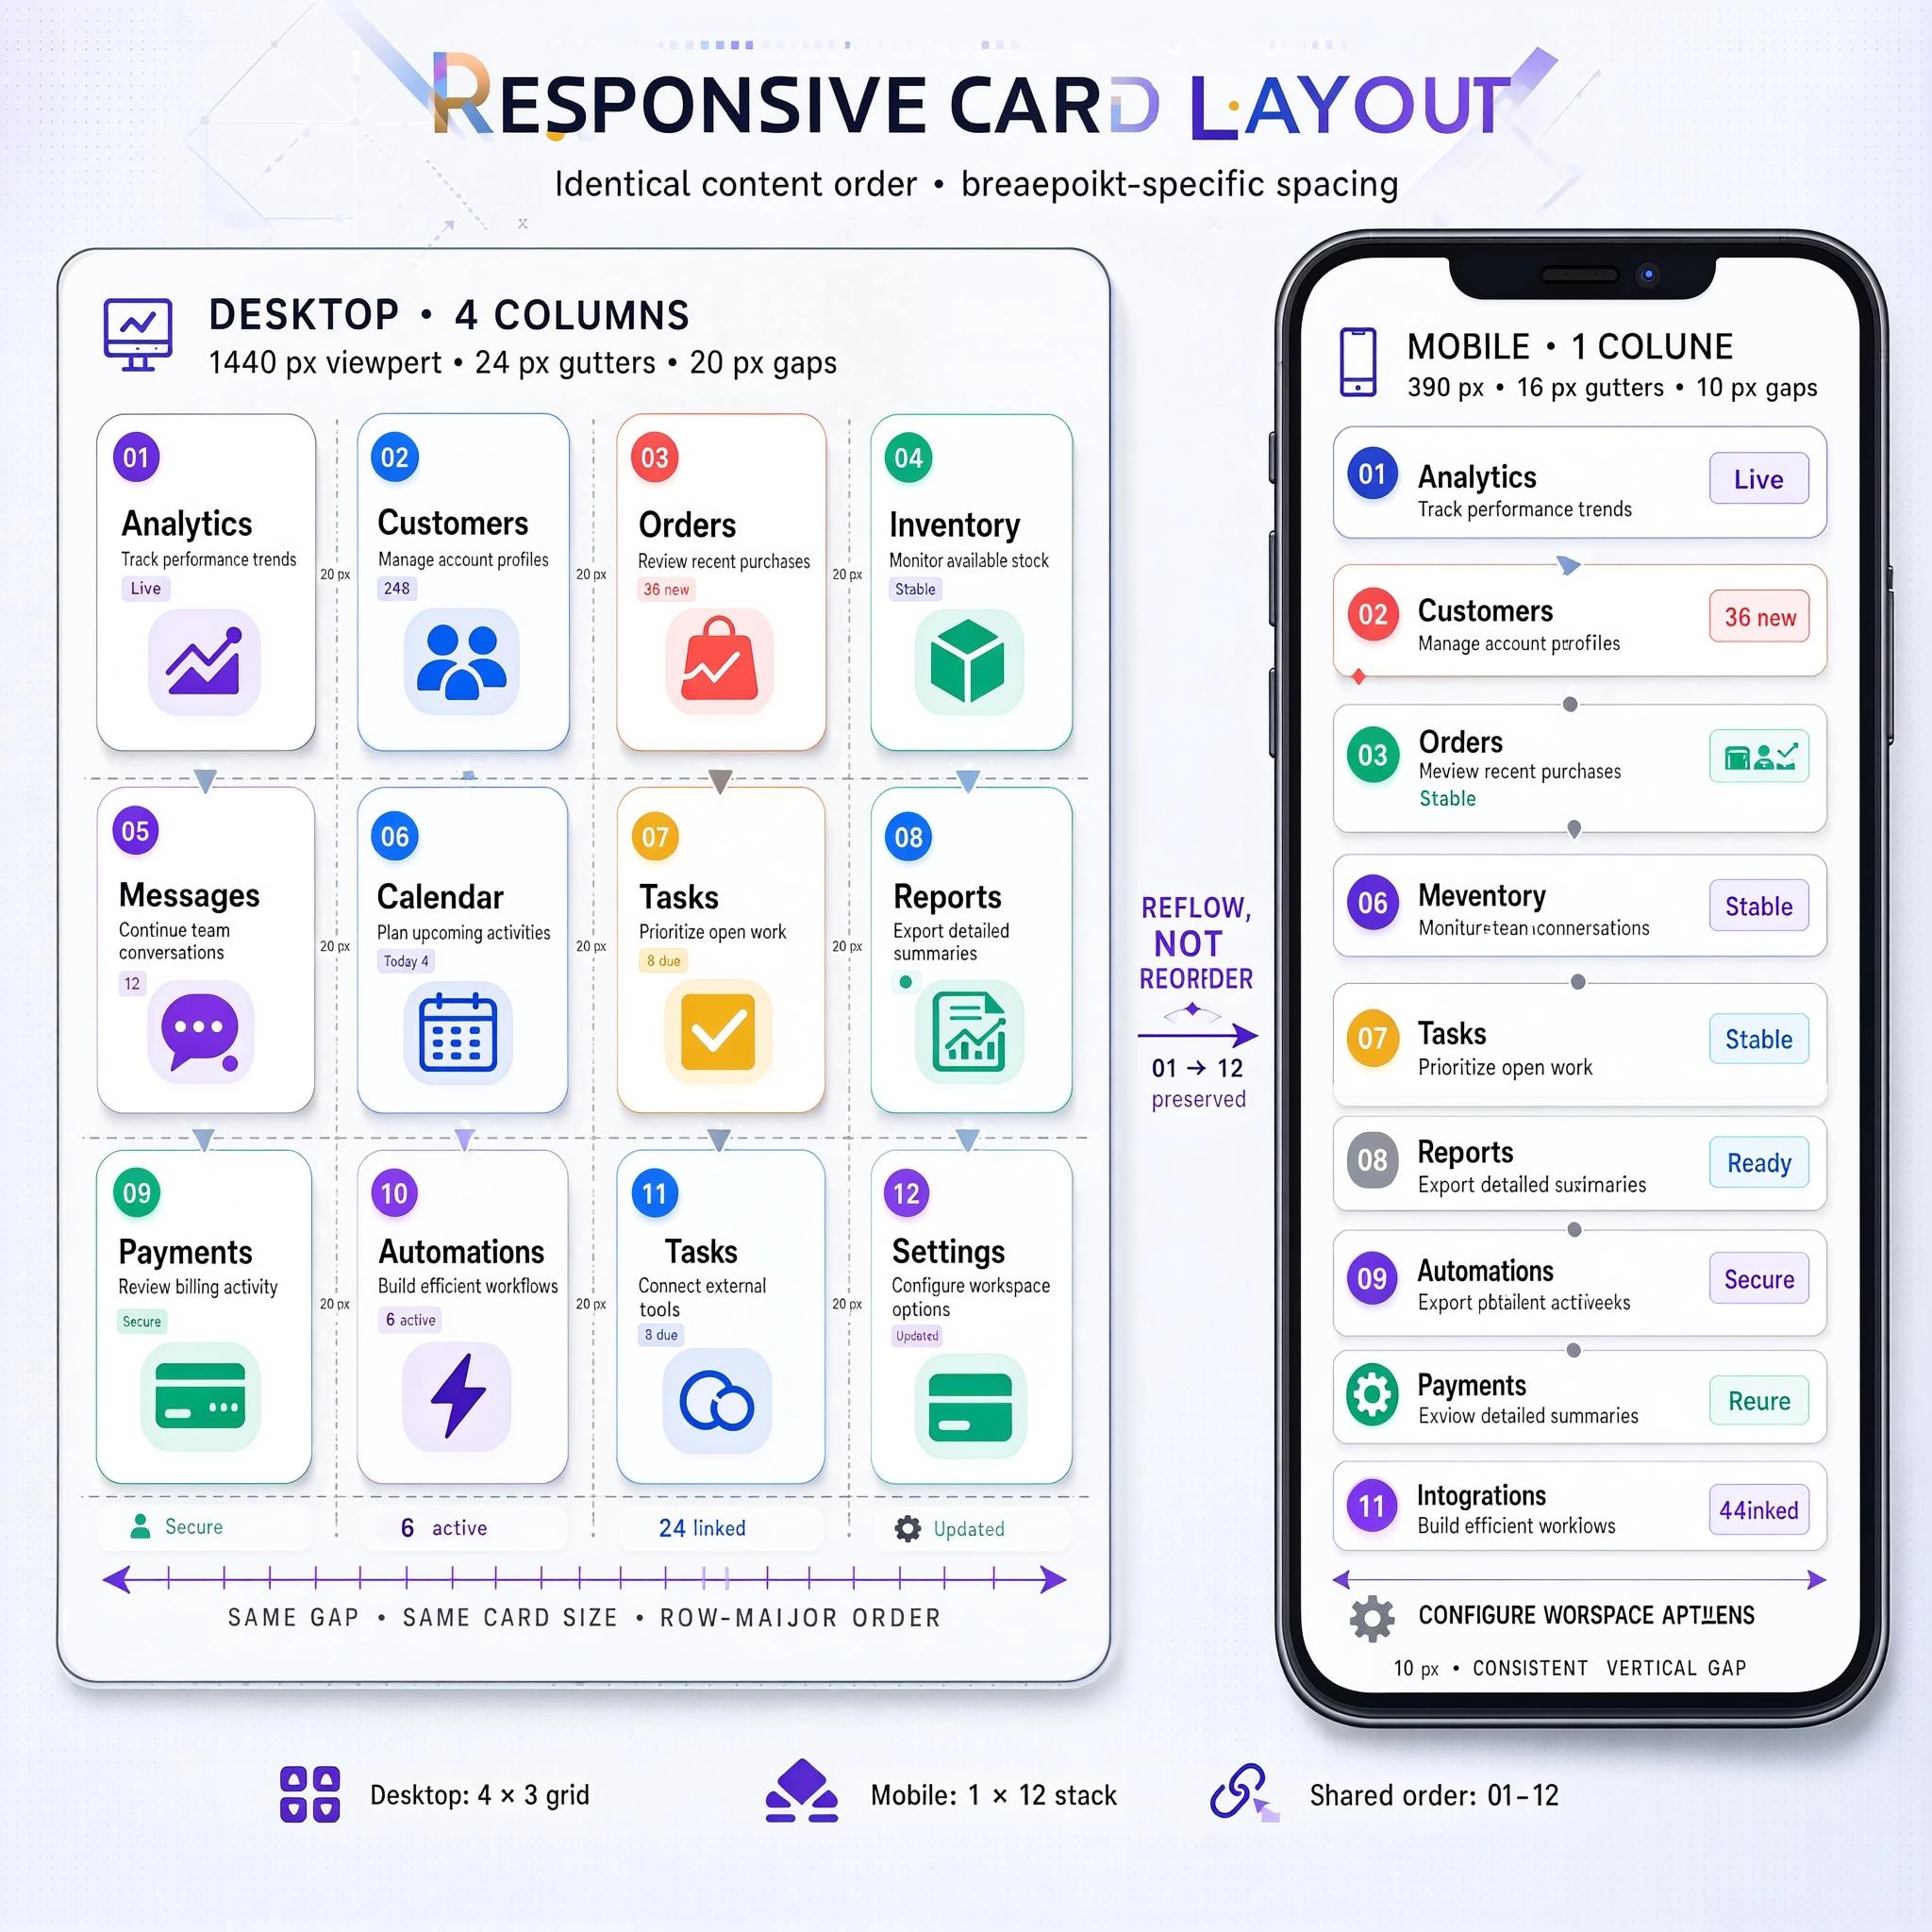
Text to imageMing-Image 0.1 Design is inclusionAI's 6B text-to-image model for UI, infographics and text-heavy posters, with RGBA transparency and official ComfyUI support.
MIT
Text to videoVideo Rebirth's HyperFlow cuts MiniMax H3 sampling from 49 transformer forwards to 8 with a data-free self-distillation LoRA; two ComfyUI ports followed.
minimax-h3-community-license-agreement
Image to videoXGEN Labs' JING-Flash-v1 builds first-person video and audio on MiniMax H3: keyboard camera control, text-driven interaction, dialogue and four-step inference.
minimax-h3-community-license-agreement
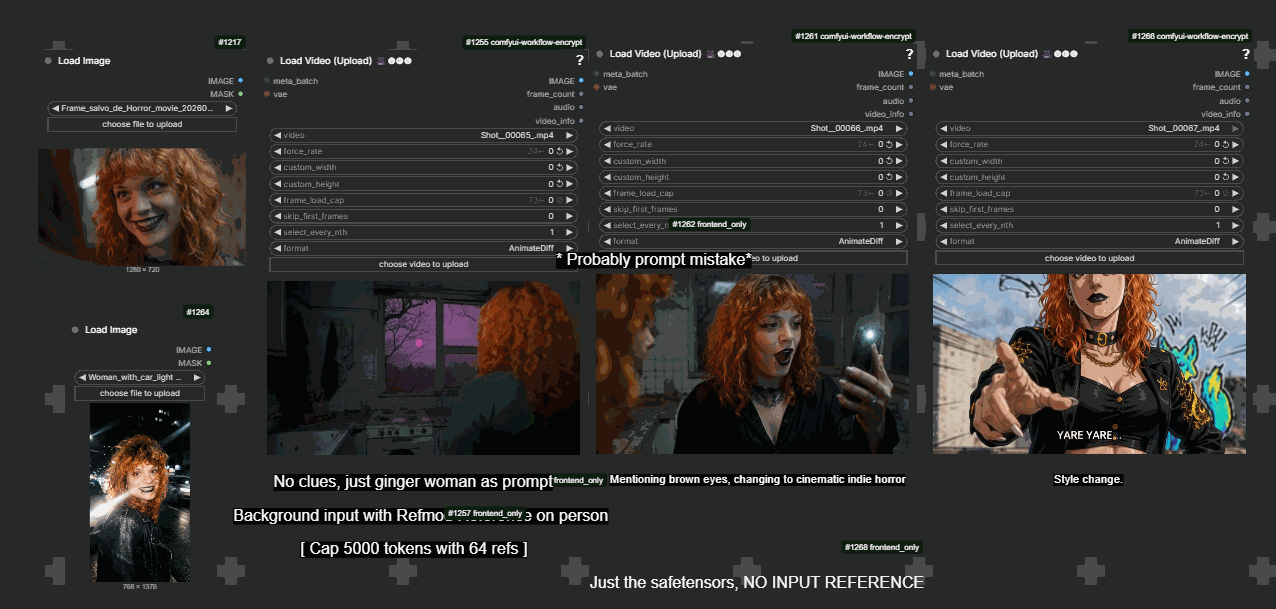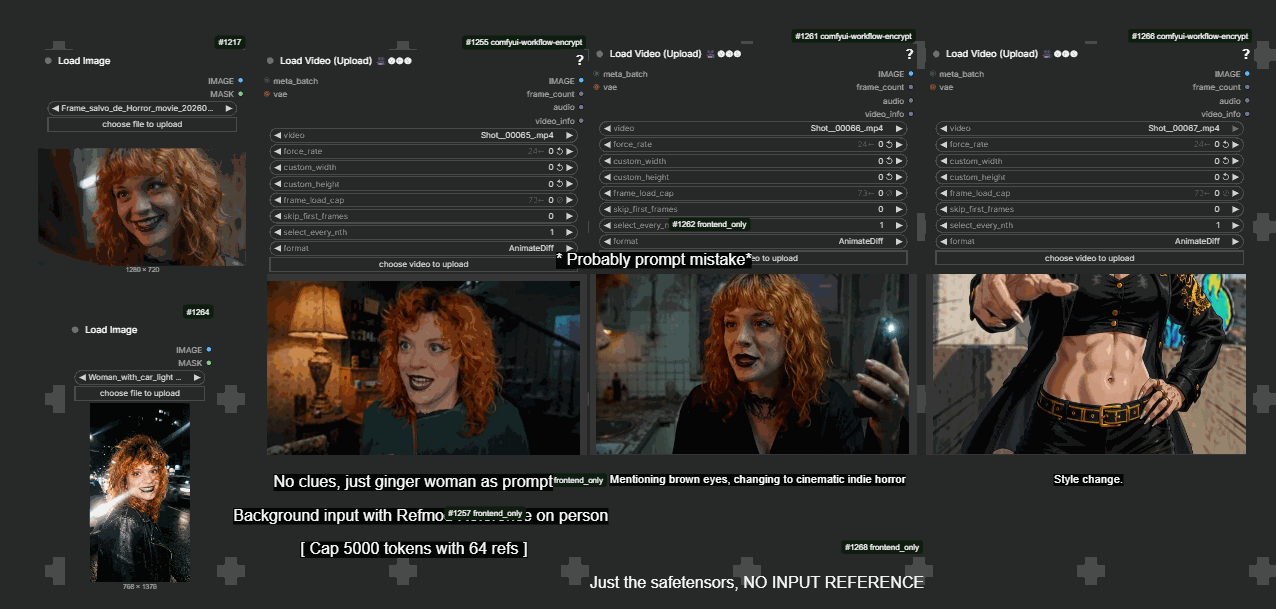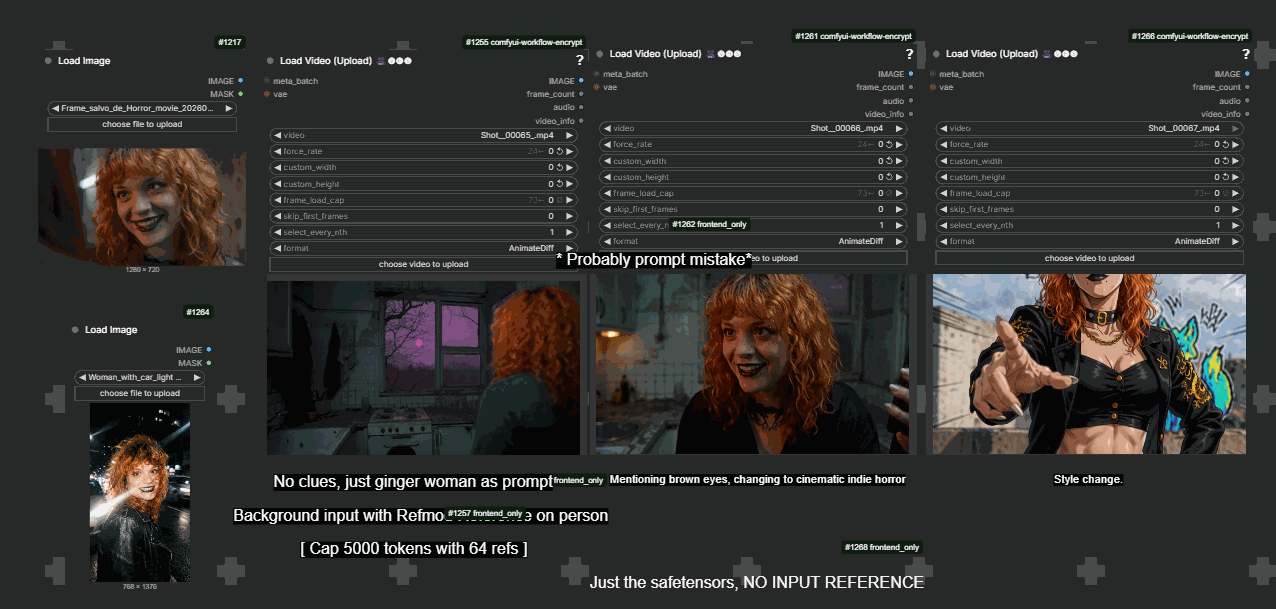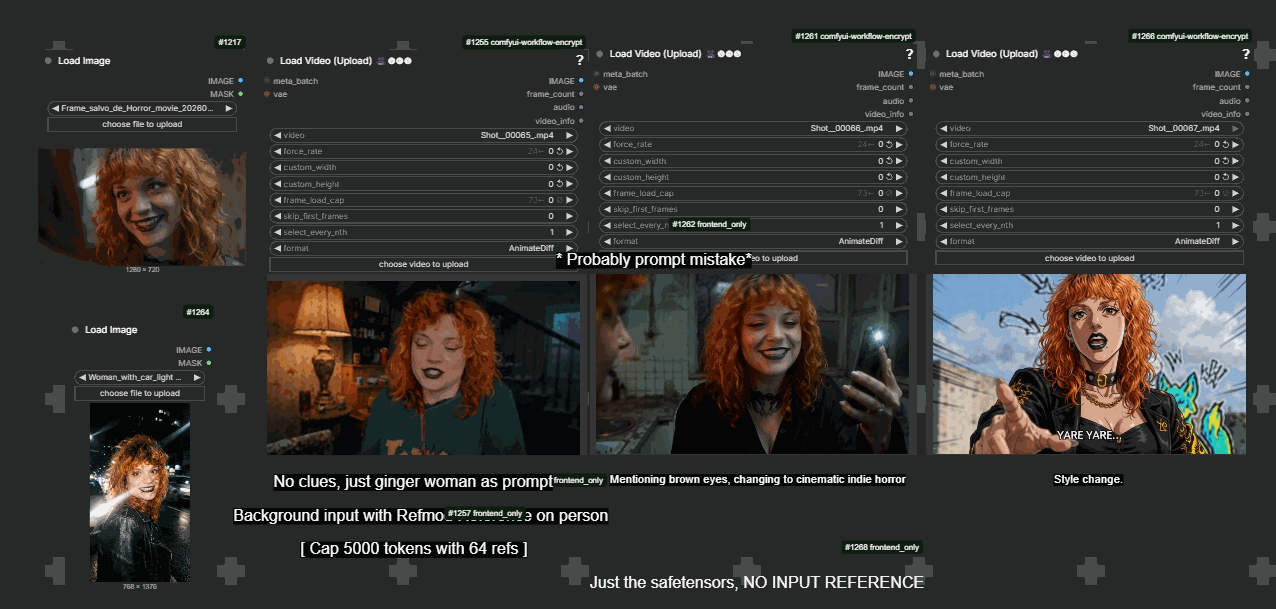
Image to videoFizgig v6.0 makes RefMods for MiniMax H3: reference photos packed into one small file, tuned against the model itself, previewed in RefMod Studio before ComfyUI.
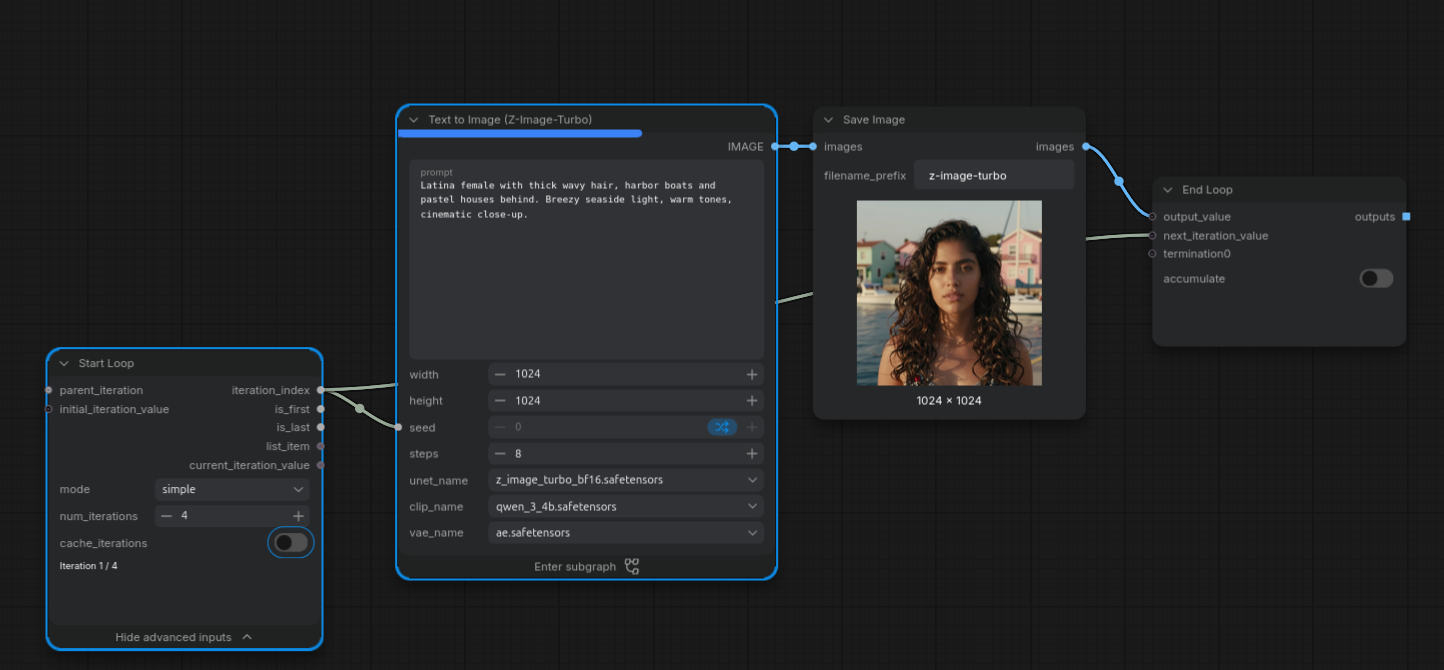
EcosystemComfyUI core now loops a workflow natively. Pair Start Loop with End Loop to iterate a graph over a count, an index range or a list, with carried values and accumulated outputs.
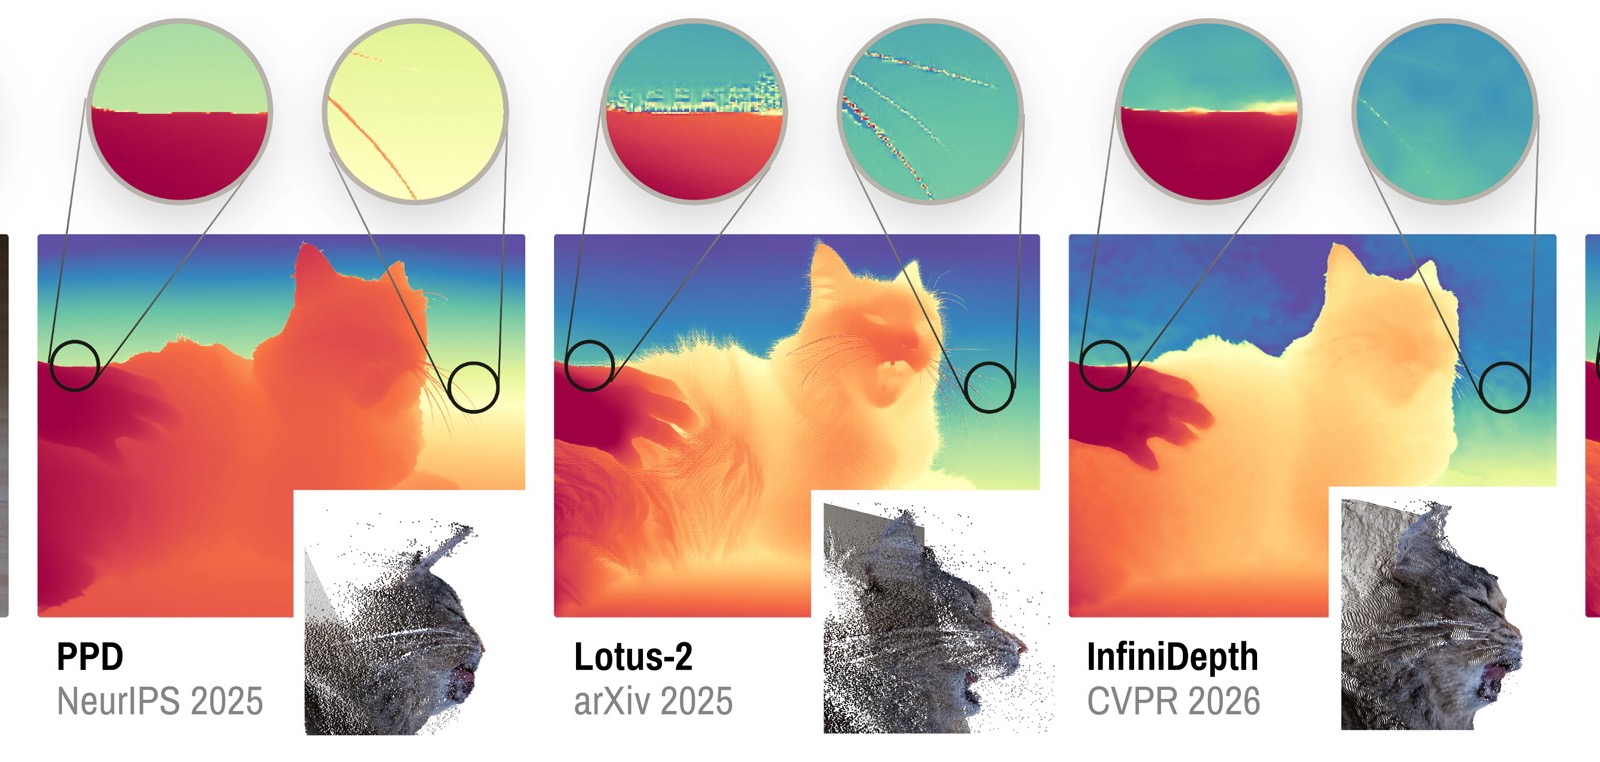
EcosystemComfyUI v0.36.0 adds native Marigold V2 depth, normal and albedo estimation with three official workflows, plus the Video Concatenate node, FastH3, YuE2 and new partner nodes.
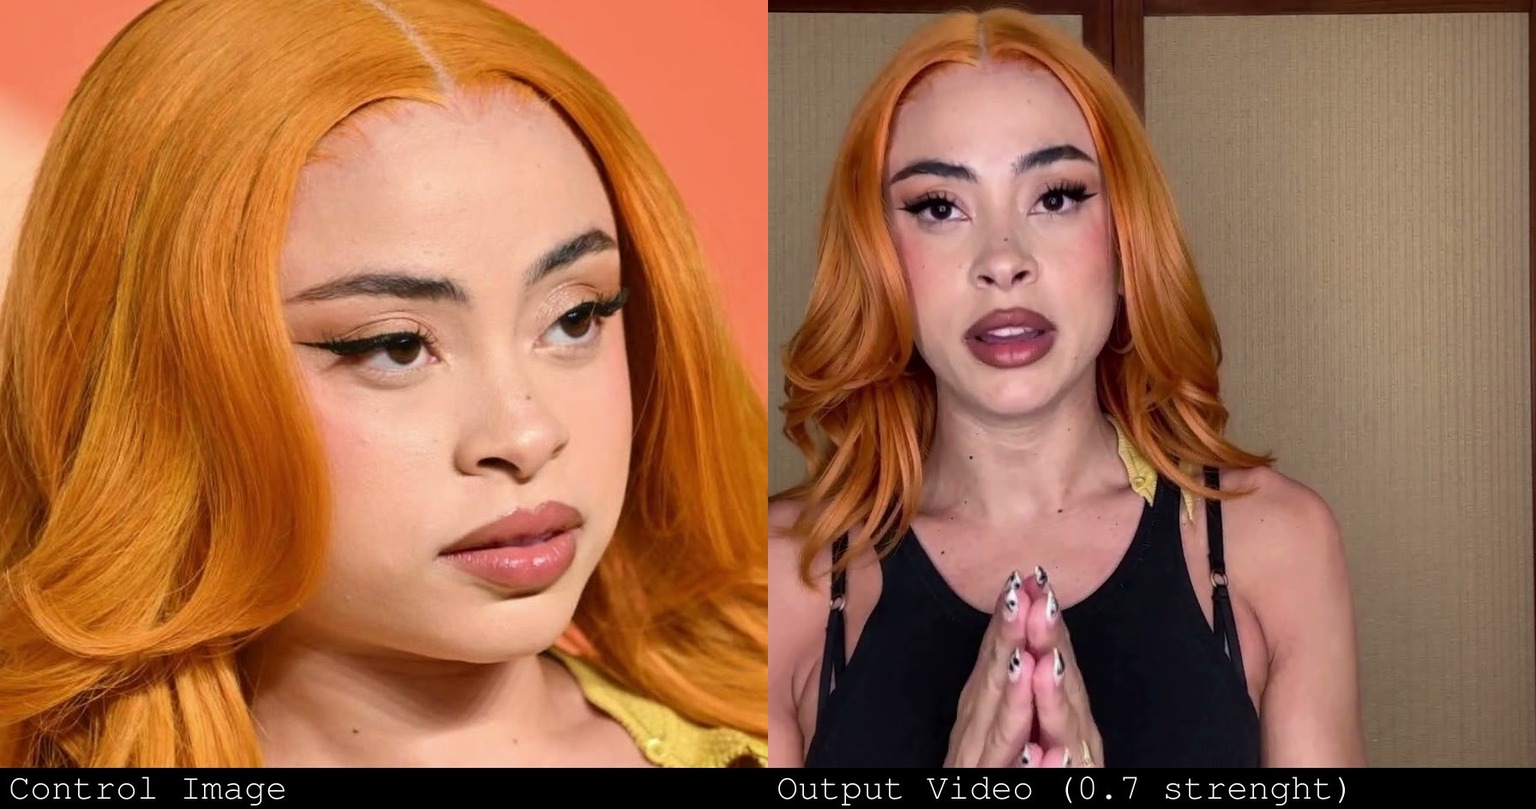
Image to videoUntMods' FaceSwap LoRA for MiniMax H3 Ref2VA swaps the identity in a reference video for the face in your reference image, with a ready ComfyUI workflow.
Apache-2.0
Text to videoComfyUI 0.36.0 speeds up the MiniMax H3 video VAE with comfy-kitchen kernels, and the official Comfy-Org repo now hosts the compact int8 convrot VAE.
Text to videoFastVideo FastH3 8-Step V2 runs natively in ComfyUI with official t2v and first/last-frame templates, BlockSparseAttention VSA settings and a Comfy-Org repacked checkpoint.
Video editingViggle Meridian re-cameras MiniMax H3 video from a geometry render: feed an existing clip plus a camera path and get a new viewpoint. Two LoRAs, two nodes, ready graphs.
minimax-h3-community-license
Text to imageA community DMD2 distillation LoRA runs Krea 2 Turbo in two steps at cfg 1.0 for fast previews and drafts, with a ready ComfyUI workflow of stock nodes only.
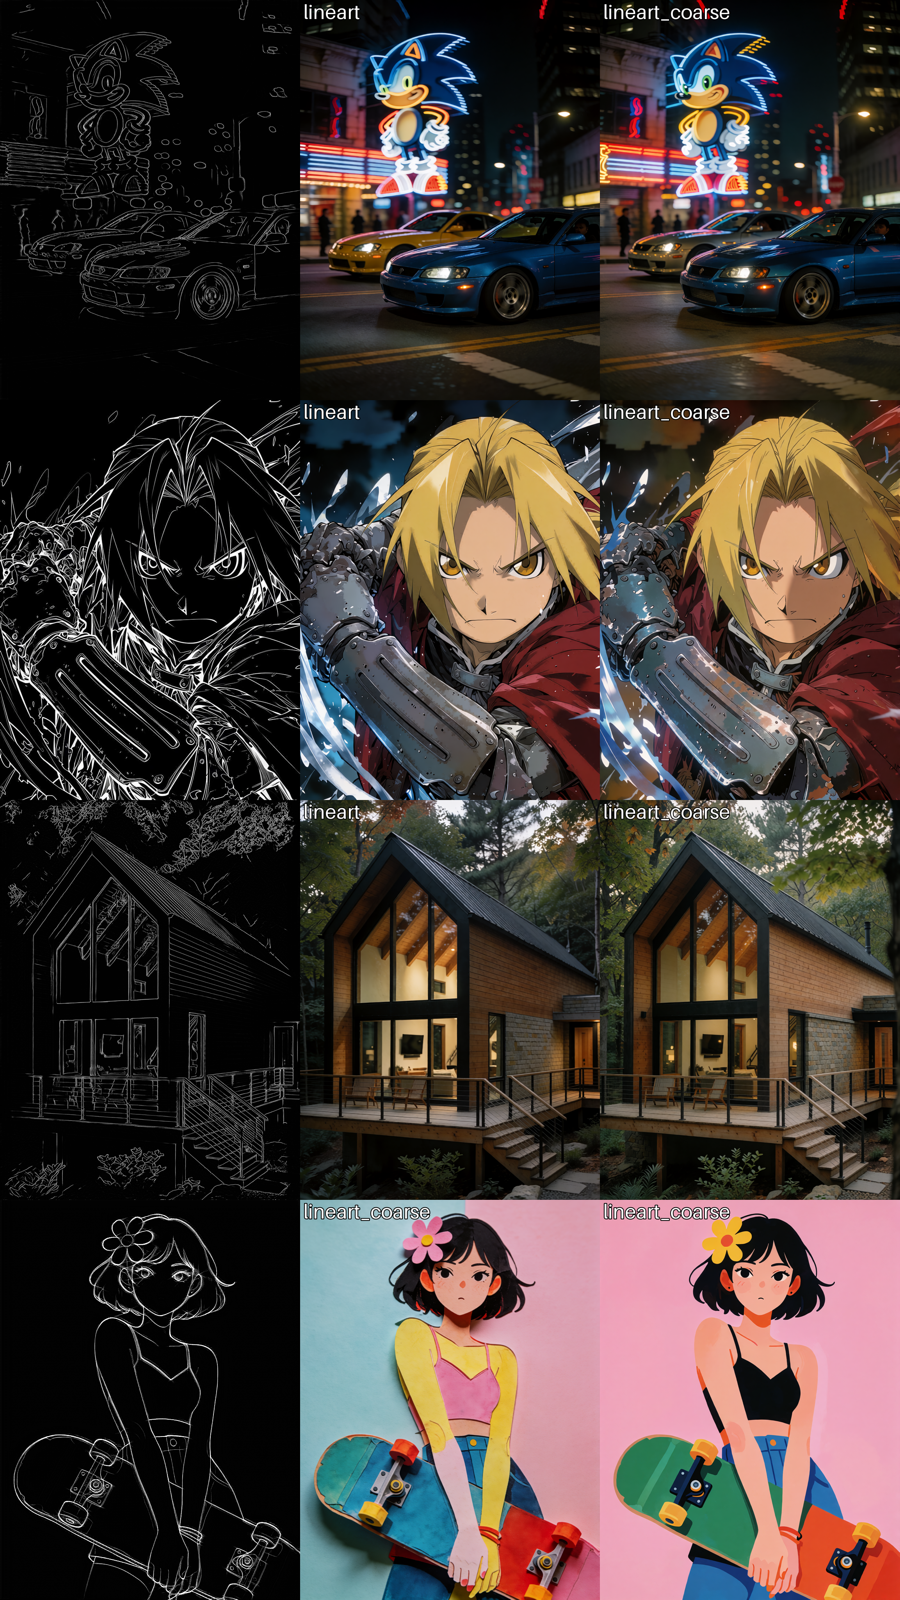
Image to imageTwo community LoRAs for Krea-2-Raw paint a finished image while following your lineart, using the Ostris edit nodes and a Realistic Lineart preprocessor in ComfyUI.
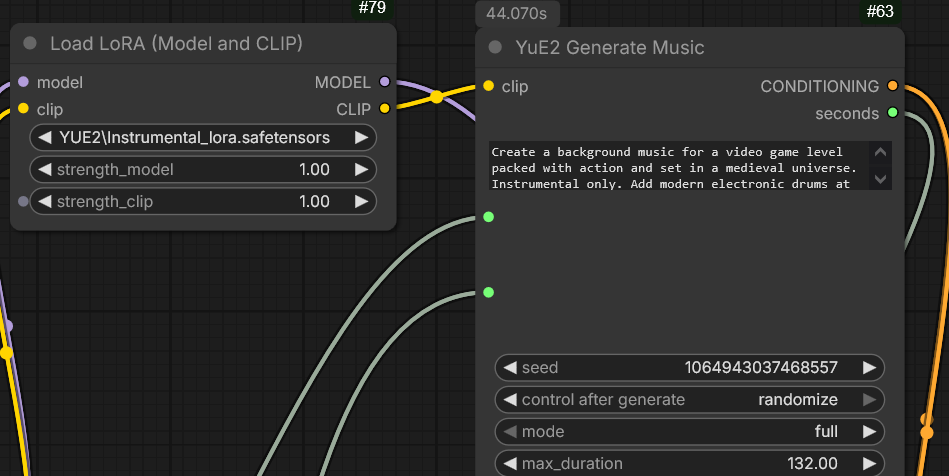
Text to speechThe community-built missing audio encoder for YuE2-3B turns your own recordings into semantic tokens for LoRA training, plus an instrumental LoRA with section prompts.
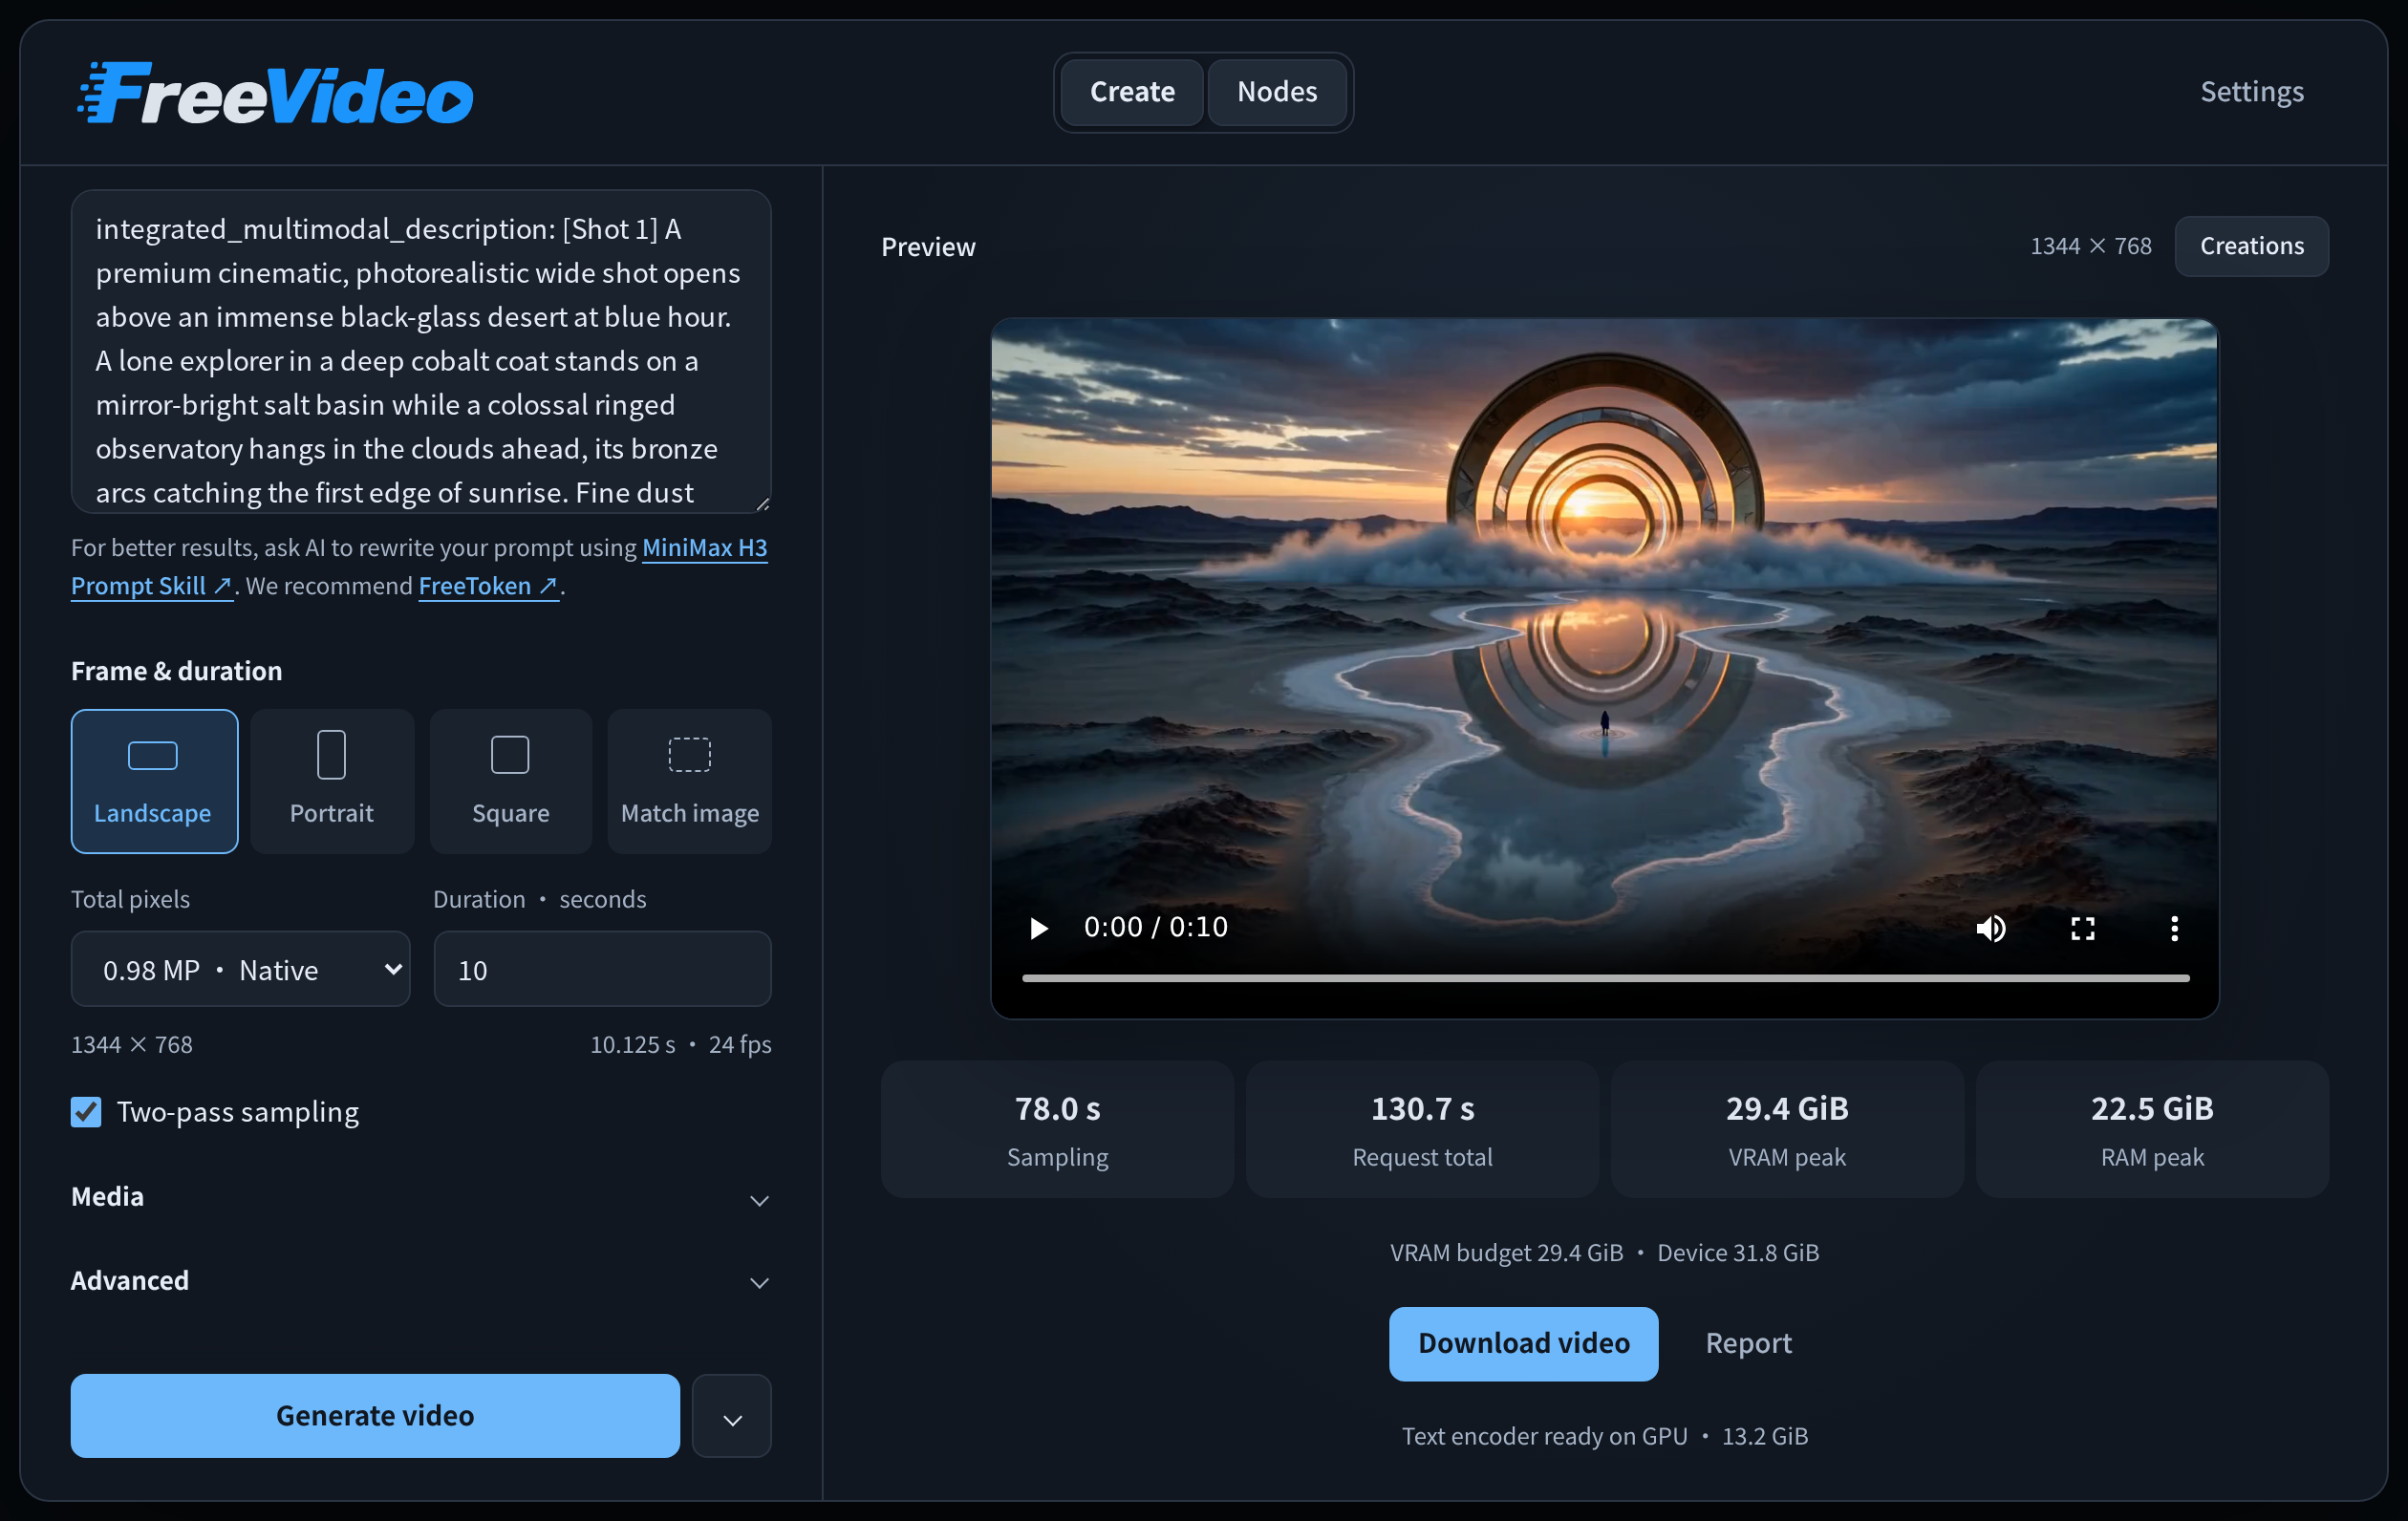
Text to videoFlashML's FreeVideo runs MiniMax H3 on as little as 8 GB of VRAM, shipped as a ComfyUI plugin and Windows launcher built on the 8-step VDN-H3 model with FP8 execution.
Apache-2.0
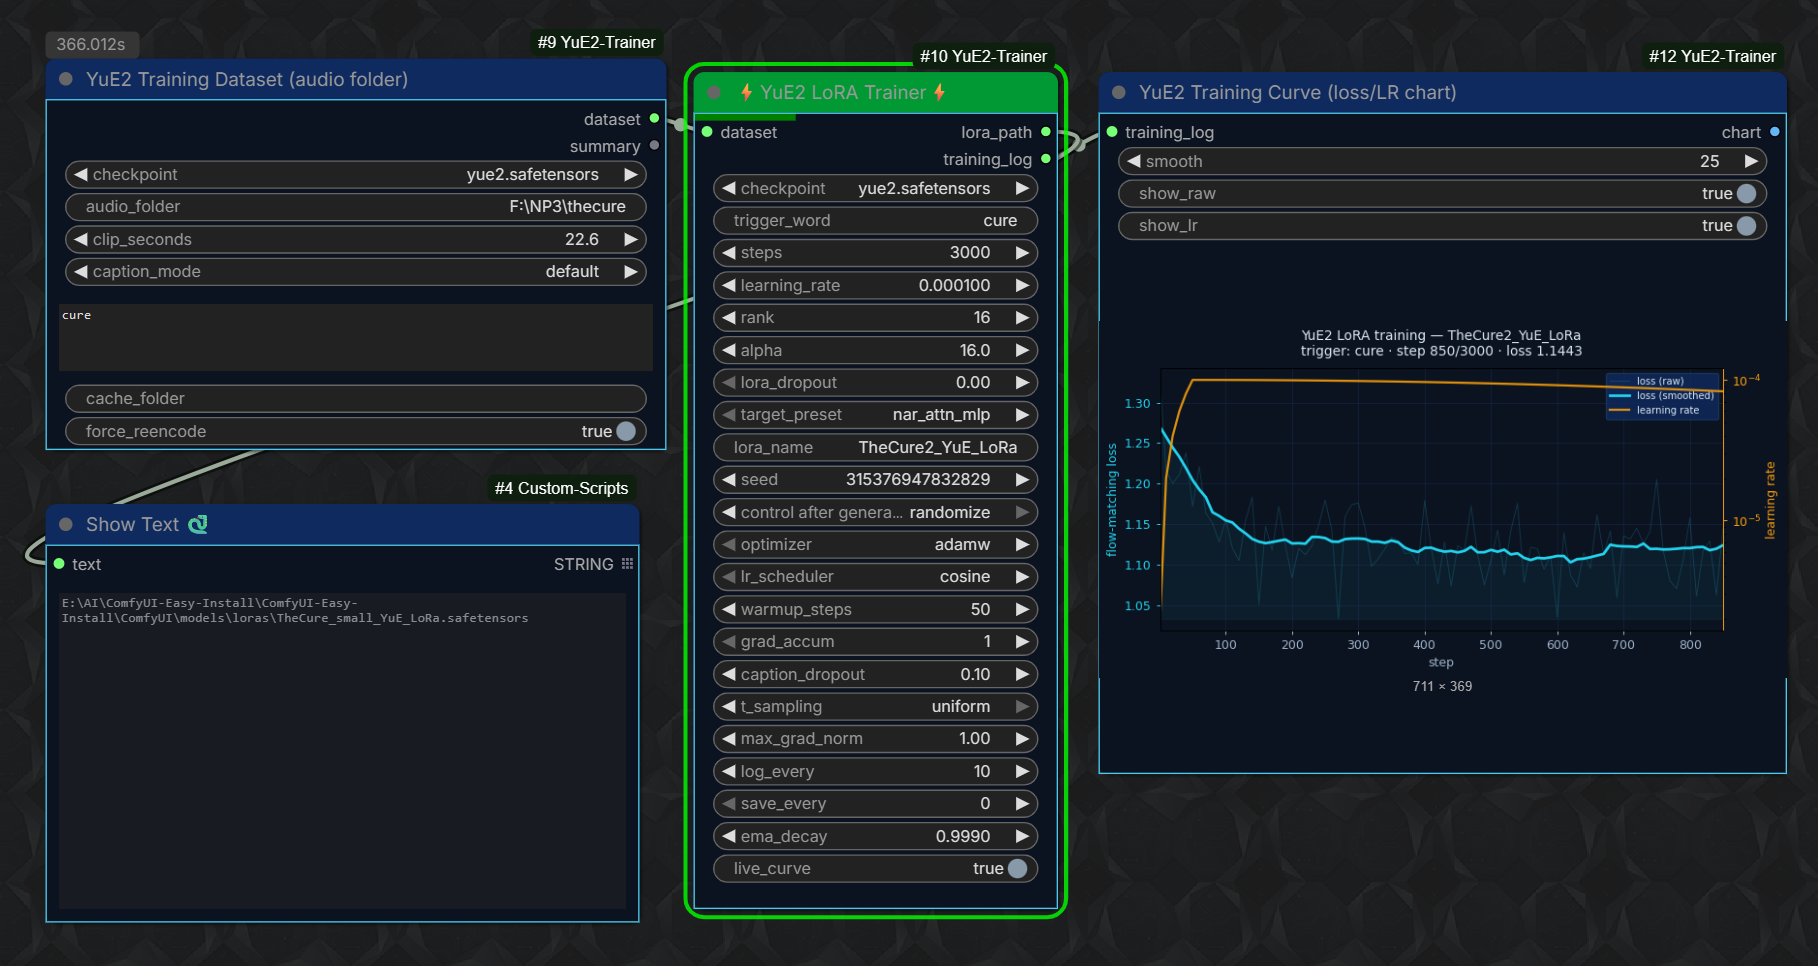
Text to speechComfyUI-YuE2-Trainer brings LoRA training for the YuE2-3B music model into ComfyUI nodes: feed it mp3 or wav files, pick a trigger word, and get a stock loader-ready LoRA.