ComfyUI v0.36.0: Marigold V2 Native Support and Video Concatenate
ComfyUI v0.36.0 adds native Marigold V2 depth, normal and albedo estimation with three official workflows, plus the Video Concatenate node, FastH3, YuE2 and new partner nodes.
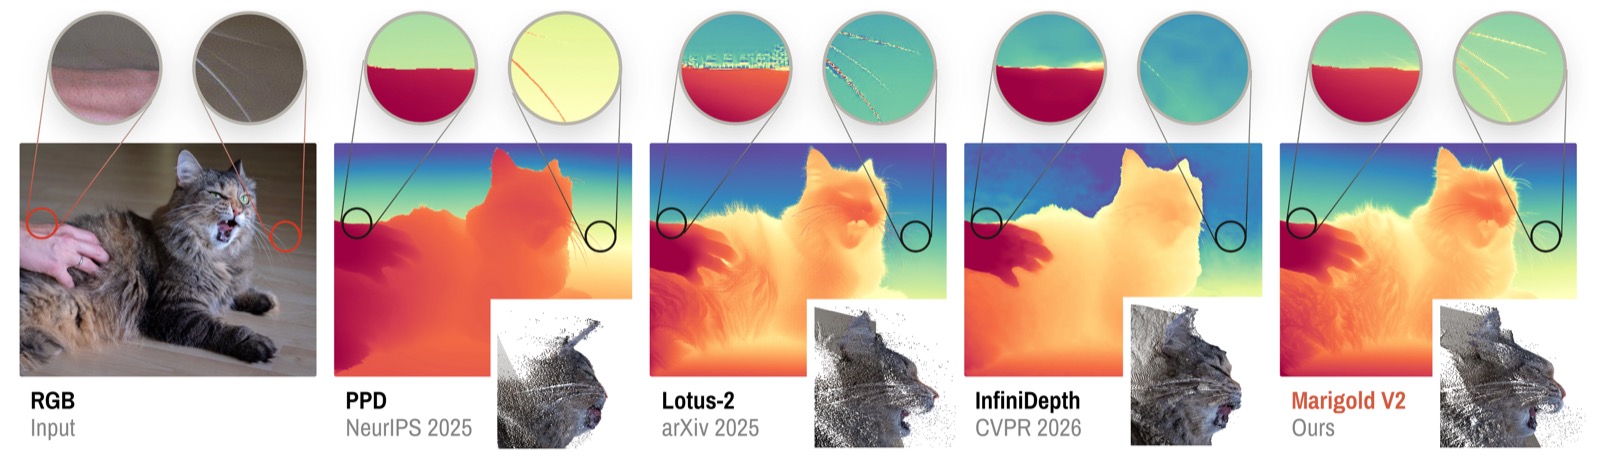
Marigold V2 reads geometry straight out of a single image: depth, surface normals and albedo from the same checkpoint family (teaser from the project repository).
Marigold V2: Depth, Surface Normals and Albedo
Marigold V2 comes from HUAWEI Bayer Lab together with EPFL and the University of Bologna, and is presented at SIGGRAPH Asia 2026 (arXiv:2609.08084). Rather than training a new diffusion model from scratch, it fine-tunes Qwen-Image-Edit-2509 with per-task LoRA weights and fine-tuned VAE decoders, then reads the prediction out of the latent in a single sampling step.
Core support landed through Comfy-Org/ComfyUI#16232 (CORE-431), and the official templates ship with Comfy-Org repacked weights in Comfy-Org/marigold-v2-0. Three tasks are covered:
- Depth: affine-invariant log depth from the paper's default
depth/Log-stage2checkpoint, trained on Hypersim and Virtual KITTI 2 (about 74k images). - Surface normals: camera-space unit normals.
- Albedo: linear RGB albedo in [0, 1].
The upstream release also carries see-through (layered) depth checkpoints that predict the geometry behind glass, along with uniform depth and disparity ablations. The ComfyUI package ships the three main modalities.
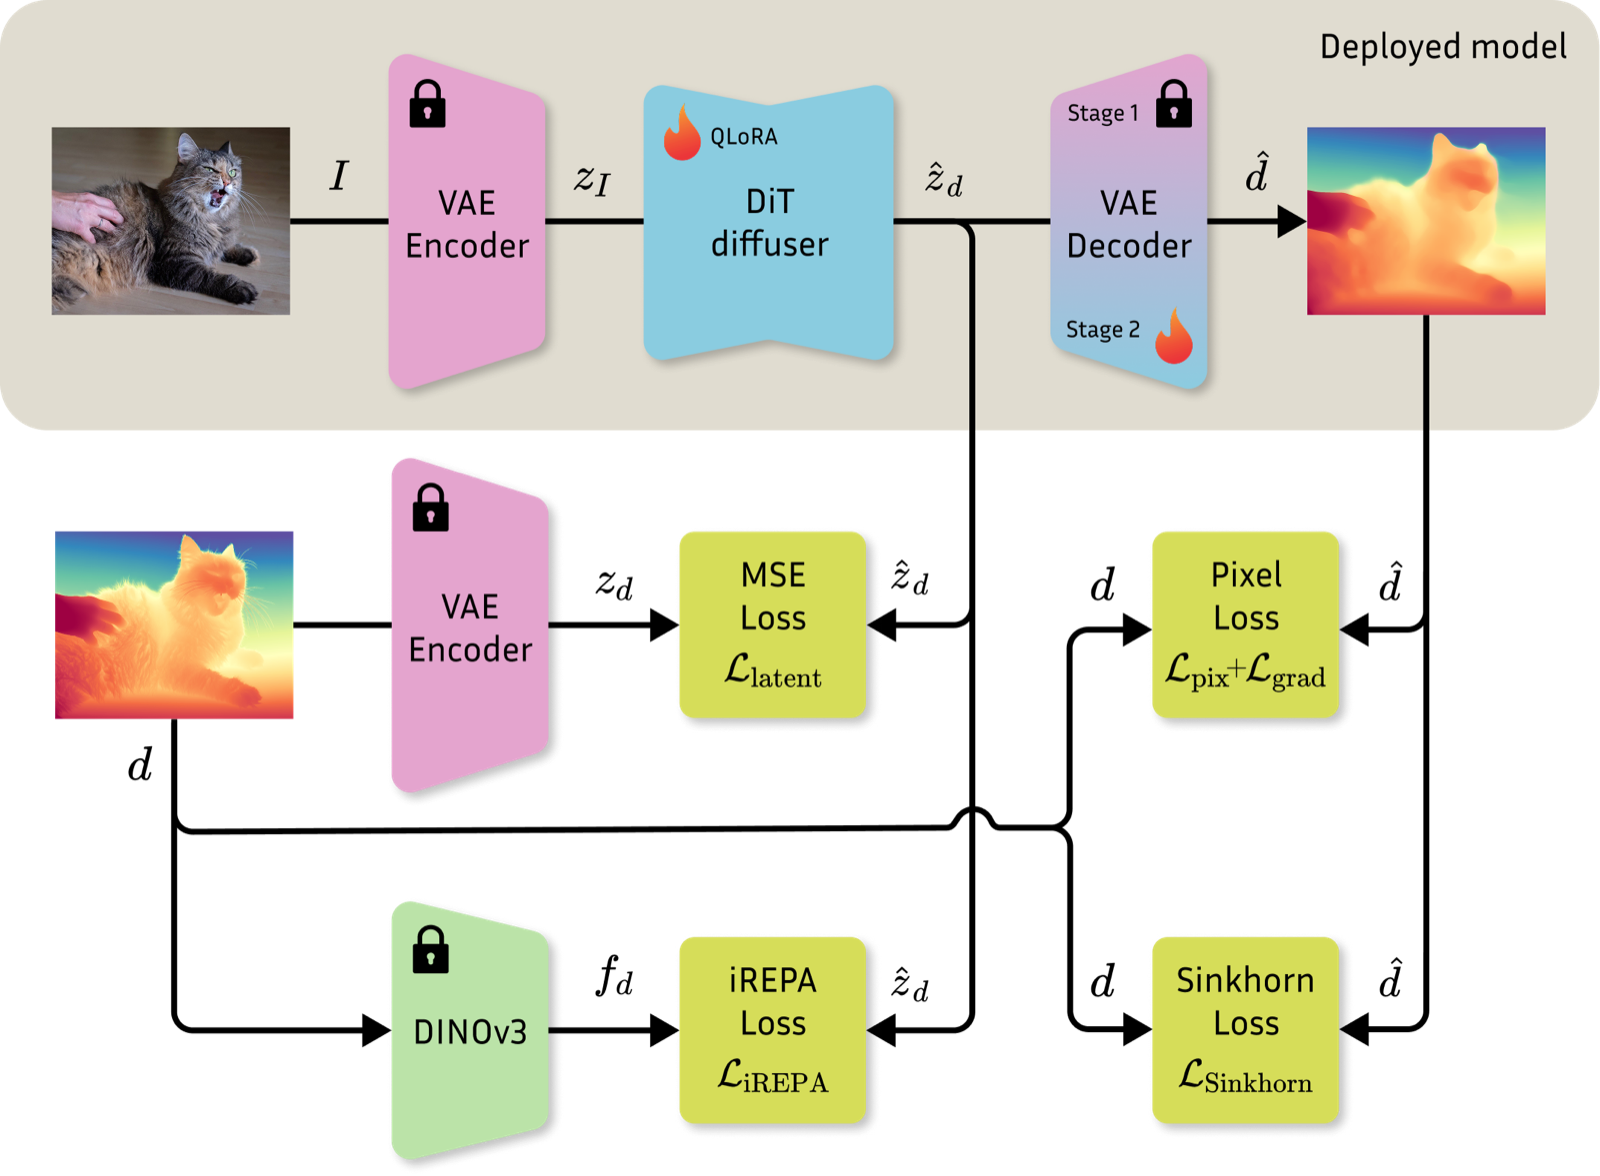
Method overview from the project repository: a single Qwen-Image-Edit-2509 backbone is adapted per dense-prediction task.
Inside the Marigold V2 workflows
Each template is built as a subgraph. It loads the int8 ConvRot Qwen-Image-Edit-2509 base qwen_image_edit_2509_int8_convrot.safetensors, applies the task LoRA, loads a precomputed conditioning embedding and the task VAE, then samples with euler on 0.5 -> 0 sigmas, which is one step. No text encoder is required: the prompt embeddings ship as *_conditioning.safetensors files, loaded through ConditioningLoader.
A new Marigold V2 Post-Process node (MarigoldV2PostProcess, category image/geometry estimation) converts the decoded prediction into a viewable image, with a prediction switch for depth (normalized, near as bright), normals (unit normals) or albedo (sRGB).
Files expected by the templates:
📂 ComfyUI/
└── 📂 models/
    ├── 📂 diffusion_models/
    │   └── qwen_image_edit_2509_int8_convrot.safetensors
    ├── 📂 loras/
    │   ├── marigold_v2_depth_log_stage2.safetensors
    │   ├── marigold_v2_normals.safetensors
    │   └── marigold_v2_albedo.safetensors
    ├── 📂 embeddings/
    │   ├── marigold_v2_depth_conditioning.safetensors
    │   ├── marigold_v2_normals_conditioning.safetensors
    │   └── marigold_v2_albedo_conditioning.safetensors
    └── 📂 vae/
        ├── marigold_v2_depth_log_stage2_vae.safetensors
        ├── marigold_v2_normals_vae.safetensors
        └── marigold_v2_albedo_vae.safetensors
Zero-shot numbers published with the model: depth AbsRel / δ1 of 3.6 / 98.0 on NYUv2, 5.4 / 97.4 on KITTI, 2.8 / 99.2 on ETH3D, 3.7 / 97.9 on ScanNet and 5.2 / 97.1 on DIODE; surface normals mean angular error 16.6° on NYUv2; albedo PSNR 20.78 and SSIM 0.811 on the Hypersim test split.
Video Concatenate Node
v0.36.0 adds a Concatenate Video node (ConcatenateVideo, category video) for joining clips end to end in the graph:
- Inputs autogrow as
video1,video2, and so on, up to 100 segments, and are appended in input order. - When the segments are already encoded with a compatible codec, they are concatenated without decoding.
codecdefaults toauto(H.264), and already encoded videos are left untouched.- An optional
complete_audioinput overrides the audio carried by the segments, which is useful when the clips come from separate generations.
FastVideo FastH3 and YuE2 Support
The release also promotes two earlier models into the core build:
- FastVideo FastH3, the 8-step distilled MiniMax H3 for text-to-video and image-to-video with native audio. See FastH3 8-Step V2 Gets Native ComfyUI Templates for the checkpoints and the VSA attention settings the templates rely on.
- YuE2, music generation from style prompts and lyrics, with follow-up fixes for AMD systems, a higher maximum song duration and more controls on the generate node. Earlier coverage: YuE2.
Other Node and Core Changes
- Generic loops:
Start LoopandEnd Looplanded in the same release for iterating over lists inside a graph, together withCreate ListandGet Item From List. - Convert Image Color Space gained a
lineardestination (linear Rec.709), on top of the existing sRGB, HDR and HDR PQ spaces. - Gemini text node:
GeminiNodeV3was added and the V2 node deprecated. - MiniMax H3: the video VAE memory footprint was lowered further on top of the int8 ConvRot VAE work.
- AMD on Windows: the virtual address quota was raised to 4TB (CORE-409), and a dead ROCm triton architecture gate was dropped from the quantization ops.
Partner Node Updates
- Tripo P2: text, image and multiview to 3D model generation nodes.
- Pruna P-Video-2: text-to-video and image-to-video at 720p/1080p with a draft mode.
- BFL: a Flux Video Edit node that edits a source clip from a text instruction.
- Bria: new image edit nodes plus a Video Eraser node.
- OpenRouter: Microsoft
mai-image-2.6models and auto aspect ratio on the image node. - Client: partner node progress now consumes estimated-duration headers for the progress display.
Fixes and Other Changes
- Fixed H3 Fun ControlNet when ComfyUI's compiler is enabled.
- The Add Noise to Image node no longer adds noise to the alpha channel.
- Yue2 AMD issues fixed, and more controls added to the generate ABC node.
- RoPE is now applied with fast kernels on more llama based models, which covers the text encoders used by Qwen-Image-Edit class models.
- comfy-kitchen updated to 0.2.34, comfyui-frontend-package to 1.52.7 and workflow templates to v0.11.62.
- Asset records were split from content behind the
--enable-assetsflag.
Getting v0.36.0
Update ComfyUI through the Manager or your launcher of choice. The Marigold V2 workflows and the Video Concatenate node require v0.36.0 or newer, while Desktop and Cloud builds follow the stable releases.
Comments
Sign in with GitHub to join the discussion.