ComfyUI MiniMax H3 SPEED V2: Multi-Sampler Progressive Resolution
ComfyUI-MiniMax-H3-SPEED V2 supports Euler, Heun, DPM2 and RES Multistep, adds a sampler-aware Sigma Harvest, and fixes I2V keyframe resizing.
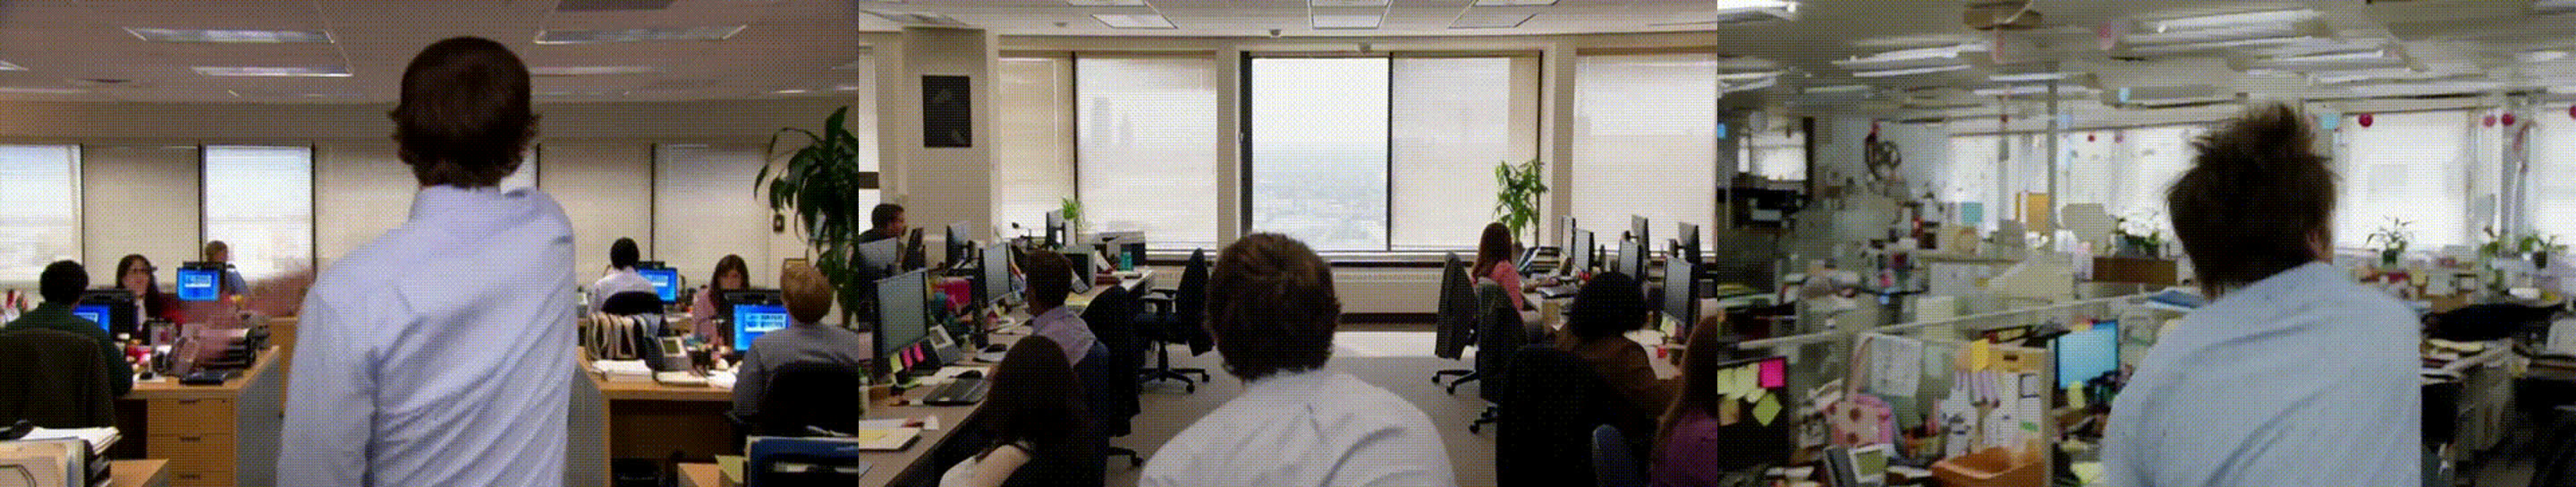
Same seed and prompt, 960x544 at 24 fps, 10.125s. Left: full-resolution baseline, no SPEED (571.49s). Middle: 3-stage at delta 0.005 (438.85s). Right: 4-stage at delta 0.05 (237.57s).
How SPEED splits the schedule
MiniMax H3 pays full spatial cost on every denoising step, including the early ones where the latent is dominated by noise and no high-frequency detail exists yet. SPEED moves those steps down to a smaller grid and works back up: the sampler denoises at a fraction of the target resolution, then transitions the latent to a larger grid for the remaining steps.
The node ships three automatic ladders, selected by a single stages value:
stages | Resolution ladder |
|---|---|
2 | 0.5 to 1.0 |
3 | 0.33 to 0.66 to 1.0 |
4 | 0.25 to 0.5 to 0.75 to 1.0 |
Tolerance (Delta), noise_amplitude and noise_decay_exponent decide when each transition happens. The nodes ship no calibration of their own: noise_amplitude and noise_decay_exponent start at 0 and the sampler stops with an error until you paste a Sigma Harvest result. For base H3 with Euler the README gives noise_amplitude = 35.4213 and noise_decay_exponent = 1.0126 as a starting point. The high-frequency bands exposed by a resolution increase are filled from a deterministic, transition-seeded Gaussian field under the default direct_coarse noise policy. A second policy, coupled_full_grid, derives those bands from a single full-resolution noise field instead; the author does not claim it improves quality, it is not the default, and on H3 video it saved only 5 to 10 percent against 15 to 30 percent for direct_coarse.
The Advanced nodes run MiniMax H3 only, and H3's audio stream always stays at full resolution. The rename that followed V2 made the pack model-agnostic: a second node family drives flow image models (MOSS Image, Krea 2) while keeping the same resolution ladder.
What changed in V2
The repository's CHANGELOG.md lists this as 2.0.0. The substantive changes:
- Sampler support. SPEED is no longer tied to Euler. V2 accepts Euler, Heun, DPM2, Exp Heun 2 X0 and RES Multistep. The stateless samplers use ComfyUI's own sampler objects; RES Multistep keeps previous-step history, so V2 runs it through a run-scoped adapter and clears that state whenever SPEED changes resolution, rather than carrying history into a differently-sized latent.
- Sampler-aware Sigma Harvest. The calibration node now reports parameters for the sampler you actually selected instead of assuming Euler, and it defaults to the same 0.005 tolerance as the automatic path.
- Unified planning. Automatic and Manual share one planning and validation implementation. Automatic now calculates transitions from the live sigma schedule and the current latent dimensions.
- I2V keyframe fix. Keyframe latents are resized from their original full-resolution copy instead of resizing an already resized tensor, and they are restored before the final stage and after a failed run. The author's summary: image-to-video should no longer get progressively blurrier at each resolution change.
- Leaner Harvest memory. V1 held every full-resolution residual tensor until the run finished and analysed them afterwards. V2 reduces each residual to a small radial DCT power profile inside the callback and discards the tensor.
- Continuous progress and previews. A SPEED run now reports as one generation instead of several unrelated sampler calls.
- Regression coverage was widened across sampler selection, RES state, I2V, transitions, Harvest, workflows and noise policies.
Measured speedups
The repository publishes an evidence folder with timings behind the claims: one RTX 5080 with 128GB of system RAM, 960x544 output at 24 fps for 10.125 seconds, same seed and prompt across every row. The full-resolution Euler baseline is 571.49s.
| Tolerance (Delta) | 2-stage | 3-stage | 4-stage |
|---|---|---|---|
| 0.005 | 462.96s (1.23x) | 438.85s (1.30x) | 435.21s (1.31x) |
| 0.010 | 450.38s (1.27x) | 409.83s (1.39x) | 384.13s (1.49x) |
| 0.050 | 278.44s (2.05x) | 262.32s (2.18x) | 237.57s (2.41x) |
The same folder states the limits of those numbers plainly. They are an Euler-only reference set: they do not establish speed or quality parity for the four samplers V2 added, and they should not be read as proof that one noise policy beats another. The author's instruction is to re-run the Harvest calibration and benchmark your own sampler, model and scheduler combination. Update 2026-11-05: the pack is now called ComfyUI SPEED Sampler and its H3 evidence set has been replaced. The current evidence folder benchmarks a 5 second 960x544 clip on a Modal L40S, where the 4 stage run at delta 0.05 is 1.58x faster than native, 182 s against 288 s. The table above is the V2 launch set as published.
Six nodes in two families
The pack ships six nodes in two families. The Advanced family handles MiniMax H3 and is wired like SamplerCustomAdvanced; the KSampler family handles flow image models and is wired like KSampler.
| Node | What it does |
|---|---|
| SPEED, Sampler Advanced | Picks the 2, 3 or 4 stage ladder and handles transitions from the live sigma schedule |
| SPEED, Sampler Advanced (Manual) | Up to four explicit (goal, resolution) pairs; ratio_mode treats a goal as a global step index (steps) or as a 0 to 1 fraction of the schedule (ratio). Active resolutions must increase and the last one must be 1.0 |
| SPEED, Sigma Harvest Advanced | Runs with your existing workflow to measure the sampler you intend to use, and returns the sampler_name, delta, noise_amplitude and noise_decay_exponent values to copy into the matching node |
| SPEED, KSampler / KSampler (Manual) / KSampler Sigma Harvest | The same three jobs for flow image models. They take model, conditioning and a latent_image like ComfyUI's own KSampler and build the noise, guider, sampler and schedule internally |
The V2 release also renamed the node IDs MiniMaxH3SPEEDSampler, MiniMaxH3SPEEDSamplerManual and MiniMaxH3HarvestToConfig to SPEEDSampler, SPEEDSamplerManual and SPEEDSigmaHarvest; the old IDs stay registered as deprecated subclasses, so workflows saved before the rename still load.
Installation is a clone of the package into ComfyUI/custom_nodes/ and a restart. In a workflow, replace SamplerCustomAdvanced with the SPEED sampler node and connect the same noise, guider, sigmas and latent_image inputs; an all-in-one KSampler has to be split into ComfyUI's advanced sampling components first.
Workflows
The repository now ships one H3 workflow plus two image workflows. video_h3_SPEED.json carries Sigma Harvest, the automatic path and the manual path on one set of loaders, with only the automatic path active, so it replaces the three separate graphs the V2 release shipped in September.
The graph loads the pruned int8 convrot fl2va checkpoint, the nvfp4 Qwen3-VL 32B text encoder and H3's separate video and audio VAEs, samples with euler on a simple schedule at 20 steps and sets the automatic node to stages = 3, direct_coarse, delta = 0.005, noise_amplitude = 35.4213, noise_decay_exponent = 1.0126 and seed_offset = 10000. image_moss_SPEED.json and image_krea2_SPEED.json do the same for MOSS Image and Krea 2 through the KSampler family, at delta = 0.05.
Availability
- Node pack: StanLukuvka/ComfyUI-SPEED-Sampler
- Workflows:
workflows/ - Benchmarks and comparison clips:
evidence/ - Changelog:
CHANGELOG.md
The repository had collected 85 stars when this was written. The announcement thread ran in r/comfyui, and much of the discussion asked for side-by-side output rather than the timing table; the author pointed readers at the evidence folder and at a separate third-party speed comparison. No independent reproduction of the V2 sampler set had been published at the time of writing.
Comments
Sign in with GitHub to join the discussion.