Supra2-IMG: A 100M Text-to-Image Model Trained in 10 Hours
SupraLabs releases Supra2-IMG, a 105M-parameter DiT text-to-image model trained from scratch in 10 hours on one H100, with samples at 256x256.
The official Supra2-IMG banner from the model repository.
What it is
Supra2-IMG is a tiny DiT: 104.1M parameters generating 256x256 images from 128 tokens of Flan-T5 context. Text conditioning comes from a frozen Flan-T5-Base encoder and latents are decoded by SD-VAE-FT-MSE, so both of those components are pulled from their own repositories rather than shipped in the checkpoint.
| Component | Value |
|---|---|
| Parameters | 104.1M (D_MODEL 576, depth 14, 9 heads, head dim 64, MLP ratio 4.0) |
| Resolution | 256x256 (32x32 latent, patch size 2) |
| Text encoder | Flan-T5-Base, frozen, 128-token context |
| VAE | SD-VAE-FT-MSE |
| Checkpoint | model_final_ema.pt |
SupraLabs is the independent lab behind the 100M-parameter Supra2 language models, and Supra2-IMG applies the same "train it small, train it from scratch" approach to image generation. The model is released as raw PyTorch code plus weights: inference.py, config.json and model_final_ema.pt.
Training
The run is deliberately modest, which is the point of the release:
- Dataset: 10 epochs over the full LucasFang/FLUX-Reason-6M dataset, 5.6M images after preparation.
- Caption selection: each image takes the first available caption in the chain
caption_compositiontocaption_entitytocaption_texttocaption_styletocaption_imaginative, keeping the highest-quality annotation for each sample. - Hardware: one Nvidia H100 SXM 80GB on RunPod, 9 hours including data preparation, on a 2.5TB disk.
Because the whole model fits in a few hundred megabytes, it is a practical base for studying small-scale pretraining and for fine-tuning experiments that would be far too expensive at 8B scale.
Samples
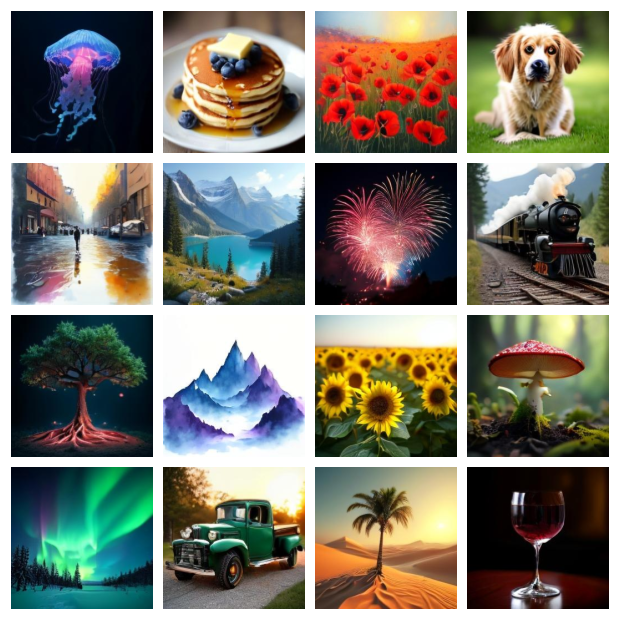
Official samples from the model repository, all at the recommended settings rather than cherry-picked runs.
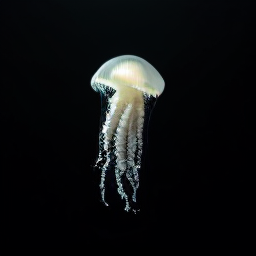
Example 256x256 output produced by the shipped inference script.
Availability
There is no ComfyUI support: Supra2-IMG is a plain PyTorch release with a custom SupraDiT architecture, so it is not a diffusers pipeline and no ComfyUI template or node is published. Running it means the bundled script plus the two external components:
wget https://huggingface.co/SupraLabs/Supra2-IMG/resolve/main/inference.py
python inference.py --prompt "a sea jellyfish floating in the pitch-black ocean depths" \
  --seed 0 --cfg 3.0 --steps 50 --n 1 --out jellyfish.png
The recommended sampling settings are seed 0, CFG 3.0 and 50 steps.
- Weights and code: SupraLabs/Supra2-IMG
- Text encoder: google/flan-t5-base
- VAE: stabilityai/sd-vae-ft-mse
- Lab: supra-labs.com
Comments
Sign in with GitHub to join the discussion.