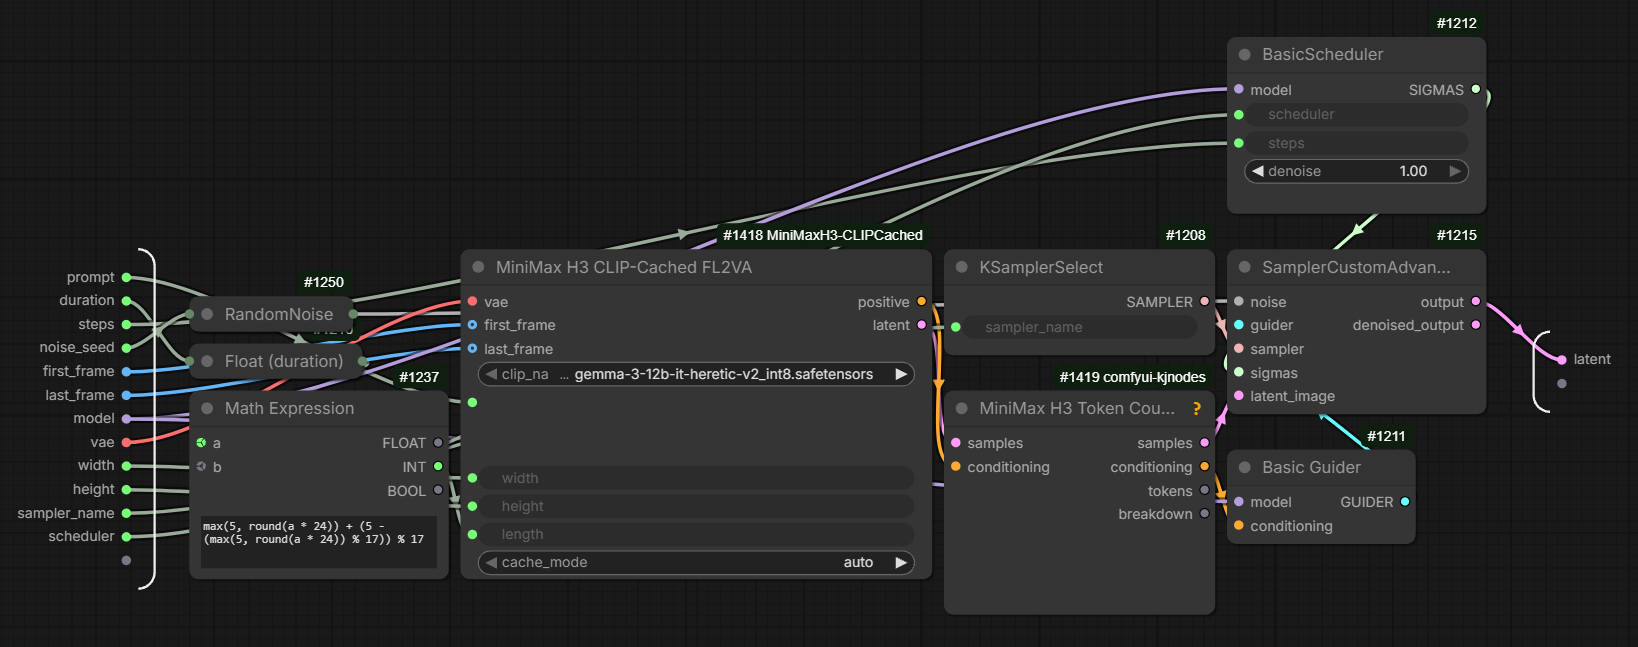
Text to videoA new ComfyUI node caches MiniMax H3 Qwen3-VL conditioning to disk: repeat runs with the same prompt skip the 14.6 GB encoder, dropping conditioning from 29.9 s to 1.1 s.
ComfyUI ecosystem updates — open-source model releases, custom nodes, workflows, and tools for image, video, and audio generation.
Text to videoA new ComfyUI node caches MiniMax H3 Qwen3-VL conditioning to disk: repeat runs with the same prompt skip the 14.6 GB encoder, dropping conditioning from 29.9 s to 1.1 s.
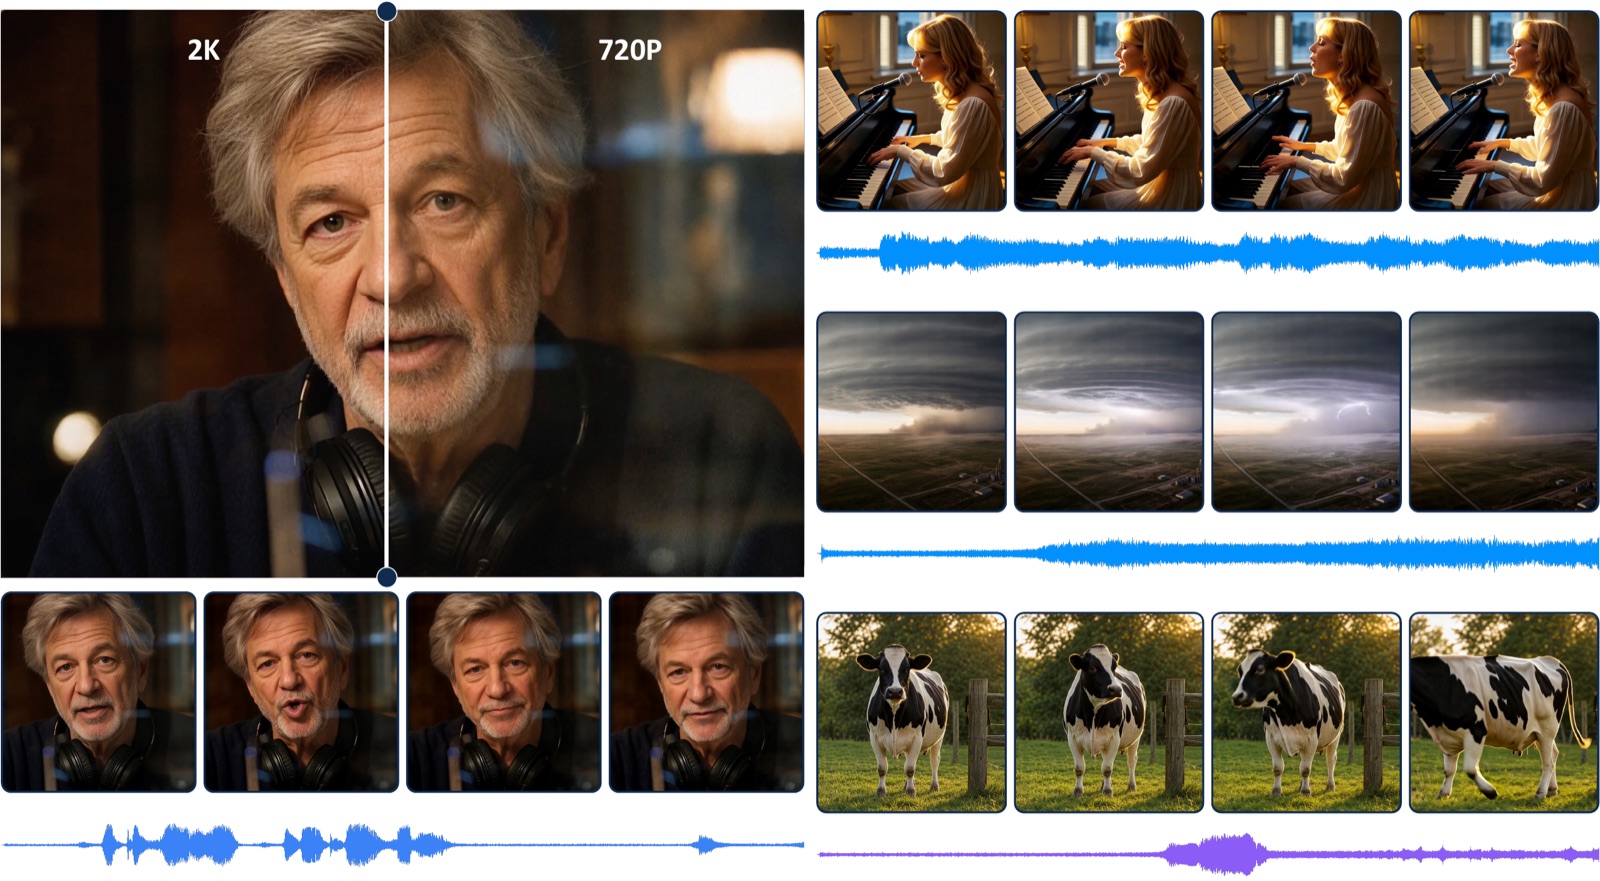
Text to videoAMap open-sources DreamX-Creator 1.0, a 7B joint audio-video generator with gated cross-modal attention and a 1-step 2K refiner, built on Wan2.2 and fully downloadable.
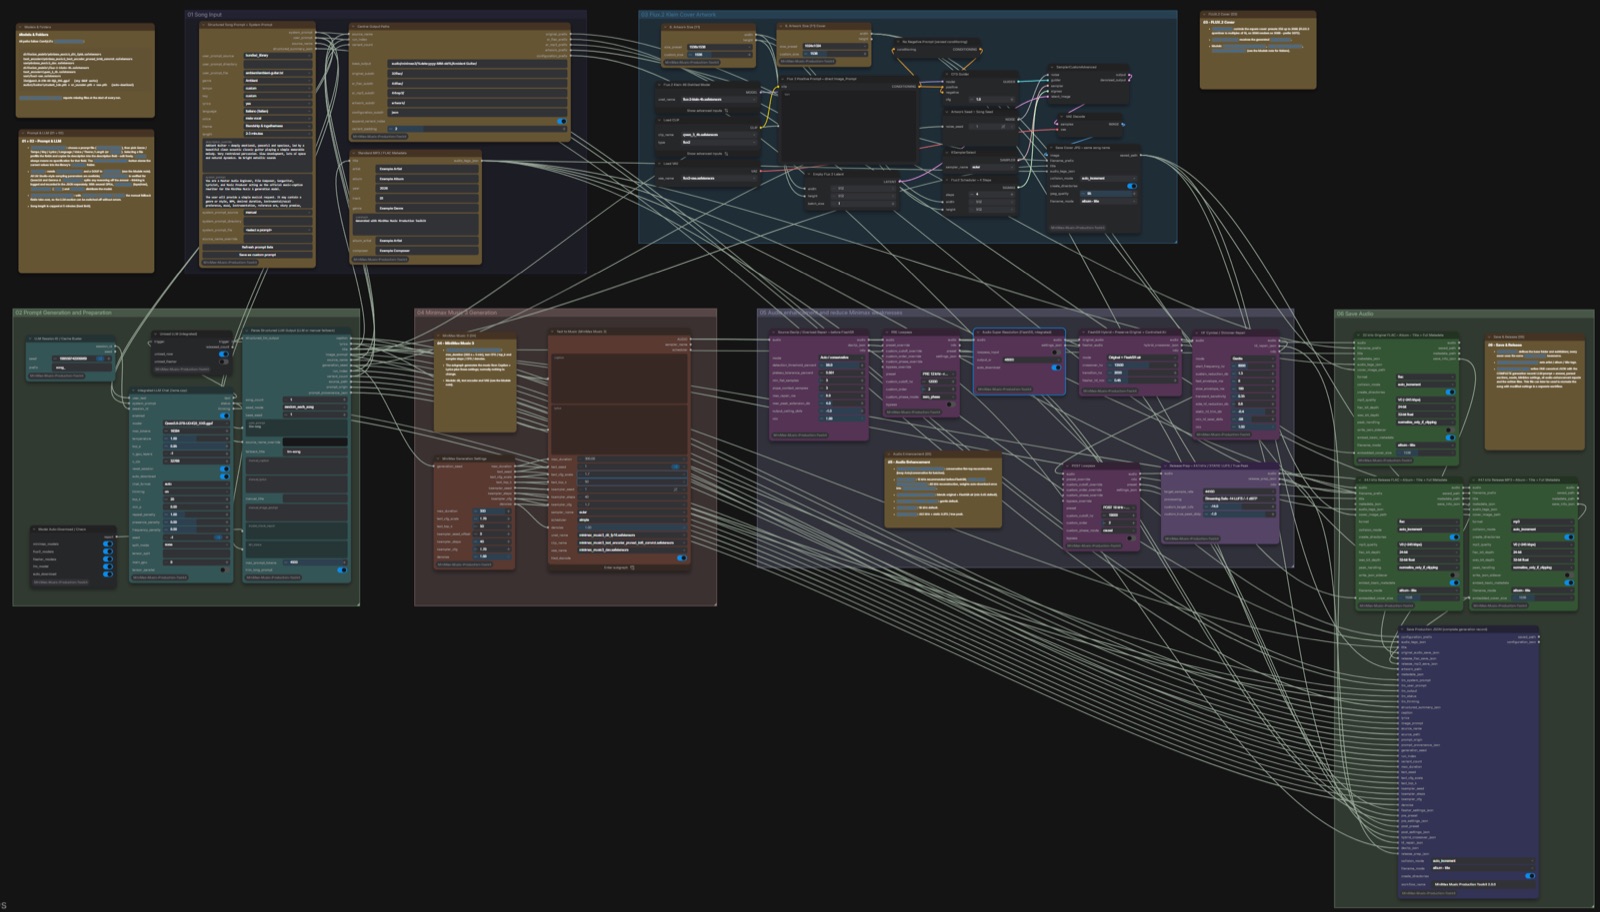
MultimodalA free MIT node pack turns ComfyUI into a MiniMax Music 3 production studio: LLM-written song prompts, 62 genre presets, FlashSR upscaling to 48 kHz and automatic FLUX.2 cover art.
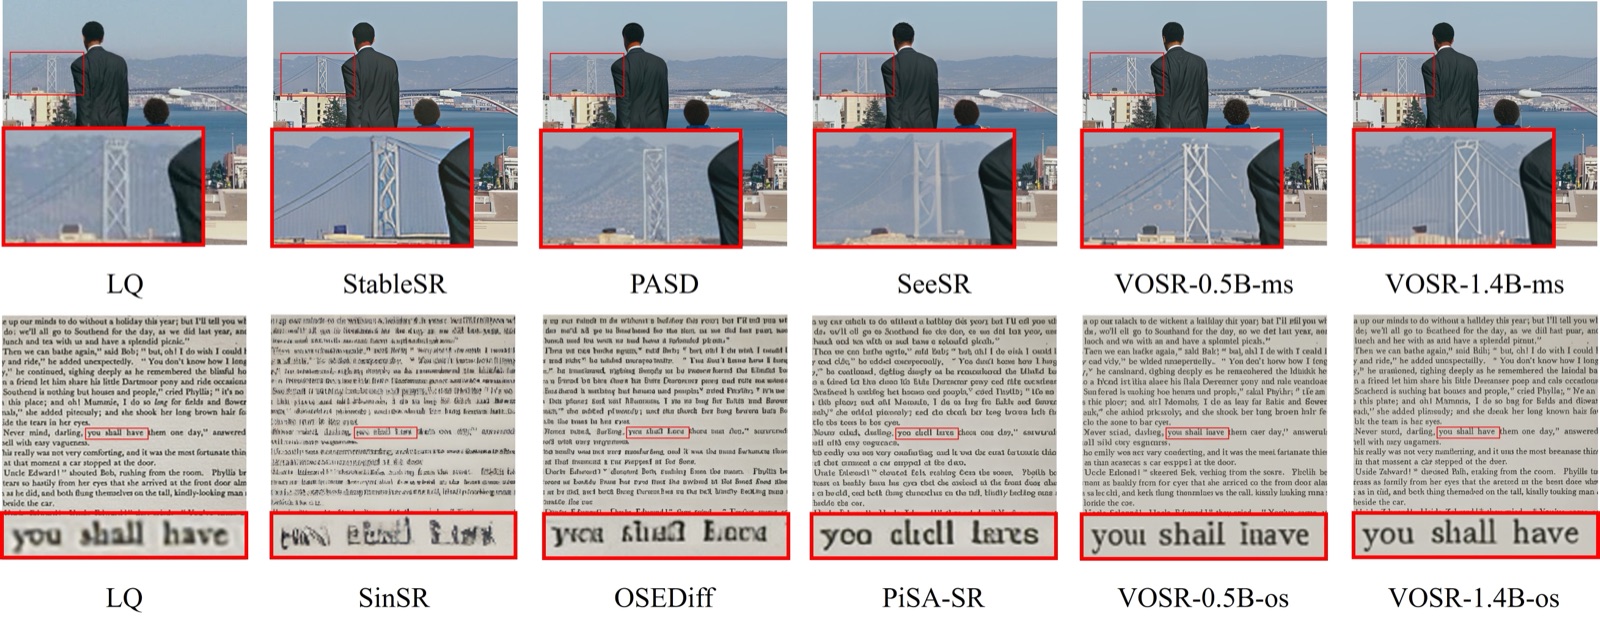
Image to imageCommunity nodes for VOSR 2.0: a one-step 1.4B super-resolution model with a Qwen-Image VAE and DINOv2 conditioning, auto-downloading weights and tiled 4x upscaling.
Text to videoComfyUI's MiniMax video nodes add H3 Max and H3 Max Turbo: a quality-focused and a speed-focused hosted variant supporting text-to-video, first-last-frame, and reference workflows.
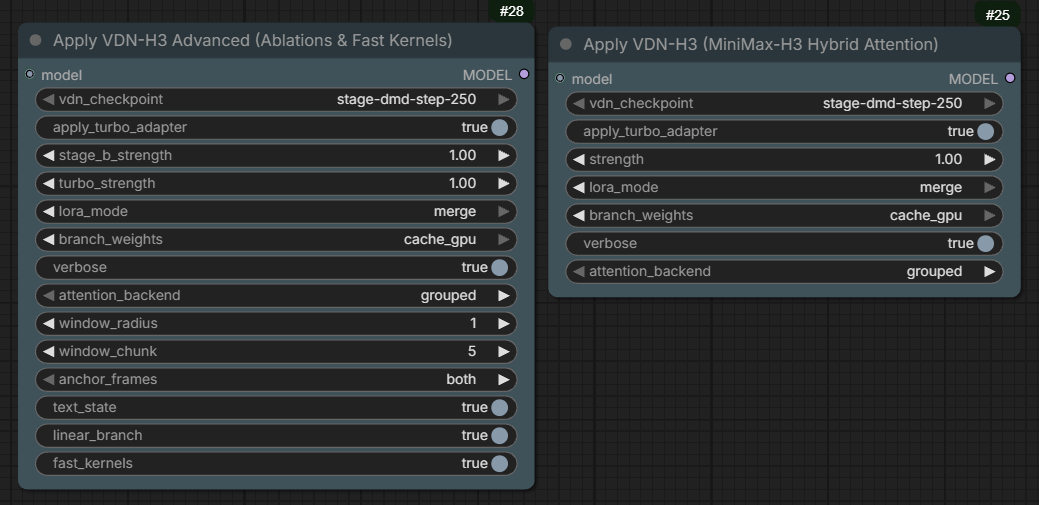
Text to videoOpenVDN's Video DeltaNet hybrid attention checkpoint for MiniMax H3 renders a 14.4s 768p clip in 8 steps, with a community ComfyUI port already available.
minimax-h3-community-license-agreement
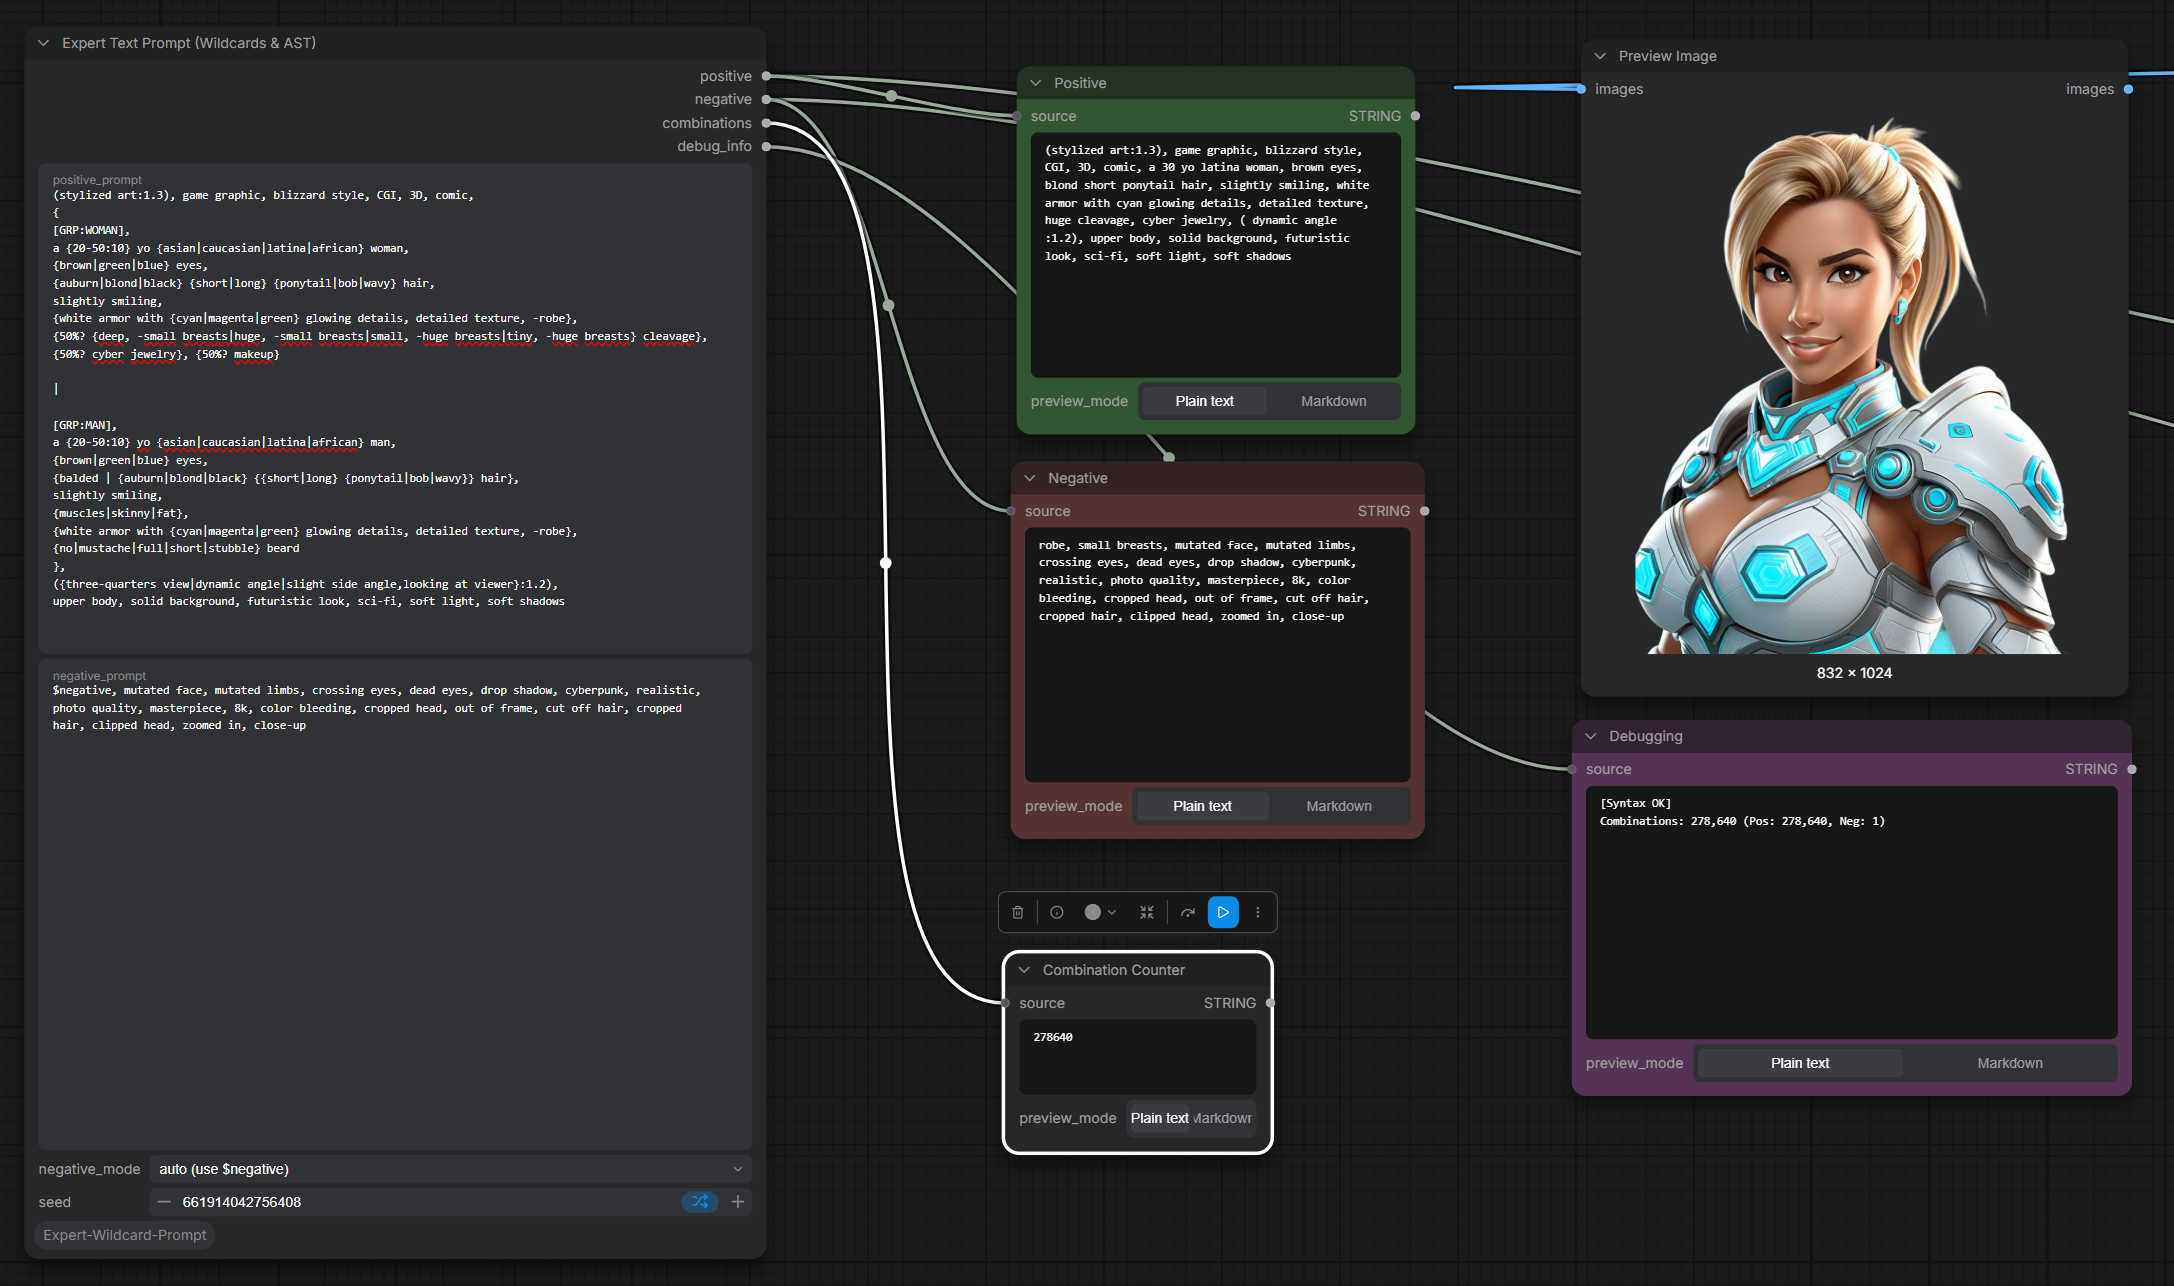
Text to imageA new ComfyUI custom node parses prompts as an AST: weighted wildcards, prompt groups, inline mute and solo, automatic negative routing and a built-in syntax checker.
Image to imageProvcheck v1.4.0 brings an offline C2PA signing node to ComfyUI: neural watermarks for image and audio, plus Content Credentials bound to your Bluesky handle.
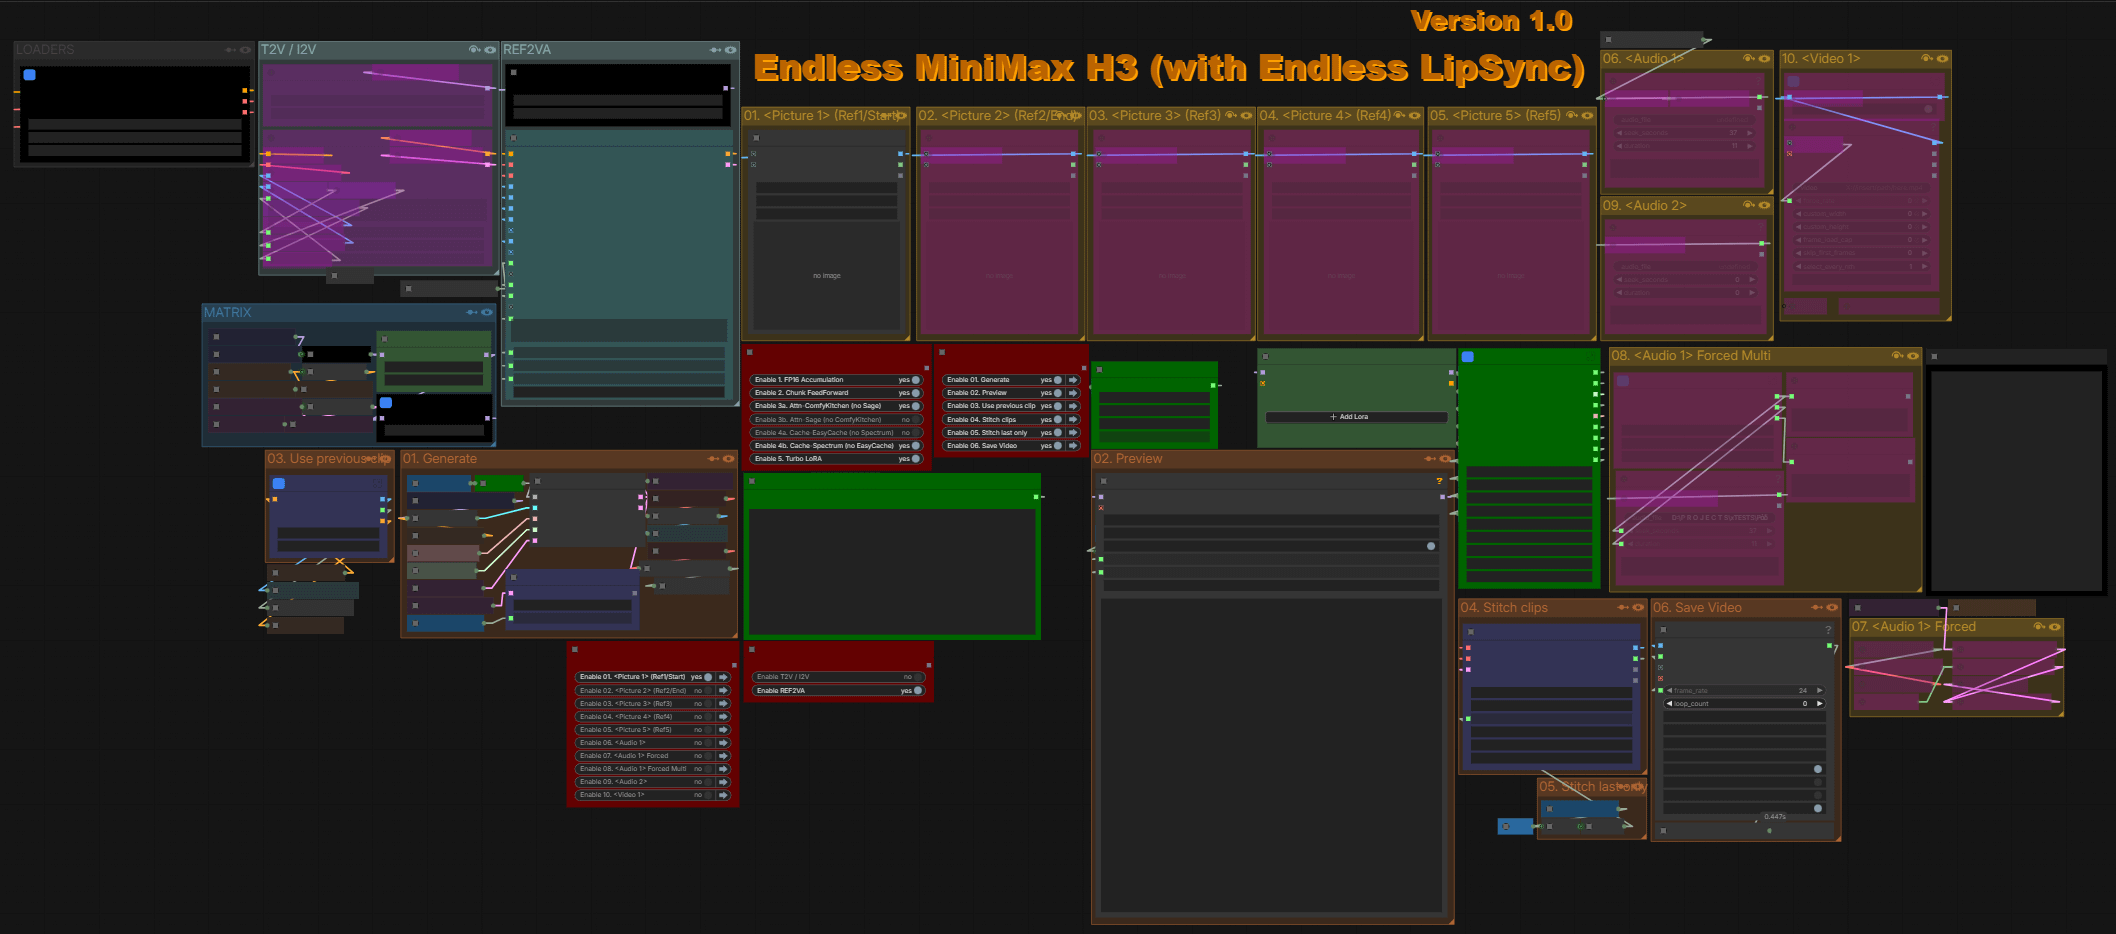
Image to videoA new workflow combines H3 Motion Context with a latent-saver node to chain MiniMax H3 clips into unlimited-length videos, with lip-sync, on a 12GB GPU.
Image to imageVibeComfy translates ComfyUI workflow JSON into editable Python for CLI agents, and now pairs with the Hivemind knowledge base for community-sourced workflow patterns.
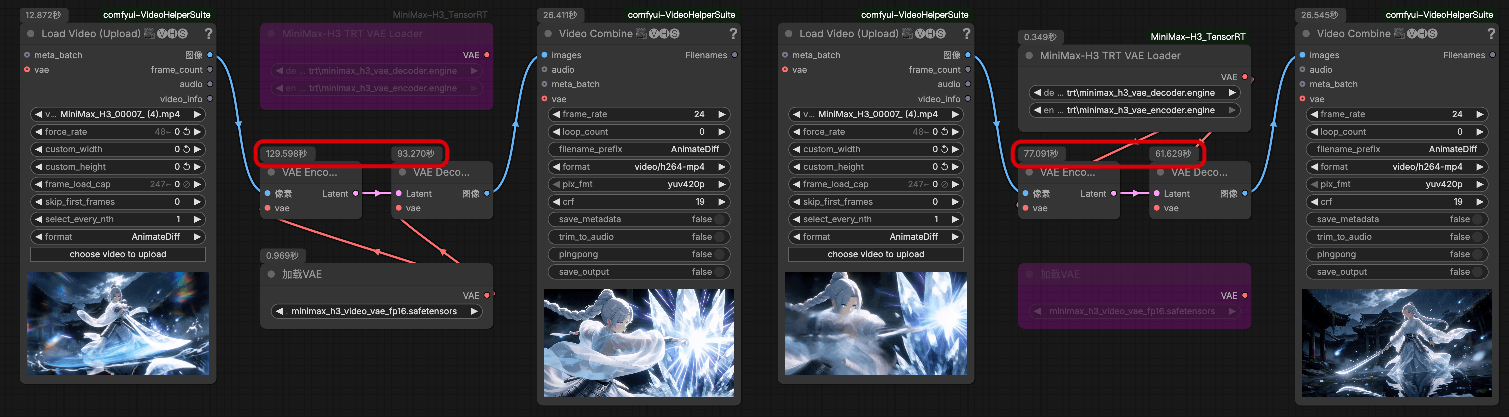
EcosystemA ComfyUI node pack compiles the MiniMax H3 video VAE to TensorRT engines, cutting VAE encode and decode time by up to 1.7x, with a w4a16 decoder for low VRAM.
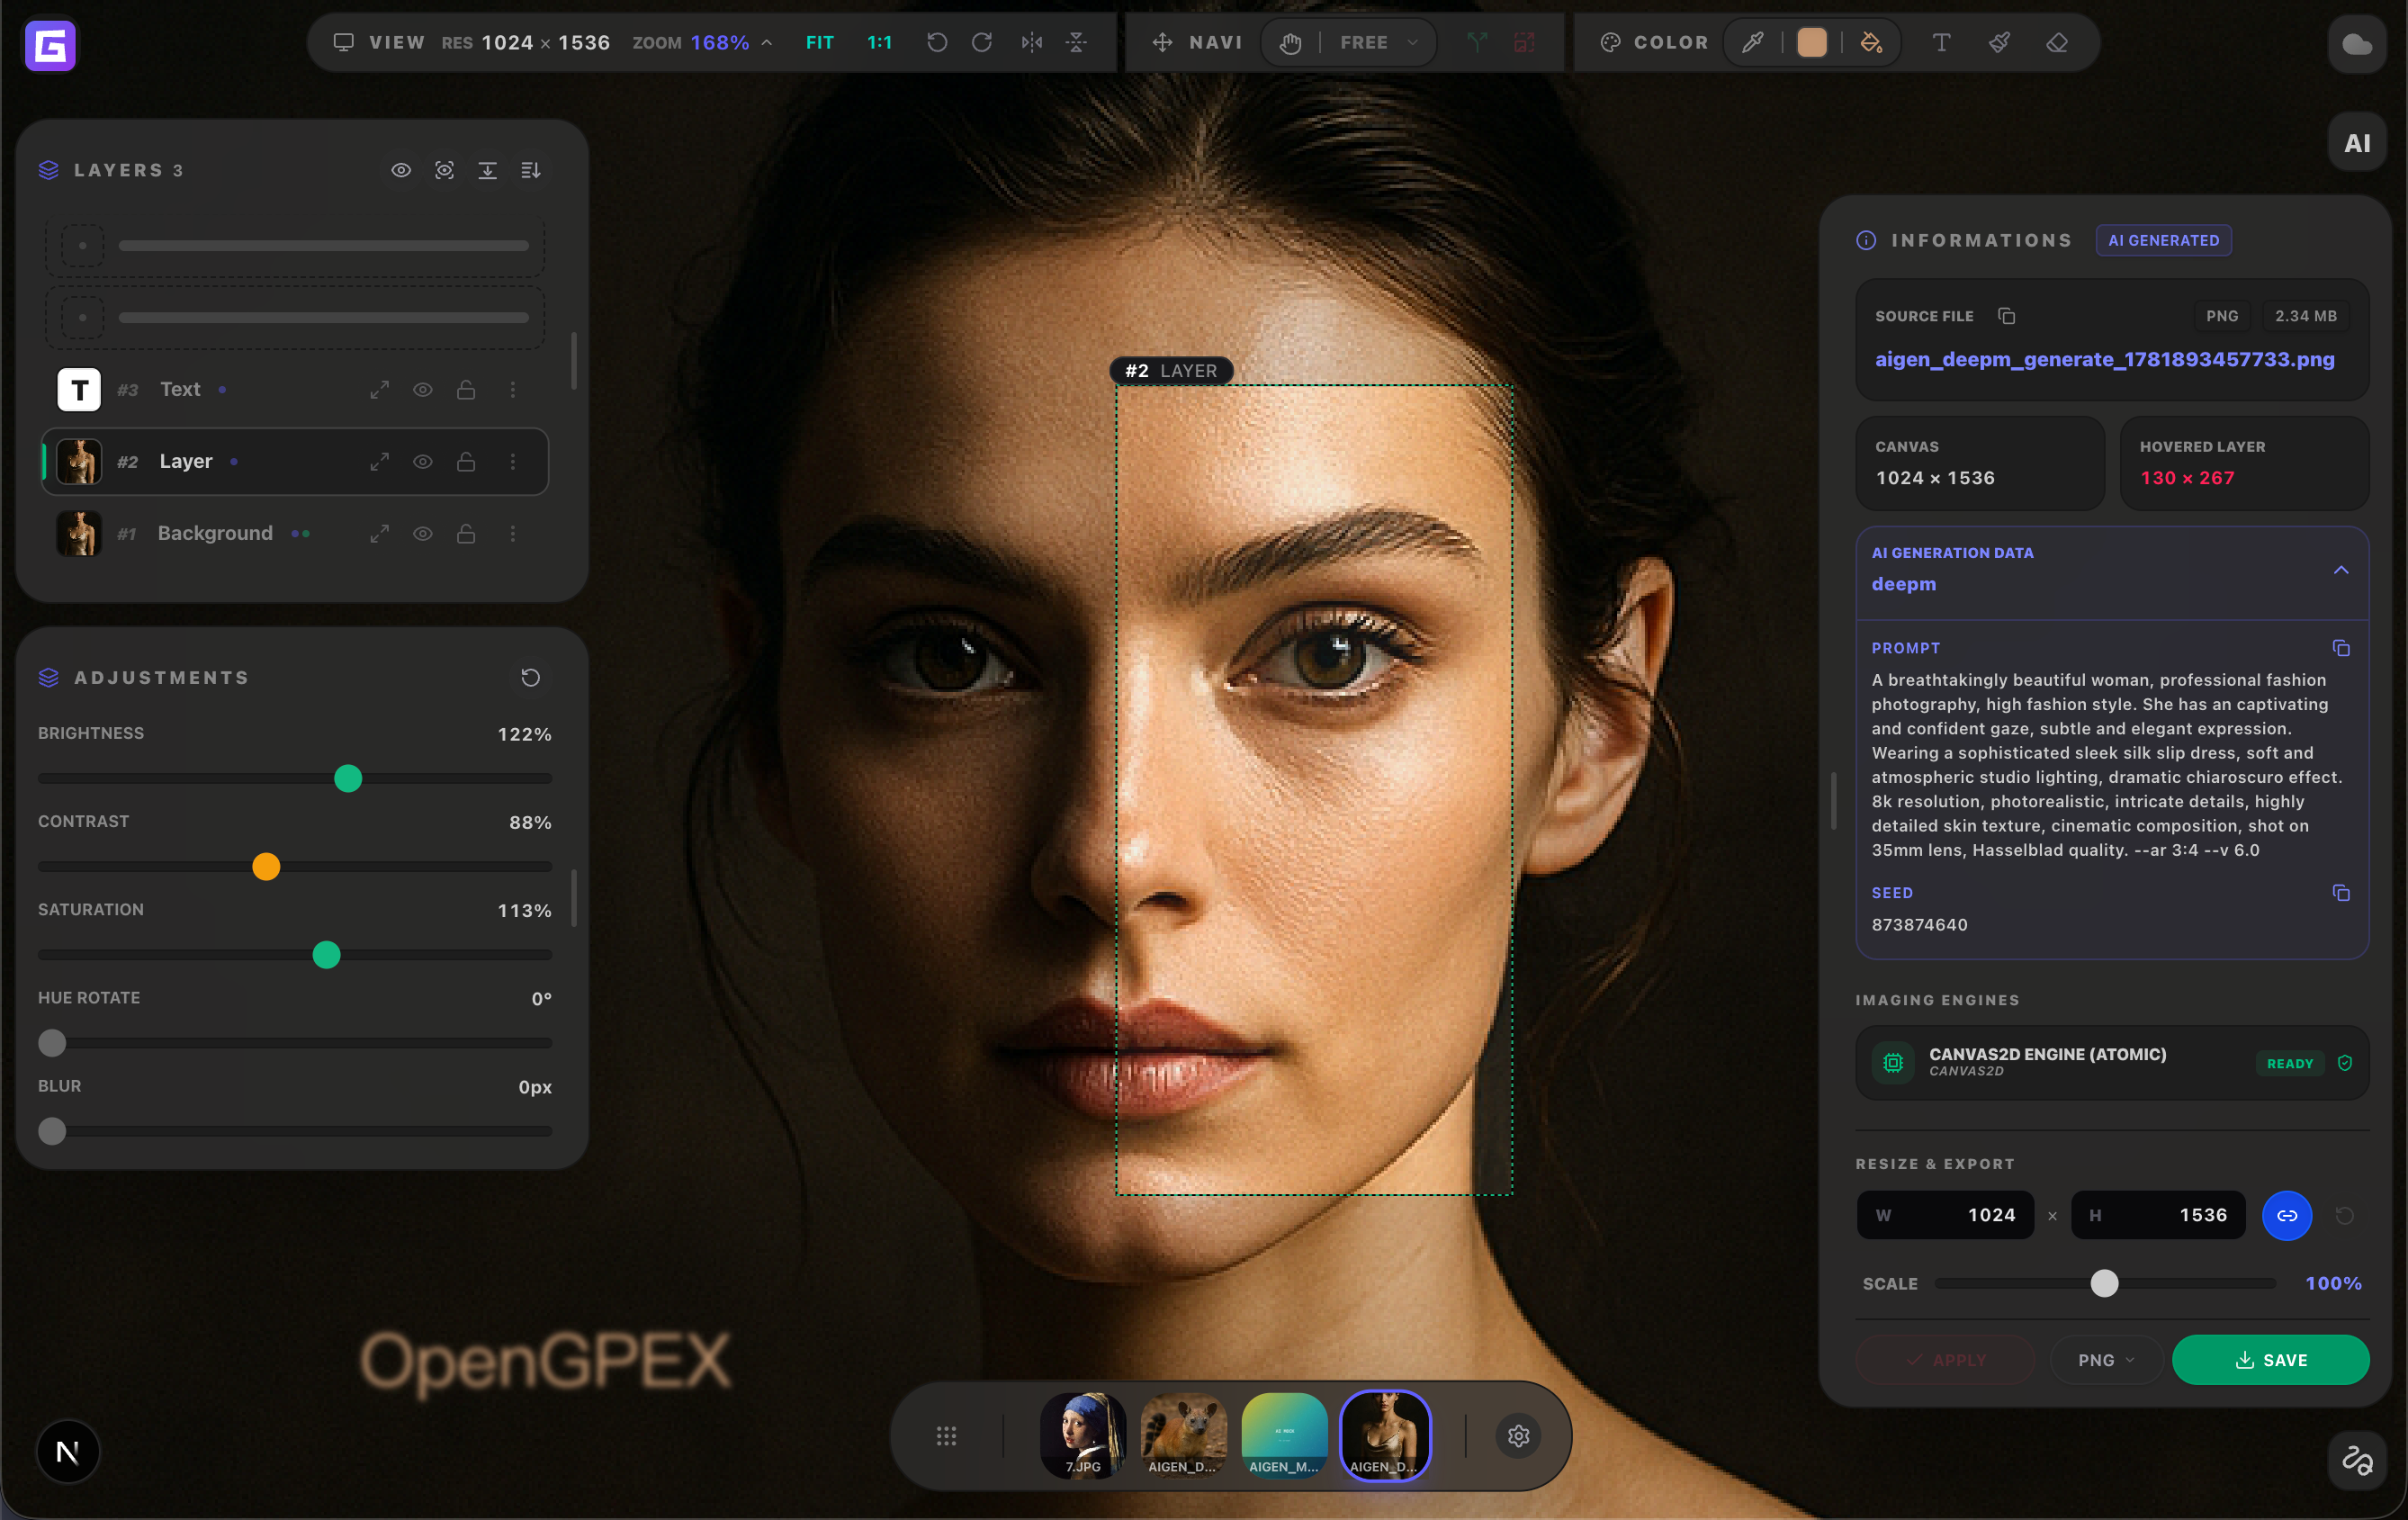
Image editingOpenGPEX is an open-source browser image editor that connects to your ComfyUI instance, runs any workflow and drops the result back as an editable layer.
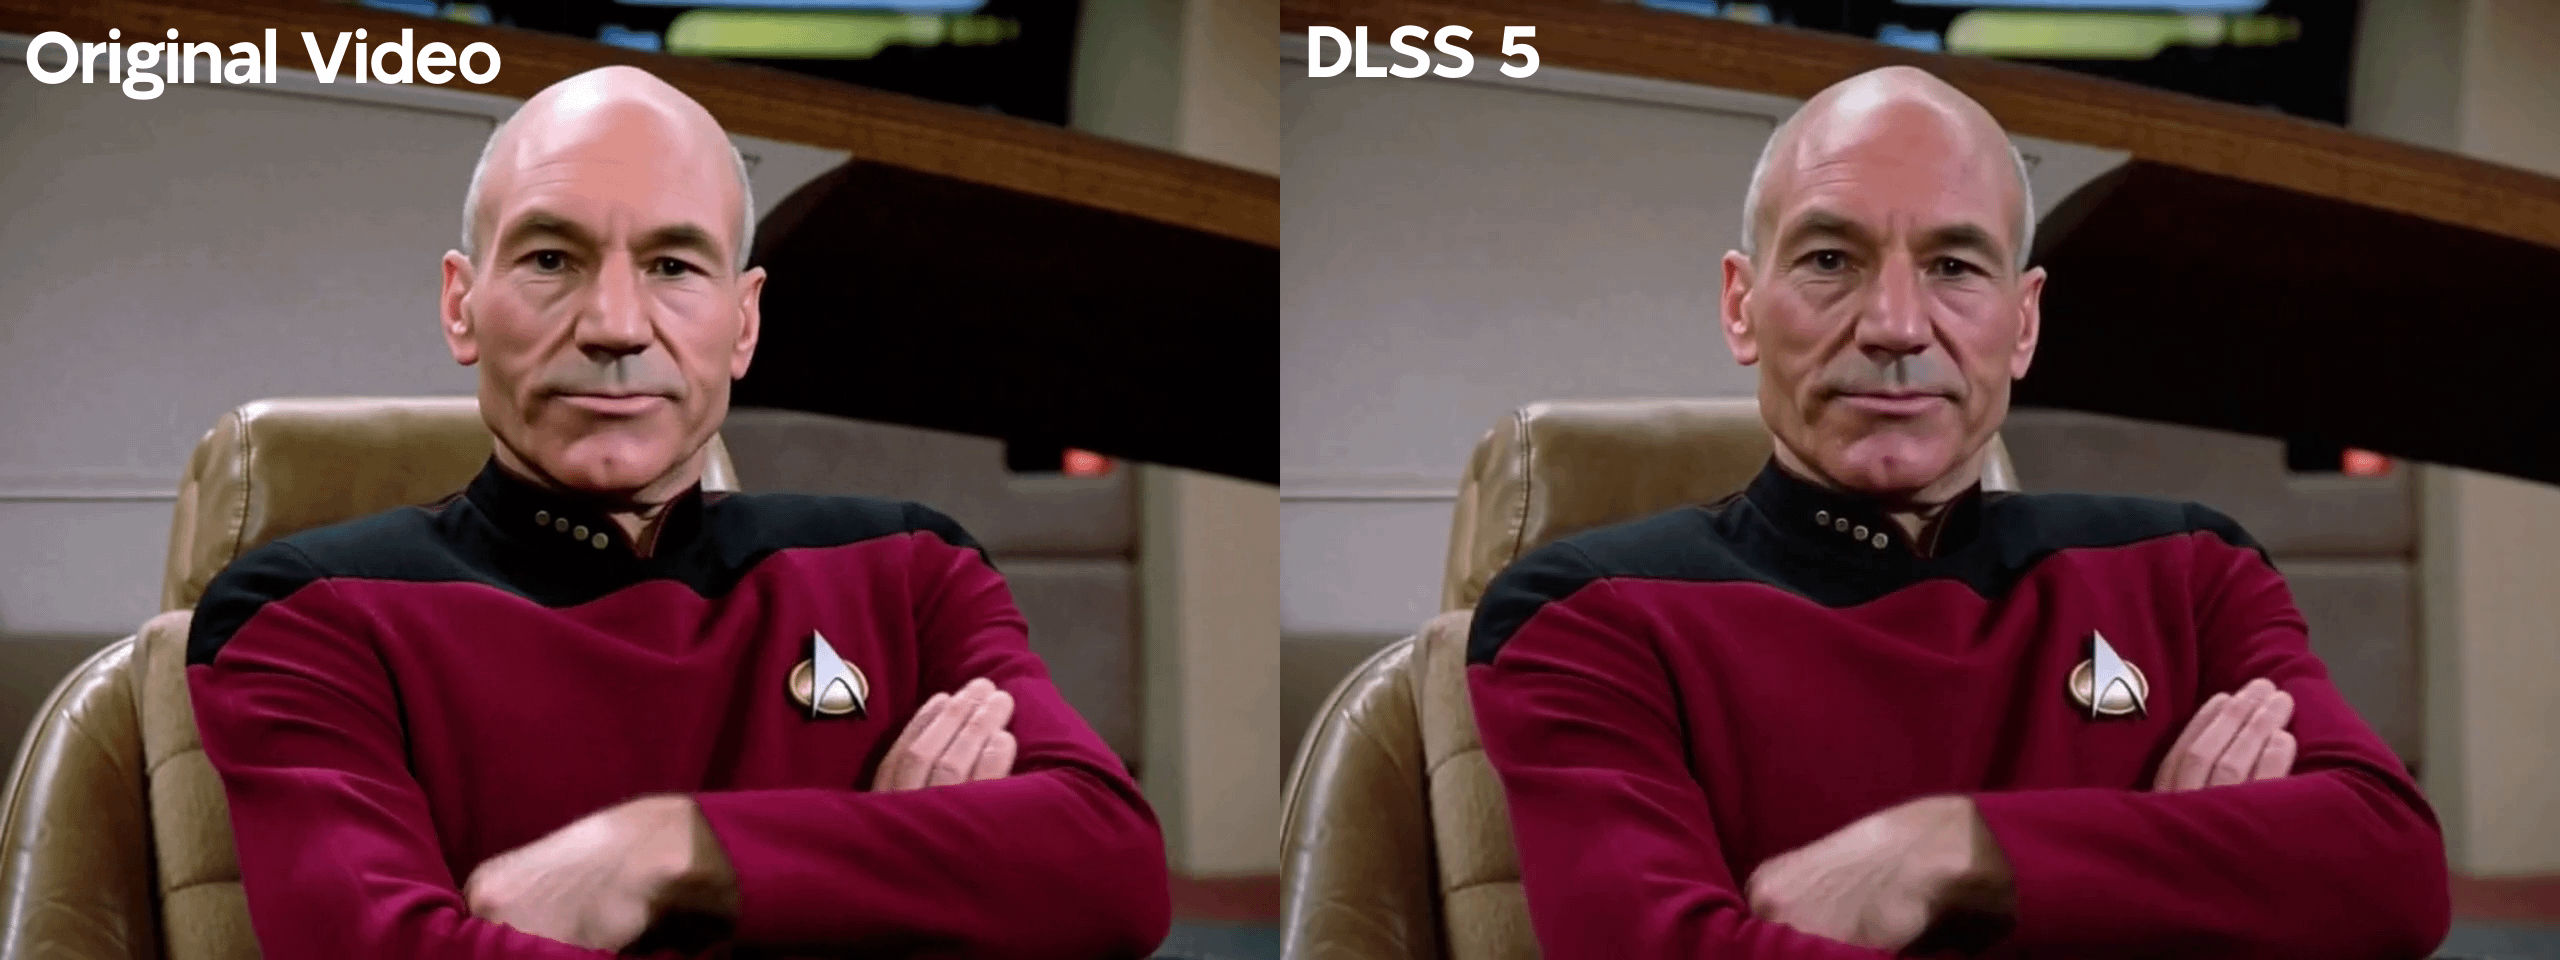
Image to imageAn experimental ComfyUI node runs NVIDIA DLSS 5 Neural Rendering in-process through a D3D12 bridge, enhancing images and video frames without leaving your workflow.
Text to videoA blind A/B arena from the ComfyUI community ranks 23 MiniMax H3 acceleration variants: FastH3, H3 Turbo distills, SLA, PDD and merges, voted on 4000 pre-generated clips.
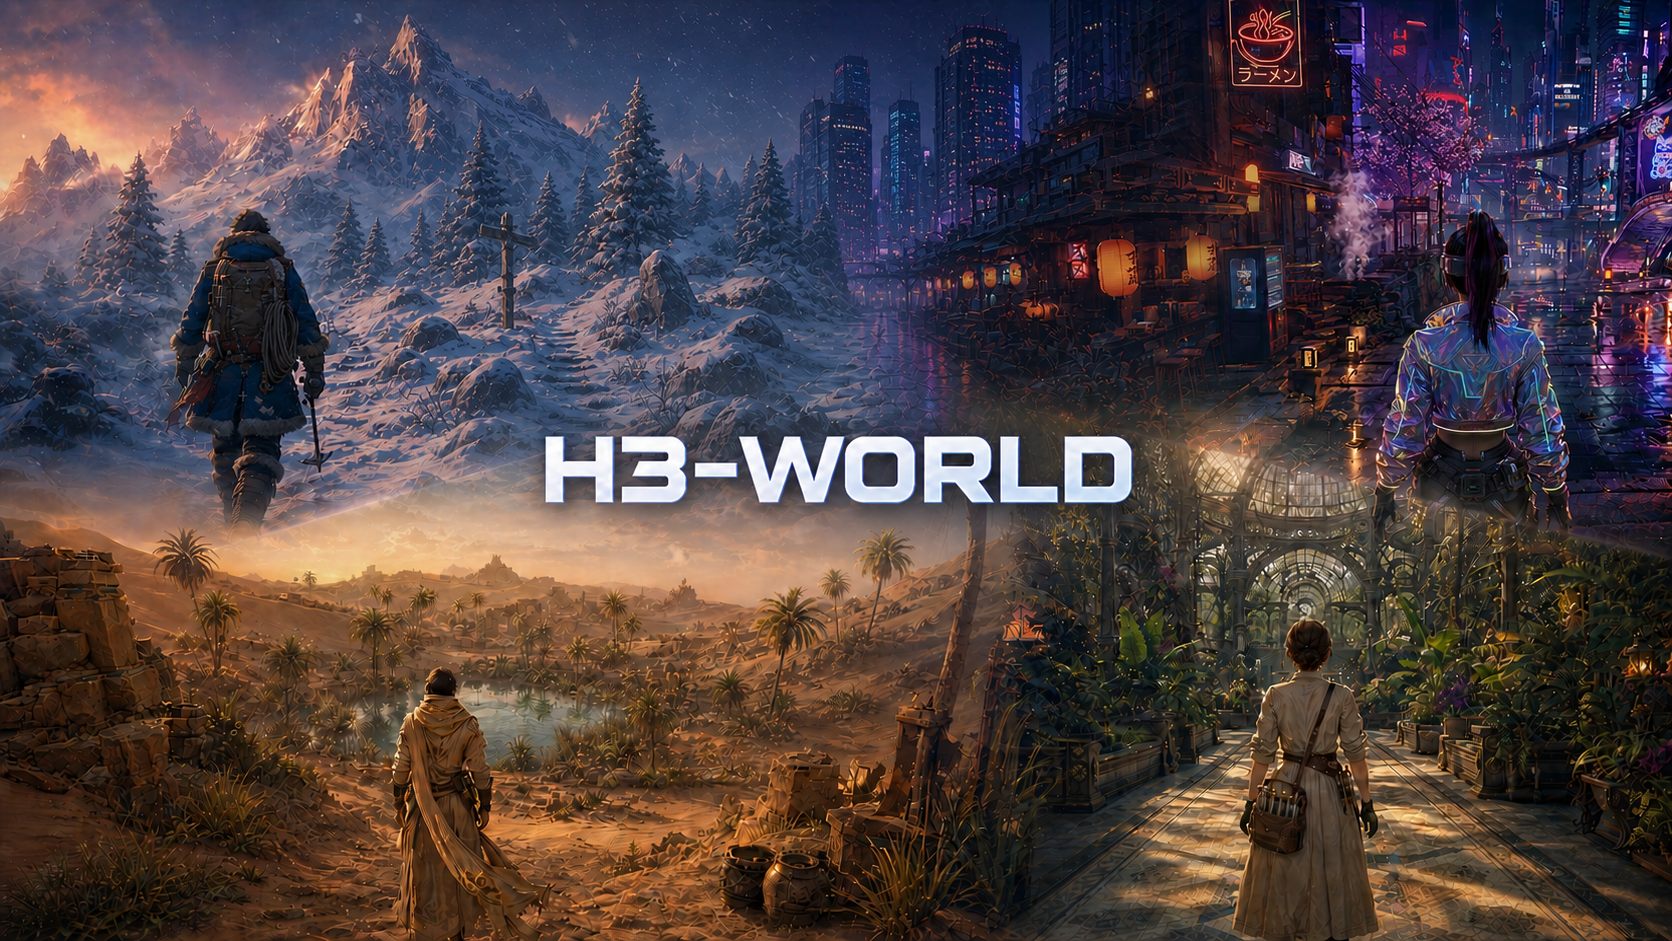
Image to videoH3-World turns MiniMax H3 into an interactive world model: a 65.6M LoRA plus an attention patch maps WASD and camera keys to action-controlled video from a single frame.
apache-2.0
Text to imageAn open source C++20 compiler for diffusion models runs Krea 2 Turbo prompt-to-PNG over 2x faster than ComfyUI on an RTX 3090 Ti, with MiniMax H3 in progress.
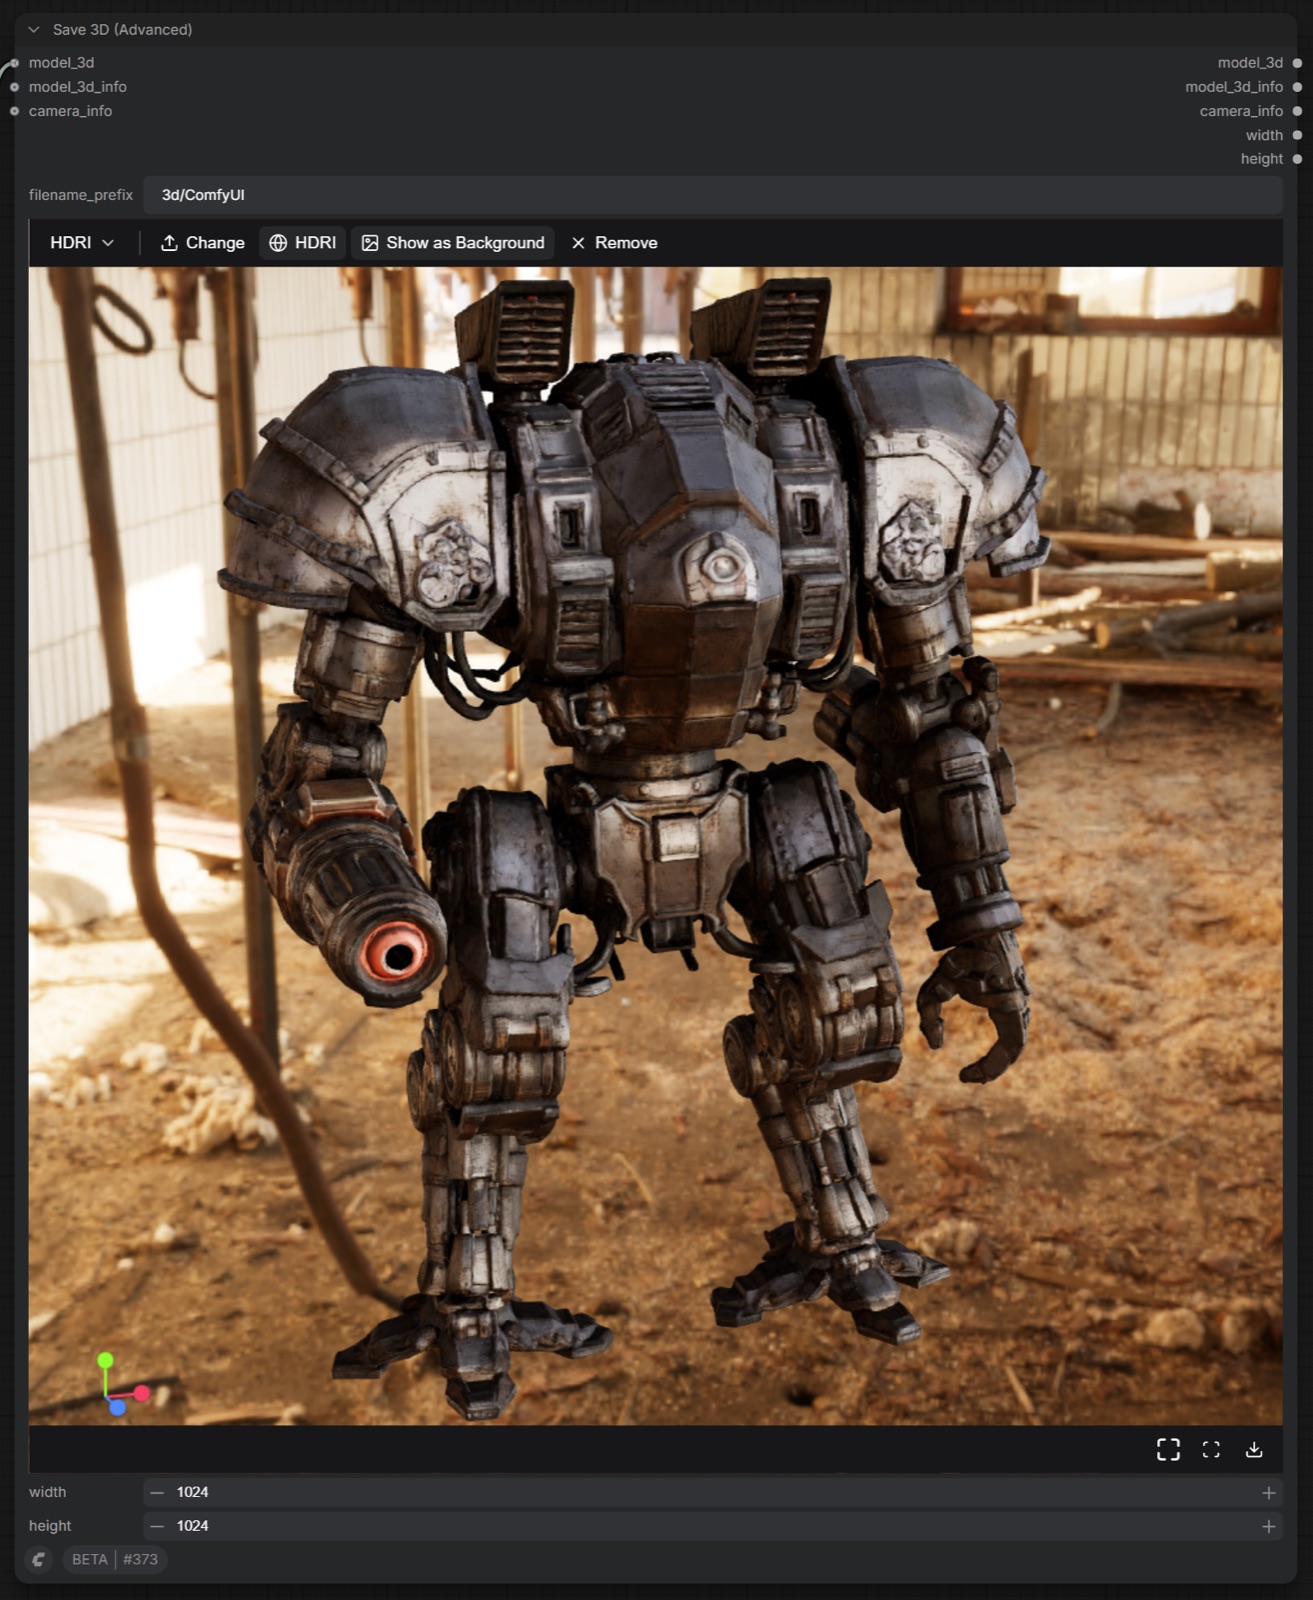
Image to 3DComfyUI core adds native Pixal3D multi-view support with new official bf16 and INT8 weights, turning four orbit shots or MV-diffusion output into a cleaner mesh.
MIT
Video editingViggle-Animate is a 33.1B finetune of MiniMax H3 ref2va with DMD distillation that swaps video characters from one repainted frame, 3 forward passes, 26 seconds per clip.
minimax-h3-community-license-agreement
vh5tape makes MiniMax H3 footage look like a worn 1980s VHS recording, with tracking noise, chroma bleed and matching tape-hiss audio. Three prompt-controlled damage levels.
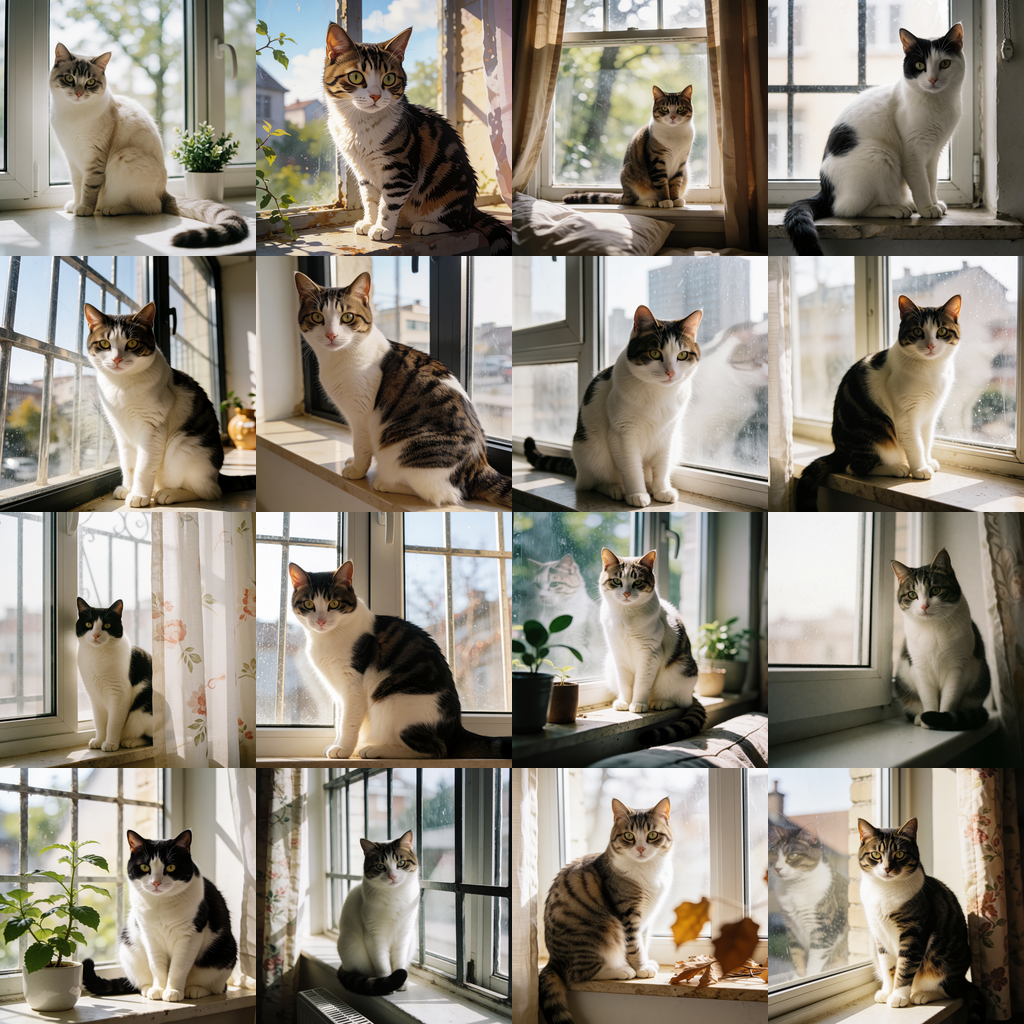
Text to imageF16 releases a Krea 2 Turbo LoRA trained with Semantic Directional Alignment: the same prompt now yields different cats, cars and scenes across seeds, with no quality loss.
krea-2-community-license