MiniMax H3 TRT VAE: 1.7x Faster H3 Decode in ComfyUI
A ComfyUI node pack compiles the MiniMax H3 video VAE to TensorRT engines, cutting VAE encode and decode time by up to 1.7x, with a w4a16 decoder for low VRAM.
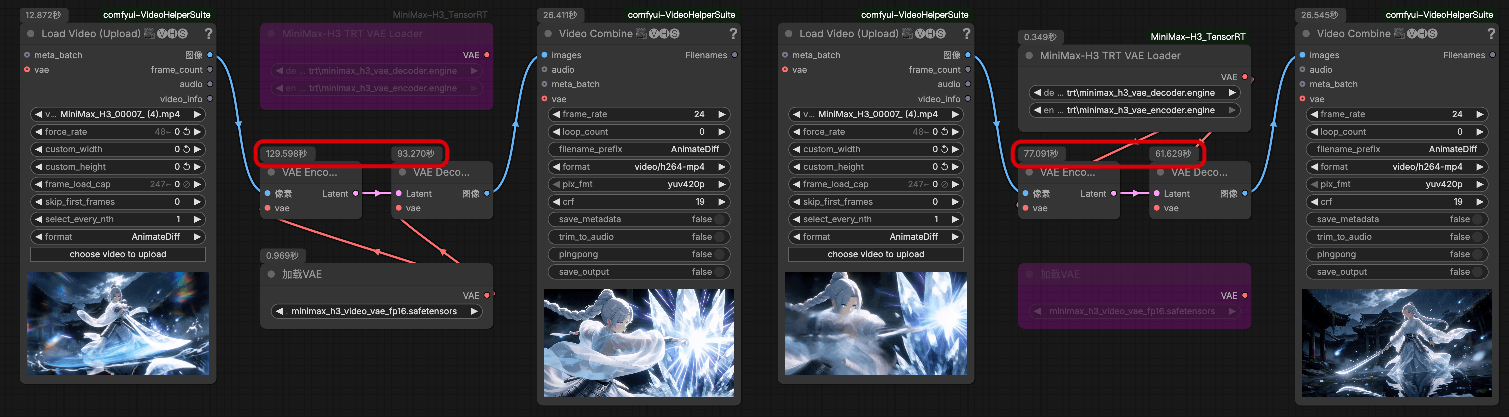
Preview from the project README: the TRT VAE compile and load nodes inside a ComfyUI graph.
VAE decode is a fixed cost on every H3 run. The built-in ComfyUI kernels already shrank that cost on the PyTorch side; this node takes the other route and hands the VAE to a compiled TensorRT engine.
What the node does
The pack ships two nodes and an ONNX route to the engine:
- MiniMax-H3 TRT VAE Compiler takes the ONNX encoder and decoder and builds TensorRT engines. This is a one-time step, and the compiled engines are reused afterwards.
- MiniMax-H3 TRT VAE Loader loads the compiled engines so they can be used in place of the regular VAE.
Weights are published as ONNX files on Hugging Face and go into ComfyUI/models/vae. The pack also includes a standalone compile.py for building the engines outside ComfyUI, which is useful when the compile step should not block the UI.
Setup
| Step | Action |
|---|---|
| 1 | git clone https://github.com/lihaoyun6/ComfyUI-H3VAE_TRT into ComfyUI/custom_nodes and install requirements.txt |
| 2 | Download the ONNX encoder and decoder into ComfyUI/models/vae |
| 3 | Run MiniMax-H3 TRT VAE Compiler once to build the engines |
| 4 | Switch the workflow's VAE to MiniMax-H3 TRT VAE Loader |
The ONNX repository also carries a w4a16_awq decoder variant, which the README recommends when the GPU does not have 12GB or more of VRAM.
Notes from the issue tracker
The repository's issues are worth reading before compiling, because TensorRT builds are sensitive to the installed stack:
- Engine compilation is slow. One report measured over five hours for a single build, so the first compile is best done ahead of time rather than mid-session.
- TensorRT and CUDA versions have to line up. There are open reports on TensorRT 11.2 with CUDA 13.0, and an
IBuilder::buildSerializedNetworkAPI usage error on another setup. - A grid pattern that the compiled encoder left on first, last and reference frames was reported and fixed in early September, so a build from the current
mainavoids it.
Availability
The node pack and the ONNX weights are both public:
Node pack: lihaoyun6/ComfyUI-H3VAE_TRT
ONNX weights: lihaoyun6/MiniMax-H3-VAE-ONNX
Base model: MiniMaxAI/MiniMax-H3
The pack has no bundled example workflow: the compiler and loader drop into an existing H3 graph in place of the standard VAE node.
Comments
Sign in with GitHub to join the discussion.