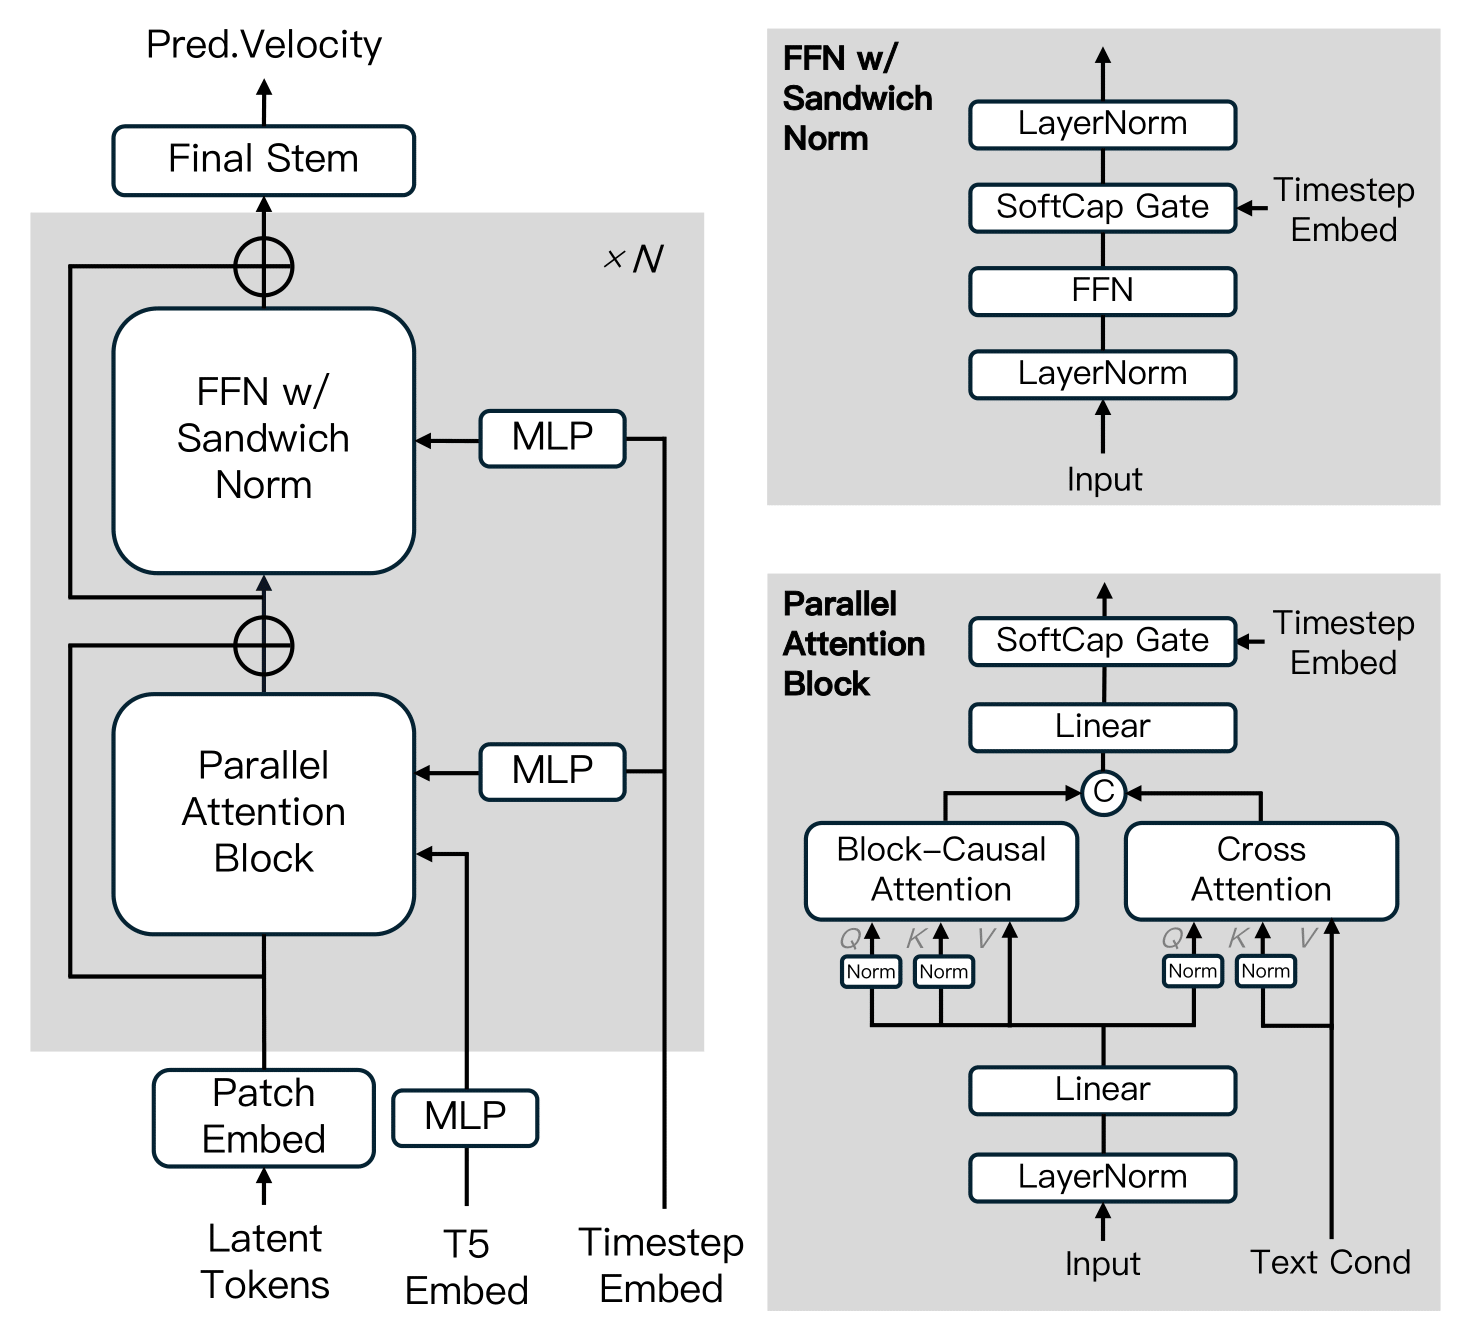
Image to videoSand AI has open-sourced MAGI-1, an autoregressive model that generates videos chunk by chunk, offering 24B and 4.5B parameter versions and supporting multiple video generation modes
Open-Weights
ComfyUI ecosystem updates — open-source model releases, custom nodes, workflows, and tools for image, video, and audio generation.
Image to videoSand AI has open-sourced MAGI-1, an autoregressive model that generates videos chunk by chunk, offering 24B and 4.5B parameter versions and supporting multiple video generation modes
Open-Weights
Image to videoSkyworkAI releases new open-source video generation model SkyReels-V2, supporting infinite-length videos with both text-to-video and image-to-video capabilities
Open-Weights
Text to speechNari Labs introduces open-source text-to-speech model Dia 1.6B, capable of generating multi-character dialogues directly from text with emotion and non-verbal communication
Open-Weights
MultimodalKunlun Wanwei's SkyReels team releases and open-sources SkyReels-V2, the world's first infinite-length film generative model using Diffusion Forcing framework, capable of producing high-quality, long-duration video content
Open-Weights
Text to imageShakker Labs launches the new FLUX.1-dev-ControlNet-Union-Pro-2.0 model with optimized control effects, support for multiple control modes, and smaller model size
Open-Weights
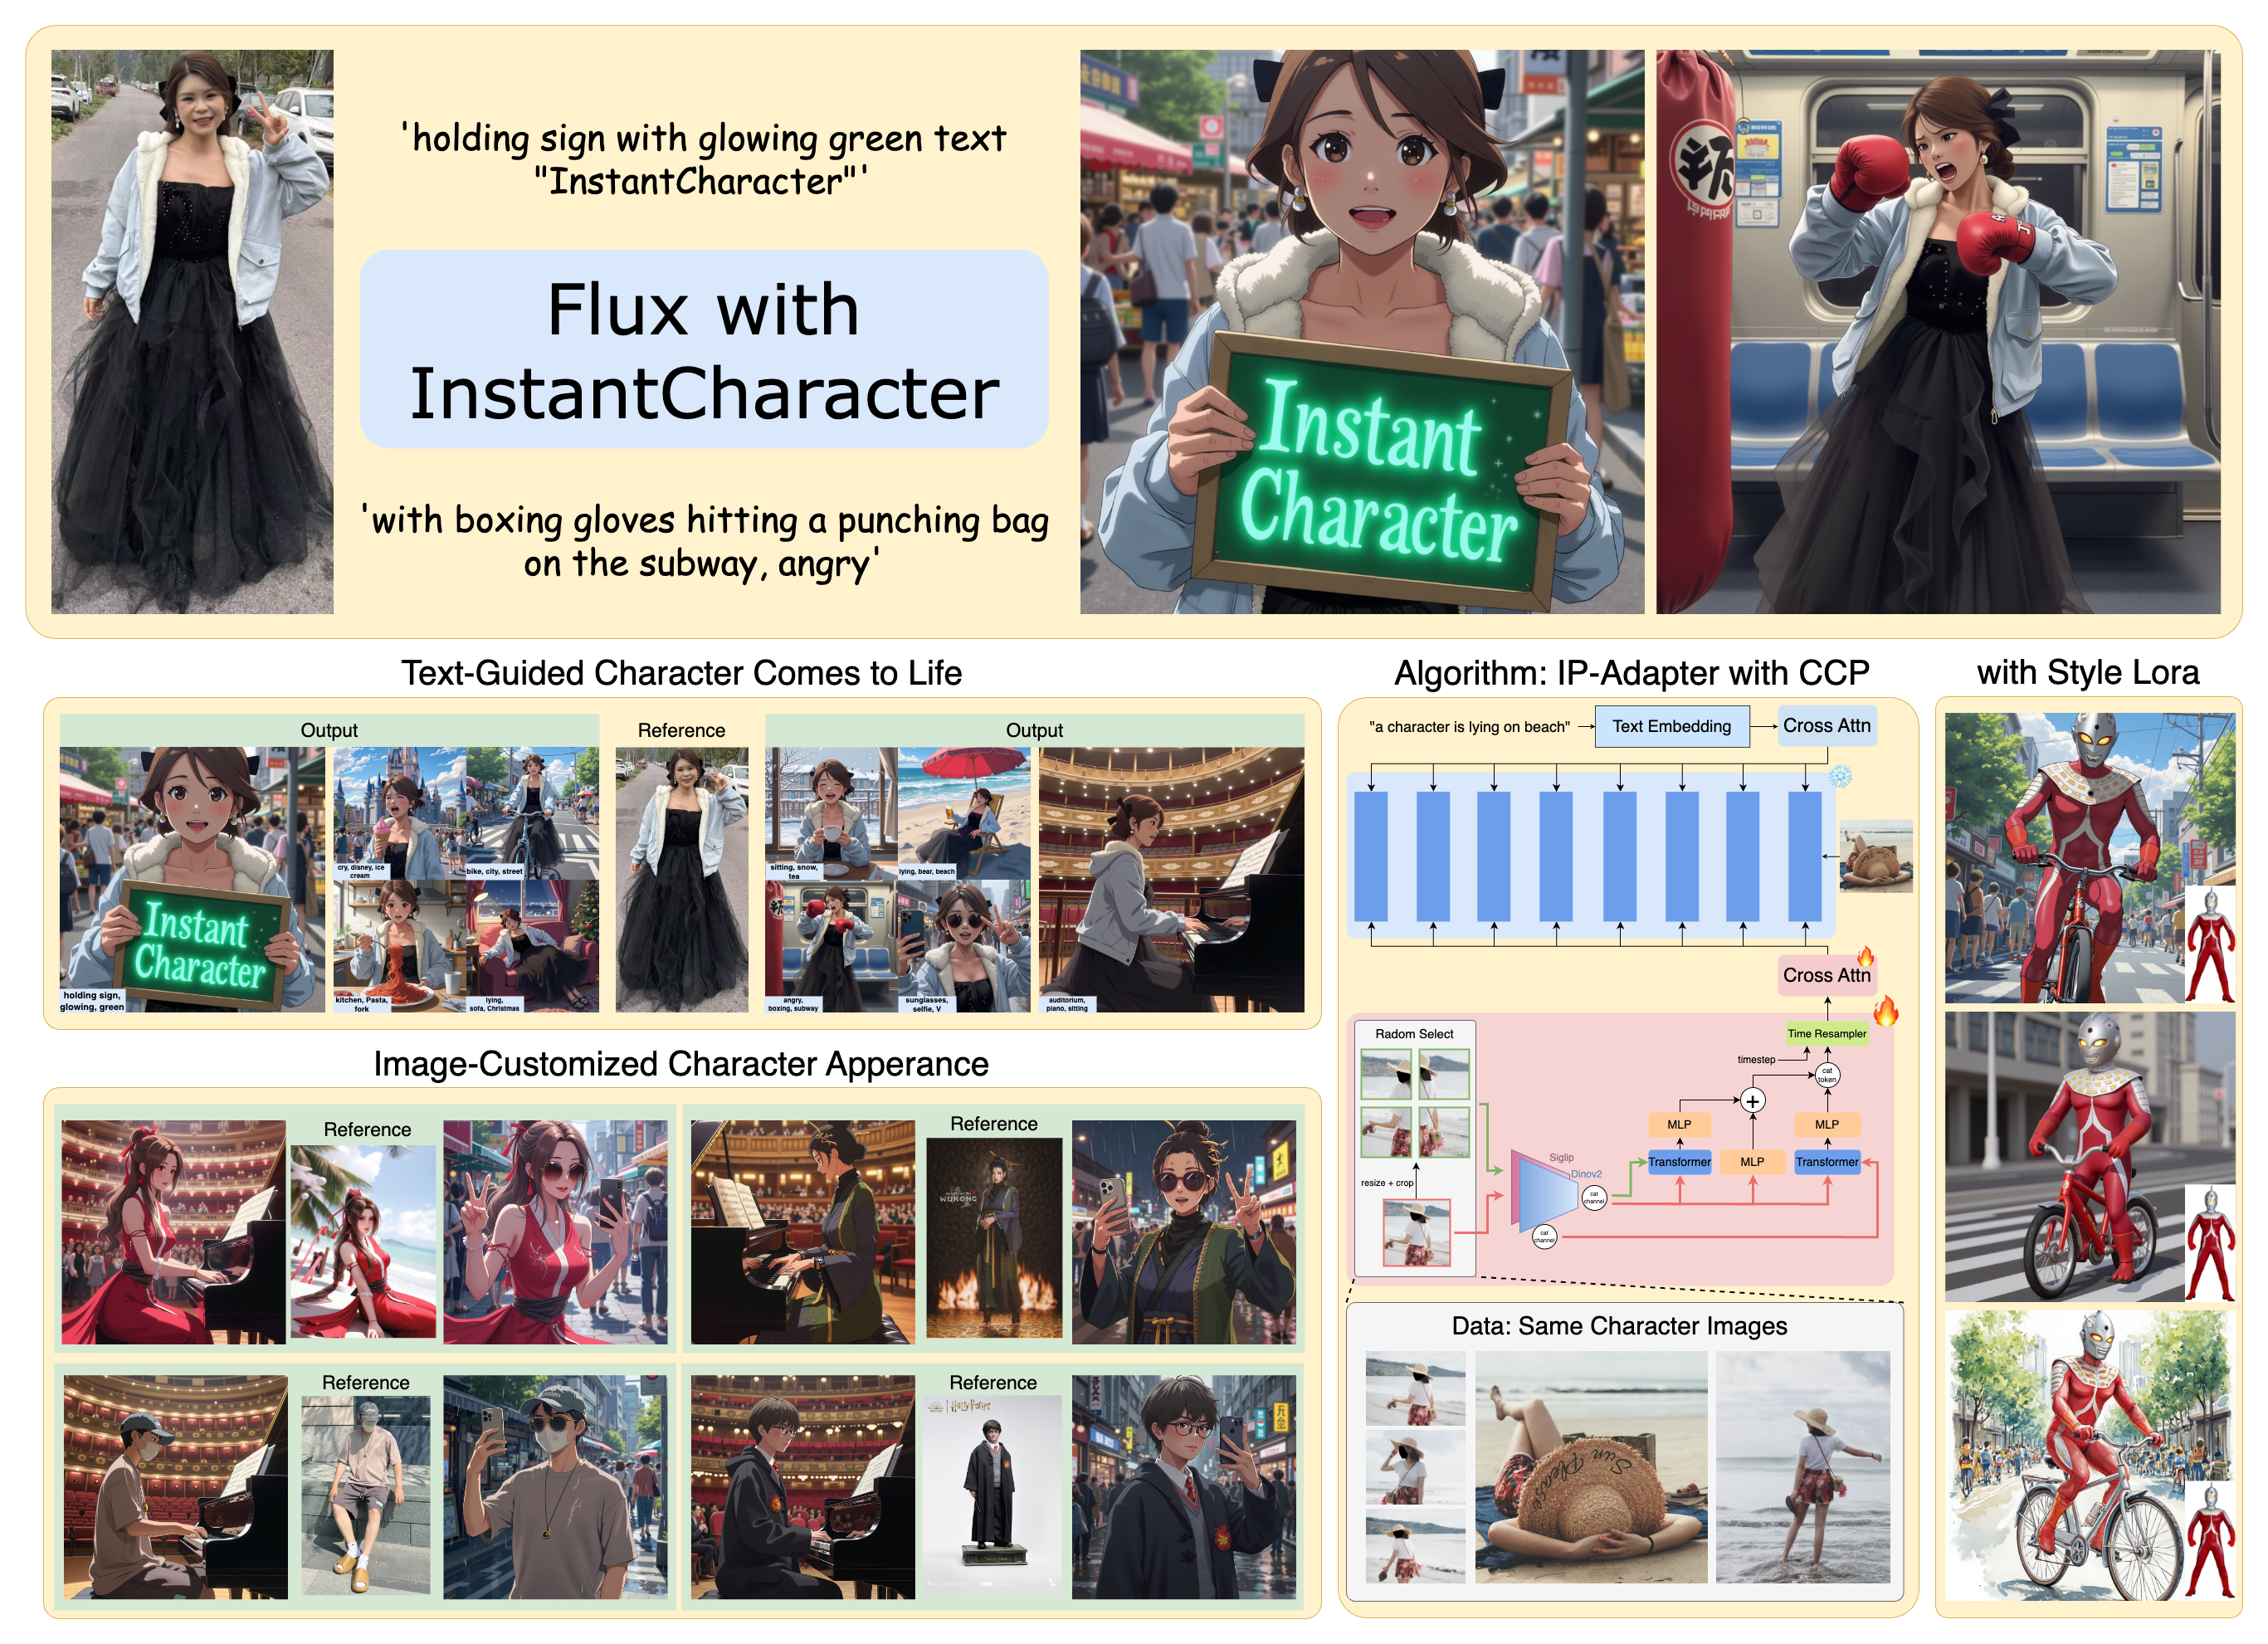
Text to imageInstantCharacter is an innovative tuning-free method that enables character-consistent generation from a single image, supporting various downstream tasks
Open-Weights
Text to videoDeveloped by Lvmin Zhang, FramePack technology compresses input frame context, making video generation workload invariant to video length, allowing processing of numerous frames even on laptop GPUs
Open-Weights
Seaweed-7B achieves performance surpassing 14B parameter models with only 7 billion parameters, at just one-third the training cost of industry standards, bringing new possibilities to the video generation field
Open-Weights
Text to videoA new video inpainting framework FloED has released its code and weights, achieving higher video coherence and computational efficiency through optical flow guidance
Open-Weights
PixelFlow innovatively operates in raw pixel space, simplifying the image generation process without requiring pre-trained variational autoencoders, enabling end-to-end trainable models
Open-Weights
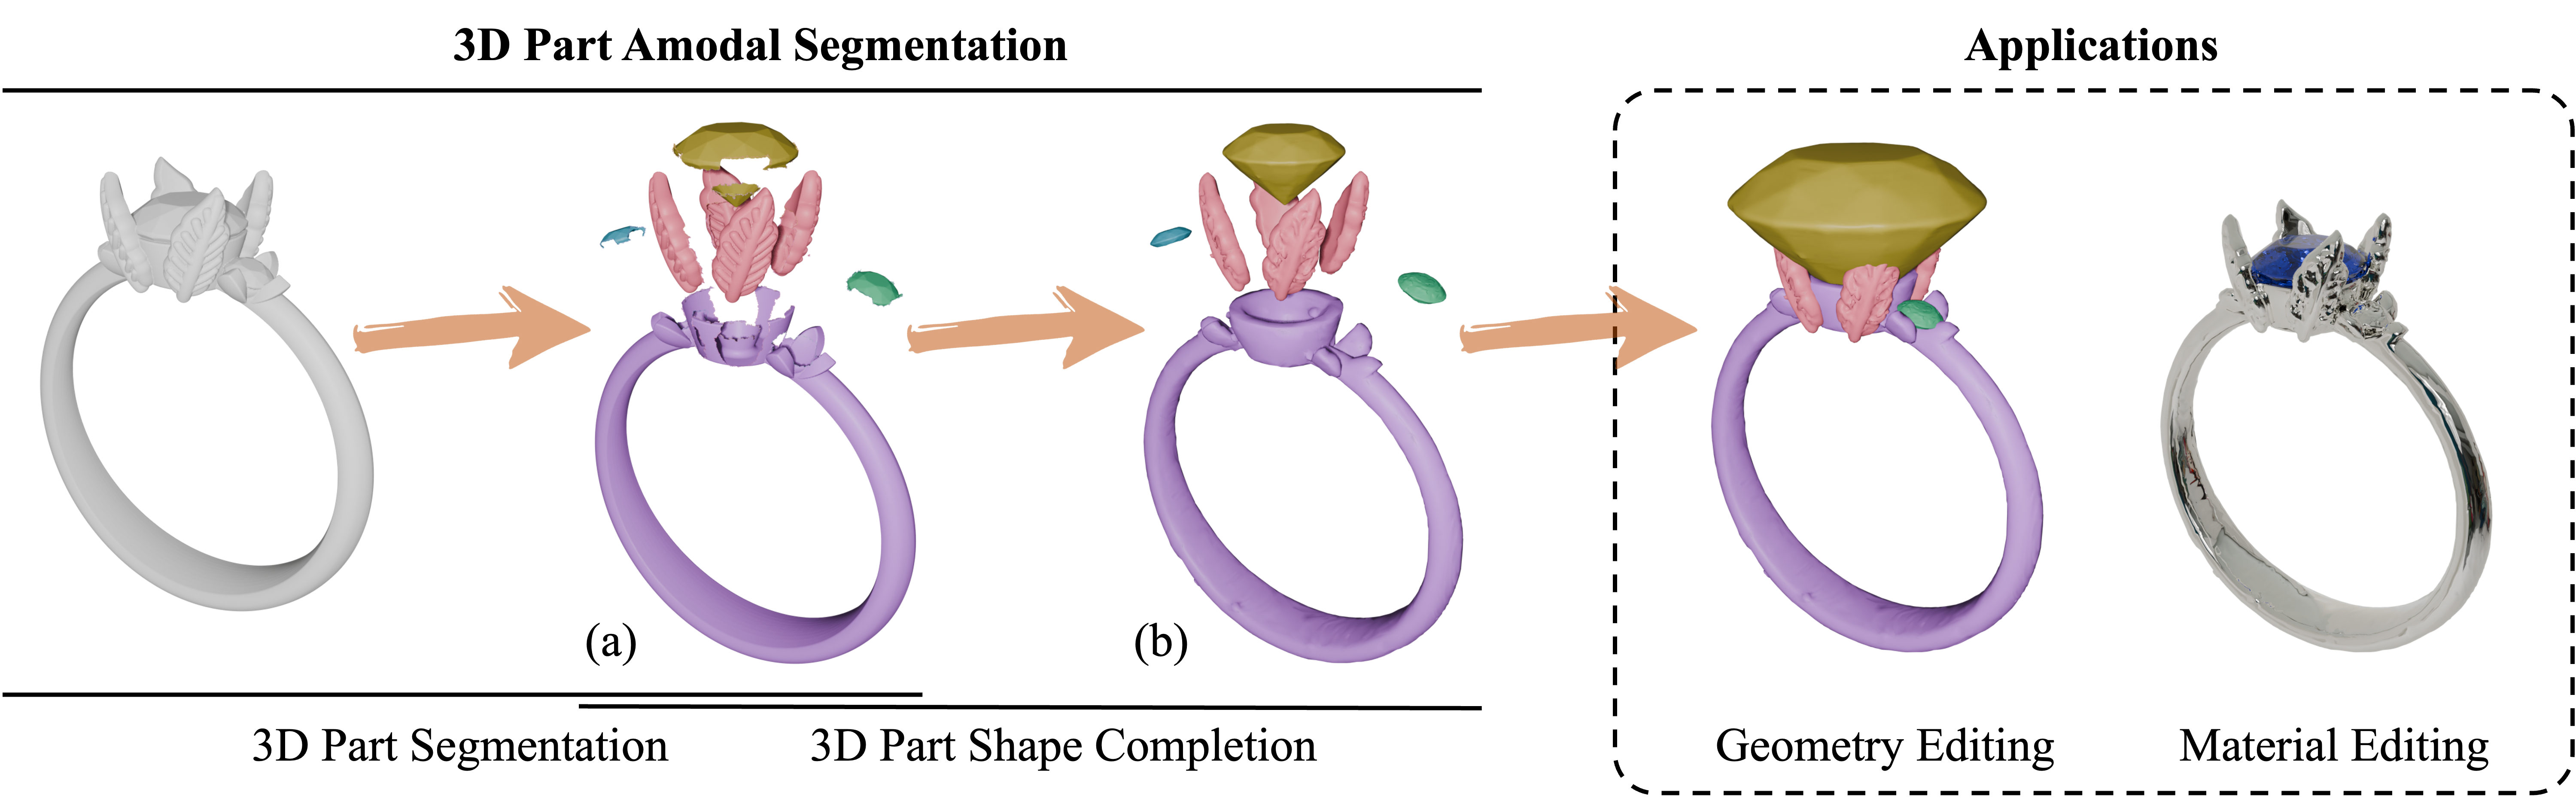
Image to 3DHoloPart can decompose 3D models into complete, semantically meaningful parts, solving editing challenges in 3D content creation
Open-Weights
Image to 3DUniRig uses autoregressive models to generate high-quality skeleton structures and skinning weights for diverse 3D models, greatly simplifying the animation workflow
Open-Weights
MultimodalOmniSVG is a new unified multimodal SVG generation model capable of producing highly complex, editable vector graphics from various inputs including text, images, or character references
Open-Weights
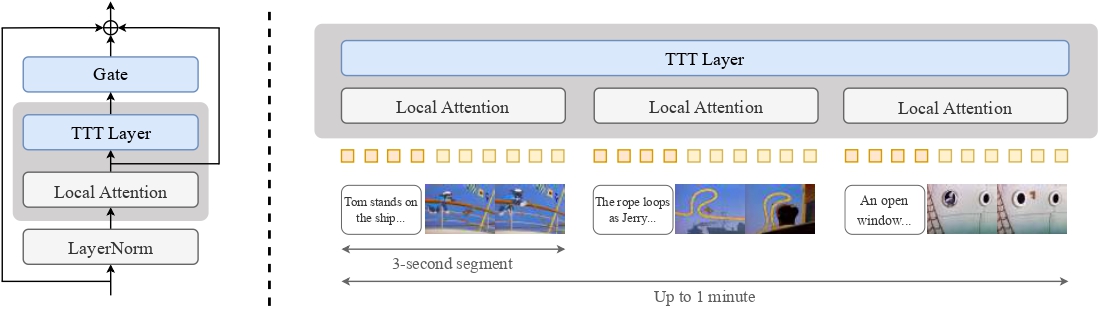
Text to videoResearchers develop TTT-Video model using Test-Time Training technology based on CogVideoX 5B, capable of generating coherent videos up to 63 seconds long
MIT
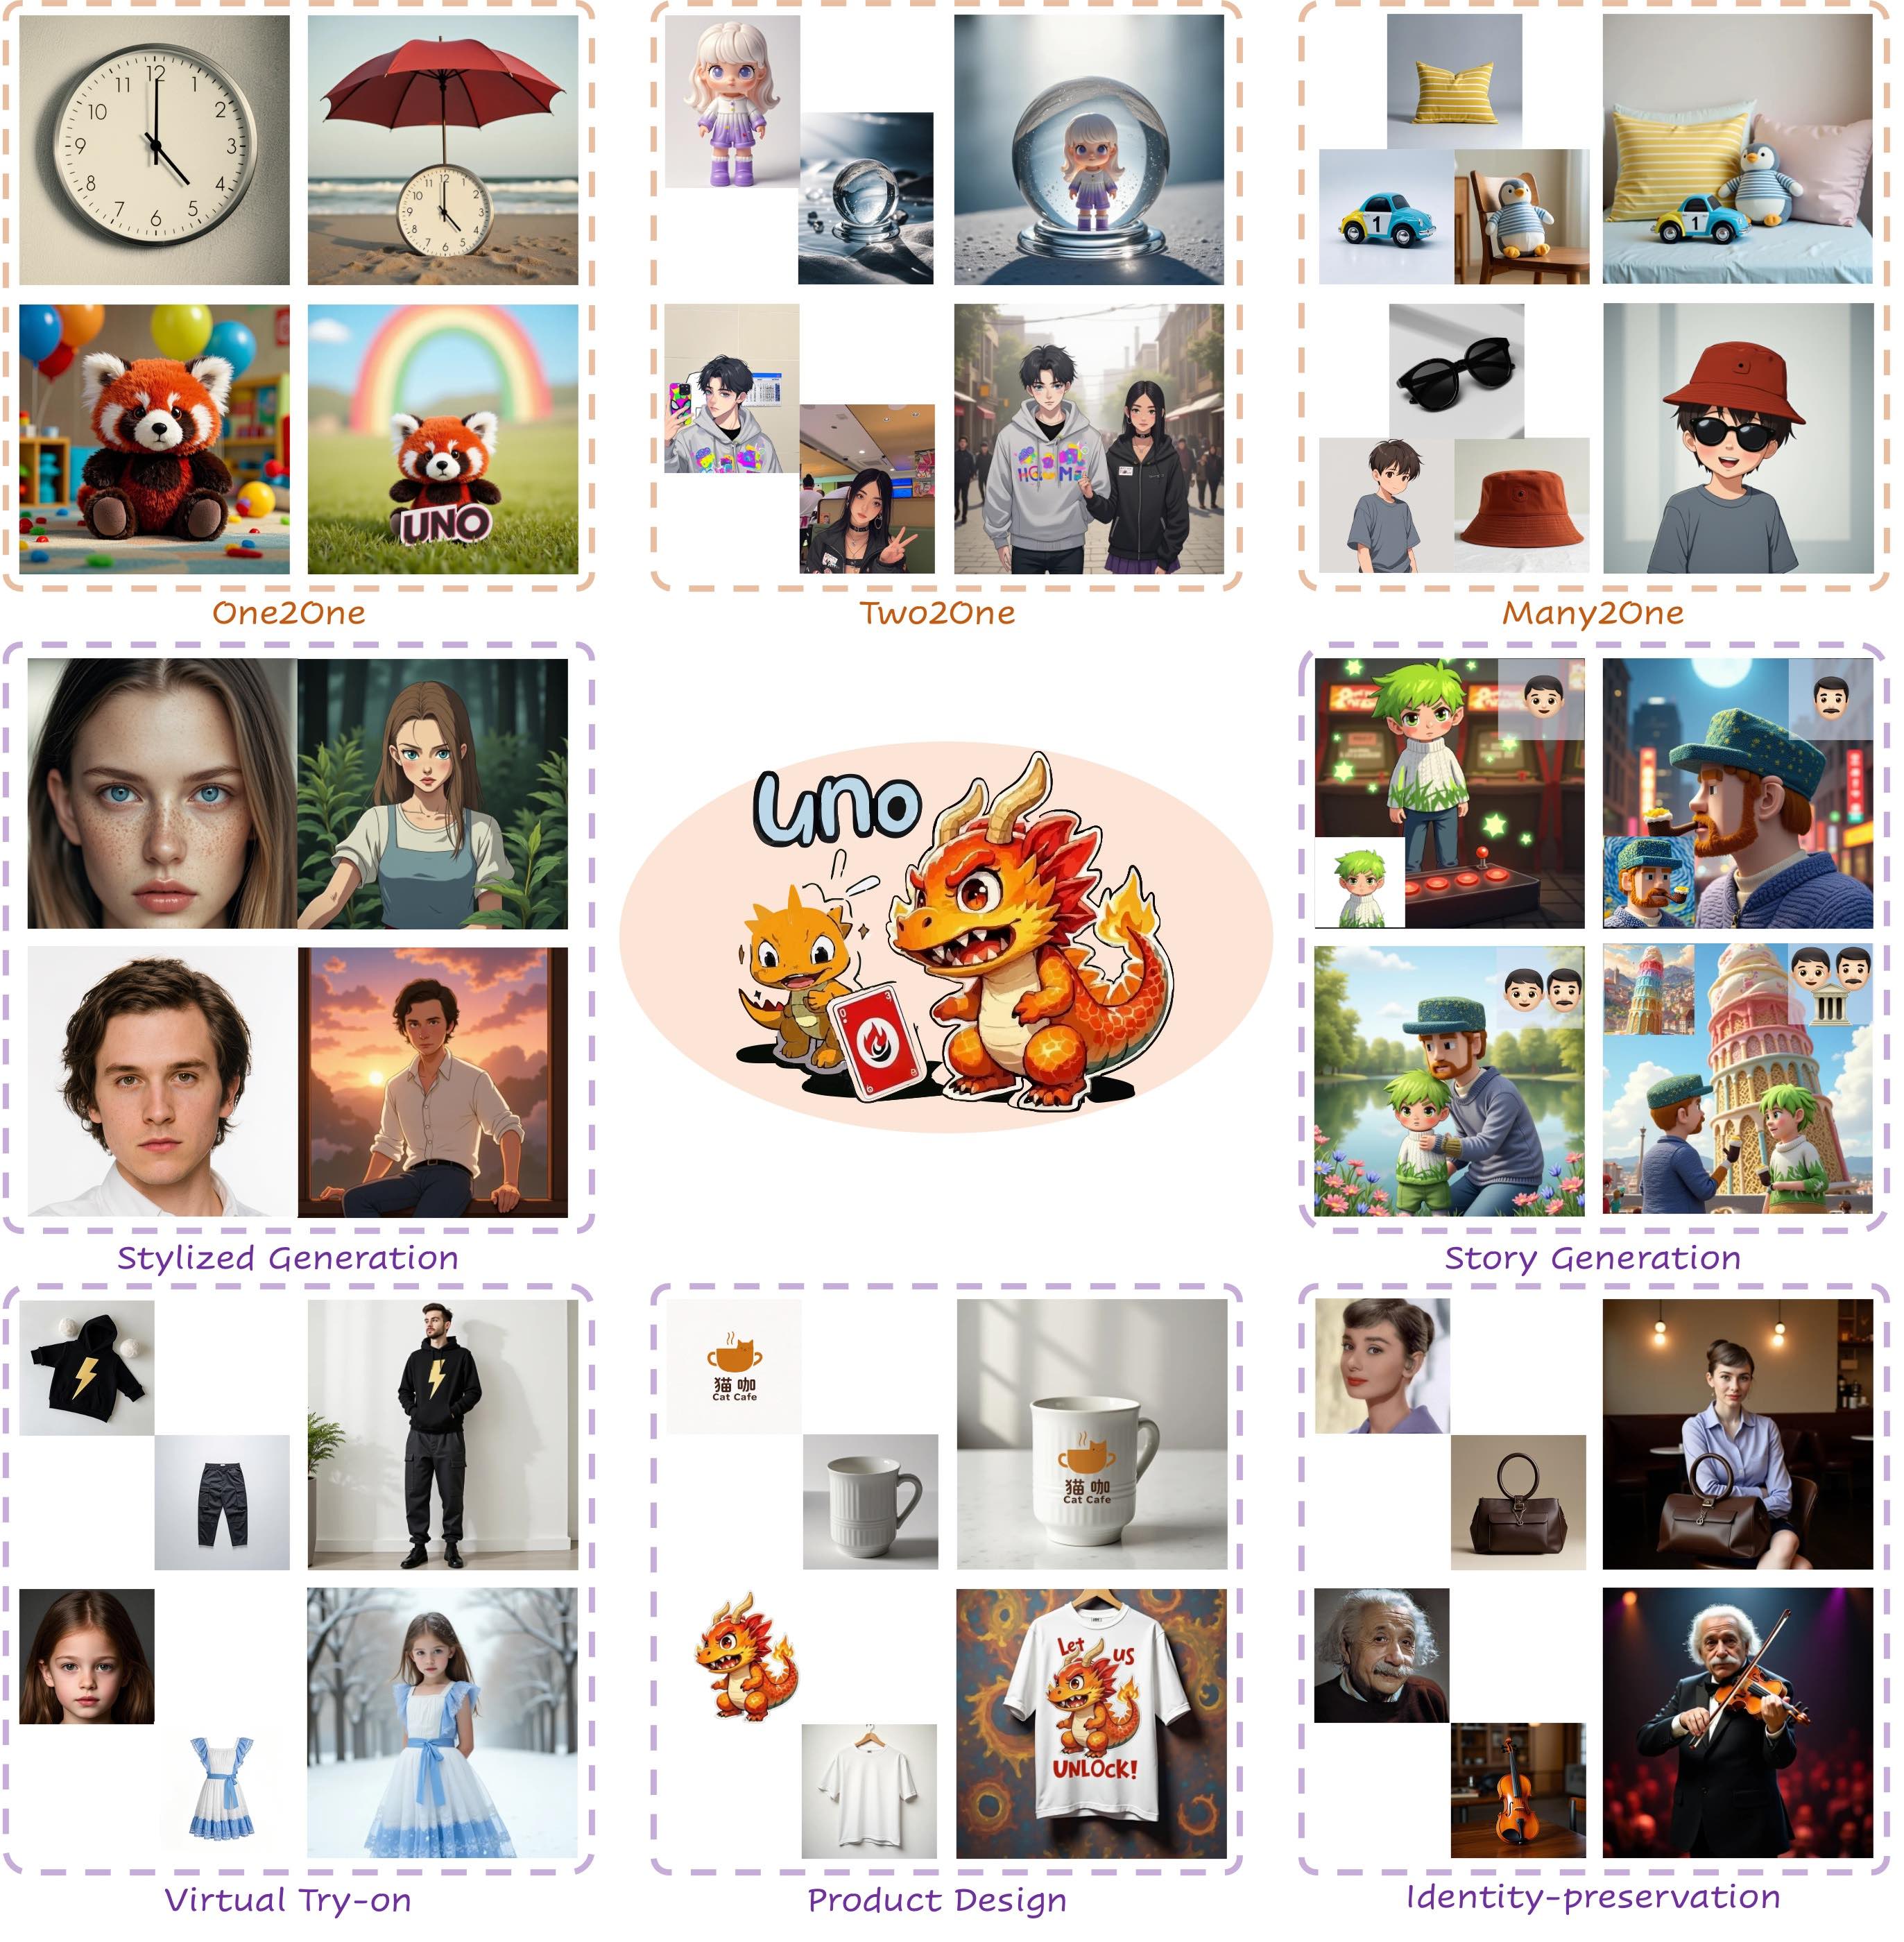
Text to imageByteDance Creative Intelligence team releases UNO model, unlocking greater controllability through in-context generation, achieving high-quality image generation from single to multiple subjects
Open-Weights
Text to imageTiamat AI team releases EasyControl framework, adding conditional control capabilities to DiT models, now supported in ComfyUI via the ComfyUI-easycontrol plugin
Open-Weights
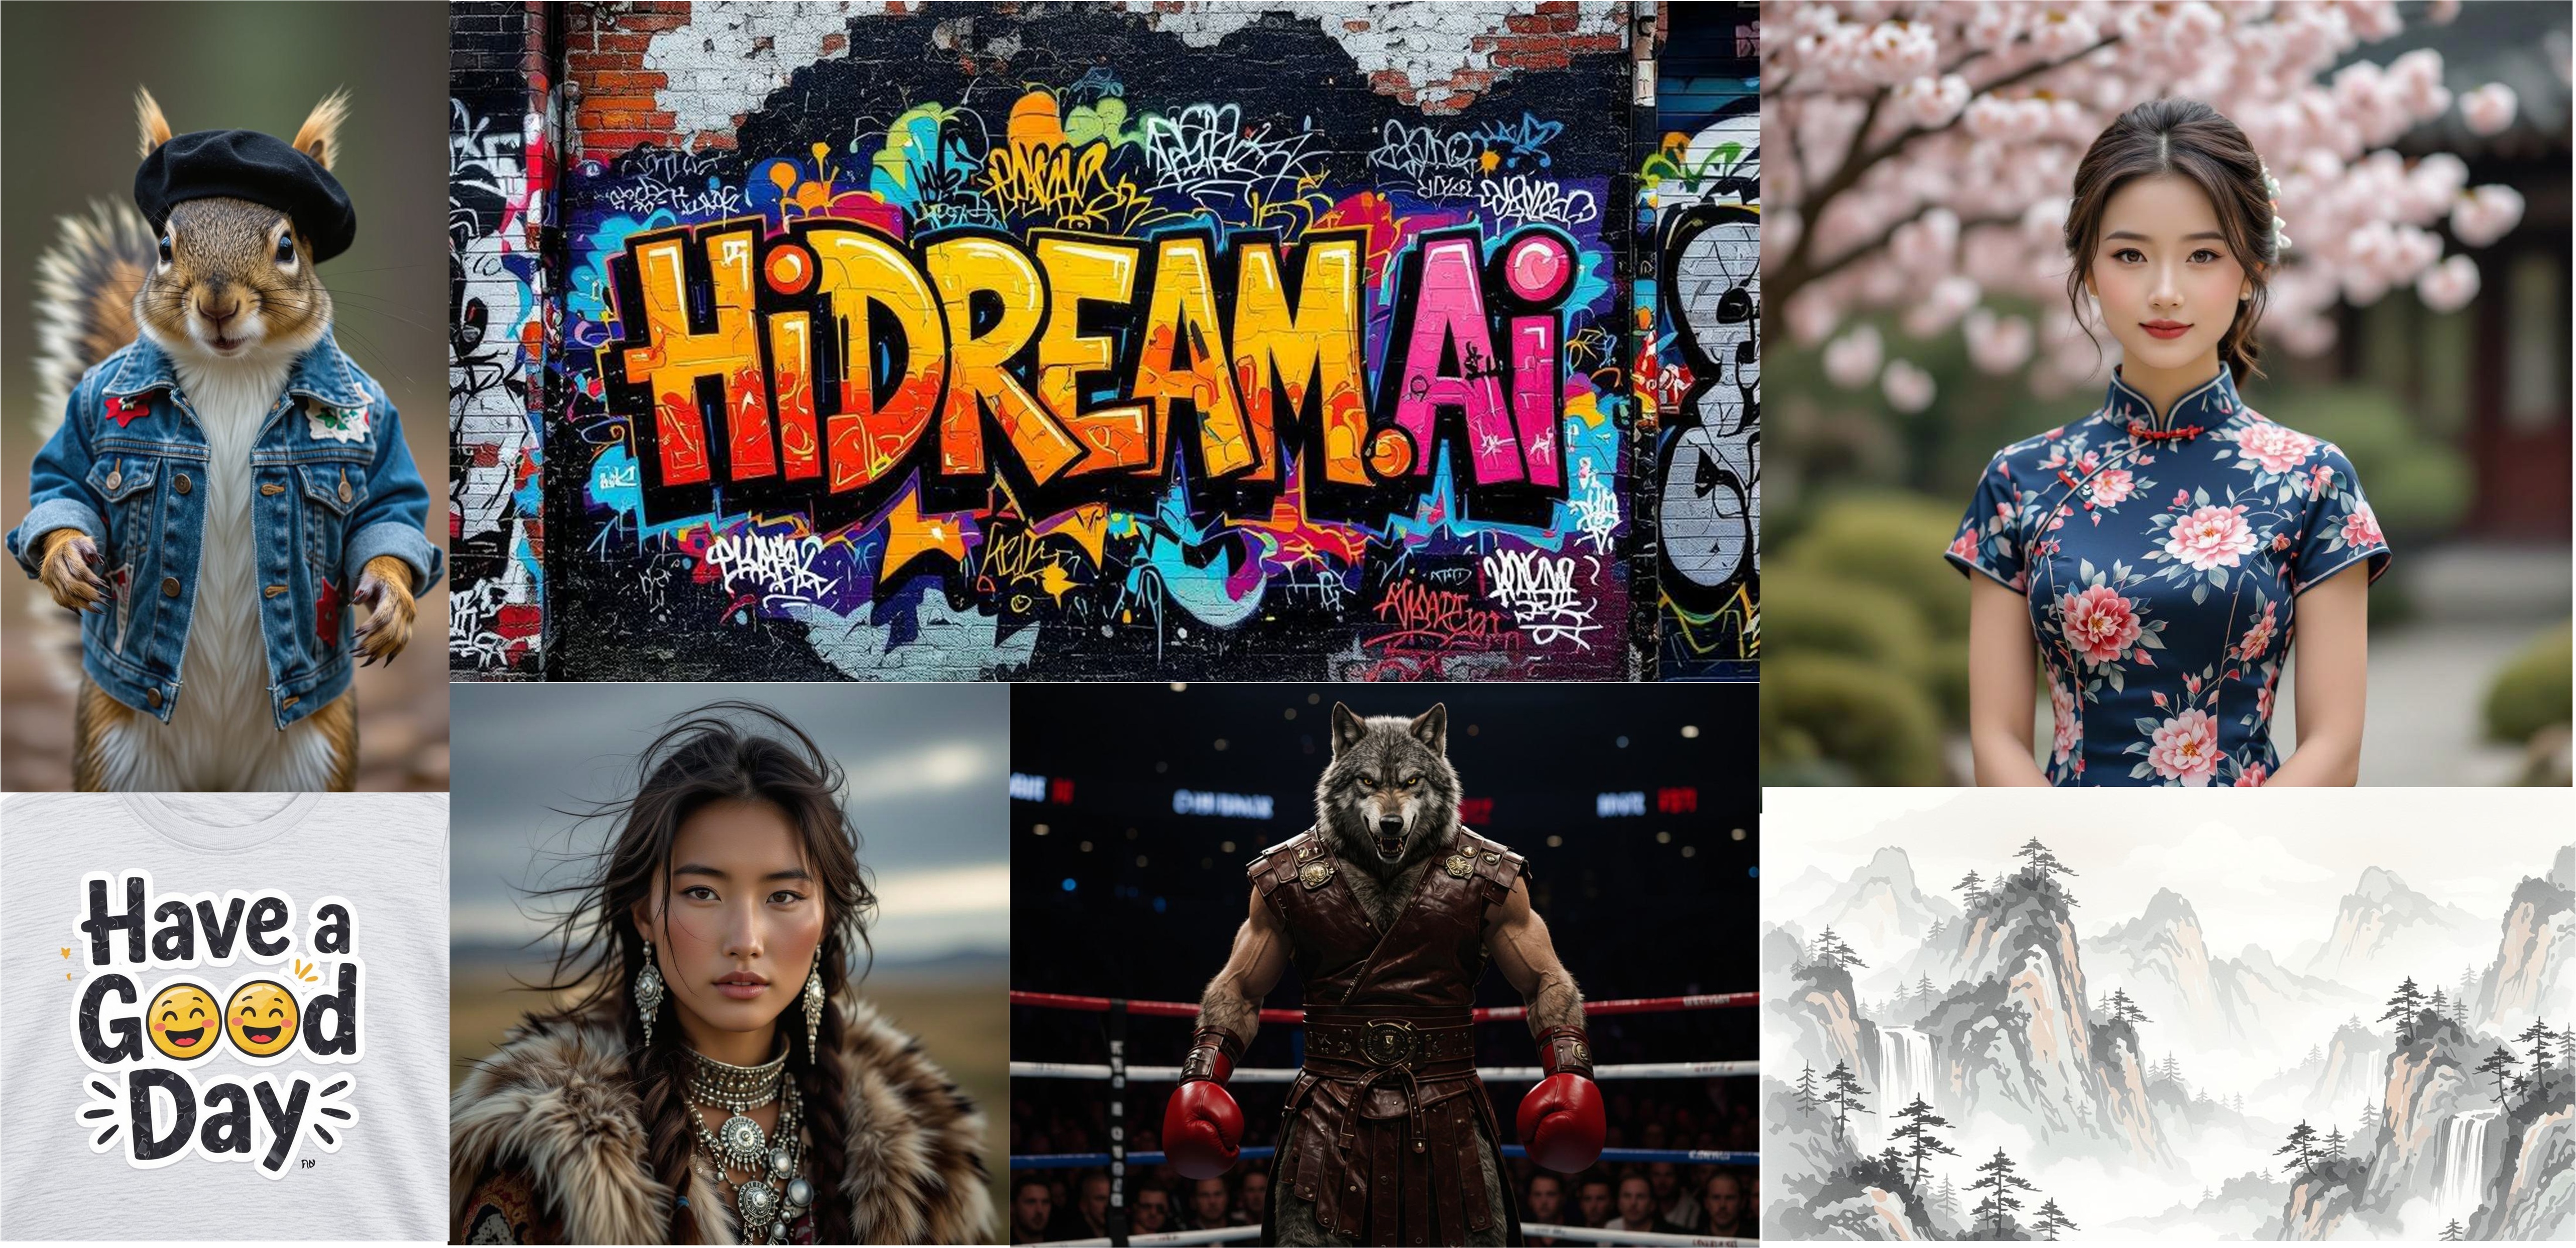
Text to imageHiDream.ai releases HiDream-I1, a new open-source text-to-image model with 17B parameters that outperforms existing open-source models in multiple benchmarks, supporting high-quality image generation in various styles
Open-Weights
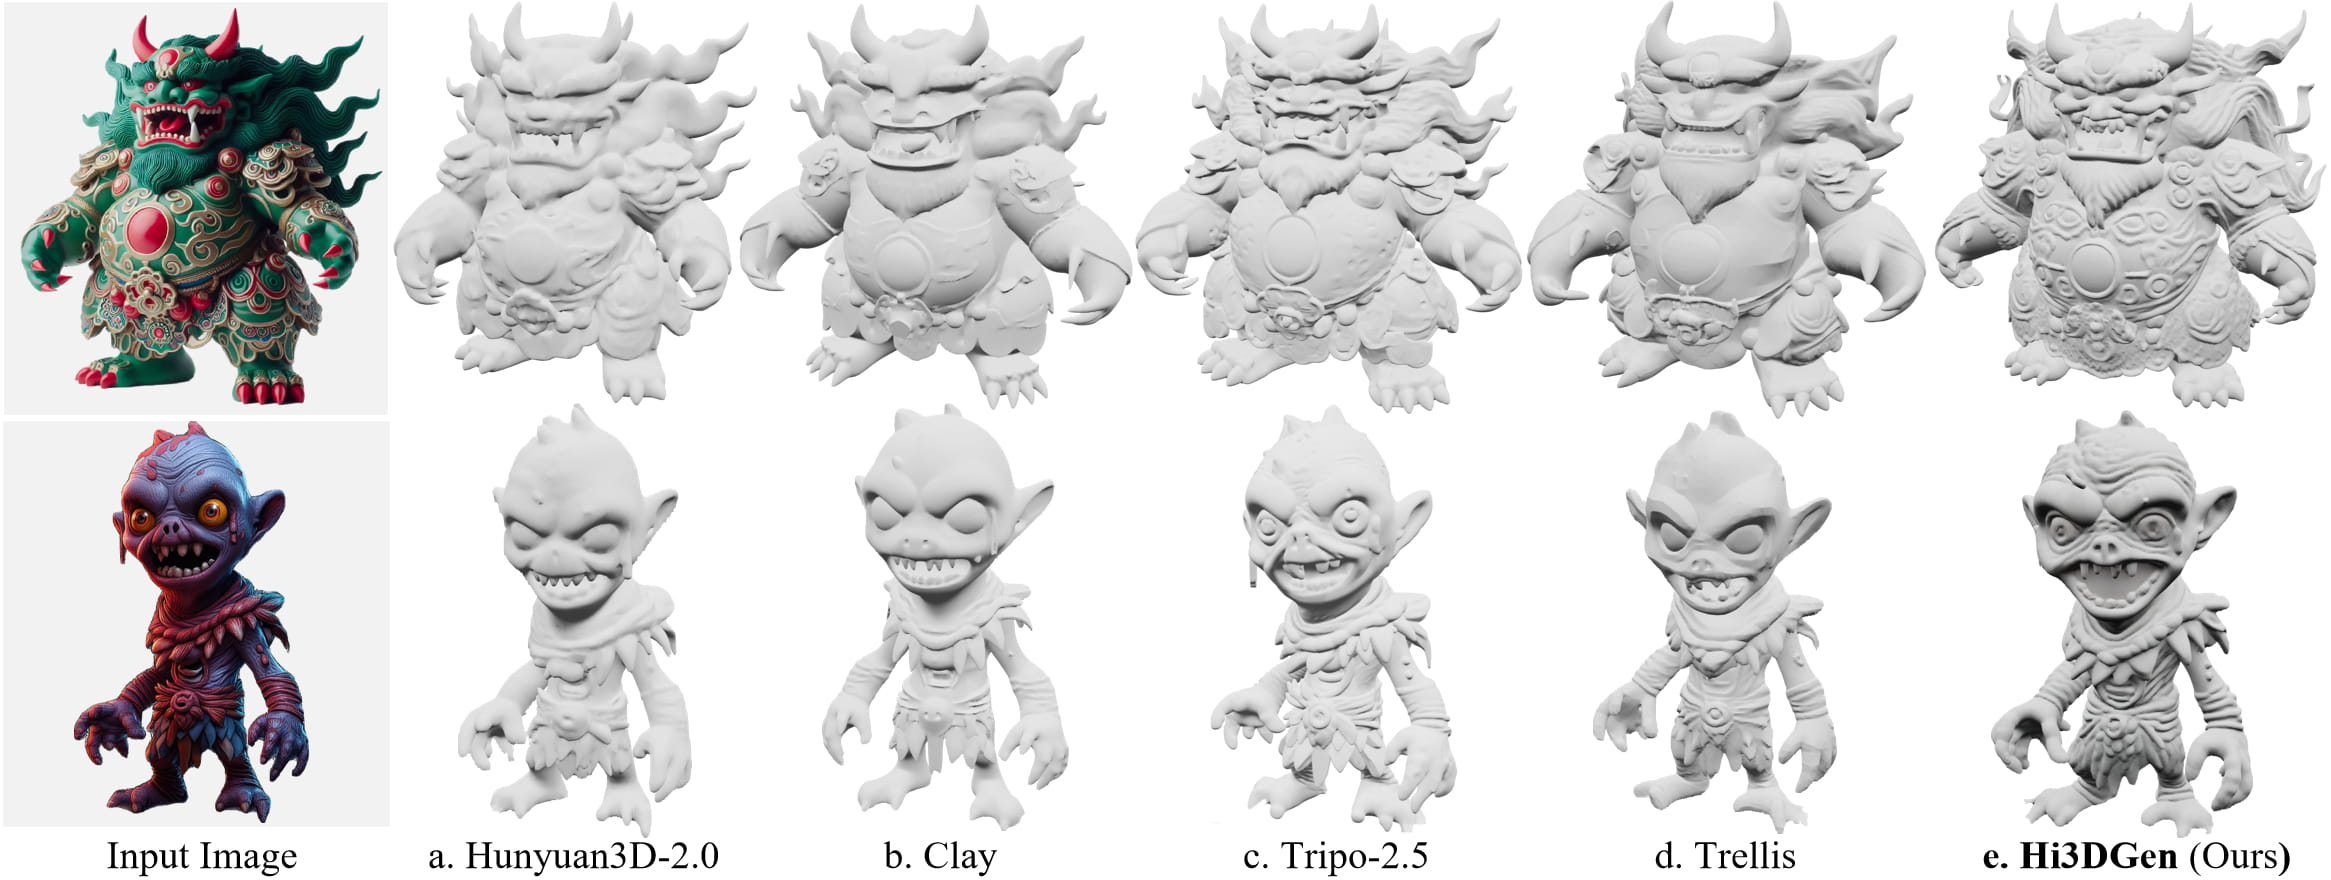
Image to 3DStable-X team introduces Hi3DGen, an innovative framework for generating high-fidelity 3D models from images, addressing the lack of geometric details in existing methods through normal bridging technology
Open-Weights
Image to 3DTripoSF, based on the innovative SparseFlex representation, supports 3D model generation at resolutions up to 1024³, capable of handling open surfaces and complex internal structures, significantly improving 3D asset quality
Open-Weights
Text to videoKunlun Wanwei releases the world's first commercial-grade controllable video generation framework SkyReels-A2, enabling multi-element video generation through dual-branch architecture, bringing new possibilities for e-commerce, film production and more
Open-Weights