Pruna's 6-Step Qwen-Image 2.1 LoRAs Get an Official ComfyUI Pack
PrunaAI's v0.2 adds two 6-step Qwen-Image 2.1 adapters, one of which folds prompt upsampling into the LoRA, plus an official ComfyUI export with six workflows.
Samples from the official model card at 1024.
When PrunaAI first released these adapters in September, they shipped as diffusers/PEFT files with the alpha stored in safetensors metadata, which ComfyUI's LoRA loader does not read, and the model card said there was no official ComfyUI package. Both of those statements now change: the adapters come as native ComfyUI files running at the intended scale, and the workflows are the author's own rather than a community conversion.
Two 6-step adapters
v0.2 keeps the whole v0.1 set (5 steps and 8 steps) and adds a pair of 6-step students trained differently:
| Adapter | Steps | What it is for |
|---|---|---|
p_q_image_2.1_6_steps_v0.2.safetensors | 6 | Advanced distillation, a drop-in for the base model. Best at editing where the input has to be preserved. |
p_q_image_2.1_6_steps_upsampled_v0.2.safetensors | 6 | Distills the recommended prompt upsampler into the LoRA, for better quality from a short prompt with no separate upsampling call. |
PrunaAI says the plain 6-step adapter improves on the v0.1 pair in almost all categories. The important detail is that the two schedules are not interchangeable: the v0.2 adapters were trained on their own sigma schedule and the model card says not to reuse the v0.1 numbers.
Prompt upsampling folded into the LoRA
Qwen-Image 2.1's official recipe runs a prompt enhancer before generation. The 6-steps-upsampled adapter absorbs that step, so a short prompt goes straight into sampling and the end-to-end time drops by the cost of a separate enhancer call.
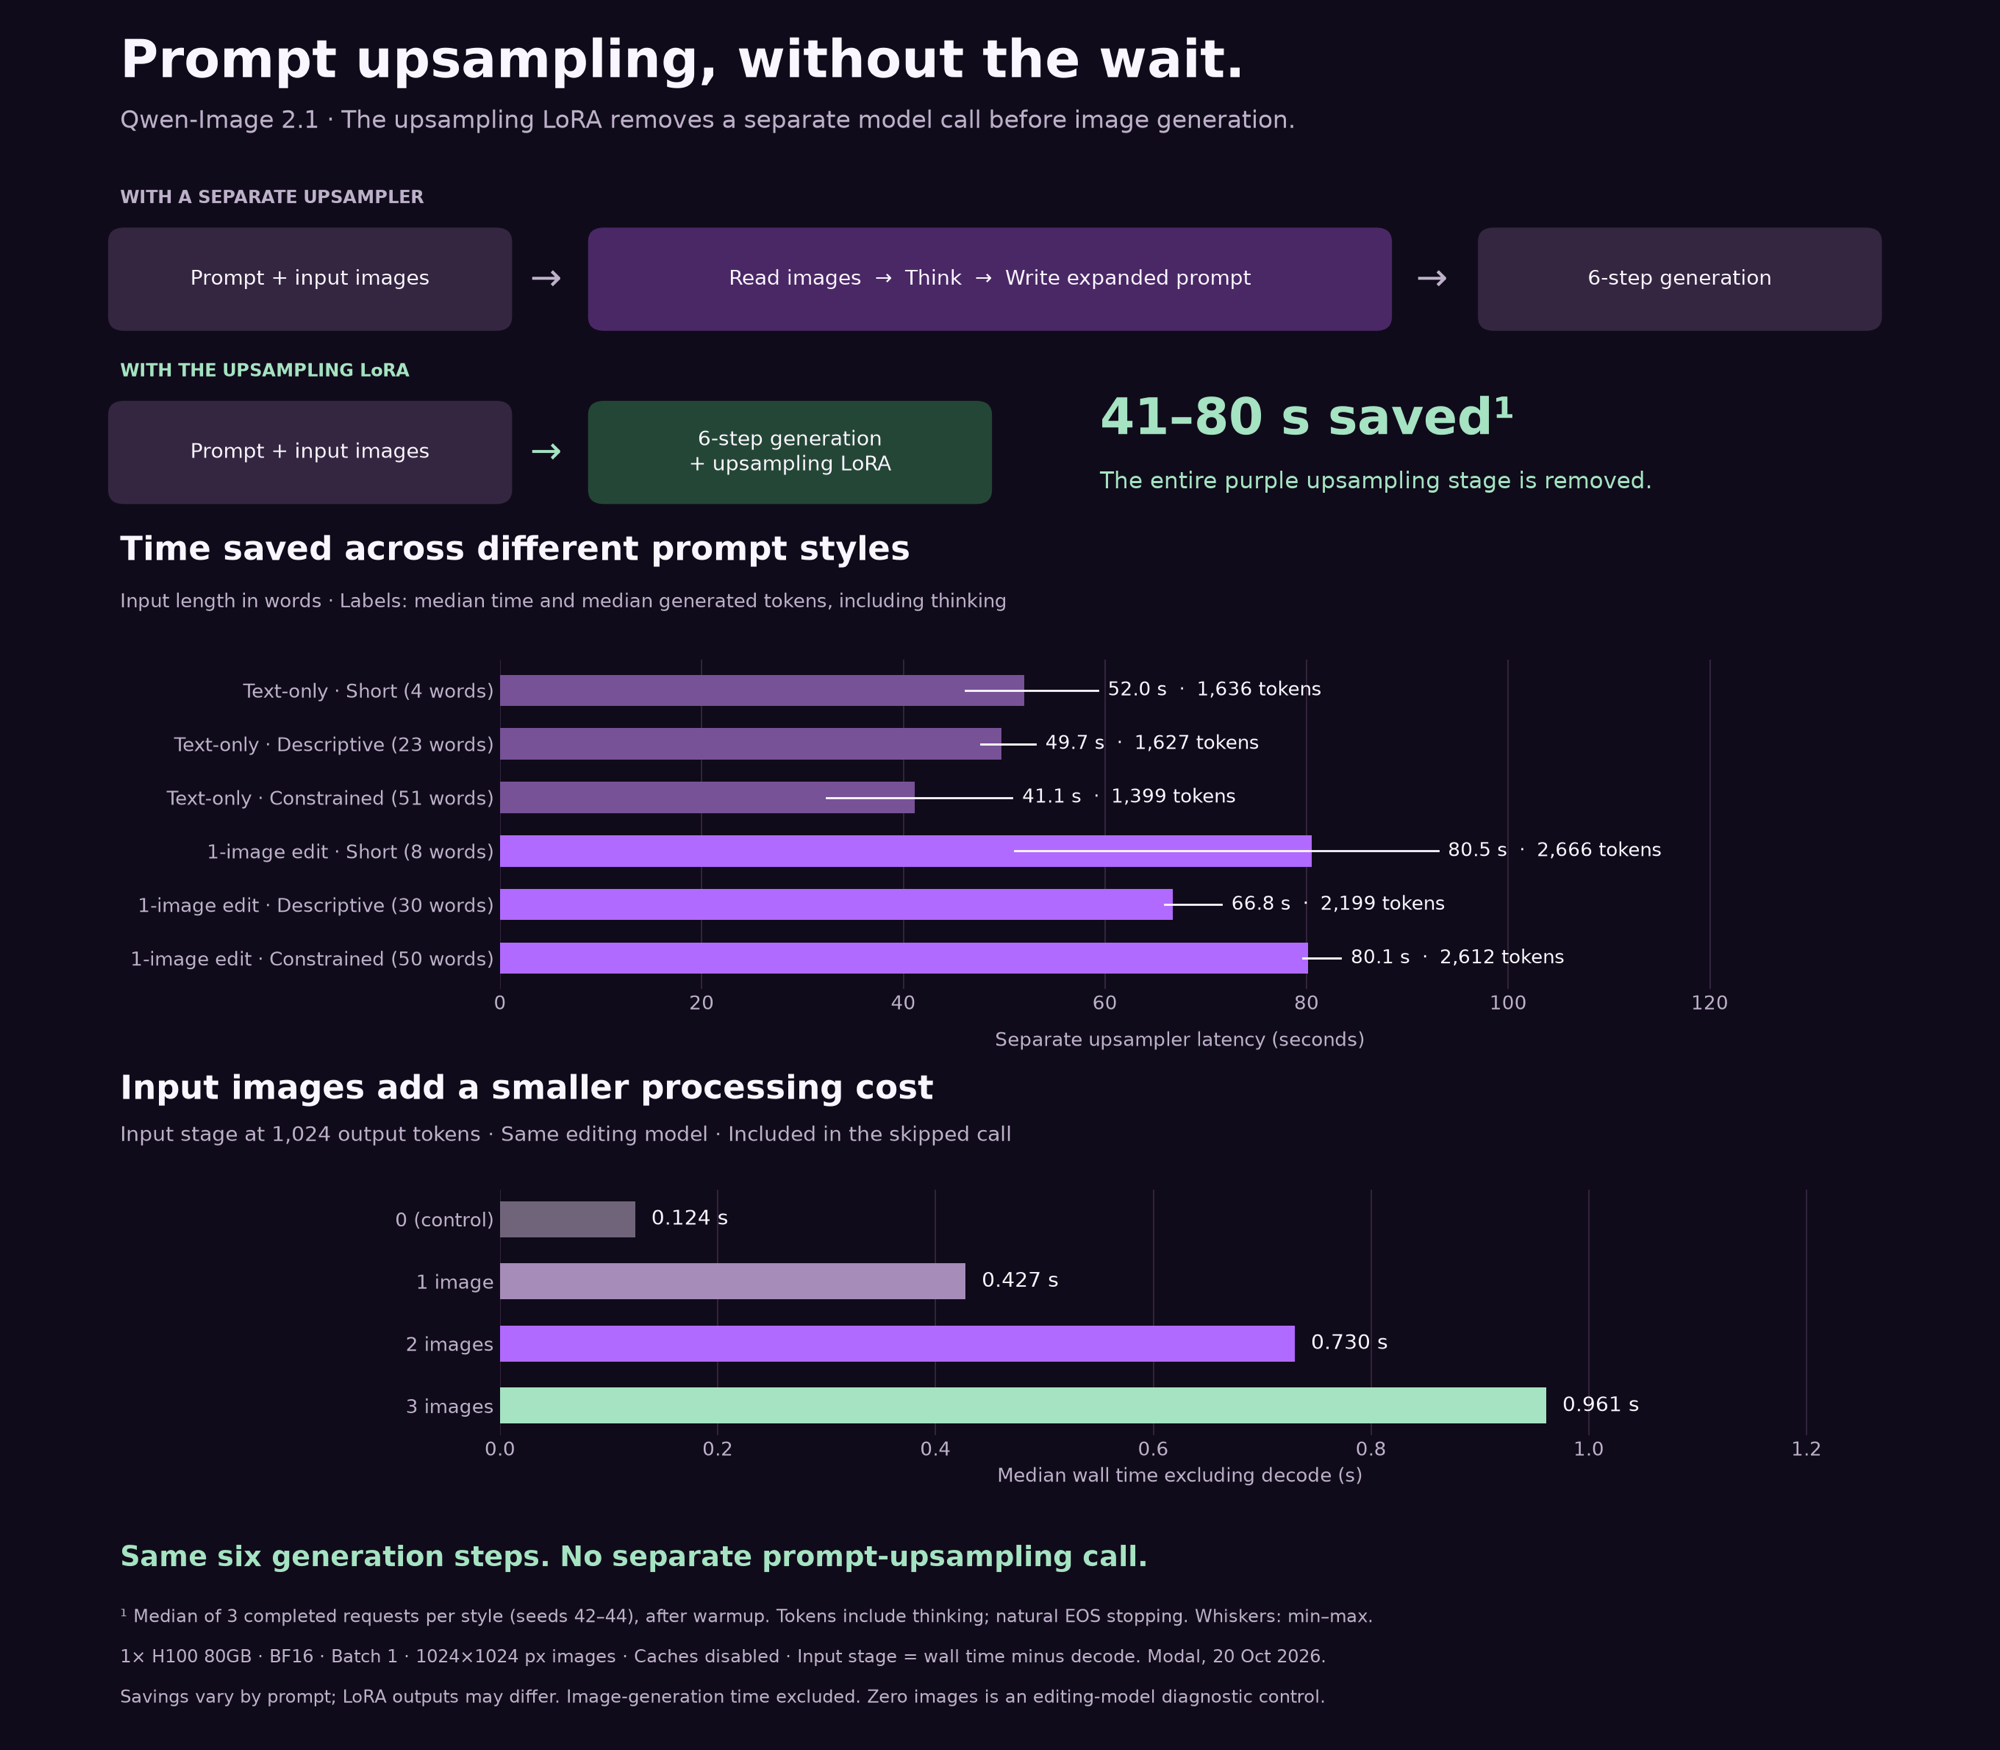
The card's separate measurement of the upsampling step that the v0.2 adapter is meant to replace.
The card is careful about the claim. It calls this the first distillation that removes the need for a separate prompt upsampling pass, and then states that the adapter may not reproduce exactly what the real upsampler would do, with more work promised. Pruna also measured the upsampler on its own, with the official Qwen-Image-2.1-PE-T2I and PE-I2I enhancers, and warns that adding the two medians is not an end-to-end number.
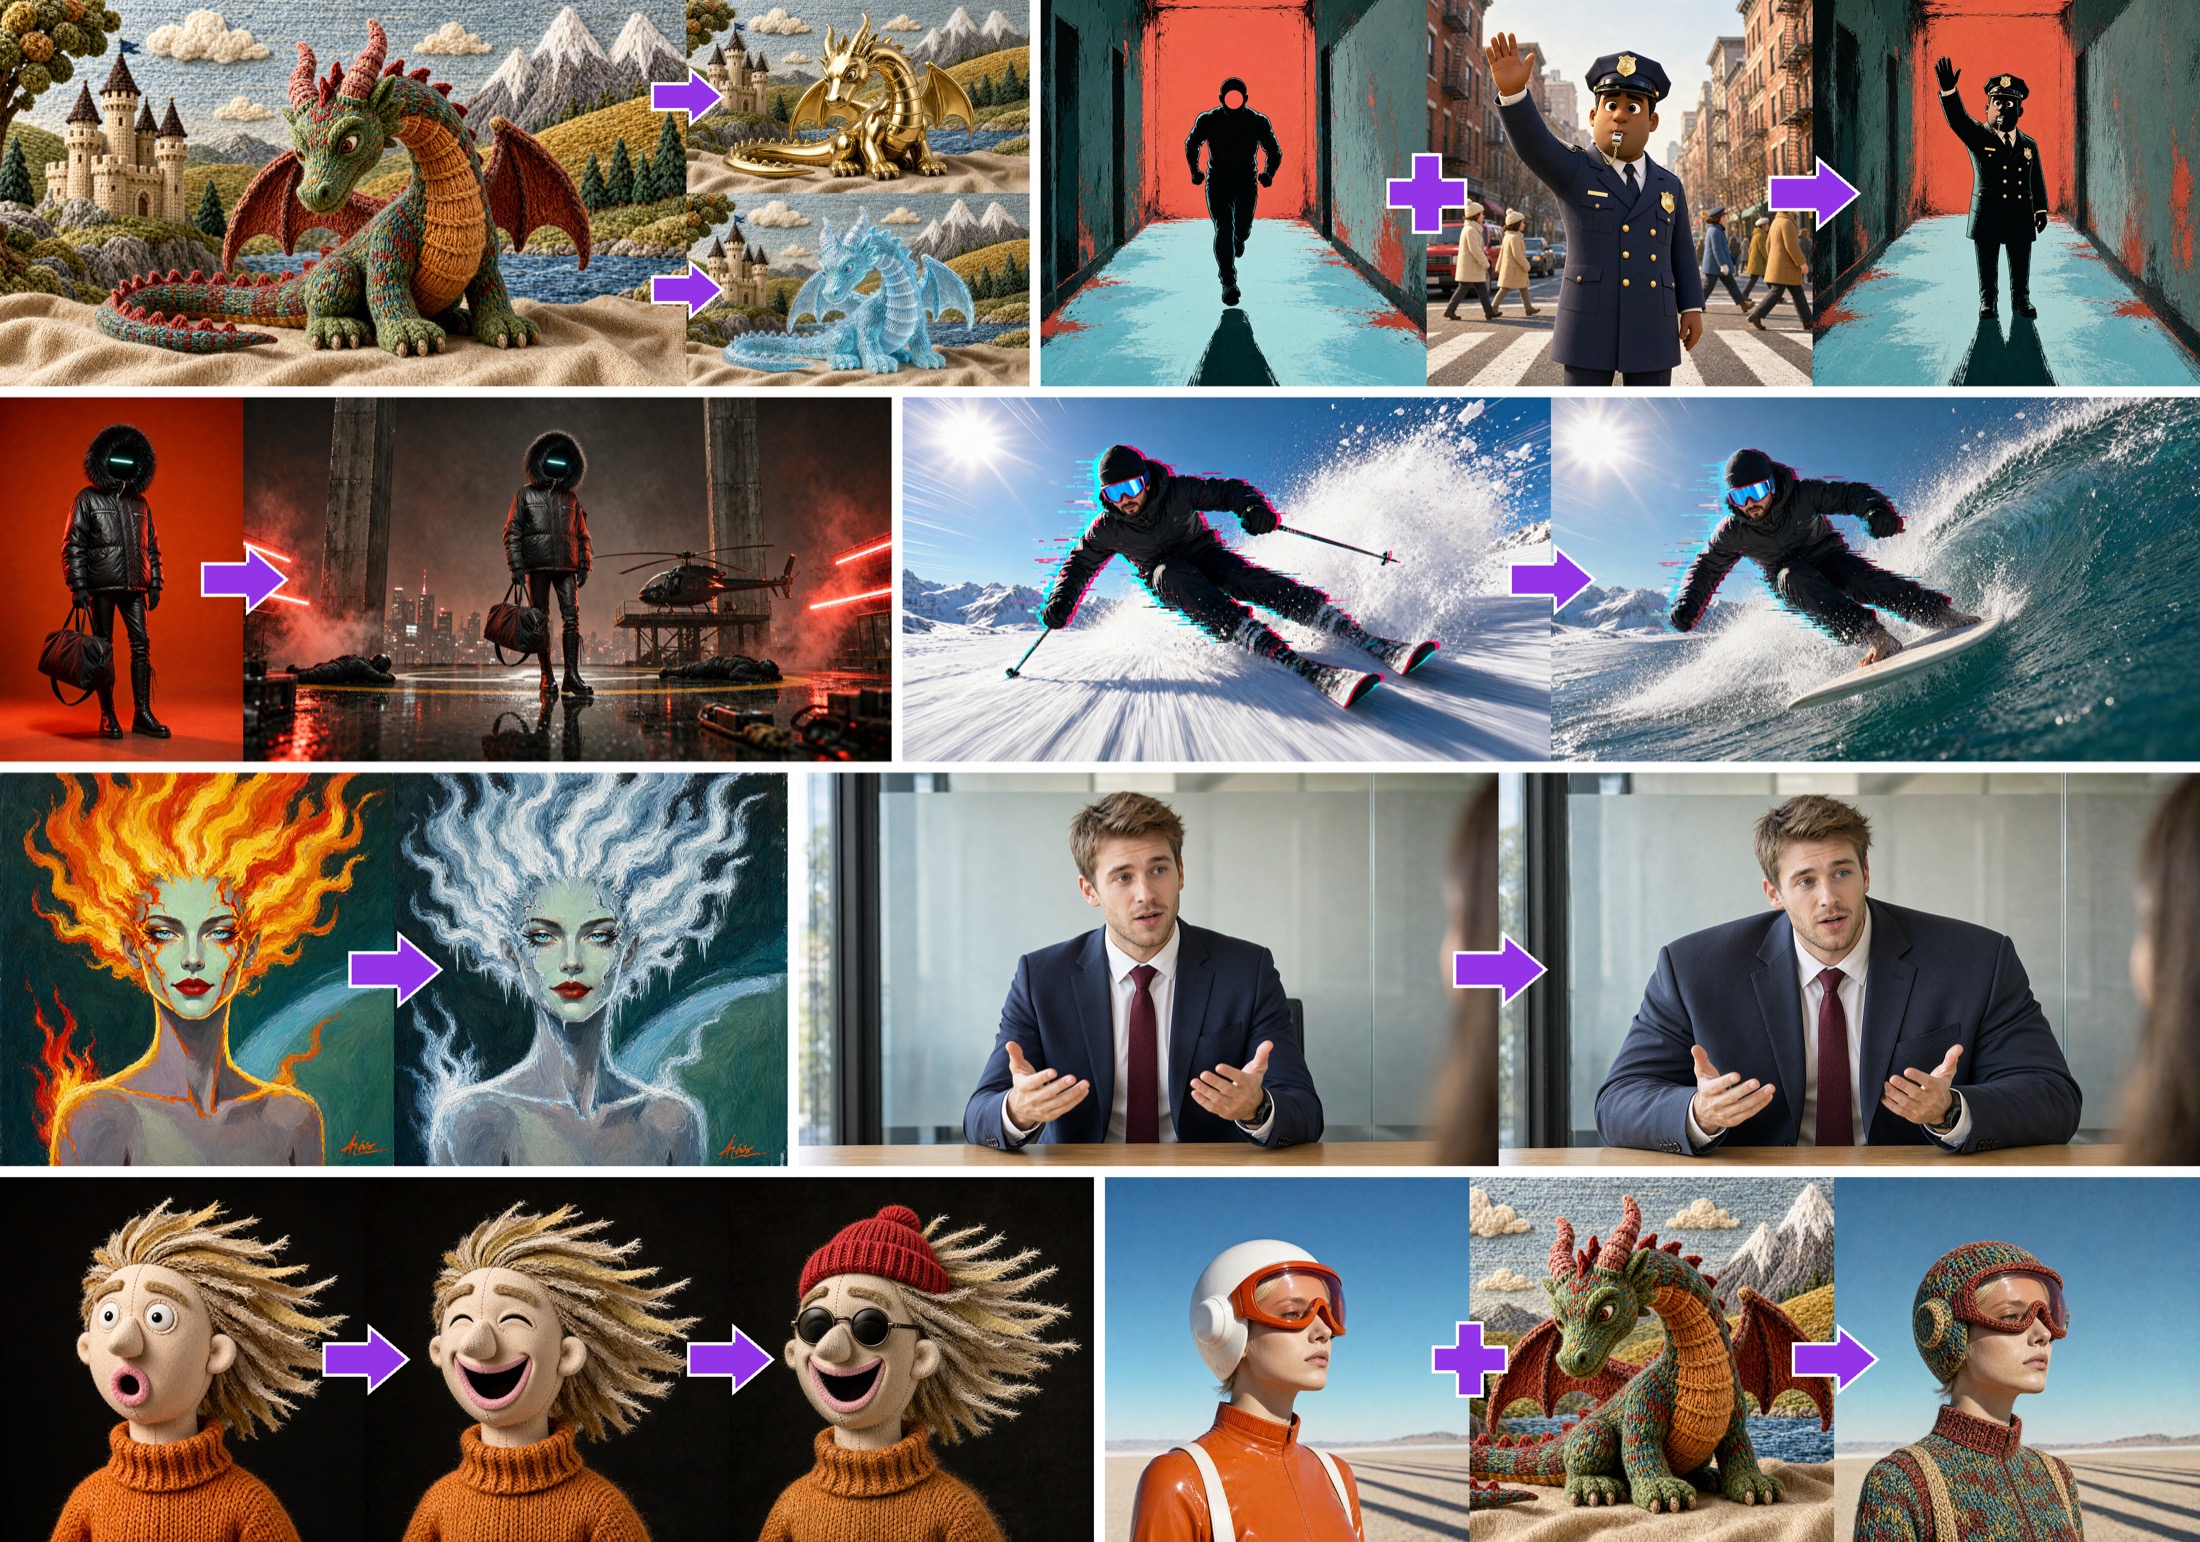
Editing results from the official card, the task the plain 6-step adapter is tuned for.
The official ComfyUI export
The ComfyUI repository carries four bf16 adapters, one per variant, and six workflows: text-to-image and image editing for the v0.2 6-step, the v0.1 8-step and the v0.1 5-step. Each workflow loads one adapter at strength 1.0 through the native LoraLoaderModelOnly node, samples with euler at CFG 1, and uses a ManualSigmas schedule. No custom nodes are needed.
The layout is the one ComfyUI users already have for Qwen-Image 2.1, with the base checkpoint from Comfy-Org/Qwen-Image-2.1:
ComfyUI/
└── models/
    ├── diffusion_models/
    │   └── qwen_image_2.1_int8_convrot.safetensors
    ├── loras/
    │   └── p_q_image_2.1_6_steps_v0.2_comfyui_bf16.safetensors
    ├── text_encoders/
    │   └── qwen3vl_8b_int8_convrot.safetensors
    └── vae/
        └── qwen_image_2.1_vae_bf16.safetensors
The card specifies the base checkpoint, not the Turbo one, and one schedule per adapter:
| Adapter | ManualSigmas |
|---|---|
| v0.2, 6 steps | 1.0, 0.961054, 0.918949, 0.769302, 0.545554, 0.222292, 0 |
| v0.1, 8 steps | 1.0, 0.933333, 0.857143, 0.769231, 0.666667, 0.545455, 0.4, 0.222222, 0 |
| v0.1, 5 steps | 1.0, 0.94, 0.857143, 0.666667, 0.4, 0 |
The same schedule covers both 6-step variants: switching lora_name in the v0.2 workflows from 6-steps to 6-steps-upsampled is the whole difference between them in ComfyUI.
What has not changed
- Training coverage is still 1K. The adapters were trained at 1024 with up to three reference images for editing. Pruna recommends starting at 1024x1024 and treats 2K and more references as outside coverage, where quality may vary.
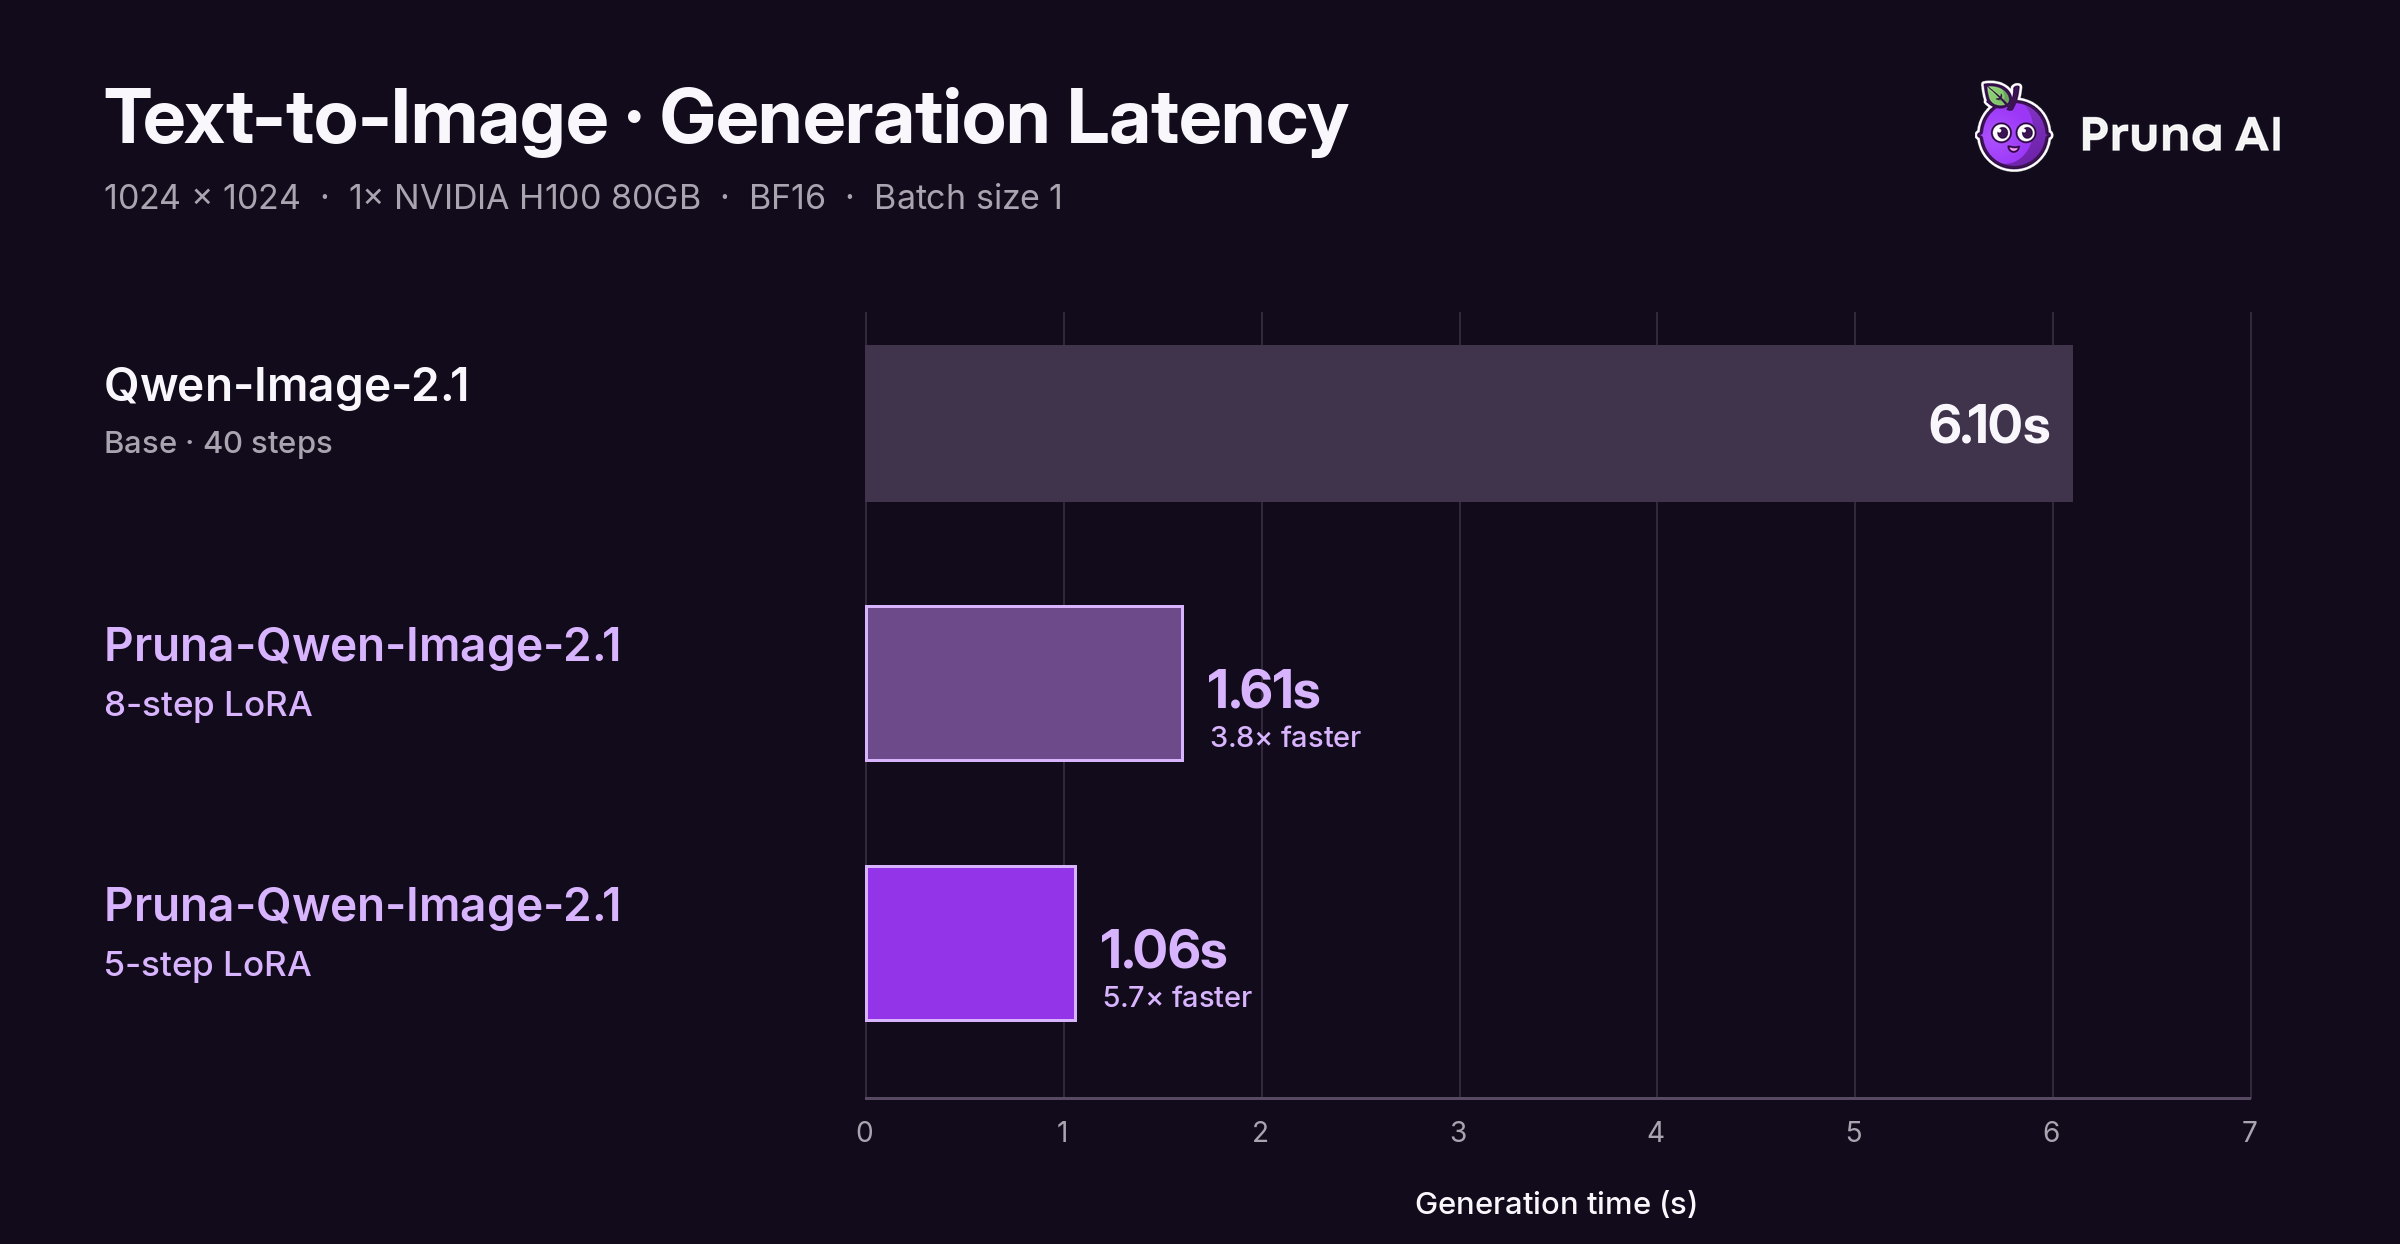
- Up to 6.3x faster remains the headline number, with no CFG and no negative prompt. The v0.2 charts are new measurements and the card notes they were not matched to the v0.1 charts.
- Rank 64 across 232 linear targets, including
proj_out, trained at alpha 128 with the 2x scale folded into the exported B matrices. That is why the strength has to stay at 1.0. - v0.1 is still there. The 5-step and 8-step adapters are unchanged, so an existing workflow using the community conversion can move to the official files without changing its schedule.
Comments
Sign in with GitHub to join the discussion.