pi-H3 Puts MiniMax H3 Video in 2 to 4 Steps in ComfyUI
The pi-H3 adapters cut MiniMax H3 video with audio down to 2 or 4 steps in ComfyUI, plus an experimental path that skips the VAE decoder. Weights are out.
Clay baker, 2 steps at 1344x768, 5 seconds with stereo audio, from the project's own gallery.
What it gives you
| 1344x768, 24 fps, with audio | pi-H3 2-step | pi-H3 4-step | Sol-H3 4-step |
|---|---|---|---|
| 5 s video | 3.81 s | 7.30 s | 9.48 s |
| 10 s video | 9.16 s | 17.56 s | 24.31 s |
| 15 s video | 18.58 s | 36.41 s | 44.96 s |
End-to-end on one B200, from text encoding to decoded video and audio, taking the authors' figures against Sol-H3's published numbers.
Two adapter families ship: plain 2/4-step versions that still decode through the H3 VAE, and DWD versions that predict pixels in the last denoising step and skip the VAE decoder entirely. The DWD ones come in INT8 ConvRot for ComfyUI. Version 1.0 swapped the DWD refiner from a convolutional net to a lighter transformer with windowed attention, which the authors say gives smoother fine-detail motion and better 2-step coherence.
Run it in ComfyUI
- Install ComfyUI-piFlow through ComfyUI Manager, or clone it into
custom_nodes. It needs ComfyUI 0.45.0 or newer, and wants any third-party pi-H3 or pi-Flow extension removed first. - Load
pi-H3-DWD.jsonorpi-H3.jsonfrom the repo'sworkflowsfolder. The pi-H3 Adapter node switches between 2 and 4 steps and sets the matching pi-Flow scheduler values. - Drop
pi_h3_2step_dwd_adapter_int8_convrot.safetensors(or the 4-step file) intomodels/loras/, and pair it withminimax_h3_fl2va_pruned_int8_convrot.safetensorsfrom Comfy-Org/MiniMax-H3. The DWD workflow needs the video VAE only for the keyframes, and the audio VAE as usual.
| RTX 3090, DWD 2-step, INT8 | 5 s | 10 s | 15 s |
|---|---|---|---|
| 864x480 | 15.5 s | 37.3 s | 69.2 s |
| 1344x768 | 38.5 s | 97.6 s | 186.1 s |
Only the FL2VA trunk is supported: text, first frame, last frame, or both. There is no Ref2VA adapter, so reference-image conditioning is not on the table.
What testers report
- Kijai converted both adapters to standard H3 LoRA keys for ComfyUI and calls this "the best 2 step one so far" among the recent distills. He is cooler on DWD: with the INT8 Sol VAE, skipping the decoder saved under a second on a 5-second 768p clip, and the DWD output looked worse than VAE-decoded frames.
- JohnDopamine ran VAE against DWD on the same prompt and noise. DWD held up better at 2 steps, VAE was better from 4 steps up, and his conclusion was that the plain adapter at 2 steps is enough for general use.
- boop reported the 2-step adapter looking fine with the VAE, with audio better than expected, though still untested on fast motion.
- Stacking other H3 LoRAs on the DWD variant can backfire: it also trains blocks 46 to 49 through the pixel head, so adapters trained without it may fight it (Kijai).
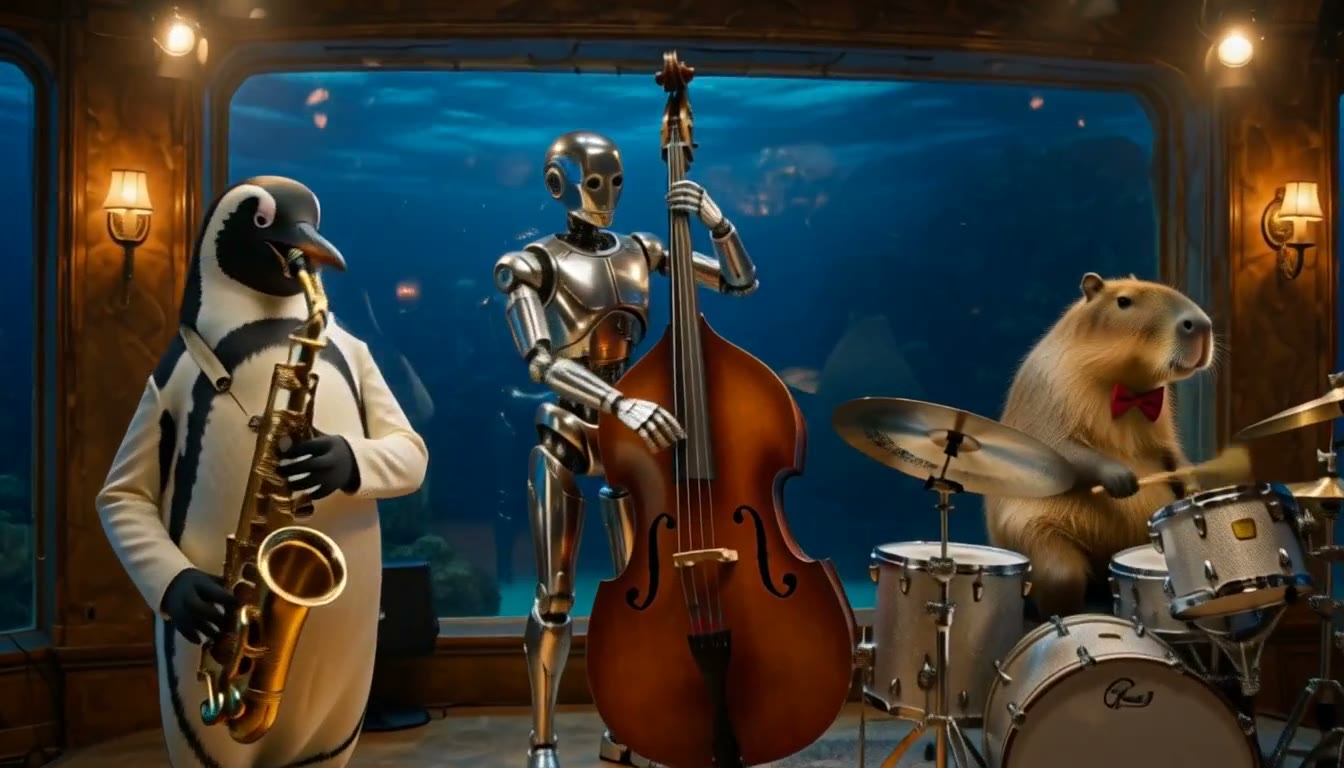
A frame from a 14-second, 2-step render without the VAE decoder.
Underwater jazz club, 2 steps, no VAE decoder, 1344x768, 14 seconds.
Get it
- Weights and adapters: Lakonik/pi-H3
- Project page with the speed numbers and galleries: hanshengchen.com/blog/pi-h3
- ComfyUI workflows, node list and file placement: ComfyUI-piFlow docs
- Try it without installing: pi-H3 Space
- Ready-made ComfyUI LoRA conversions: Kijai/MiniMax-H3_comfy
Comments
Sign in with GitHub to join the discussion.