H3-Tiny: MiniMax H3 Pruned to 14B for Native ComfyUI
H3-Tiny cuts MiniMax H3 from 33B to 17B without training and to 14B with distillation, and ships single-file checkpoints that load in stock H3 nodes.
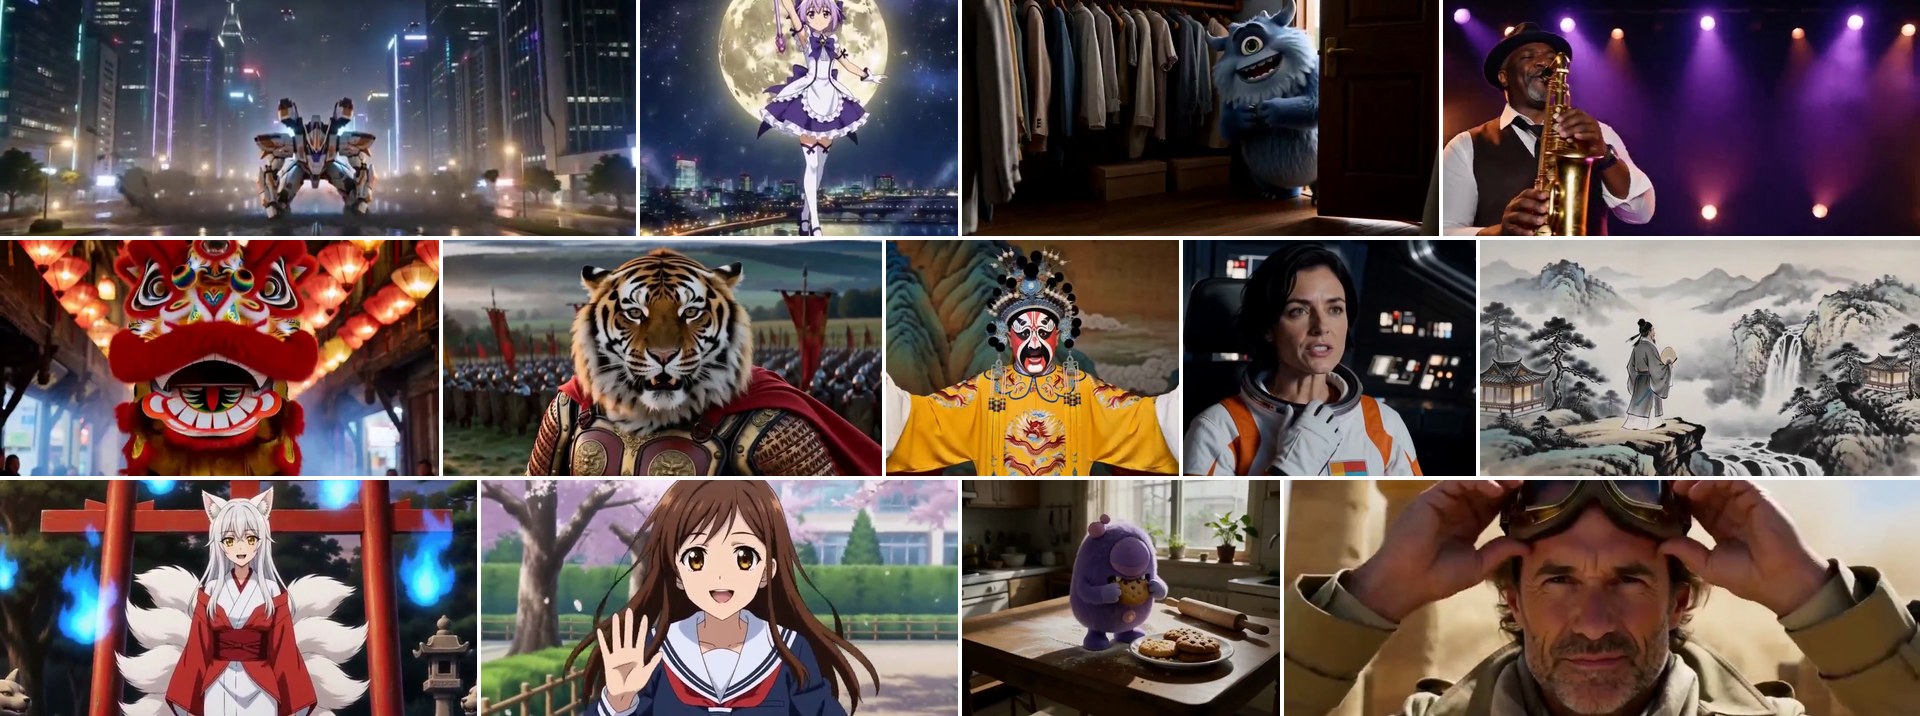
Clips from the 17B checkpoint, pruned with no training, 50 steps, with its own generated audio. Source: fuyi25/MiniMax-H3-Tiny
What you get
| File | Params | Size (bf16) | Load it in |
|---|---|---|---|
minimax_h3_tiny_17b_ref2va_bf16.safetensors | 17.1B | 34.2 GB | MiniMax H3 Reference to Video |
minimax_h3_tiny_17b_fl2va_bf16.safetensors | 17.1B | 34.2 GB | MiniMax H3 Image to Video (first/last frame or text only) |
minimax_h3_tiny_14b_okd_ref2va_bf16.safetensors | 14.0B | 28.1 GB | MiniMax H3 Reference to Video |
minimax_h3_tiny_17b_fewstep_ref2va_bf16.safetensors | 17.1B | 34.2 GB | Reference to Video, plus the H3-Tiny nodes (6 steps) |
The 17B drops 8 of 50 blocks and folds the per-block AdaLN tables into a rank-8 map: 13.0B of the original parameters sat in those tables, and they only read the timestep, so no data is needed to fit them. The 14B narrows every feed-forward layer from 14336 to 9792 channels and refits them against the 33B teacher.
Run it in ComfyUI
- Put one checkpoint in
ComfyUI/models/diffusion_models/. - Take the text encoder and VAEs from Comfy-Org/MiniMax-H3:
qwen3vl_32b_minimax_h3_*.safetensorsintomodels/text_encoders/,minimax_h3_video_vae_fp16.safetensorsandminimax_h3_audio_vae_fp32.safetensorsintomodels/vae/. - Open the built-in H3 template, pick the file in Load Diffusion Model, and sample at 50 steps,
simplescheduler, BasicGuider with no CFG. Do not add the turbo LoRA: the Comfy-Org turbo adapters were trained on the 33B and are untested here.
The few-step file needs the time-step endpoint that stock ComfyUI does not pass. Symlink the repo's comfyui/ folder into custom_nodes/, then load through H3-Tiny Few-Step Loader and take sigmas from H3-Tiny Few-Step Sigmas (6 steps by default, 4 or more work) into SamplerCustomAdvanced with euler.
The author tested the single files on ComfyUI commit afcb984 (2026-11-21) at 1344×768 and 243 frames on one H200, and reports the output matches their diffusers pipeline. Both formats are bf16, so 28 to 34 GB of weights plus the 51 GB text encoder: expect ComfyUI to stream them from RAM on smaller cards.
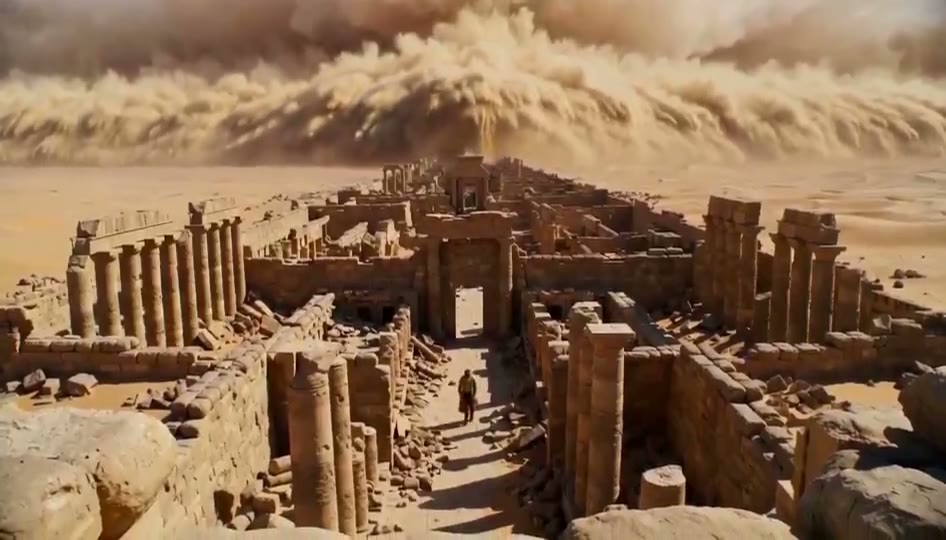
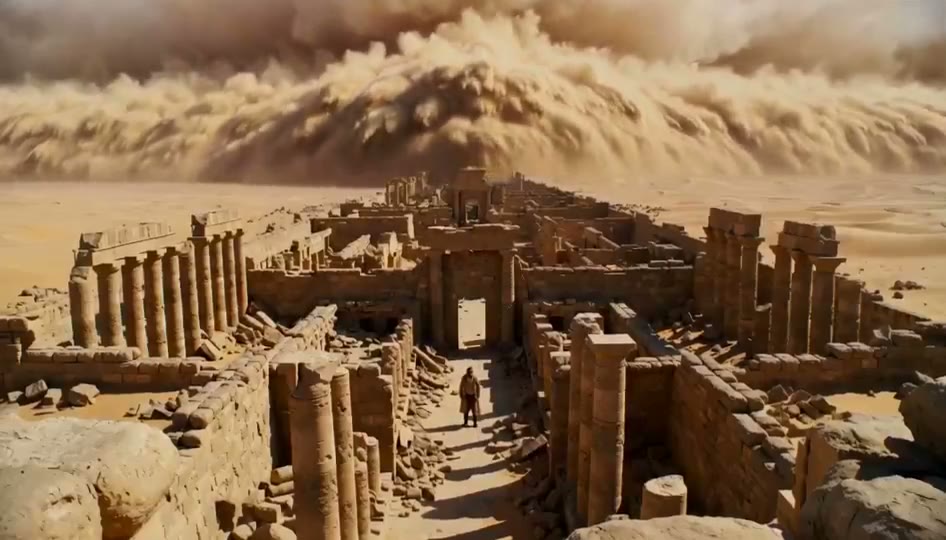
Same prompt, 33B against 17B
 |  |
|---|---|
| MiniMax H3 33B, 50 steps | H3-Tiny 17B, no training, 50 steps |
The 17B pruned checkpoint on the sandstorm case, audio included. Source: project page
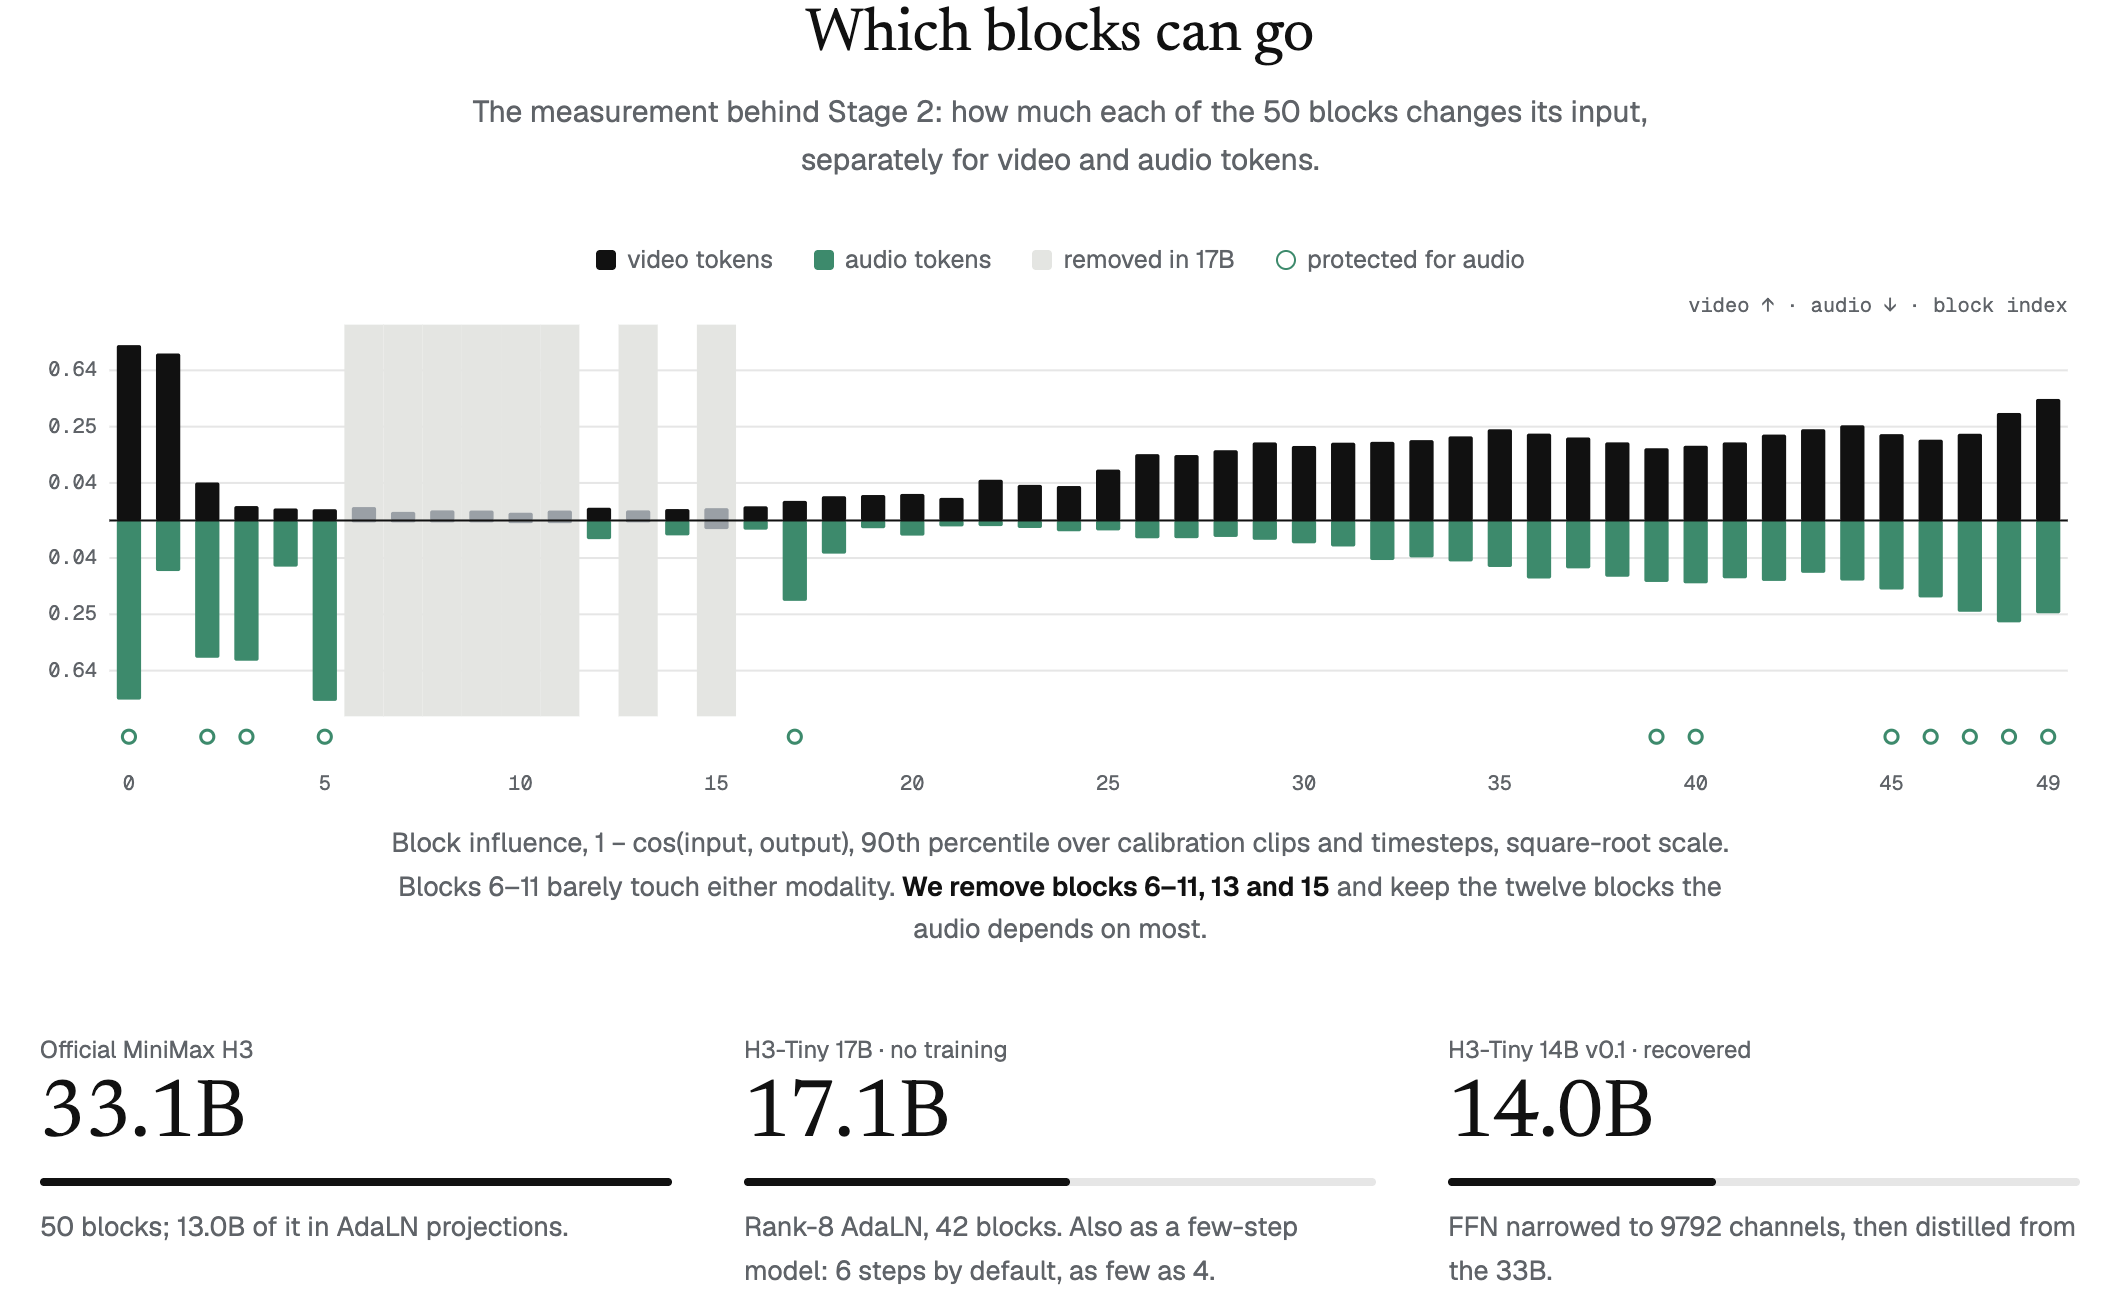
How much each of the 50 blocks changes video and audio tokens. Blocks 6–11, 13 and 15 are the ones removed in the 17B. Source: fuyi25/MiniMax-H3-Tiny
The project page pairs every clip with the original 33B and with HyperFlow H3 Flash at the same step count, so quality checks are a side-by-side rather than a score. Recovery (OKD) and few-step training code, plus the 14B few-step weights, are still marked as coming, and the paper is unpublished.
Availability
- ComfyUI single files: H3-Tiny/MiniMax-H3-Tiny-ComfyUI
- Diffusers checkpoints, 17B and 14B: H3-Tiny on Hugging Face
- Code, pruning scripts, conversion: fuyi25/MiniMax-H3-Tiny
- Samples and method: project page
Comments
Sign in with GitHub to join the discussion.