MOSS-Image 4-Step LoRA: eDMD Distillation Keeps Fine Detail
A rank-64 ComfyUI LoRA runs MOSS-Image-SFT in 4 steps at CFG 1 instead of 50 at CFG 3, with fine texture measured above the 50-step teacher.
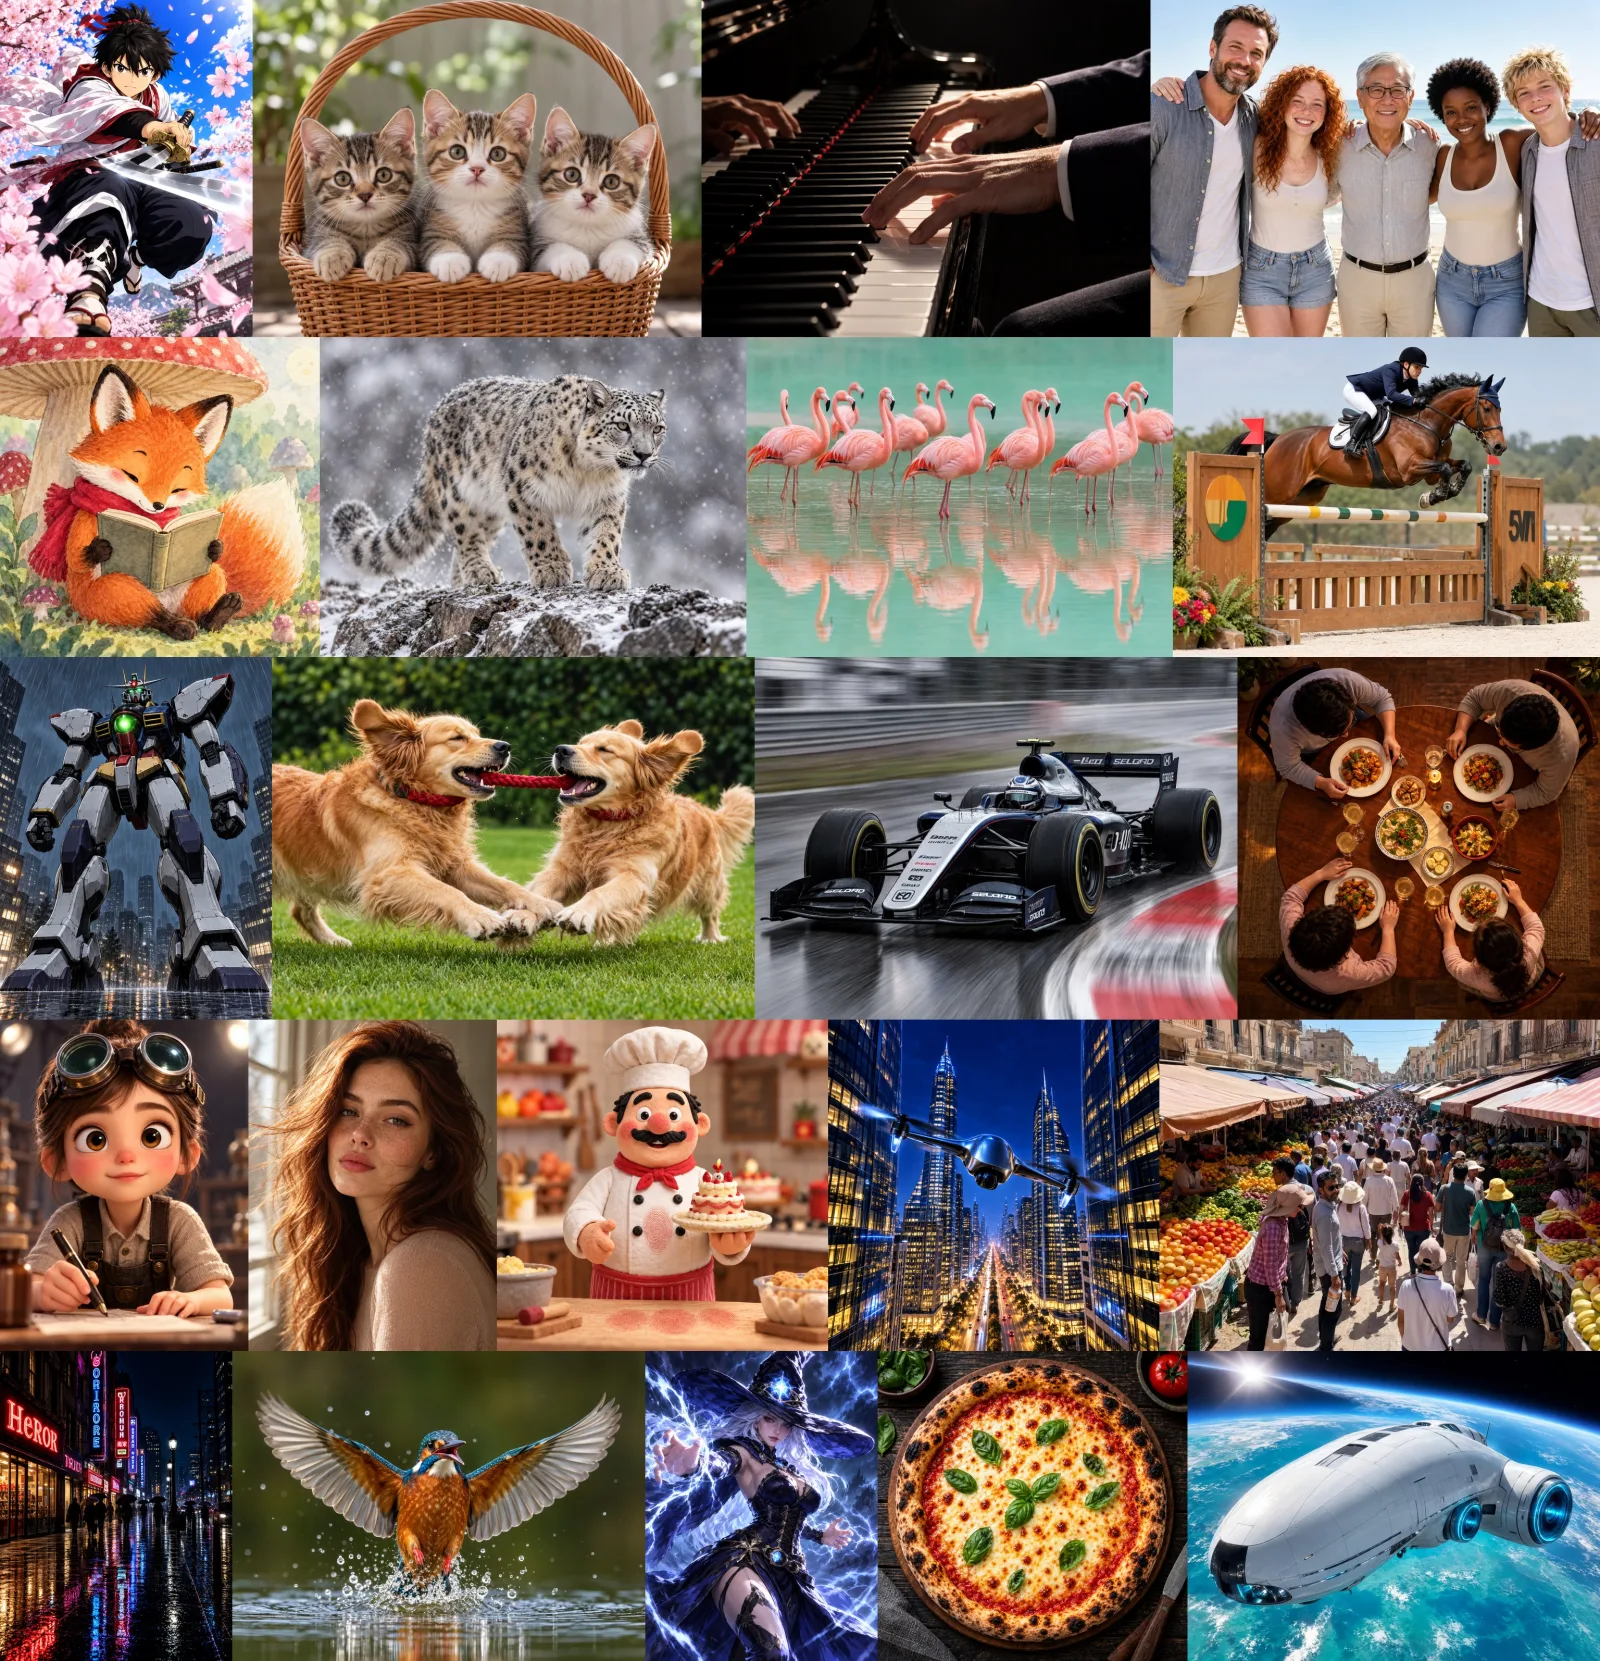
22 test prompts rendered by the LoRA at 4 steps. Source: lvladikov
What the 4 steps cost and keep
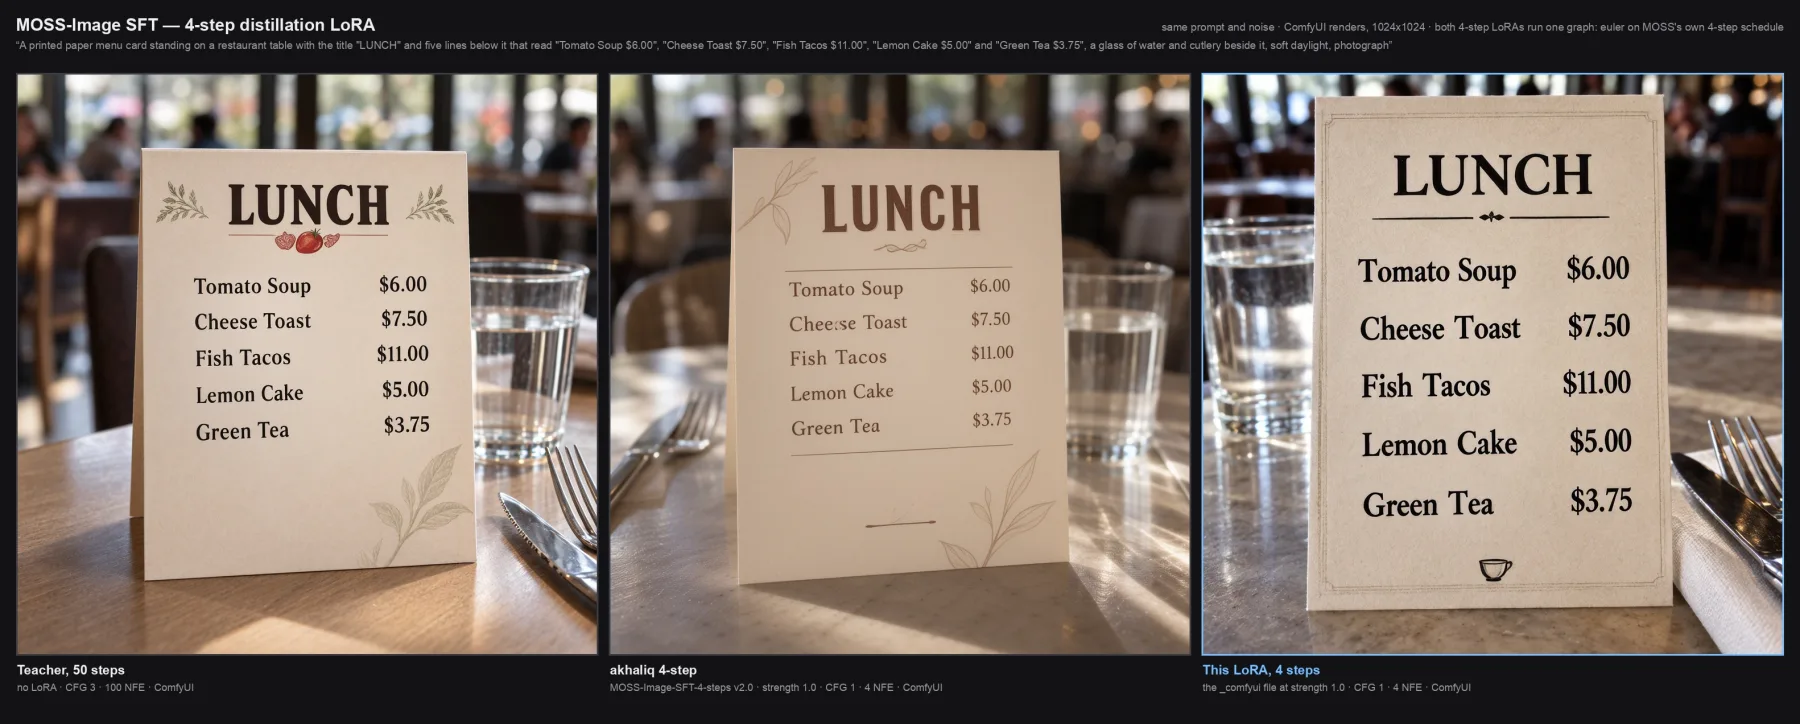
On the author's own measurements, 22 pictures at 1024² take 26.6 s instead of 387.3 s (Comfy Cloud billed GPU time), and fine texture averages 1.22× the 50-step teacher because the training mixes teacher pictures with about 8,000 captioned photo crops. Text rendering is the second claim: 14 of 15 text prompts come out with every requested string right, against 12 for akhaliq's 4-step LoRA.
These are the author's numbers. One independent check exists: a user compared nine MOSS turbo LoRAs against the 50-step baseline on classical-painting texture (craquelure, canvas weave, paper grain) and picked this one as closest to the baseline, ahead of the 12-step contenders.
 |
|---|
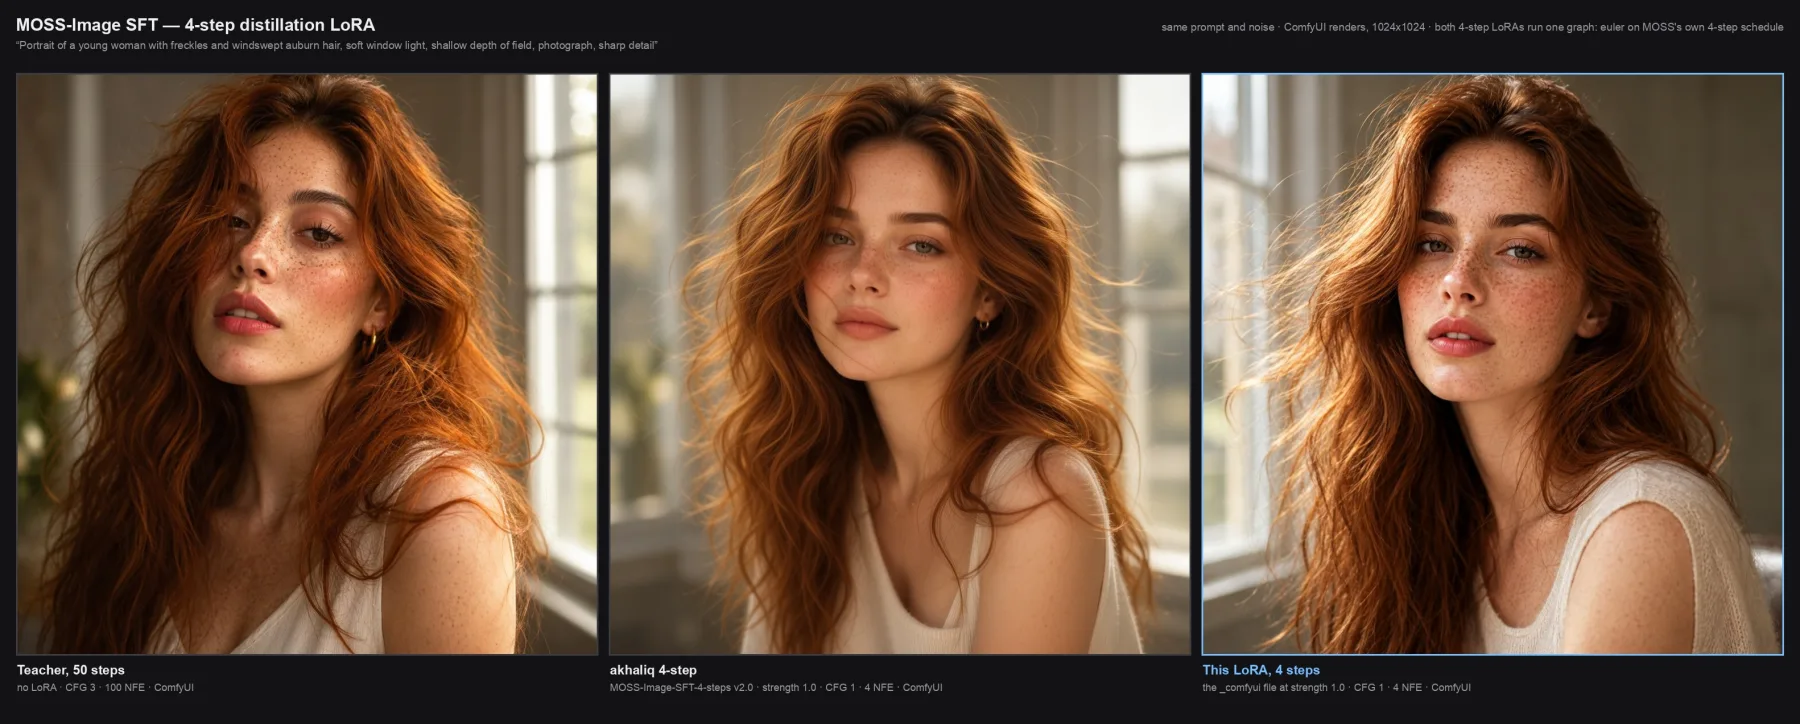
| One prompt, one starting noise: 50-step teacher · akhaliq 4-step · this LoRA. Source: lvladikov |
Where it is weaker
The LoRA is trained by distribution matching with an endpoint critic (eDMD) plus latent adversarial distillation (LADD), not by copying the teacher's output. Soft painted styles and dense photo detail land below the teacher: the watercolour test is 0.66× its fine texture, the portrait and a market crowd 0.80 to 0.85.
Early reports match that: the 4-step edit workflow works and layout prompting holds up, but photoreal faces are weaker, and one user sees occasional missing limbs. Another calls it "on par with lodestones' newest LoRAs" rather than a clean win.
 |
|---|
| A menu with five printed lines and prices: teacher · akhaliq 4-step · this LoRA. Source: lvladikov |
Run it in ComfyUI
Use the _comfyui file, not the plain one: ComfyUI adds the LoRA to bf16 weights and rounds the sum, so the shipped ComfyUI file carries a measured 1.18 factor in its alpha values. Load it at strength 1.0, 4 steps, CFG 1, and do not add the 50-step teacher's layer-skipping or negative prompt settings.
| File | Folder |
|---|---|
moss_sft_4step_rank_64_lora_comfyui.safetensors | ComfyUI/models/loras/ |
moss_image_sft_bf16.safetensors | ComfyUI/models/diffusion_models/ |
qwen3.5_9b_w4a8_gptq.safetensors | ComfyUI/models/text_encoders/ |
flux2-vae_small.safetensors | ComfyUI/models/vae/ |
The three base files come from Comfy-Org/MOSS-Image. The LoRA was trained on 12 resolutions, from 768×512 and 512×768 up to 1824×1024 and 1024×1824, so other aspect ratios are outside its training set.
Availability
- LoRA and eight workflows: lvladikov/MOSS-SFT-Distill-4step-LoRA. Text-to-image, layout-to-image, image edit and PiD 4× upscale, each for local ComfyUI and Comfy Cloud.
- Base model: OpenMOSS-Team/MOSS-Image-SFT, ComfyUI repack in Comfy-Org/MOSS-Image.
- Earlier 4-step options: akhaliq/MOSS-Image-SFT-4-steps, covered with the DMAD-based adapters in MOSS-Image few-step LoRAs.
Comments
Sign in with GitHub to join the discussion.