LongCat Video Avatar 1.6 Now Runs in ComfyUI
Meituan's audio-driven avatar model runs in ComfyUI now: Comfy-Org repackaged weights, a community native node pack, and core support in review.
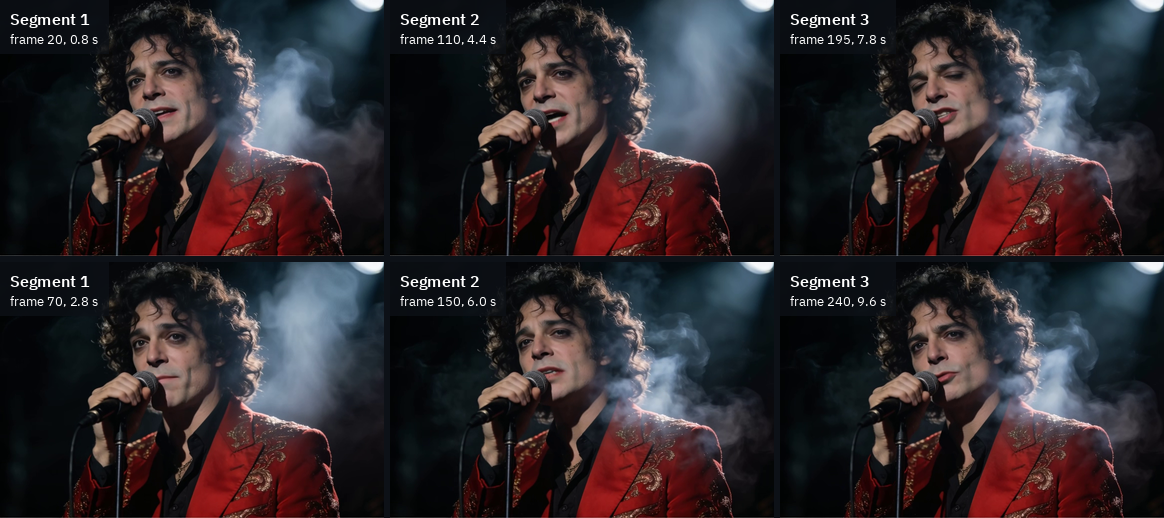
Two frames from each of the three 93-frame segments. Every segment continues from the last 13 frames of the one before.
Three ways in
| Path | State | What it is |
|---|---|---|
| Comfy-Org weights | Ready to download | Official int8 DiT, both LoRAs, the Whisper encoder and Wan 2.1's shared VAE and text encoder |
| ComfyUI-LongCat-Avatar (community) | Working today | Native node pack by Pedro (LatentSpacer), 8-step distilled and 50-step base video nodes |
| Core support (CORE-720, Kijai) | PR 17831, open | Adds comfy/ldm/wan/model_longcat.py and the audio encoder wiring; not merged yet |
The node pack installs from ComfyUI-Manager as LongCat Avatar Native, or with comfy node install longcat-avatar-native. It was tested on ComfyUI 0.44 and needs no packages beyond ComfyUI's own.
What you download
From Comfy-Org/LongCat-Video-Avatar, folders mirror ComfyUI/models:
| File | Folder | Size |
|---|---|---|
longcat-avatar-1.6_int8_convrot.safetensors | diffusion_models | 14.9 GiB |
longcat-avatar-1.6_dmd_lora_rank128_bf16.safetensors | loras | 1.2 GiB |
longcat-avatar-1.6_opsd_lora_rank128_bf16.safetensors | loras | 1.2 GiB |
umt5_xxl_int8_convrot or umt5_xxl_fp16 | text_encoders | 5.3 or 10.6 GiB |
whisper_large_v3_encoder_fp16.safetensors | audio_encoders | 1.2 GiB |
wan_2.1_vae.safetensors | vae | 242 MiB |
The text encoder and VAE are the Wan 2.1 files, so an existing ComfyUI install probably has them already.
Speed on one 4090
The port's author measured 5.1 s per continued step at 768×512 with int8 ConvRot and ComfyUI's ck attention: a 253-frame clip (10.1 s of speech) in three segments took about 162 s. He also shipped W6A8 and W4A8 copies, 12.3 and 8.8 GiB against 14.9 GiB for int8 and 29.5 GiB for bf16, and both LoRAs apply to all of them.
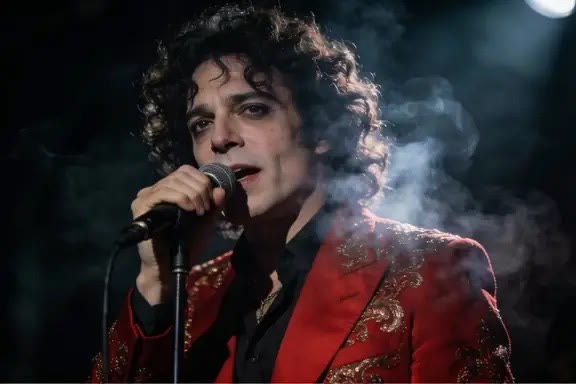
One clip from the node pack: the mouth follows the speech across all three segments.
The base 50-step node runs with text and audio guidance and no LoRAs, and since each step runs the model three times it is many times slower than the distilled path.
Availability
- ComfyUI weights: Comfy-Org/LongCat-Video-Avatar
- Node pack: ComfyUI-LongCat-Avatar, weights mirror at PedroMarinhoDev/LongCat-Video-Avatar-1.6-ComfyUI
- Core support: Comfy-Org/ComfyUI PR 17831
- Original model: meituan-longcat/LongCat-Video-Avatar-1.6
Comments
Sign in with GitHub to join the discussion.