PAN 2 runs natively in ComfyUI: int8, 26.7 GB, 241 frames
PAN 2, MBZUAI's 29B world model, now loads in ComfyUI through Kijai's core PR: int8 weights at 26.7 GB and 241 frames at 15.2 s/step on an RTX 5090.
PAN 2 no longer needs a custom node. PR #17755 merged into ComfyUI core on 15 November, so the 29B world model from MBZUAI loads through the built-in UNETLoader and CLIPLoader, and image-to-video reuses the stock Wan 2.2 latent node. The int8 build is 26.7 GB, and a 241-frame clip samples at 15.2 s/step on an RTX 5090.
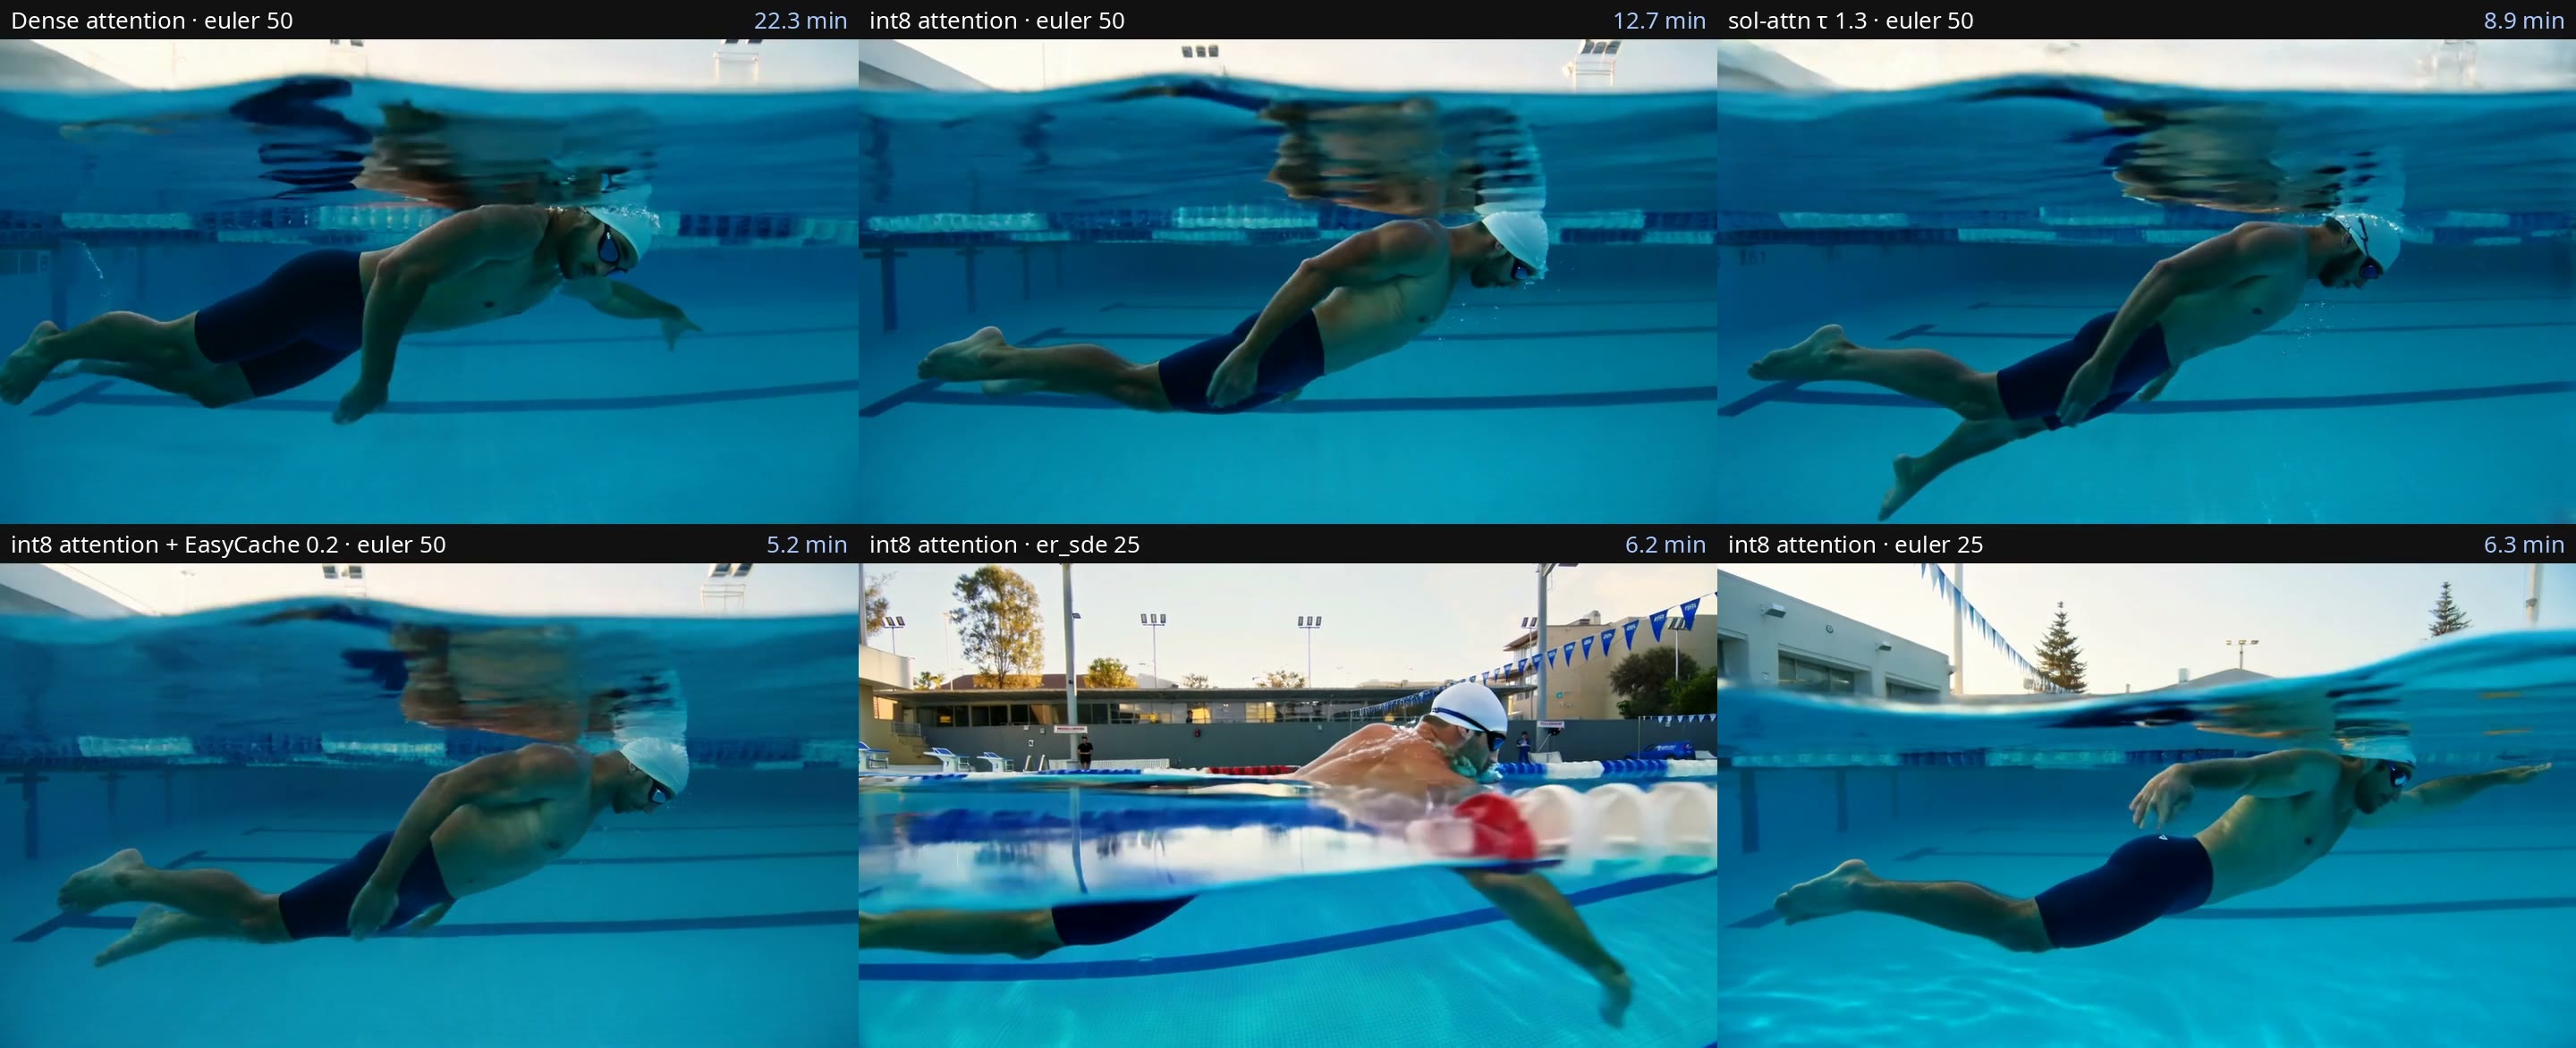
A frame from the 241-frame int8 sample attached to the core PR. Source: Comfy-Org/ComfyUI #17755
The full 241-frame clip, 2880x1172 at 24 fps, re-encoded at 960 px wide. Source: Comfy-Org/ComfyUI #17755
What core support changes
- Text encoder:
CLIPLoadergains apan2type. It runs stock Qwen3.5-9B and taps layer 30 of 32 without the final norm, then trims the caption span after the system turn. - Image-to-video: the conditioning carries
[latent * known, known]fromlatent_imageanddenoise_mask, so the existingWan22ImageToVideoLatentnode drives the first frame. - Smaller int8: the 44 per-block adaLN linears only read
silu(temb(t)), so the checkpoint can ship a 4097x192 curve table instead of the time embedder. Modulation error stays at 1.3e-4 and the int8 file drops from 30.4 GB to 26.7 GB. - Lower activation peak: the video FFN runs in token chunks, bit-identical output, and the peak falls from 12.5 GB to 3.8 GB at 241 frames.
Defaults match the authors' code: 50 steps, euler/simple, CFG 2.5, 24 fps, shift 9.
Files to download
Everything comes from the Comfy-Org/PAN2 repack, as single files for the standard model folders.
| File | Size |
|---|---|
diffusion_models/pan2_int8_convrot.safetensors | 26.7 GB |
diffusion_models/pan2_bf16.safetensors | 67.4 GB |
text_encoders/qwen3.5_9b_int8_convrot.safetensors | 9.8 GB |
text_encoders/qwen3.5_9b_bf16.safetensors | 19.3 GB |
vae/wan2.2_vae.safetensors | 1.4 GB |
Speed
On the same RTX 5090, 241 frames: 15.2 s/step with int8 weights and int8 attention on the joint blocks, against 26.8 s/step for the dense build. The PR author checked same-seed clips visually and reports the velocity error matches int8 weights against bf16. BlockSparseAttention and EasyCache work on top of it unchanged.
Prompts still need structure
PAN 2 was trained on structured JSON captions. A one-line prompt returns noise, including the one-liner in the model's own example, so write the scene, event, subject, lighting, viewpoint and style fields before sampling. The prompt rewriter's system prompt can run through TextGenerateV2 on the same text encoder file, which keeps the rewrite inside one graph.
Getting it
There is no official workflow template for PAN 2 yet, so the graph is built by hand: UNETLoader → CLIPLoader (pan2) → CLIPTextEncode, plus Wan22ImageToVideoLatent for image-to-video, then KSampler → VAEDecode → CreateVideo.
The feature merged after the current release, so it is only in builds newer than v0.45.0. For the older custom-node route and the original model files, see our PAN 2 report from 10 November.
Comments
Sign in with GitHub to join the discussion.