TaoMate-FVSR Restores Faces in AI Video From the Audio
TaoMate-FVSR rebuilds blurry or wrong mouths in generated video using the soundtrack as a guide, re-syncs lips for dubbing, with ComfyUI nodes on the official weights.
comfyui branch with nodes, four example workflows and a model downloader, so it runs inside ComfyUI without a converted checkpoint.
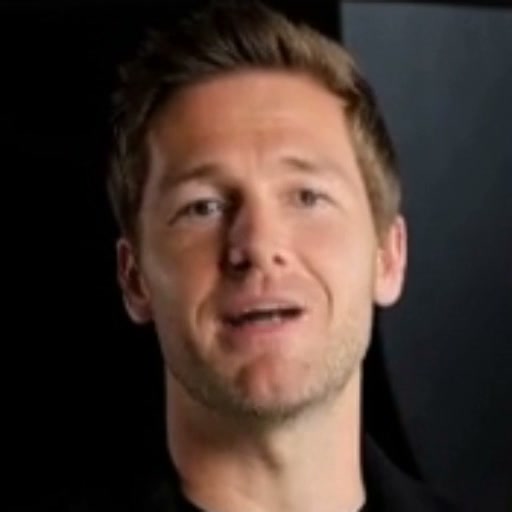
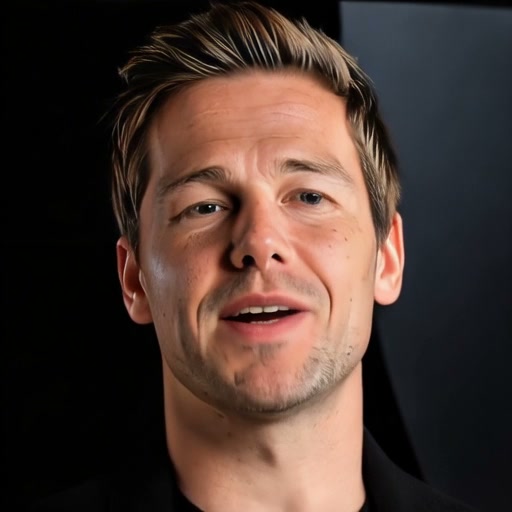
It is aimed at the specific failure that shows up in generated video: the face renders soft, teeth fuse into a white blur, and the mouth does not follow the line. Enhancing what is there keeps the broken shape; regenerating the face changes who it is. TaoMate-FVSR does both at once, using the audio to drive the mouth, a reference frame to hold the identity, and previously generated frames to keep the shot stable.
 |  |
|---|---|
| Input 512×512 face crop | TaoMate-FVSR output, same frame |
The project's synchronised before/after clip, face crops at 25 fps.
What it does to a clip
- Full-scene mode. It crops the head, restores it, then blends colour and mask and pastes it back. Output keeps the source resolution, frame rate and audio, so it drops into an existing edit.
- Visual dubbing. Feed it replacement speech instead of the original track and the mouth is re-timed to that audio.
- Reference frame. By default the first frame goes through GPEN once to build the identity reference. You can also supply your own edited first frame, which the paper's "Ours+" variant does with a GPT-Image-enhanced frame: nicer skin and detail, but pixels drift further from the ground truth.
On its 150-clip talking-head benchmark it takes the best LPIPS (0.0793) and DISTS (0.0858) among the restoration baselines it compares against, plus the best lip-sync score (Sync-C 7.413). One caveat worth knowing before you judge the numbers: the enhancement-based variant scores lower on PSNR (23.52) while scoring highest on perceptual quality (MUSIQ 77.62), so "restored" and "matching the ground truth" are not the same thing here.
Run it in ComfyUI
- In
ComfyUI/custom_nodes, clone thecomfyuibranch:git clone --depth 1 --single-branch --branch comfyui https://github.com/TaoLiveAIGC/TaoMate-FVSR.git ComfyUI-TaoMate-FVSR - Install its requirements with ComfyUI's own Python, keeping the existing CUDA PyTorch build.
- Fetch the model files:
python scripts/download_models.py --dest ../../models/TaoMate-FVSR --gpen-source-dir ../../models/TaoMate-GPEN-source. It checks sizes and SHA256, and resumes partial downloads. - Open one of the four example workflows.
yolo-gpen-workflowis the full-scene path with automatic face cropping;cropped-face-workflowstarts from prepared 512×512 faces.
Budget around 14.89 GB of model and config files, and 32 GB of system RAM on the longest tested clip. The 16 GB VRAM target is measured on an H20 with a memory cap, not a consumer card, and 8/12 GB operation is untested. Linux, Python 3.10 and PyTorch 2.9 were the accepted setup; Windows paths are documented but not verified.
1× or 2×
The model runs at two scales. 1× keeps the face crop at 512×512 and is the default; 2× runs at 1024×1024 for more detail and needs more VRAM, with the result scaled back to 512×512 before paste-back. Defaults sit in config.json: 10 steps, noise 0.8, shift 5.0, audio guidance 4.0, reference guidance 1.7, seed 42.
Availability
- Weights: TaoLiveAIGC/TaoMate-FVSR, single
TaoMate-FVSR.safetensorsplusconfig.json. - Code and ComfyUI nodes: TaoLiveAIGC/TaoMate-FVSR, with the install guide in English and Chinese.
- Paper: arXiv 2611.03393; more comparisons on the project page.
The ComfyUI branch is labelled experimental: it is a manual install, it is not registered in ComfyUI Manager, and it reuses the original weights rather than shipping a node-specific checkpoint.
Comments
Sign in with GitHub to join the discussion.