LongCat Video Avatar 1.6 Keeps a Talking Avatar Going Past 10 Minutes
Meituan's LongCat Video Avatar 1.6 turns one photo and an audio track into lip-synced avatar video past ten minutes, with a faster 8-step path and INT8 weights.
Frames from the 1.6 preview clips: one portrait plus one audio track.
What changed in 1.6
| Area | 1.6 |
|---|---|
| Lip and mouth motion | fewer strained or over-red mouth shapes, less flicker in the mouth region |
| Long clips | autoregressive error buildup reduced, so videos can run past 10 minutes while holding identity and body structure |
| Speed | end-to-end pipeline and per-frame execution optimizations, no new model to learn |
| Deployment | optional weight-only INT8 DiT, plus an FP8 flag for Transformer Engine |
1.6 runs on the same base architecture as 1.5 and keeps the two adapter stack: a DMD LoRA for the first passes and an OPSD LoRA for the rest, mixed per step. With the default 8-step setup the first four steps use DMD only and the last four use OPSD only; raise --mix_steps or --mix_alpha to give DMD more influence early.
Watch it
A continuation test from the model card, where the clip keeps going instead of degrading.
Beyond speech: the model also drives singing and performance from the audio alone.
How it compares
Meituan ran an arena of 33,051 pairwise human votes over 15 model pairings. 1.6 finishes second behind OmniHuman-2.0, and its margin over 1.5 is small: 16 Elo.
| Rank | Model | Arena Elo |
|---|---|---|
| 1 | OmniHuman-2.0 (closed) | 1236.7 |
| 2 | LongCat-Video-Avatar 1.6 (open) | 1068.1 |
| 3 | LongCat-Video-Avatar 1.5 (open) | 1051.8 |
| 4 | HeyGen (closed) | 906.4 |
| 5 | OmniHuman-1.5 (closed) | 880.6 |
| 6 | Kling Avatar 2.0 (closed) | 854.7 |
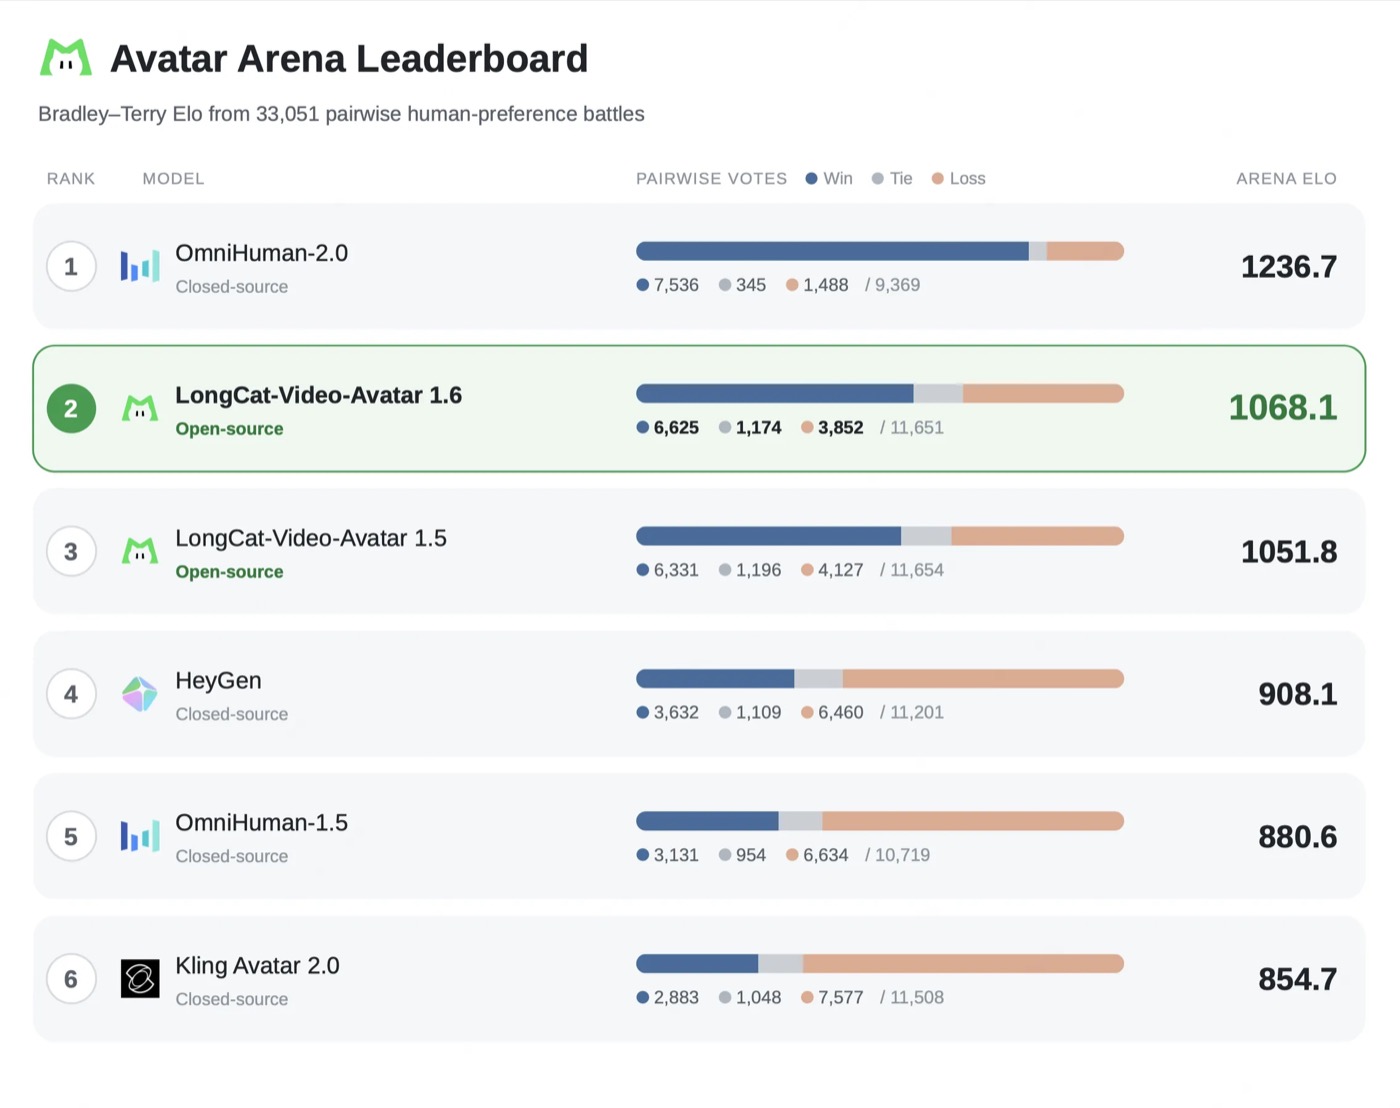
The leaderboard as published in the 1.6 model card.
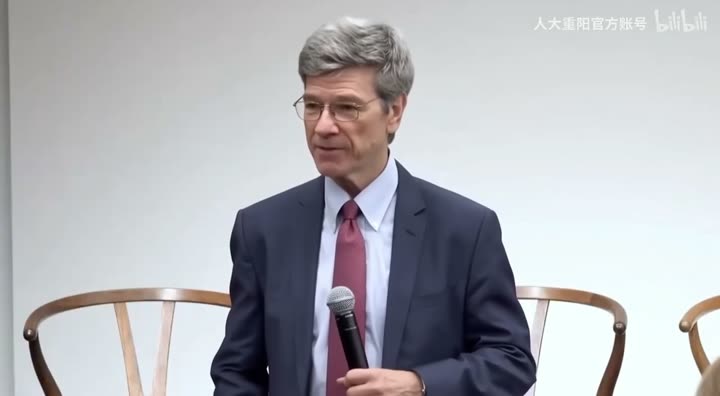
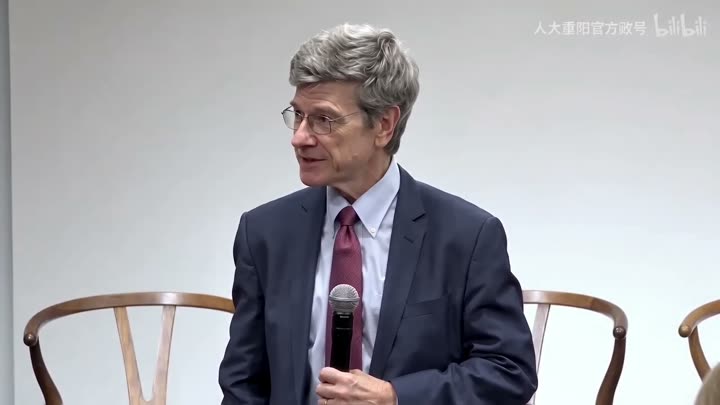
Same input, three systems, one frame each:
| LongCat-Video-Avatar 1.6 | OmniHuman-2.0 | HeyGen |
|---|---|---|
 |  |  |
What it takes to run
- BF16 DiT is about 30 GB across six shards; the optional INT8 DiT drops that to about 15 GB.
- The two LoRAs are 2.35 GB each, and the repo bundles its Whisper-large-v3 audio encoder and a vocal separator.
- Official demo commands use
torchrunover two GPUs with context parallel. More than two GPUs gets an All-to-All workspace viaLONGCAT_A2A_WORKSPACE=1. - Do not combine
--use_int8with--use_fp8. FP8 needs Transformer Engine, and--compile_ditpays a tracing cost on the first run of each input shape.
ComfyUI status
ComfyUI support still stops at 1.5. The community pack ComfyUI-LongCat-Avatar (★43) has not been updated for the new checkpoint, so there is no 1.6 node path yet. Until one appears, 1.6 runs through the official Python pipeline.
Availability
- Weights: meituan-longcat/LongCat-Video-Avatar-1.6
- Project page with full comparison videos: LongCat-Video-Avatar 1.6
- Inference code and Technical Report: meituan-longcat/LongCat-Video
Comments
Sign in with GitHub to join the discussion.