ComfyUI v0.45.0 Doubles Qwen3.x Text Generation Speed
ComfyUI v0.45.0 rewrites Qwen3.x text generation: Qwen3.5 9B on an RTX 5090 goes from 106 to 219 tokens per second, with adaptive tree MTP and INT8 attention.
Prompt enhancement, image captioning and story writing in ComfyUI are all text generation, so they get the speedup for free. The only thing to set is the mtp option of the Generate Text node, which stays on auto by default.
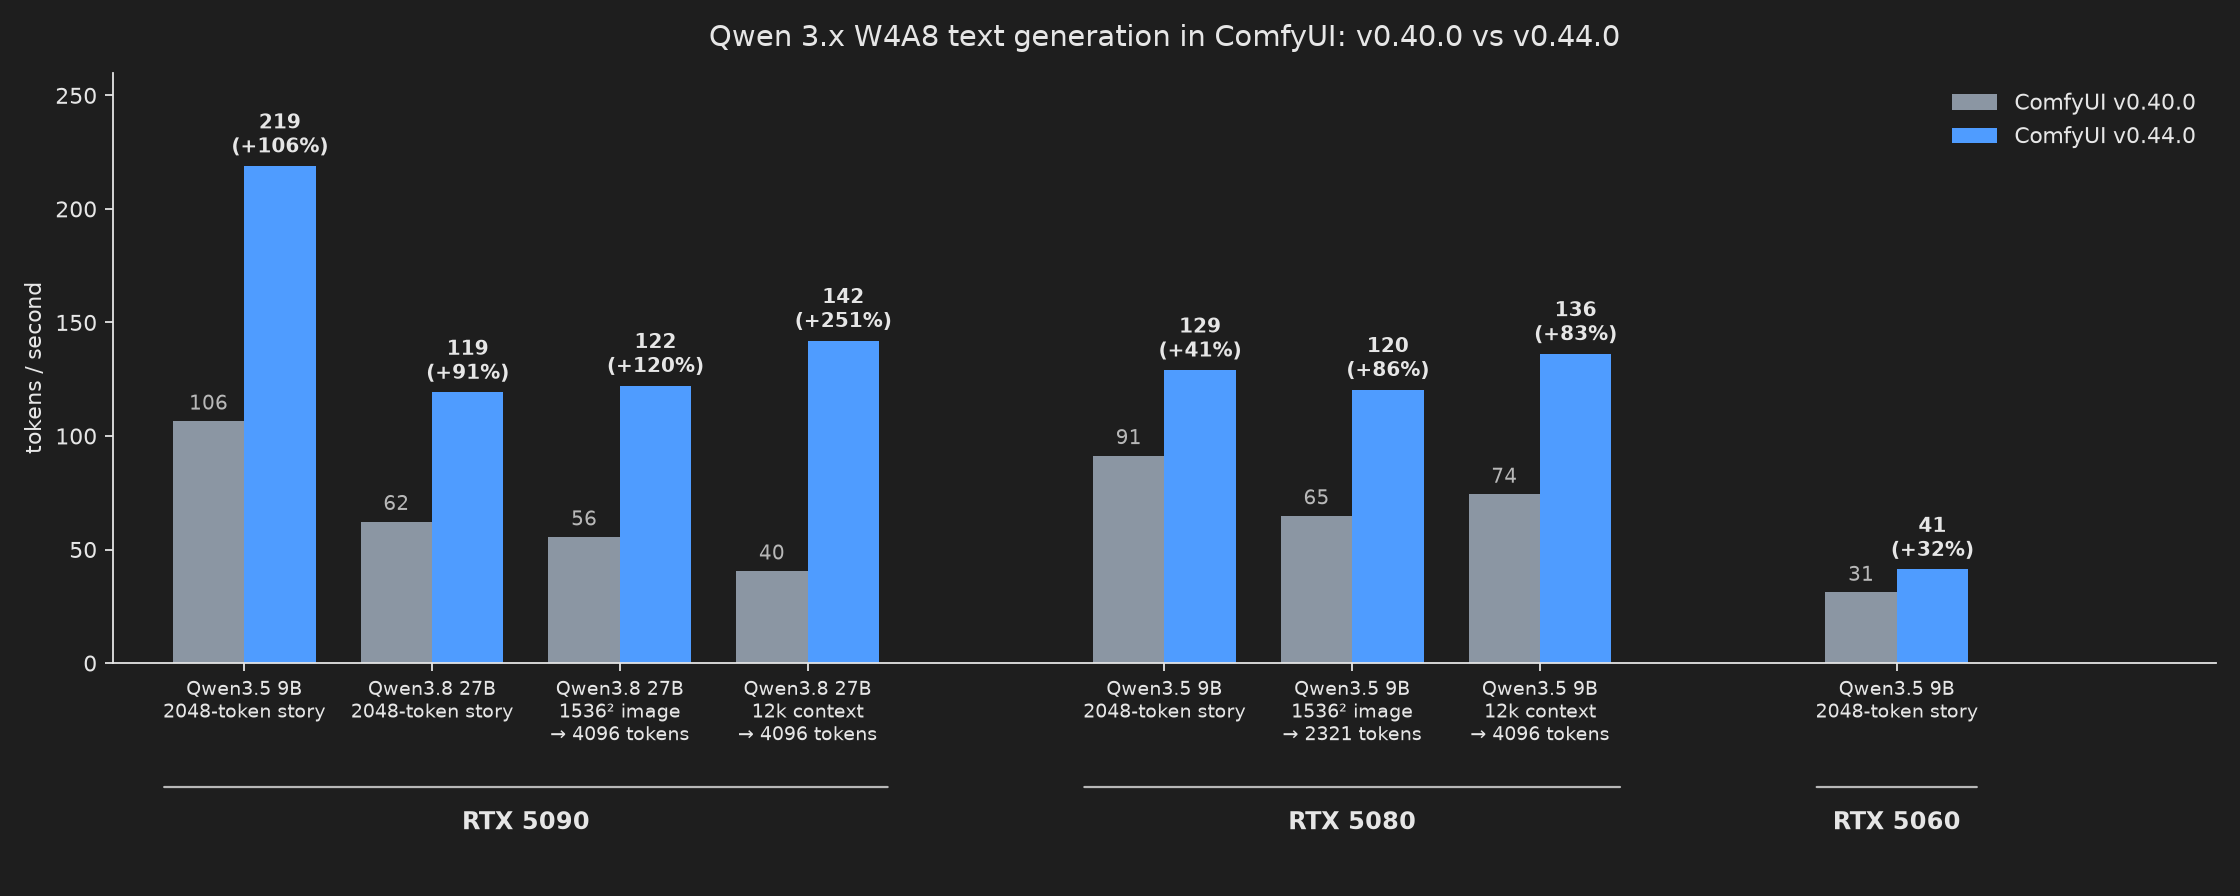
From the Comfy-Org engineering post announcing the rewrite.
Measured token rates
| Checkpoint | GPU | Before | v0.45.0 |
|---|---|---|---|
| Qwen3.5 9B | RTX 5090 | 106 tok/s | 219 tok/s |
| Qwen3.5 9B | RTX 5080 | 91 tok/s | 129 tok/s |
| Qwen3.8 27B, describing a 1536×1536 image | RTX 5090 | 55 tok/s | 122 tok/s |
Qwen3.8 27B W4A8 reached 137 tokens per second on an RTX 5090 while describing a 1500×1500 image and writing a story.
What changed
- Matrix-vector kernel: W4A8 and W6A8 weights are now interleaved with their per-group scales in the order the kernel reads them, so each thread block streams one contiguous run instead of hopping between two tensors. The re-layout happens once per model load, in VRAM, with no extra RAM or VRAM cost.
- Adaptive tree MTP: the multi-token-prediction head no longer drafts a single chain of guesses. It keeps runner-up tokens as siblings, verifies up to eight rows in one pass, and re-plans the tree shape every 32 steps. Code, lists and prompts reused in the output reward depth; creative writing rewards breadth.
- Comfy-Kitchen attention: INT8 attention plus KV cache support for the LLM attention path, which cuts KV cache VRAM use and speeds up prefill on long prompts and system prompts.
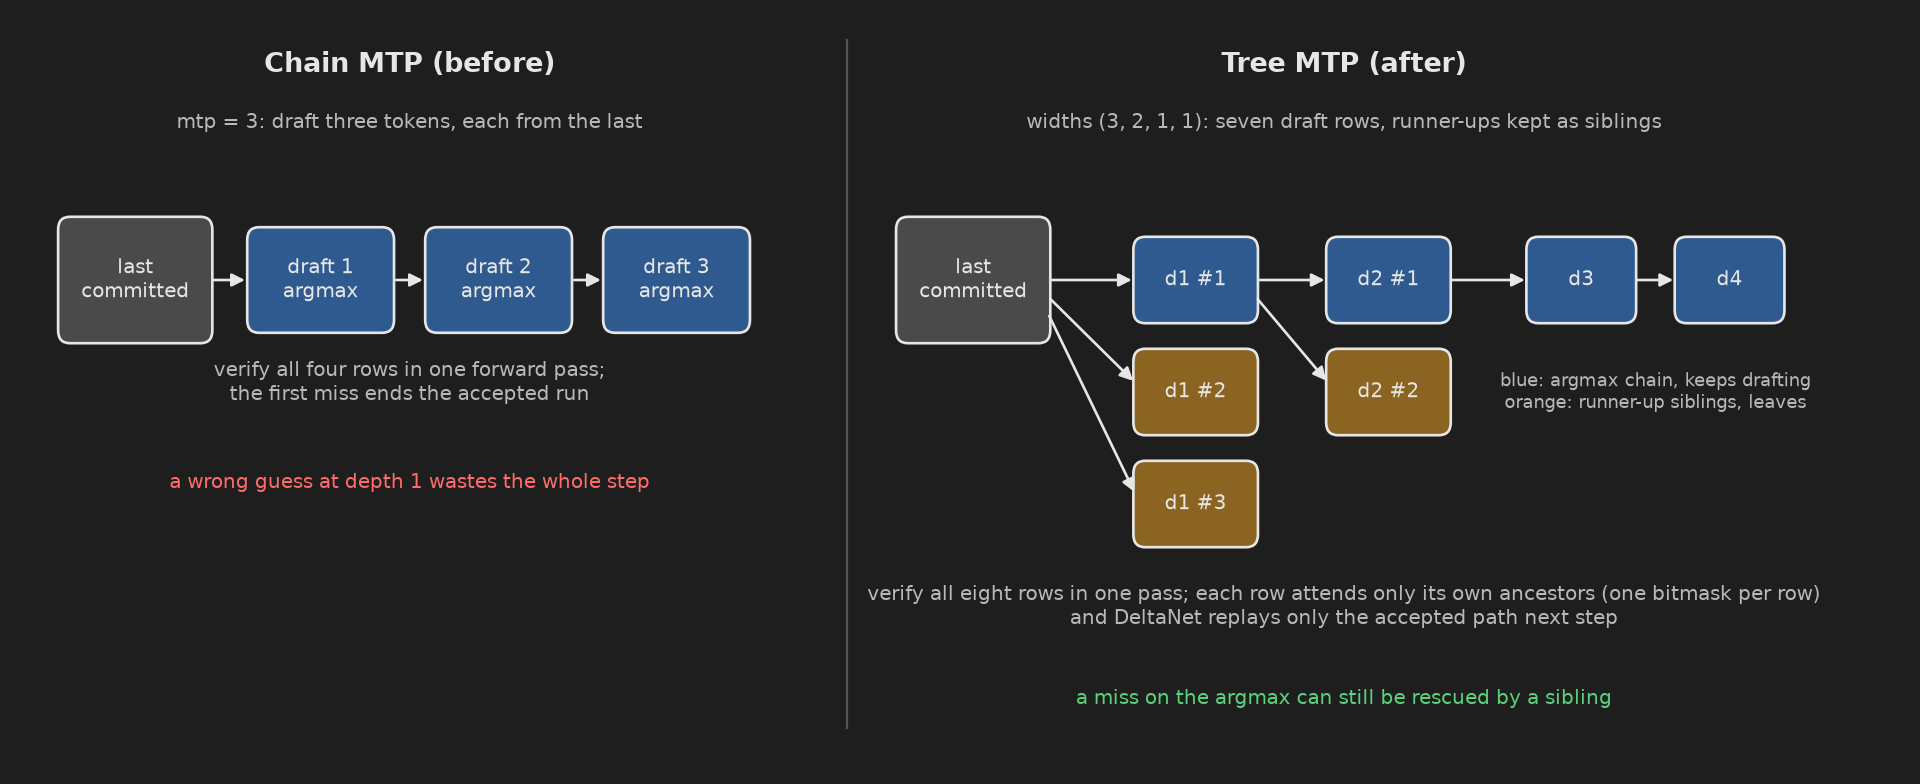
Chain MTP drafts one path; tree MTP keeps the runner-up tokens as siblings and verifies them together.
How to turn it on
- Update to ComfyUI v0.45.0 or newer.
- Load a Qwen3.x checkpoint and run it through the
Generate Textnode. - Leave
mtponauto. Pinned values2to5still fix the draft depth, and thetree*modes fix both breadth and depth. - Optional: start ComfyUI with
--use-ck-attentionfor Comfy-Kitchen attention. This needs a Comfy Kitchen build that includes attention support.
Everything above works on NVIDIA and AMD GPUs, on Windows and Linux, and longer contexts that used to run out of memory now fit. One detail from the node tooltip: MTP output stays correctly distributed but differs from non-MTP output for the same seed.
Comments
Sign in with GitHub to join the discussion.