WeVisOne-VL in ComfyUI: Boxes, Masks and Mattes From One Prompt
Tencent's WeVisOne-VL now runs in ComfyUI core. One Detect node turns a text query into boxes, masks, alpha mattes, points, counts and OCR boxes.
WeVisOne-VL is Tencent WeChat Vision's vision model, and it now runs in ComfyUI core. The support landed on 2026-11-09 as PR 17632. You give it an image and a phrase, it gives back boxes, masks, alpha mattes, points, a count, or OCR boxes. No SAM, no custom nodes, no separate segmentation backend.
The 2B and 4B checkpoints are Qwen3-VL fine-tunes with a 9.6M-parameter mask decoder. The node reads the phrase, writes coordinates as plain tokens, and the decoder turns the matching tokens into pixel-level output.
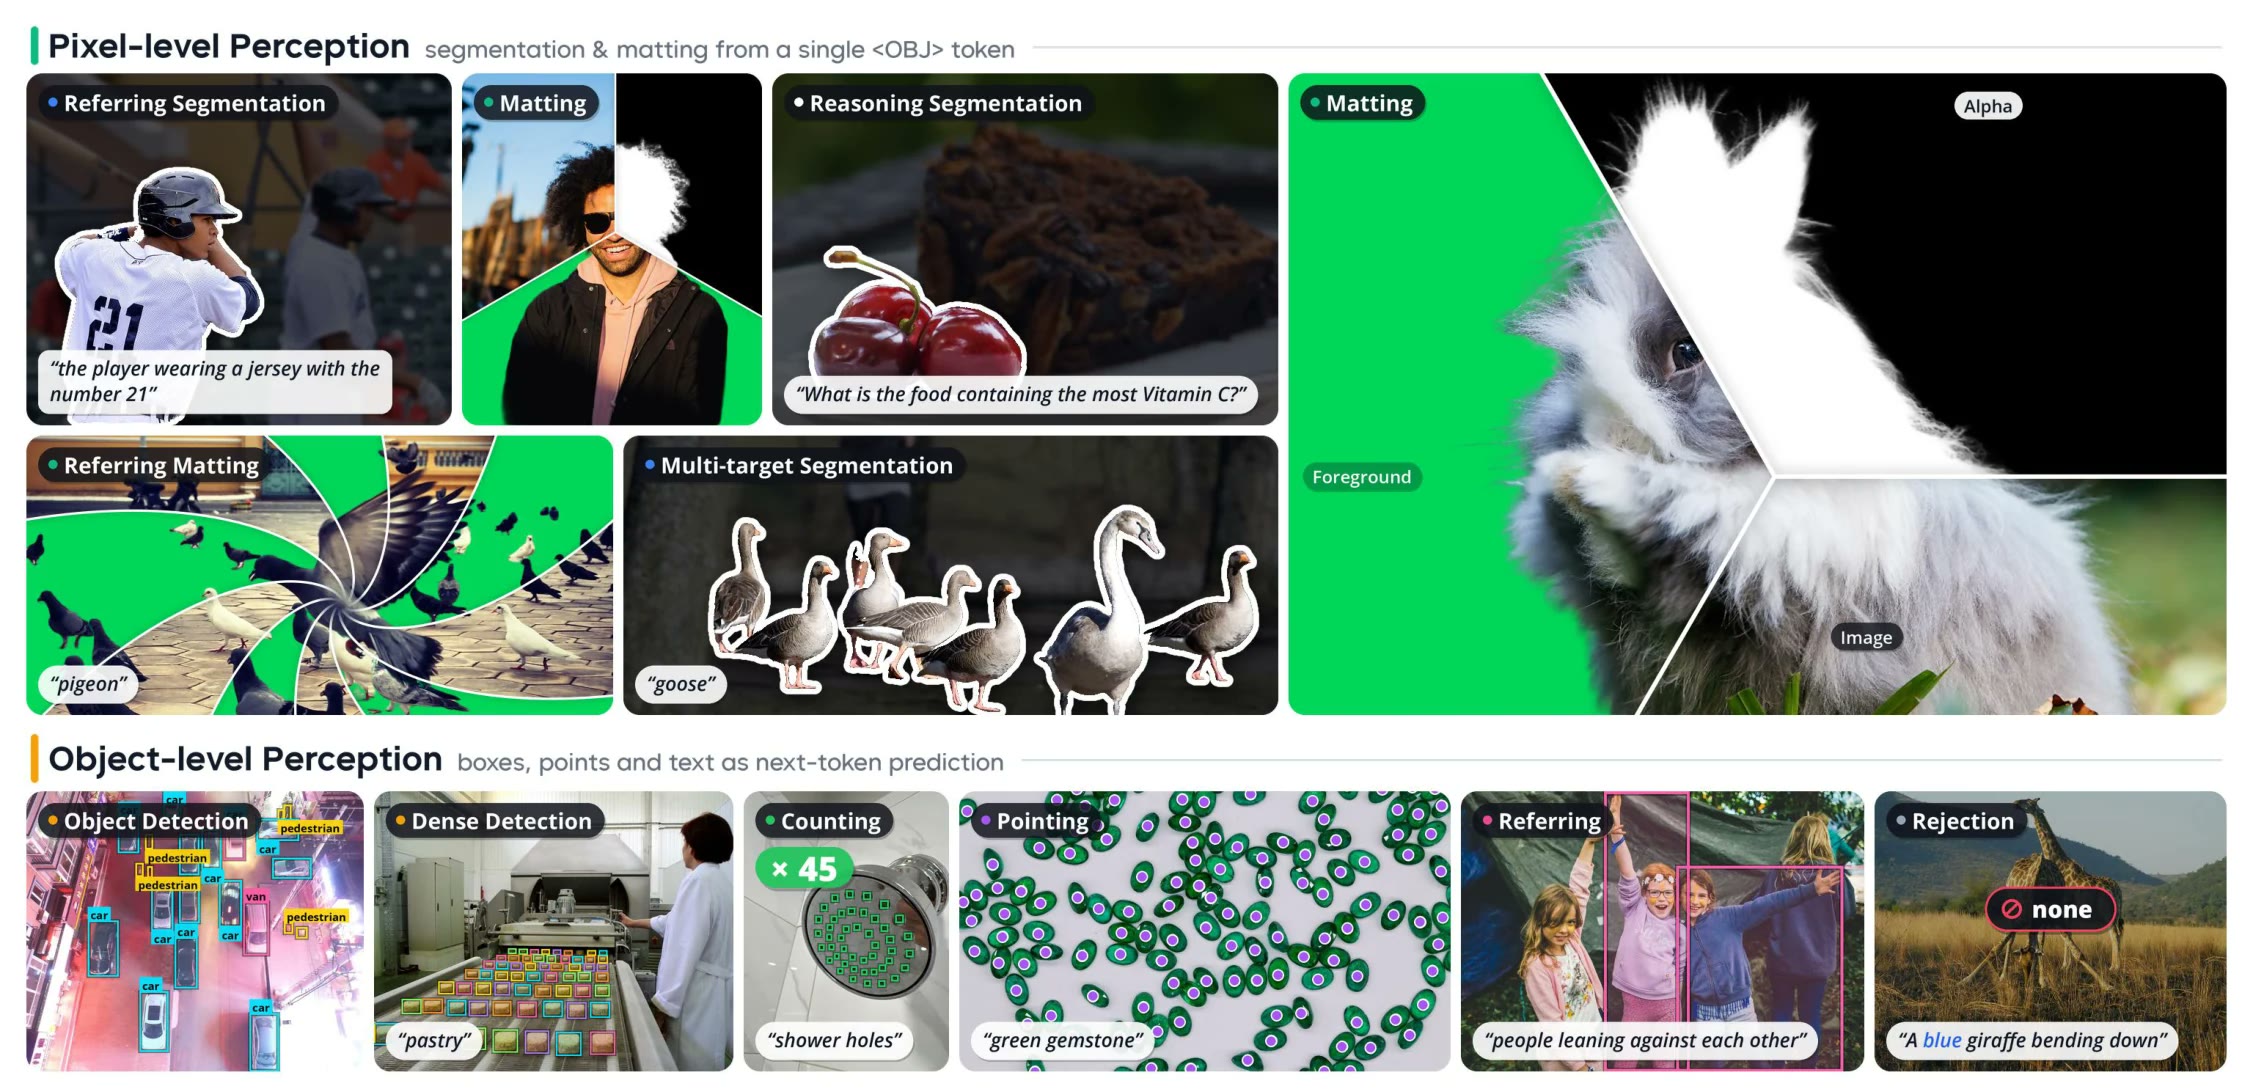
One model covers points, boxes, binary masks and continuous alpha mattes. Source: project page
What the node returns
WeVisOne-VL Detect sits under image/detection and has four outputs: masks, bboxes, points (JSON in pixel coordinates), and the raw answer text. What you get depends on the task you pick.
| Task | What you type | Output |
|---|---|---|
segmentation | a phrase, e.g. person | boxes plus per-instance alpha mattes |
detection | one label per line | boxes, ready for Draw BBoxes |
referring | a describing phrase | boxes for the matching object |
point | one label per line | point coordinates as JSON |
count_box / count_point | the subject, e.g. cars | count, with boxes or points |
ocr | leave empty | every word as a box |
ocr_grounding | the text string | where that text is |
visual_prompt | reference boxes from another run | objects similar to the reference |
freeform | your whole prompt | raw answer |
Turn on individual_masks to keep one mask per box instead of a single union mask. For cutouts, wire masks and the image into InvertMask + JoinImageWithAlpha.
Every coordinate is one token from <0> to <1000>, so a box costs four tokens. Source: project page
How to run it
-
Update ComfyUI. The node is on master; the latest tag (v0.44.2) does not include it yet.
-
Download the weights from Comfy-Org/WeVisOne-VL into
ComfyUI/models/text_encoders/. The repack ships four files:File Size wevisone_vl_4b_bf16.safetensors9.7 GB wevisone_vl_4b_int8_convrot.safetensors5.3 GB wevisone_vl_2b_bf16.safetensors4.9 GB wevisone_vl_2b_int8_convrot.safetensors2.9 GB -
Load a
CLIPLoaderwith typestable_diffusionand pick one of those files, then connect it to the node'sclipinput.
The three-group example from the PR: alpha matting on a person, detection and OCR. Swap the three LoadImage nodes for your own images.
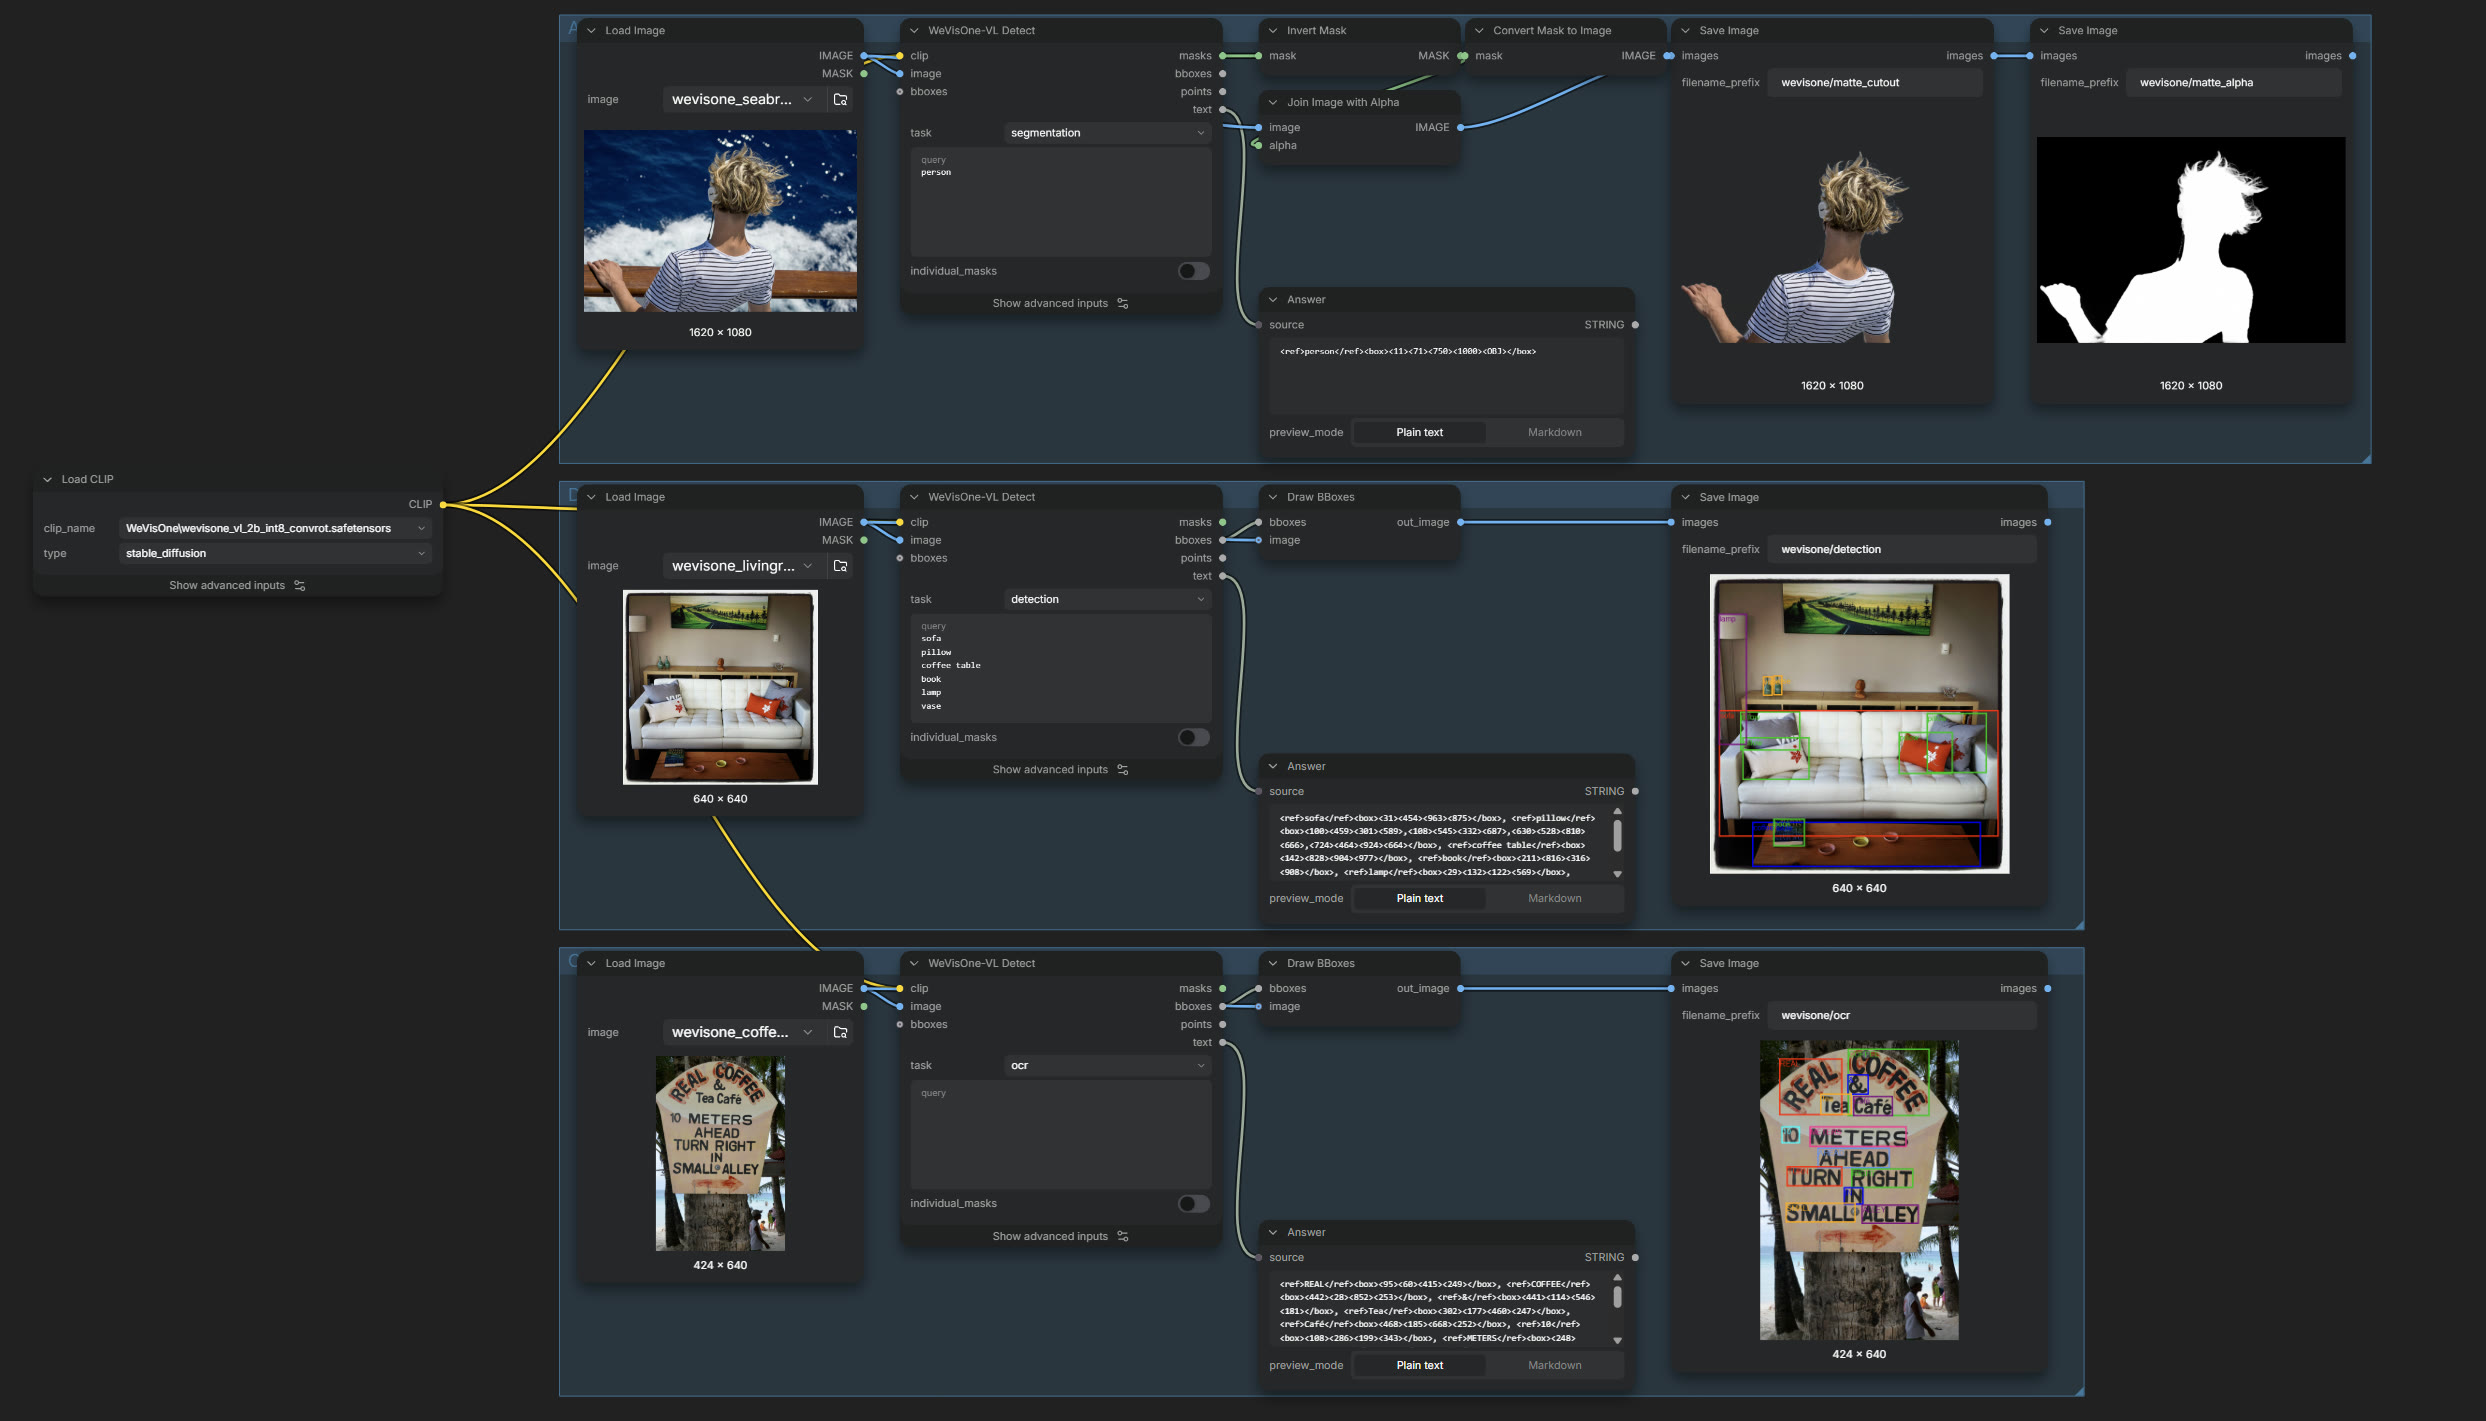
Alpha matting, detection and OCR in one graph. Source: PR 17632
How good is it
Headline numbers for the 4B model against the strongest open baseline in each benchmark:
| Task | Benchmark | Baseline | WeVisOne-VL-4B |
|---|---|---|---|
| Detection | LVIS, F1 | 50.7 | 55.3 |
| Rejection of absent targets | WeRef-Bench | 73.0 | 96.4 |
| OCR | TotalText, F1 | 43.3 | 52.0 |
| Referring segmentation | ReasonSeg, gIoU | 65.0 | 71.2 |
| Box matting | P3M-500-NP, MAD (lower is better) | 15.4 | 7.3 |
The rejection row is the one that matters in a graph: ask for something that is not in the frame and the model writes None instead of inventing a box.
Limits
- Single images only. The pixel decoder rejects video grids, so this is not a tracking node.
- Fine alpha edges still drift on heavy occlusion or transparent subjects, and the phrasing of the query changes results.
detectionandpointwant one label per line; a comma-separated list is read as one phrase.
Original weights: tencent/WeVisOne-VL-4B and 2B. The ComfyUI repack above is the one that loads.
Comments
Sign in with GitHub to join the discussion.