HyperFlow H3 Flash: 14B MiniMax H3 in 6 Steps on One GPU
Video Rebirth's HyperFlow H3 Flash compresses MiniMax H3 to 13.7B, samples in 4 to 8 steps at CFG 1, and runs from a 9.1 GB GGUF on a 24 GB GPU with stereo audio.
Q4_K_M GGUF is 9.1 GB, and the whole thing runs on a 24 GB GPU. Video Rebirth measures 12.7× over the H3 baseline on a single B200.
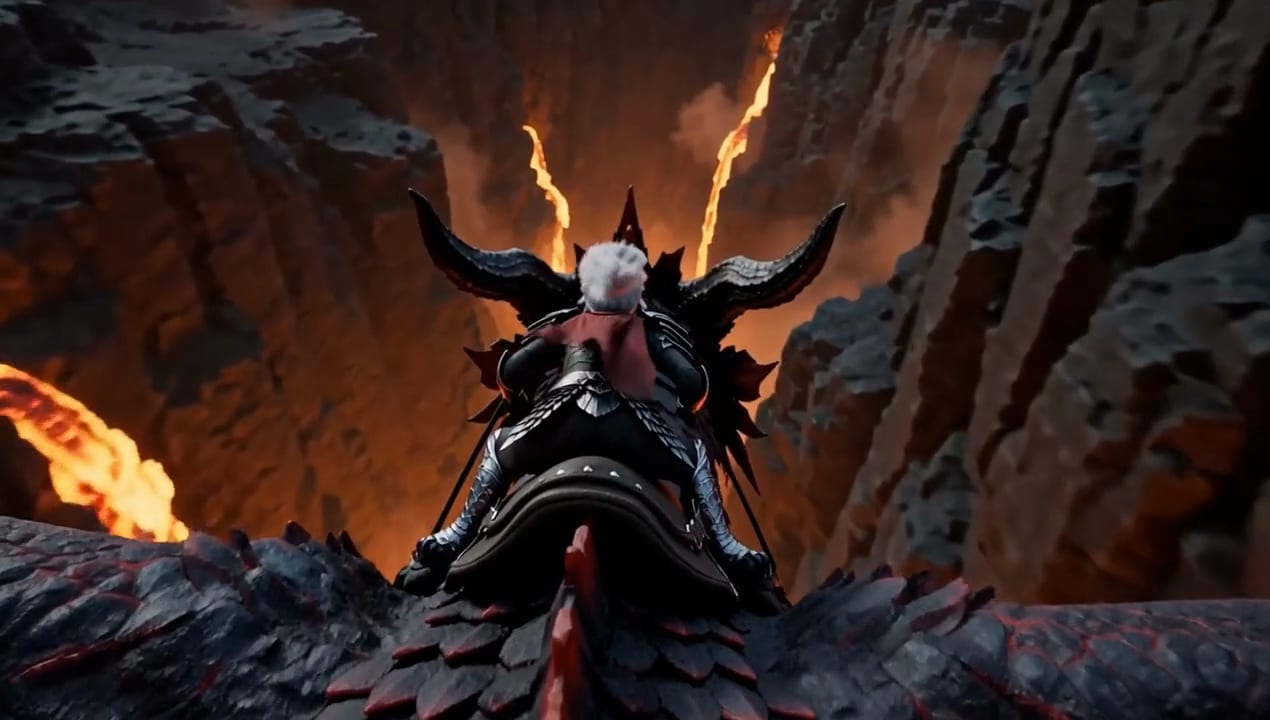
Full-quality output at 6 steps. Stills published with the release.
What changed
The small size comes from low-rank factorization of the base transformer, not from a new architecture. Everything else is H3: the same text encoder, video VAE, audio VAE and the native ComfyUI H3 nodes.
- Output: 5.2 to 15 s at 24 fps, 1344x768 by default, 32 kHz stereo soundtrack.
- Sampling:
euler, 4 steps for speed, 6 for the default, 8 for quality. No negative prompt: the model was trained at CFG 1. - Tasks: text to video, first frame, first and last frame, and reference to video with up to 9 images (12 in the Python path, which also takes video and audio references).
Sizes and speed
A 5.2 s clip at 6 steps, Video Rebirth's numbers:
| hardware | time |
|---|---|
| 4x B200 | 8.7 s |
| 1x H200 | 36 s |
| 1x RTX 5090 | 92 s |
| GGUF quant | fl2va | ref2va | when |
|---|---|---|---|
Q4_K_M | 9.1 GB | 9.2 GB | default for 24 GB GPUs |
Q8_0 | 14.9 GB | 15.2 GB | closest to full precision |
Q3_K_M | 7.2 GB | 7.4 GB | smallest |
The INT8 convrot build is about 16 GB per task and targets H100 and B200 class cards, or a 24 GB RTX card with plenty of system RAM.
Run it in ComfyUI
- Update ComfyUI to 0.43 or newer for
MiniMaxH3ImageToVideoandMiniMaxH3ReferenceToVideo. - Clone ComfyUI-GGUF and ComfyUI-HyperFlow-Flash into
custom_nodes/. - Put the GGUF in
models/diffusion_models/, and the 15.7 GBqwen3vl_32b_minimax_h3_nvfp4_awqtext encoder plus the video and audio VAEs from Comfy-Org/MiniMax-H3. - Open Workflow > Browse Templates > ComfyUI-HyperFlow-Flash. Four templates:
hyperflow_t2v,hyperflow_i2v,hyperflow_flf2v,hyperflow_ref2v.
On a 16 GB or 32 GB RAM machine, start ComfyUI with --fast-disk. The text encoder alone is 15.7 GB, so it is the RAM, not the VRAM, that usually runs out first.
The hyperflow_t2v template: HyperFlow GGUF Loader and HyperFlow Sigmas replace the H3 loader and scheduler.
Before you download
- LoRAs trained on the full H3 do not load. The compressed transformer has no layers to match them, so turbos and sliders from the 31B model are out.
- The speedup is smaller than the parameter count suggests. Kijai measured roughly 10% over the pruned full model in ComfyUI, because attention cost stays the same at this resolution. LukeG89 called it not worth it.
- 16 GB GPUs are not measured yet. The smallest tested footprint is 24 GB.
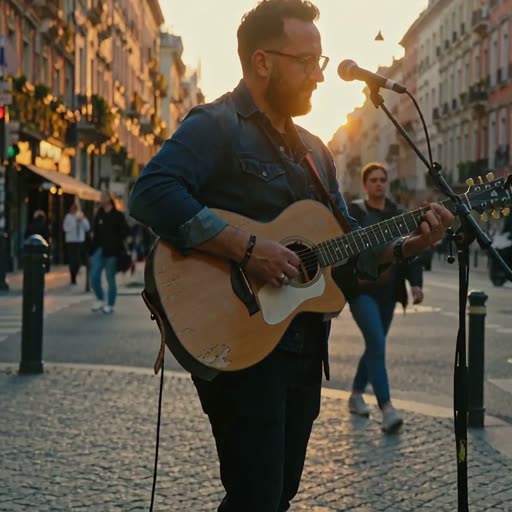
The consumer-GPU clip from the release page.
Availability
Weights: VideoRebirthAI/hyperflow-h3-flash (GGUF and INT8 convrot, v1.0.0, 2026-11-06). Code and ComfyUI nodes: Video-Rebirth/hyperflow-h3-flash and ComfyUI-HyperFlow-Flash. Showcase: videorebirth.com/lp/hyperflow-flash.
This is a Video Rebirth model, not a MiniMax release. It is separate from the HyperFlow 8-step LoRA, which still runs on the full 31B H3.
Comments
Sign in with GitHub to join the discussion.