NitroFusion2: Z-Image-Turbo at 1 Step, With ComfyUI Workflows
NitroFusion2 distills Z-Image-Turbo to one and two steps, ships native ComfyUI workflows and GGUF files from 2.0 GB, plus int8 files about 1.7x faster per step.
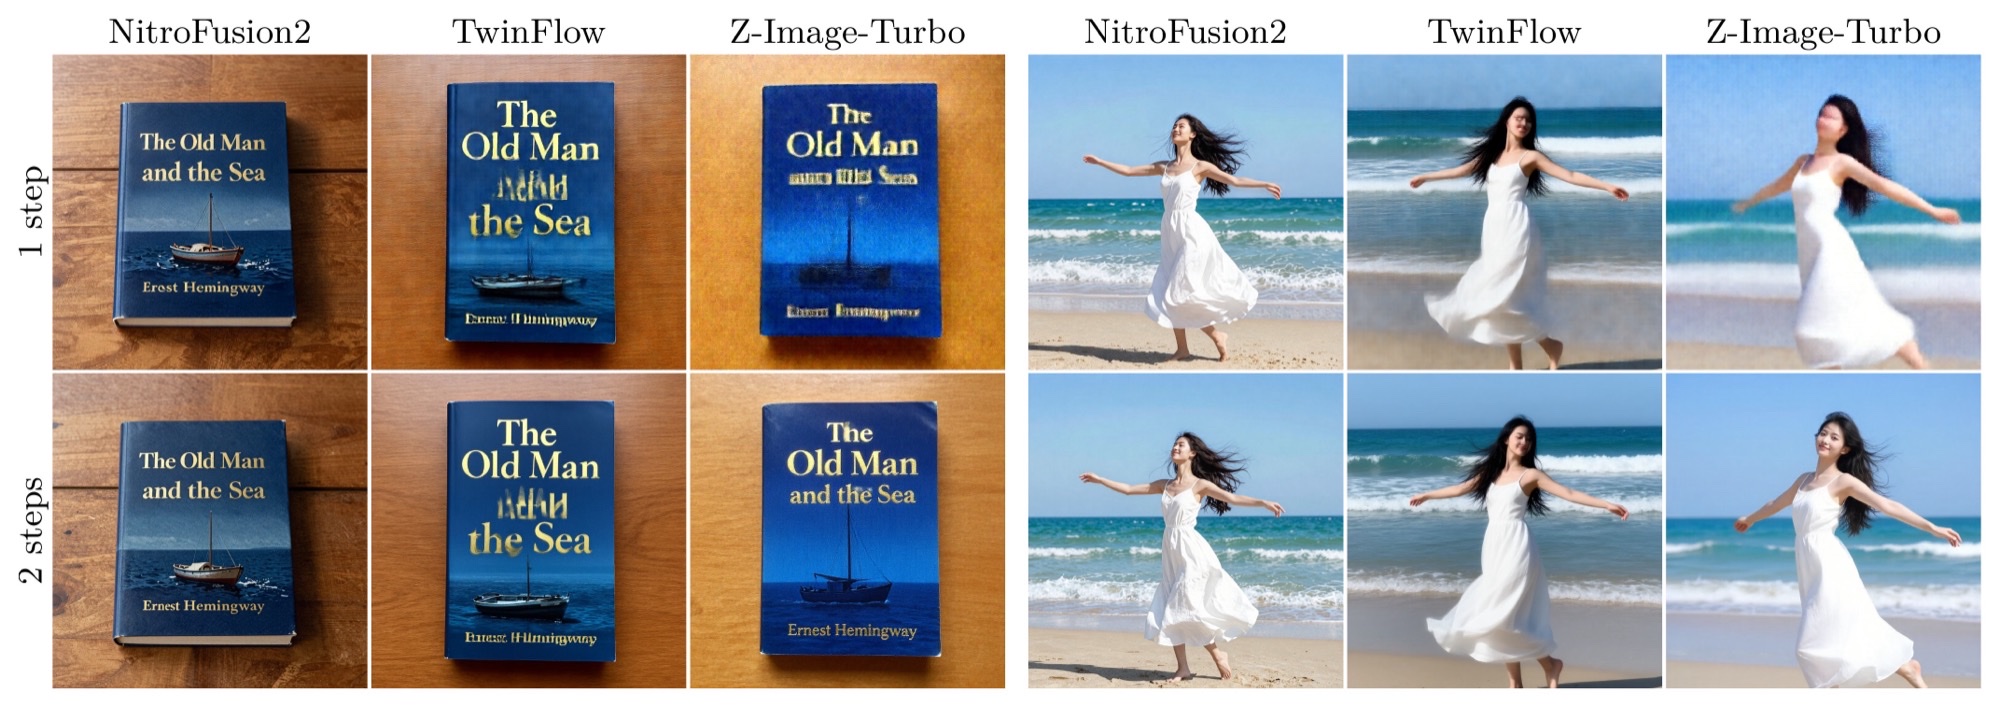
Same prompt and seed: Z-Image-Turbo against NitroFusion2 at one and two steps. From the model card.
What changed
The base model already runs in eight steps. NitroFusion2 pushes it to one by moving the adversarial loss onto the text stream of the MMDiT: by the middle of the network the text tokens have read the image and hold a summary of what was generated, so a discriminator trained there sees the prompt's own view of the picture. The practical effect is that typography and small detail survive a single step better than a plain step-count distillation usually manages.
Running it
Three files in ComfyUI's stock folders, then a workflow:
nf2-bf16.safetensors(12.31 GB) intomodels/diffusion_models/qwen_3_4b.safetensorsintomodels/text_encoders/, loaded aslumina2ae.safetensorsintomodels/vae/
One step runs on euler / simple, CFG 1, shift 3. Two steps switches to shift 6 and adds the de-distillation LoRA at 0.5 for the first step only, then 0.0 for the second; the official two-step workflow does that with two sampler passes.
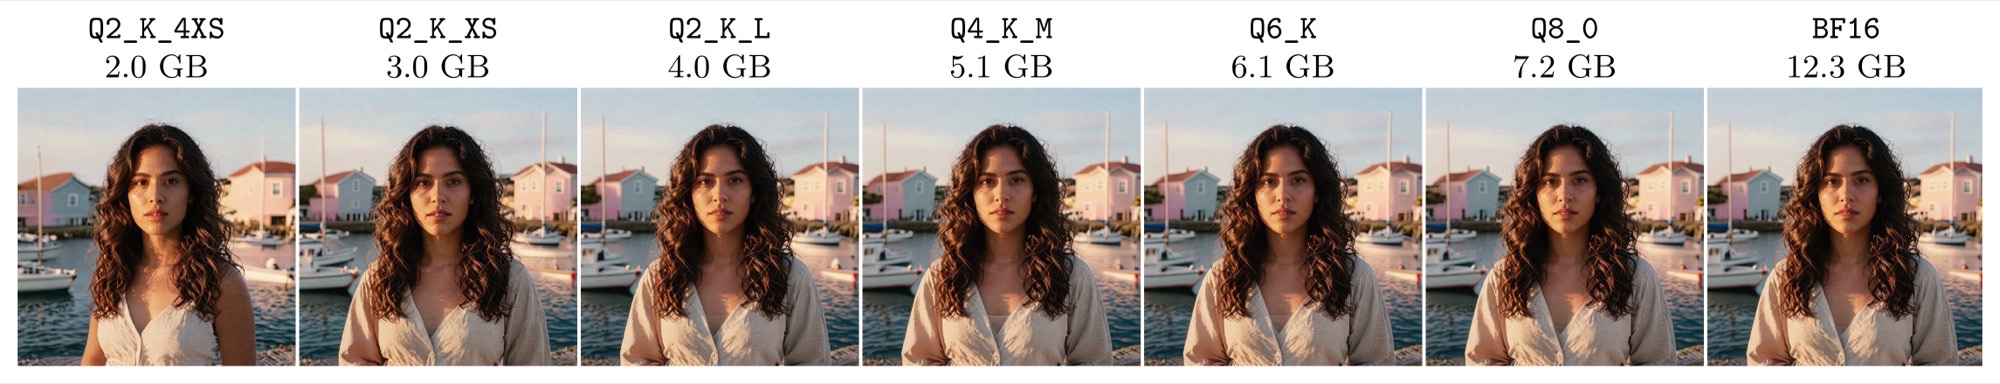
The published GGUF tiers on one prompt and seed, high to low precision. From the model card.
Smaller files
The repository carries GGUF from nf2-Q2_K_4XS (2.0 GB) to nf2-Q8_0 (7.2 GB), each with its own one and two step workflow on the model page. A third-party ComfyUI set adds ComfyUI-native quantizations of the same nf2-bf16 file, measured at 1024² on a 4090 (PedroMarinhoDev/NitroFusion2-ComfyUI):
| File | Size | 1 step, 4090 | Prediction error vs bf16 |
|---|---|---|---|
| bf16 | 12.31 GB | 0.50 s | 0 |
| int8 ConvRot | 6.18 GB | 0.29 s | 13.4% |
| W6A8 | 5.02 GB | 0.30 s | 17.5% |
| W4A8 | 3.49 GB | 0.29 s | 33.6% |
That error is relative to the bf16 prediction on 12 prompts x 4 noise samples, and the author says almost all of it lands in fine texture rather than composition, faces or text. Read it as a ranking between the three files, not as an absolute quality score.
Comments
Sign in with GitHub to join the discussion.