MOSS-Image Few-Step LoRAs: 4-Step rapid-moss and 8-Step DMD
Two community LoRAs cut MOSS-Image-SFT from 50 steps to 4 or 8 network evaluations, and the 4-step rapid-moss adapter ships a ComfyUI node with native workflows.
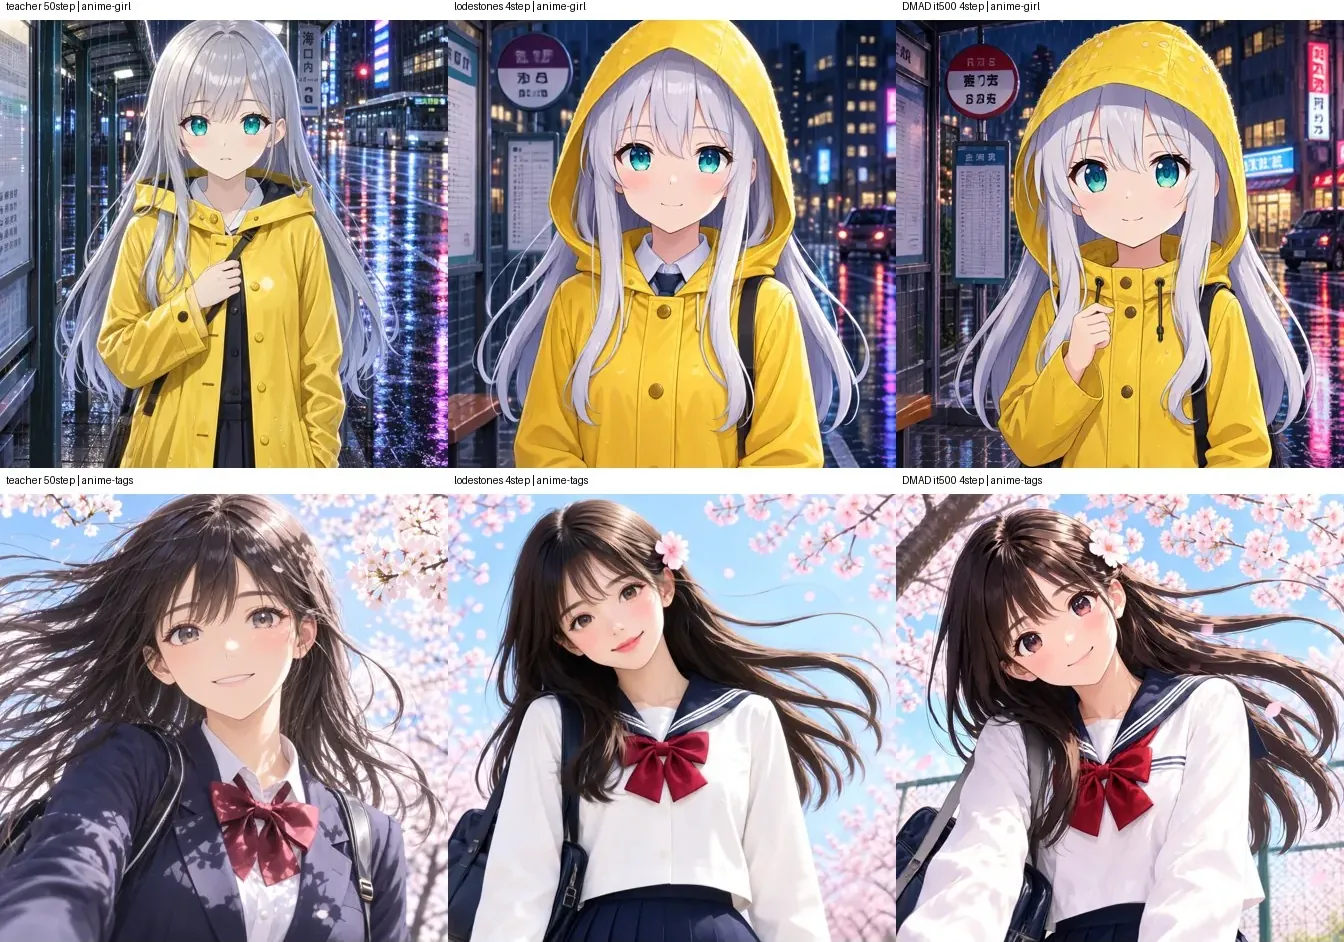
Left to right: the 50-step teacher, the 8-step checkpoint run for 4 steps, and the 4-step rapid-moss adapter. Same seed, evaluation prompts never used in training. Source: darask0
Why the sampling loop shrinks
MOSS-Image-SFT renders one image in 50 steps with CFG 3, and CFG doubles the forward pass, so a single picture costs about 100 DiT evaluations. The 8-step checkpoint replaces that loop with data-space DMD (arXiv 2610.12102): the generator iterates four to eight times on its own clean estimate from a fixed noise tensor, with no CFG and no timestep schedule.
The 4-step adapter continues from that checkpoint and restricts it to four iterations, trained with DMAD (arXiv 2610.02188). A LoRA critic on the frozen teacher separates teacher samples from student samples, and the student minimises the negative critic logit. The author trained on 3,199 prompts with one teacher sample each, and published the 500-iteration checkpoint before later iterations started to degrade prompt adherence.
DiT time per 1024² image on one H100:
| Checkpoint | DiT time | DiT evaluations |
|---|---|---|
| MOSS-Image-SFT (50 steps, CFG 3) | 16.2 s | 100 |
| lodestones 8-step DMD | 1.54 s | 8 |
| rapid-moss 4-step DMAD | 0.81 s | 4 |
The timings cover the transformer only, not the Qwen3.5-9B text encoder or the VAE. Inside ComfyUI on an RTX PRO 6000, the author measured 4.5 to 6.9 seconds for a 1024² image with text encoding and decoding included.
The ComfyUI node
Both adapters are fp32 LoRA deltas whose magnitude is smaller than bf16's rounding step, so merging them into bf16 weights wipes out most of the distillation. That rules out LoraLoaderModelOnly, diffusers fuse_lora, and any workflow that loads pre-merged weights. The bundled MOSS-Image Few-Step Adapter (rapid-moss) node instead adds the LoRA in fp32 at runtime, replaces the fp32 time path, and returns a matched MODEL, SAMPLER and SIGMAS triple.
The outputs have to be wired together as a set: MODEL into BasicGuider with no CFG, then SAMPLER and SIGMAS into SamplerCustomAdvanced, then VAE Decode. Euler, sgm_uniform, ModelSamplingSD3 with shift 5 and layer 22 skipping are all settings for the 50-step teacher and should not be added here. Steps run from 1 to 4 for rapid-moss and 1 to 8 for the 8-step checkpoint, and strength 1.0 is the recommended default.
Two workflows are included. The native one uses standard ComfyUI loaders: moss_image_sft_bf16.safetensors from Comfy-Org/MOSS-Image, CLIPLoader with type moss_image, and the FLUX.2 VAE.
The second workflow keeps OpenMOSS's own moss-image HF Loader node and points it at a local Diffusers directory:
comfyui/rapid-moss/ from the model repository into ComfyUI/custom_nodes/rapid-moss/ and restart.
2. Put lora.safetensors, time_embedding.safetensors and dataspace.safetensors in ComfyUI/models/rapid_moss/rapid-moss-4step/. Each subfolder under models/rapid_moss/ becomes an entry in the node's adapter menu, so the 8-step files go in a second folder.
3. Load a workflow, pick the adapter and set the base diffusion model to the SFT weights in bf16 or fp32.
Side-by-side results
Across 17 evaluation prompts, the author reports more background detail and livelier composition than the 8-step checkpoint run for four steps, plus a fix for a doubled "夏" on a vertical poster, with Japanese text on sticky notes, signs and speech bubbles staying accurate.
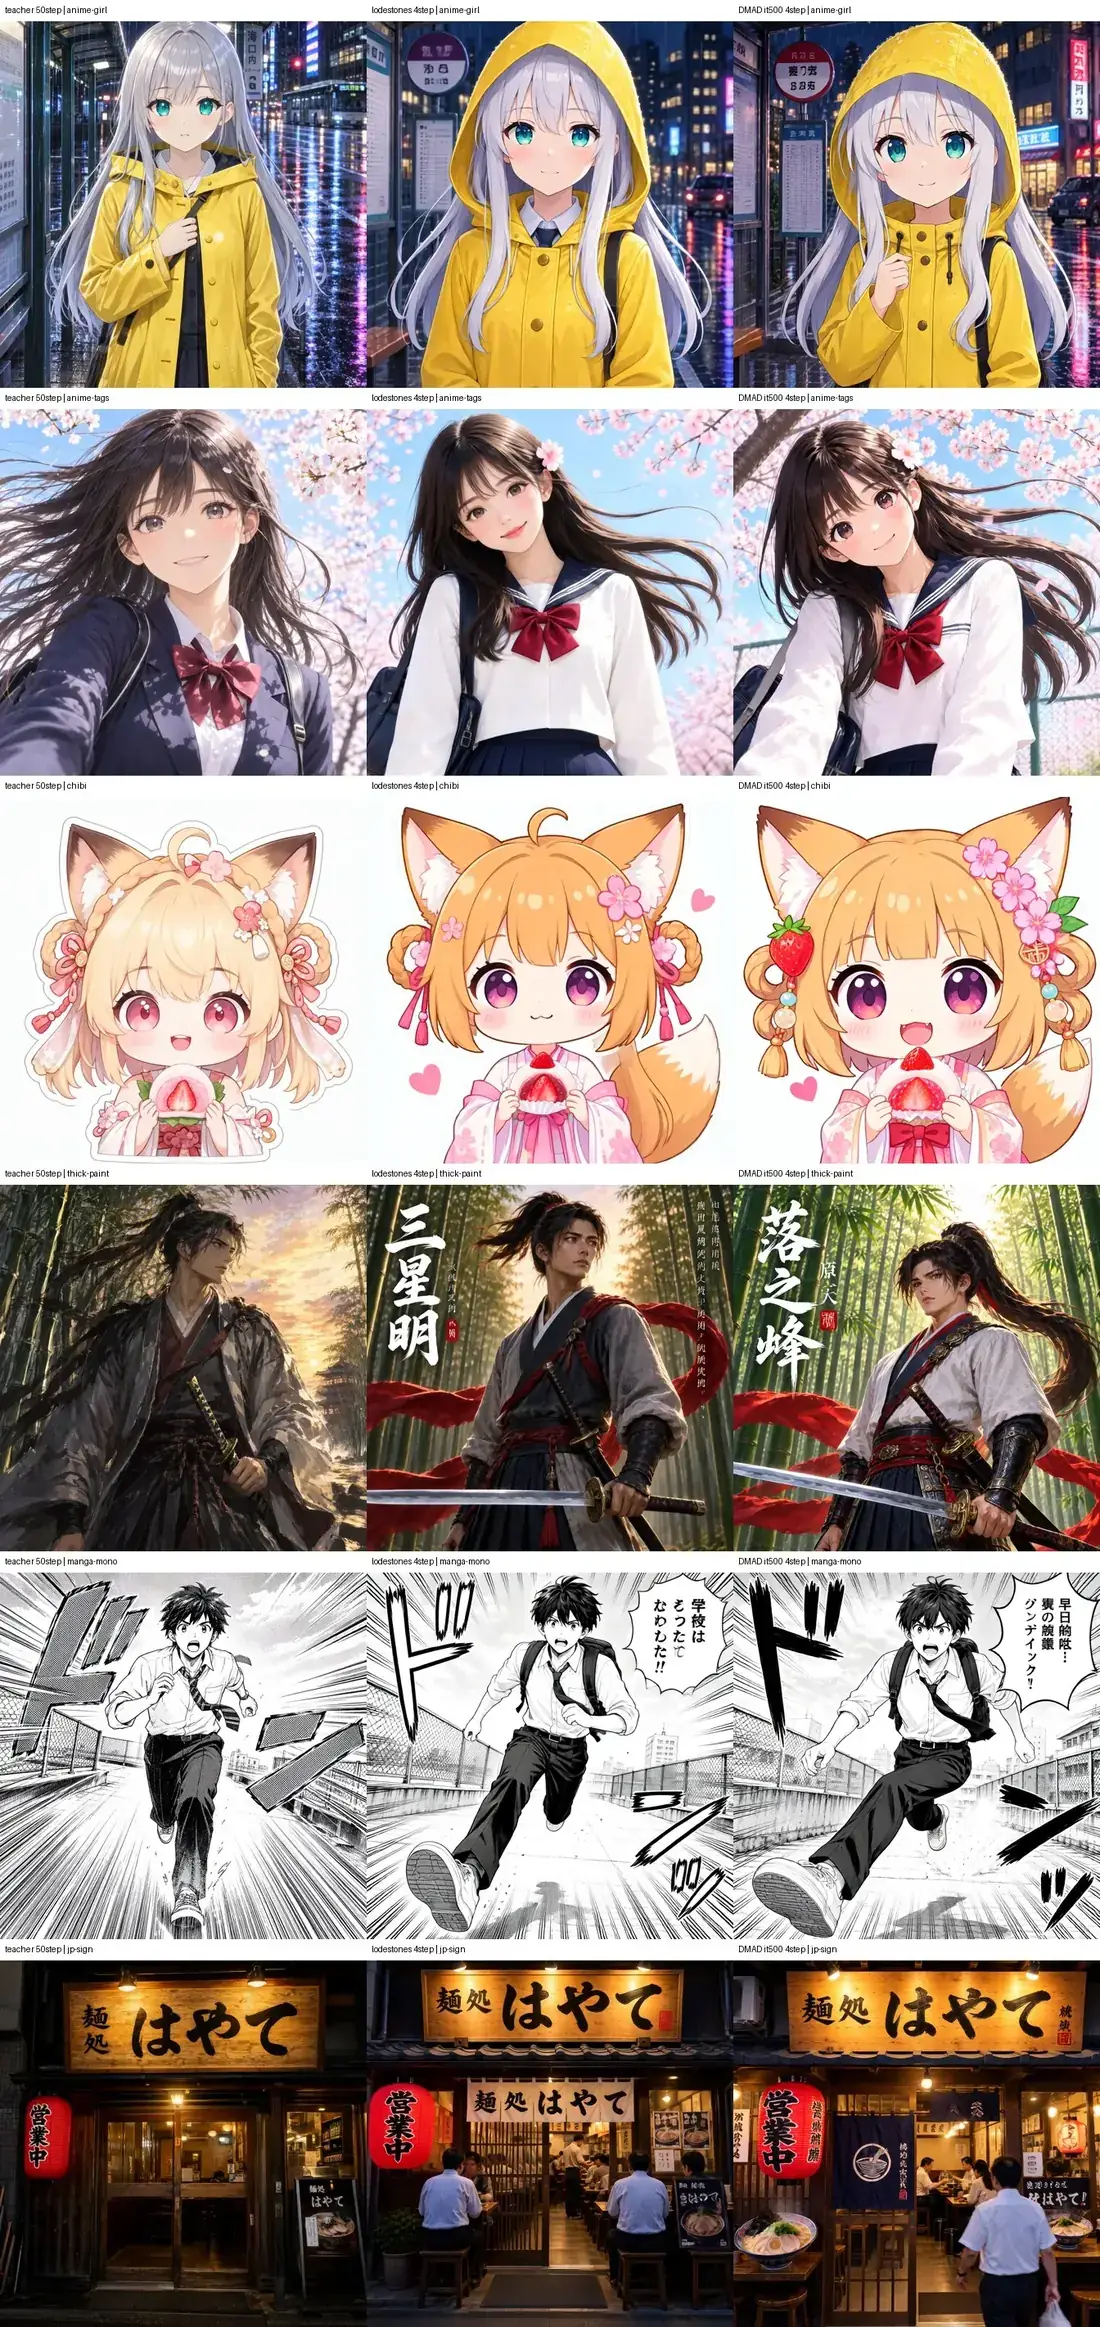
Teacher, 8-step checkpoint at 4 steps, and the 4-step adapter. Source: darask0
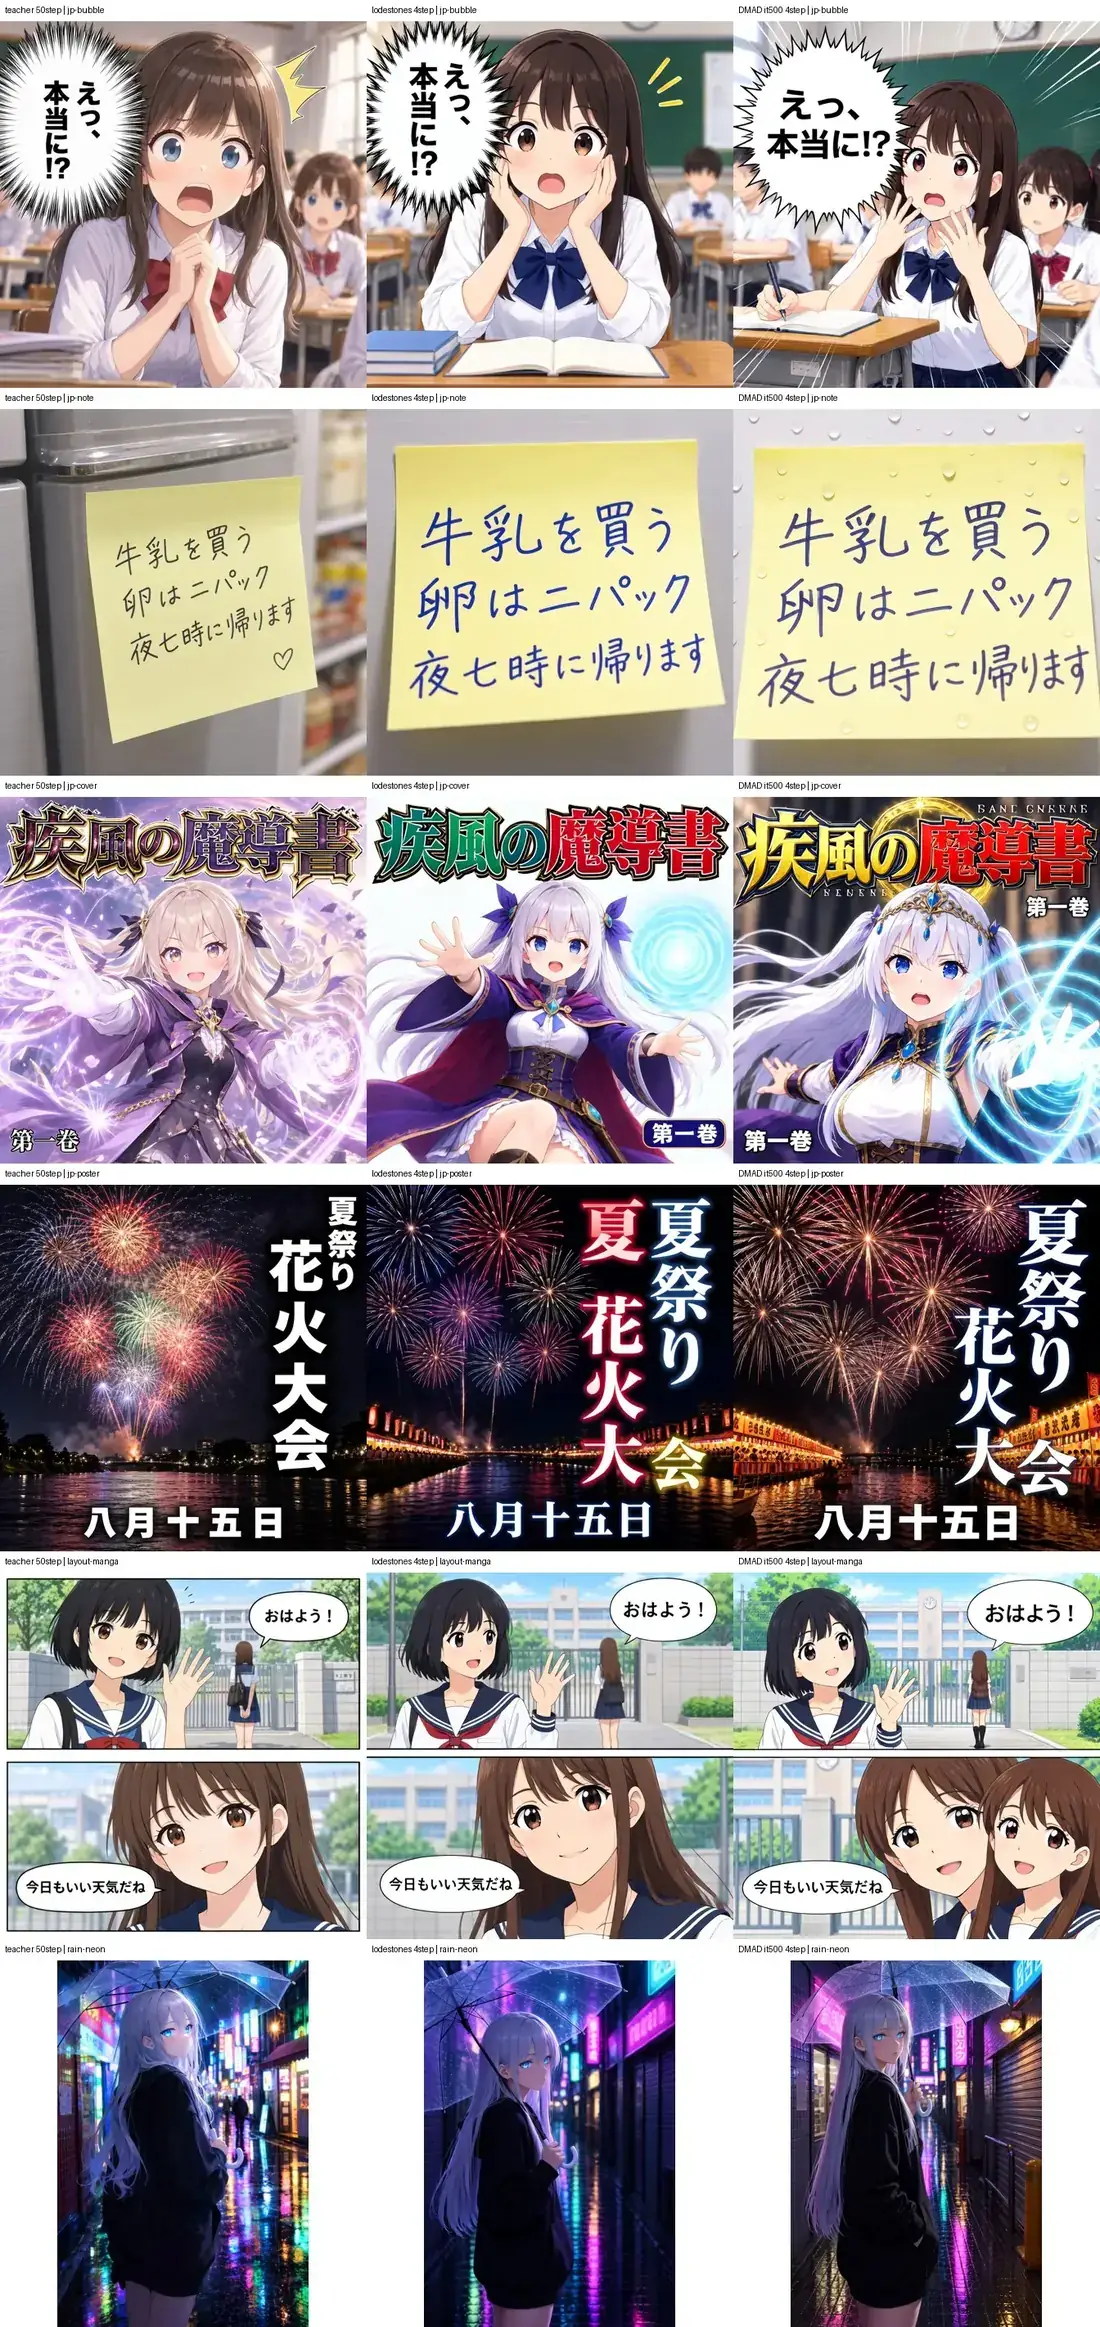
The same three-way comparison on a second prompt. Source: darask0
The author also lists the regressions instead of smoothing them over: stray Latin lettering appears on light-novel covers, a JSON layout request for a two-panel manga added an unrequested second person in the lower panel, and small text on shop curtains and manga bubbles still fails. Quality stays below the 50-step teacher.
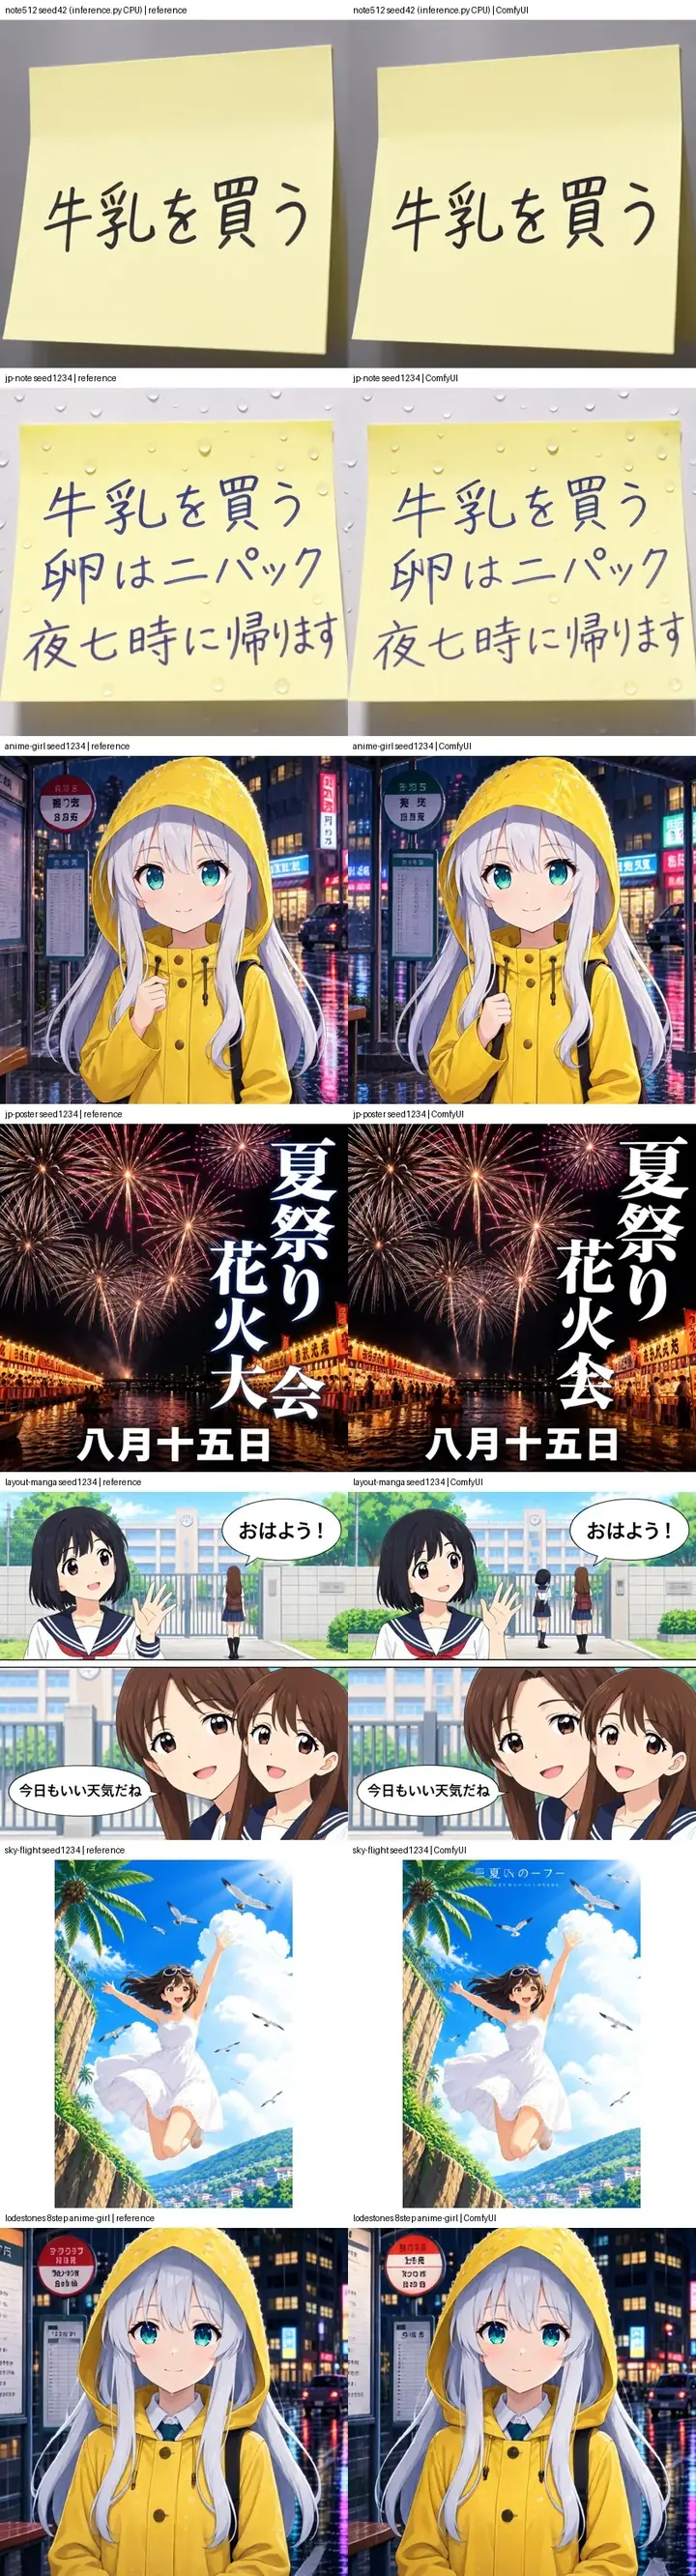
The rapid-moss node inside ComfyUI, with the fp32 adapter wired into BasicGuider and SamplerCustomAdvanced. Source: darask0
The 8-step checkpoint on its own
lodestones published the earlier 8-step checkpoint on October 16 as a work in progress. It is files-only: lora.safetensors at strength 1.0, or lora_latest.safetensors at 0.7, plus the same time_embedding.safetensors and dataspace.safetensors. Its own card points at the standard ComfyUI LoRA loader for the 8-step weights, while the rapid-moss node can drive both adapters with the fp32 path that the 4-step delta needs.
For anyone running the adapters outside ComfyUI, inference.py in the 4-step repository reproduces the sampler directly: keep the initial noise tensor fixed, mix it with the current estimate through the 128x128 matrix in dataspace.safetensors, and read the step codes from the same file.
Availability
- 4-step adapter: darask0/MOSS-Image_4-step_adapter_lora with training code, logs, evaluation prompts and the ComfyUI node.
- 8-step checkpoint: lodestones/MOSS-Image-SFT-8-steps-dmd with a public demo Space.
- Base model: OpenMOSS-Team/MOSS-Image-SFT and the ComfyUI repack in Comfy-Org/MOSS-Image.
Comments
Sign in with GitHub to join the discussion.