ComfyUI-Drama3: Fish Audio Drama 3 Runs Locally on 8 GB Cards
ComfyUI-Drama3 is a node pack that runs Fish Audio Drama 3 inside ComfyUI from 8 GB of VRAM, with voice cloning, 16-speaker dialogue, inline cues and Qwen3-ASR.
ComfyUI-Drama3: Drama 3 and Qwen3-ASR as ComfyUI nodes, no extra packages to install.
Drama 3 is a 35B mixture-of-experts text-to-speech model with 3B parameters active per token. Fish Audio's own package is eight safetensors shards plus a codec, roughly 40 GB on disk, and the ComfyUI partner node reaches it over the API. This pack is the local route: it loads the released checkpoints itself, generates audio codes inside ComfyUI, and decodes them to 44.1 kHz on the same graph.
A 35B model on an 8 GB card
Drama 3 is a Qwen3.5-style mixture of experts: 40 layers, each with 256 routed experts of which 8 run per audio frame, plus attention or DeltaNet, a shared expert and a 13-layer codebook decoder. Everything except the routed experts is about 6 GB and stays on the GPU. With experts in RAM, the 32 GB of expert weights sit in pinned system memory: each frame copies the eight experts per layer it needs, and a least-recently-used cache in the VRAM that is left free keeps the ones that come back, with 85 to 95 percent of reads hitting a 13 GB cache.
The pack ships four builds of the checkpoint and lets you pick per machine:
| File | Size | Experts | RAM with experts in RAM |
|---|---|---|---|
drama3_fp8experts_bf16 | 38.6 GB | FP8, as Fish Audio ships them | ~48 GB |
drama3_int8experts_bf16 | 38.7 GB | int8 ConvRot | ~48 GB |
drama3_w6a8experts_bf16 | 32.7 GB | W6A8 | ~40 GB |
drama3_w4a8experts_bf16 | 24.6 GB | W4A8 | ~32 GB |
FP8 keeps Fish Audio's own expert weights byte for byte. int8 is the same size and ran 14 to 17 percent faster on an RTX 3090, because int8 experts run as int8 while FP8 experts are turned into bf16 on every pass. Smaller files are for machines short of the FP8 file's ~48 GB of RAM. A second GPU can take the expert weights when experts is set to VRAM instead of RAM.
Voices, dialogue and cues
The pack keeps to Drama 3's own prompt syntax, the same one the technical report documents:
| Control | How to write it | Example |
|---|---|---|
| Speaker | <|speaker:N|> at the start of a line, N from 0 to 15 | <|speaker:0|> Ready? |
| Point tag | [tag] where the sound should land | Well [sighs] fine, you win. |
| Scoped tag | <tag>...</tag> around the words it shapes | Promise me <whisper>you won't tell her</whisper>. |
| Style prefix | [style] at the start of a line | [with bright eager excitement] We won! |
| Director's note | Direction: then Line: on the next line | Direction: icy calm. |
| Language hint | [language: xx] after a line, not spoken | Welcome back. [language: en] |
Up to 16 speakers can share one text, and each one gets a voice slot. Long text is cut into chunks of about 300 bytes without splitting a tag. Take generation has four modes: one take per line, one take per line that hears the line before, one take per speaker, or the whole script together so every line hears the others. Decode joins separate takes with 0.3 seconds of silence and can shorten long pauses.
A voice is encoded once from a clip plus its transcript and can then be saved as a few-kilobyte file in output/drama3_voices, so later runs need neither the clip nor the codec. Generated takes can be saved the same way in output/drama3_codes and re-decoded or edited without generating again.
Transcribing and editing takes
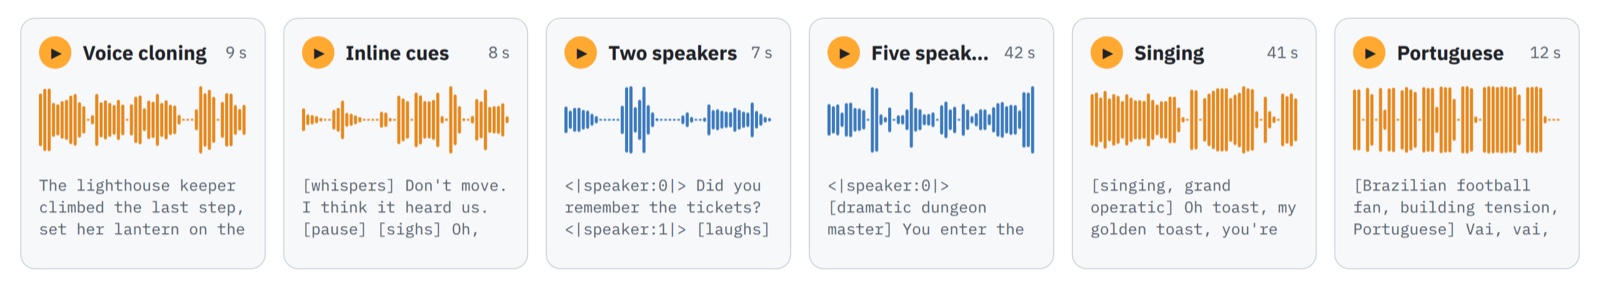
Six samples from the pack's samples page: cloning, cues, a two-speaker scene, a five-speaker scene, singing and Portuguese. Each was generated on an RTX 3090 or RTX 4090 with the FP8 build.
Voice cloning starts with a transcript, and the pack supplies one: Load Qwen3-ASR plus Qwen3-ASR Transcribe run a 1.7B or 0.6B speech recognition model, and a forced aligner, in 30 languages with no extra packages. On an RTX 3090 a 6.6 second clip transcribes in about 2 seconds with the 1.7B model and about a second with the 0.6B, model load included. The same aligner feeds Drama 3 Editor, which opens over the ComfyUI canvas: captions follow the voice word by word, one track per voice, and the editor cuts, adds silence, names voices and sets their volume. Pressing Use these edits runs the node again with them, and they stay in the workflow.
Speed
Drama 3 makes 21.5 audio frames per second of speech, so 46 ms per frame is real time. Decoding one frame at a time is CPU-bound, since a single core launches many small GPU kernels, so the expert cache size moves the speed less than expected. Measured with a cloned voice and about 9 seconds of speech on an Intel Core i9-14900K, prompt pass included:
| GPU | File | Expert cache | ms per frame | Peak VRAM |
|---|---|---|---|---|
| RTX 4090 | W4A8 | 16 GB | 52 | 21.3 GB |
| RTX 4090 | W4A8 | 4 GB | 67 | 11.7 GB |
| RTX 4090 | int8 | 16 GB | 69 | 21.5 GB |
| RTX 3090 | int8 | 16 GB | 69 | 21.6 GB |
| RTX 3090 | FP8 | 16 GB | 84 | 21.6 GB |
| RTX 3090 | FP8 | 4 GB | 119 | 11.9 GB |
| RTX 3090 held to 12 GB | FP8 | automatic | 137 | 9.8 GB |
| RTX 3090 held to 8 GB | FP8 | automatic | 214 | 6.5 GB |
The last two rows ran with the rest of the 3090's memory taken by another process, standing in for a 12 GB or 8 GB card. The author also warns that Fish Audio's server sends top_k 30, which makes takes go silent at pauses, so the nodes default to the Space's own settings of temperature 1.0, top_p 0.9 and no top_k cap.
Getting started
ComfyUI/custom_nodes/ and restart ComfyUI. Nothing needs pip install: the nodes use only what ComfyUI already ships.
cd ComfyUI/custom_nodes
git clone https://github.com/PedroMarinhoDev/ComfyUI-Drama3
Download the weights
The checkpoints go to models/diffusion_models, the codec to models/vae, and the ASR and aligner files to models/asr:
hf download PedroMarinhoDev/Drama-3-ComfyUI drama3_fp8experts_bf16.safetensors --local-dir ComfyUI/models/diffusion_models
hf download PedroMarinhoDev/Drama-3-ComfyUI drama3_codec.safetensors --local-dir ComfyUI/models/vae
hf download PedroMarinhoDev/Qwen3-ASR-ComfyUI qwen3_asr_0.6b_bf16.safetensors --local-dir ComfyUI/models/asr
Run a workflow
Drag an example workflow into ComfyUI, pick a few seconds of clean speech in Load Audio, write the text in Drama 3 Generate and queue.
Availability
Node pack: PedroMarinhoDev/ComfyUI-Drama3
Weights: PedroMarinhoDev/Drama-3-ComfyUI · PedroMarinhoDev/Qwen3-ASR-ComfyUI
Samples: pedromarinhodev.github.io/ComfyUI-Drama3
Base model: fishaudio/drama-3 · the Drama 3 news
Comments
Sign in with GitHub to join the discussion.