LightX2V Lightning: 4-Step LoRA for Qwen-Image 2.1
LightX2V publishes a 4-step DMD-distilled Lightning LoRA for Qwen-Image 2.1, covering text-to-image and multi-reference editing with side-by-side samples.
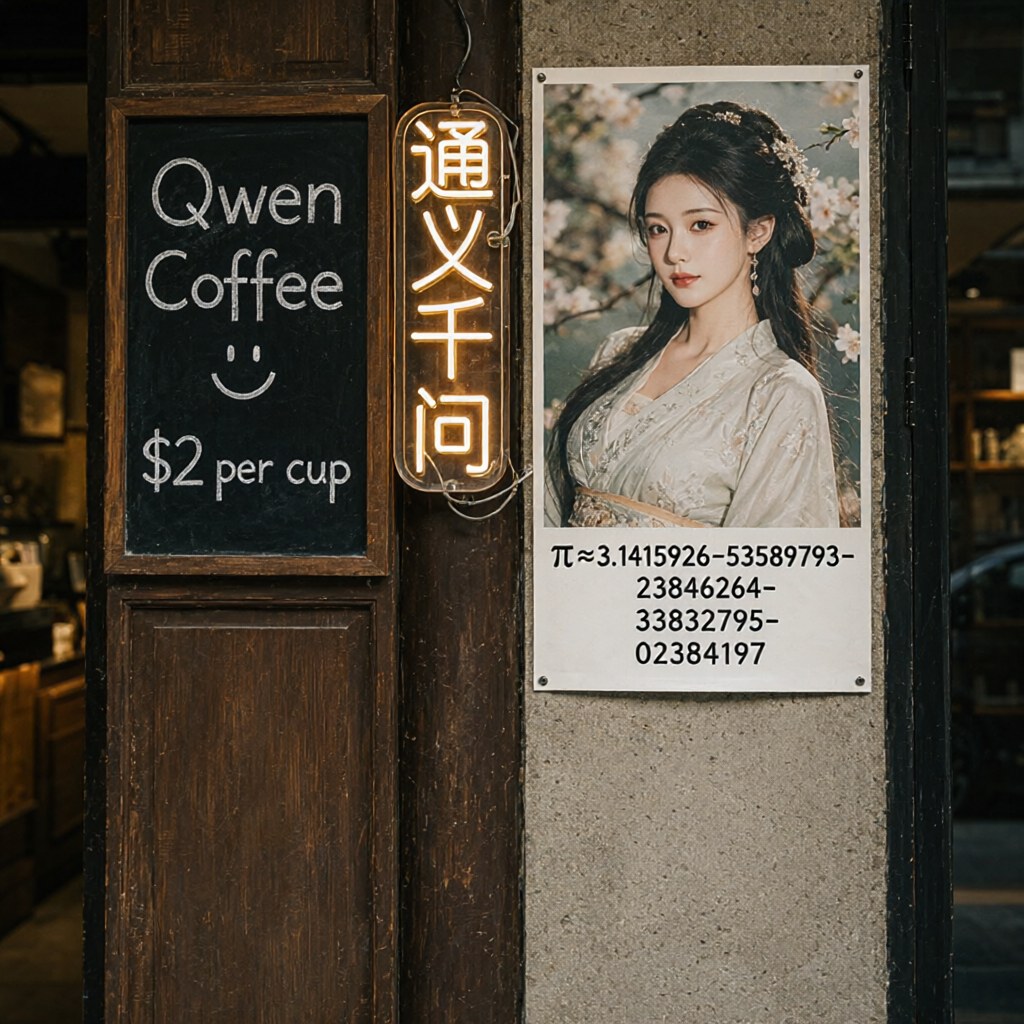
Coffee shop storefront generated by the Lightning LoRA in 4 steps, with the base model's fixed text embeddings and the same seed.
What the LoRA changes
Qwen-Image 2.1 generates at 40 steps by default. The Lightning adapter collapses that to four, with the schedule written directly into the sampler call:
pipe.scheduler = FlowMatchEulerDiscreteScheduler.from_config(
    pipe.scheduler.config, shift_terminal=None
)

image = pipe(
    prompt=prompt,
    width=1024,
    height=1024,
    num_inference_steps=4,
    sigmas=[1.0, 0.75, 0.5, 0.25],
    true_cfg_scale=1.0,
    use_kv_cache=False,
).images[0]
CFG is disabled (true_cfg_scale=1.0) and the four sigma values are fixed, so the only thing that changes from a normal Qwen-Image 2.1 workflow is loading the LoRA and switching the sampler to a 4-step, CFG-free configuration.
Four steps against forty
The model card ships five text-to-image comparisons using the same prompts, seeds and output sizes, with CFG disabled for both sides. The base-model images are from an earlier 40-step run.
| Base model, 40 steps | Lightning LoRA, 4 steps |
|---|---|
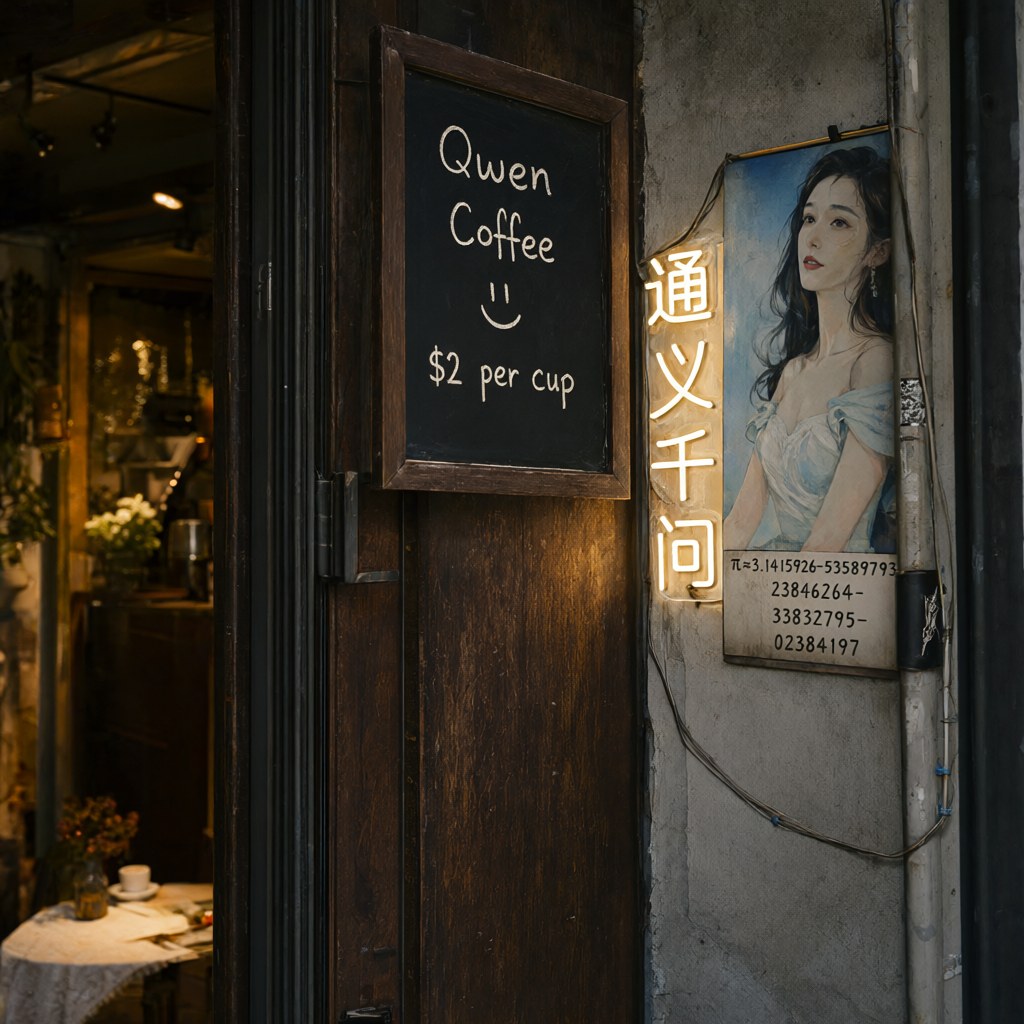 | |
| Coffee shop signage | Coffee shop signage |
The remaining examples in the repository cover a nine-headed fox beast, a sheep designer toy, an office cow selfie and a floral wine advertisement.
Editing with multiple references
The same adapter is trained for the editing pipeline, including multi-reference inputs. In the first example the target is the person's jacket:
| Reference | Base model, 40 steps | Lightning LoRA, 4 steps |
|---|---|---|
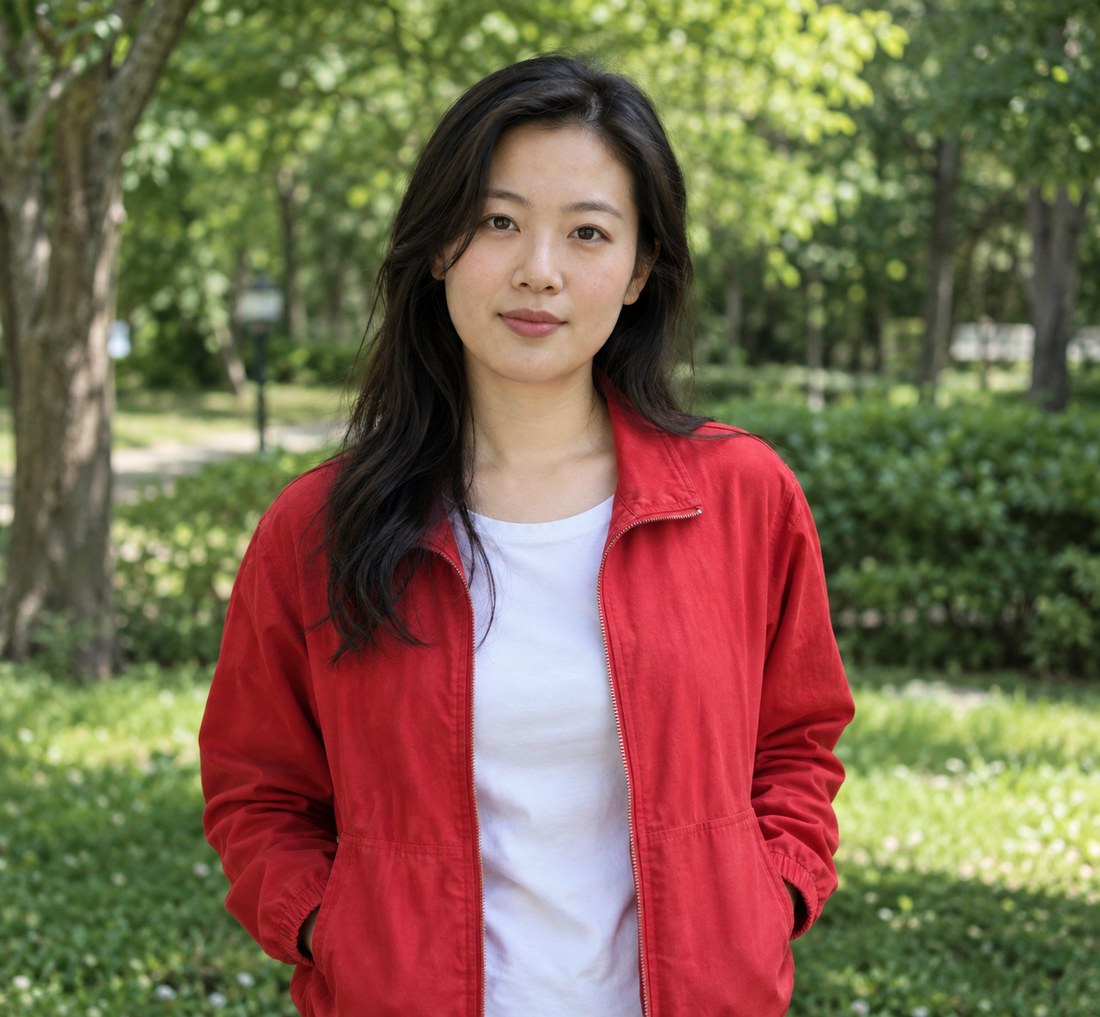 | 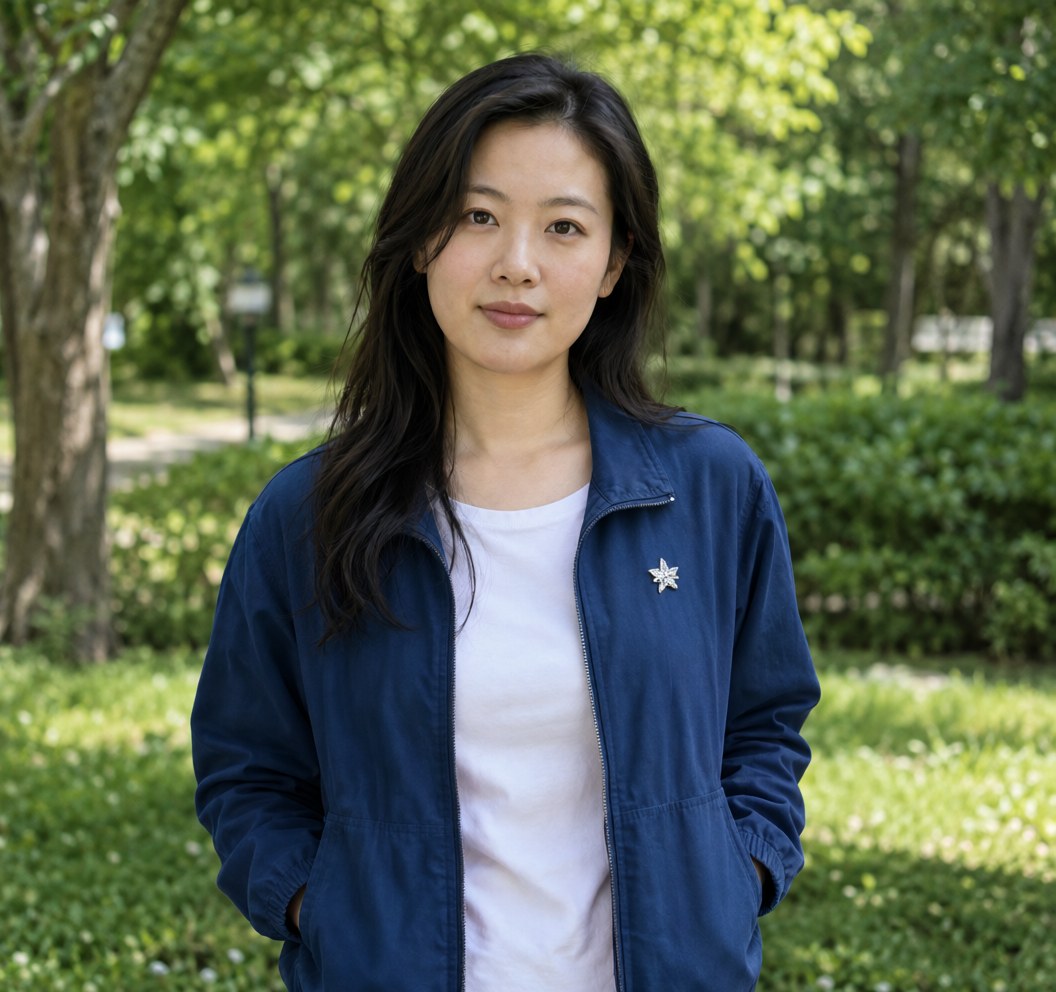 | 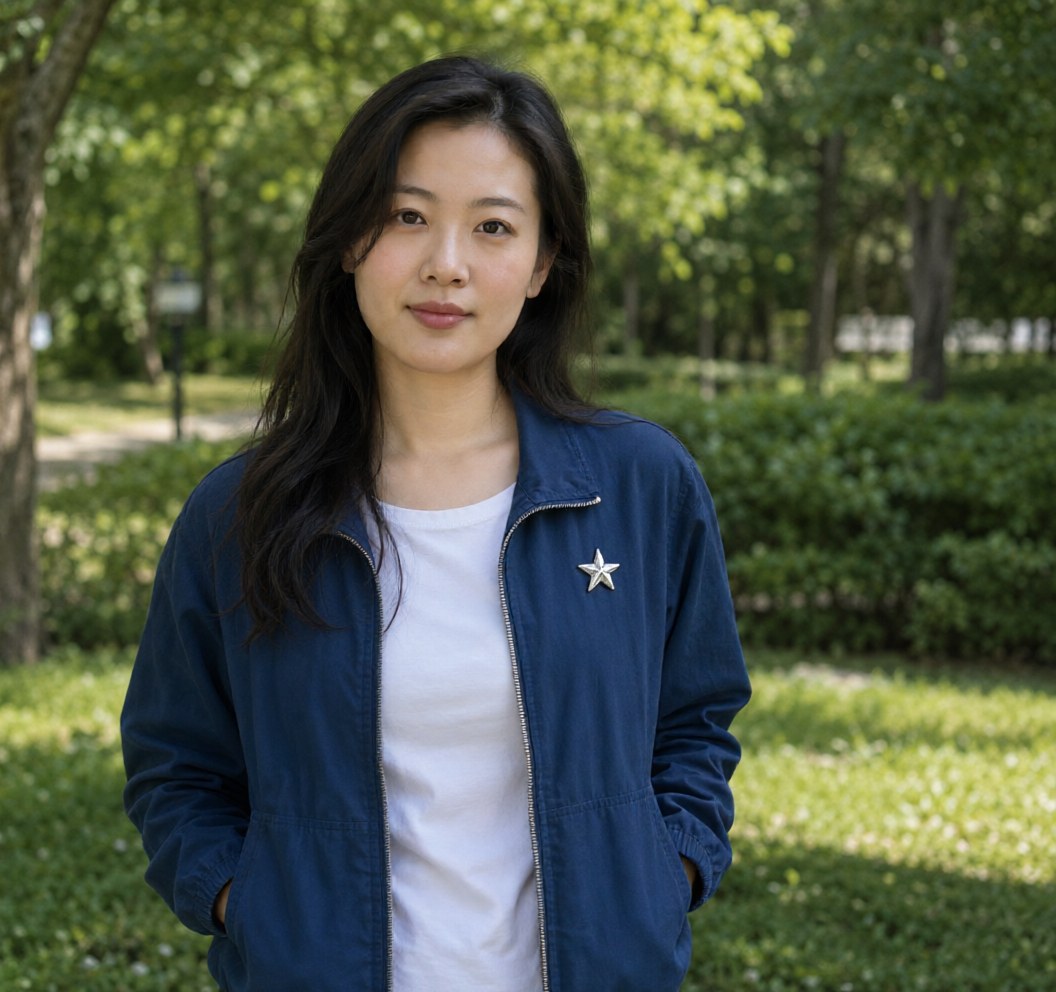 |
"Change the red jacket to dark blue and add a small silver star-shaped brooch on the left chest. Keep the person's identity, expression, hairstyle, pose, jacket material and folds; keep the background and lighting unchanged. …"
Seven further editing examples are in the model card, covering outfit and night scene, person and cat, product advertisement, sofa and pendant lamp, floor material transfer, mirror reflection and backpack try-on. Each one lists its reference images next to the 40-step and 4-step results.
Using it
The weights are a single pytorch_lora_weights.safetensors (67 MB) that loads on top of the Qwen-Image 2.1 checkpoint, so ComfyUI picks it up through the usual LoRA loader for the Qwen-Image 2.1 graph, set to 4 steps at CFG 1. LightX2V's own platform scripts cover non-NVIDIA hardware, including the Ascend NPUs the adapter was trained on.
Availability
LoRA weights: lightx2v/Qwen-Image-2.1-Lightning on Hugging Face. Base model: Qwen/Qwen-Image-2.1. Inference framework: ModelTC/LightX2V.
Comments
Sign in with GitHub to join the discussion.