Prism: 2K Joint Video and Audio Generation at 2.5x Training Speed
Prism from Fudan, Tencent Hunyuan and ZJU trains joint 2K video-audio models with dynamic sparse attention, 2.5x faster than full attention, with preview weights.
An example generation from the released preview checkpoint.
What Prism does
Native high resolution training is how joint video-audio models learn finer visual detail and sharper motion, but full attention grows quadratically with sequence length, and at 2K it spreads attention across a mass of redundant tokens. Prism keeps the resolution and changes the attention instead.
The method organizes the token sequence into spatiotemporal macro-zones. For every zone it estimates the local information structure from two signals:
- Video feature variance along the channel dimension, which shows how fast visual content varies in each direction.
- Feature norms from the audio-to-video cross-attention, which show how strongly audio influences each visual region.
Those signals decide a block shape per zone: finer partitioning along axes where visual content varies quickly or audio-visual coupling is strong, coarser partitioning elsewhere. The intent is that tokens inside a block stay semantically coherent, so block-level features carry both visual content and joint audio-video interaction. A hybrid block selection strategy (top-k combined with a top-p CDF threshold) then sets sparsity per query.
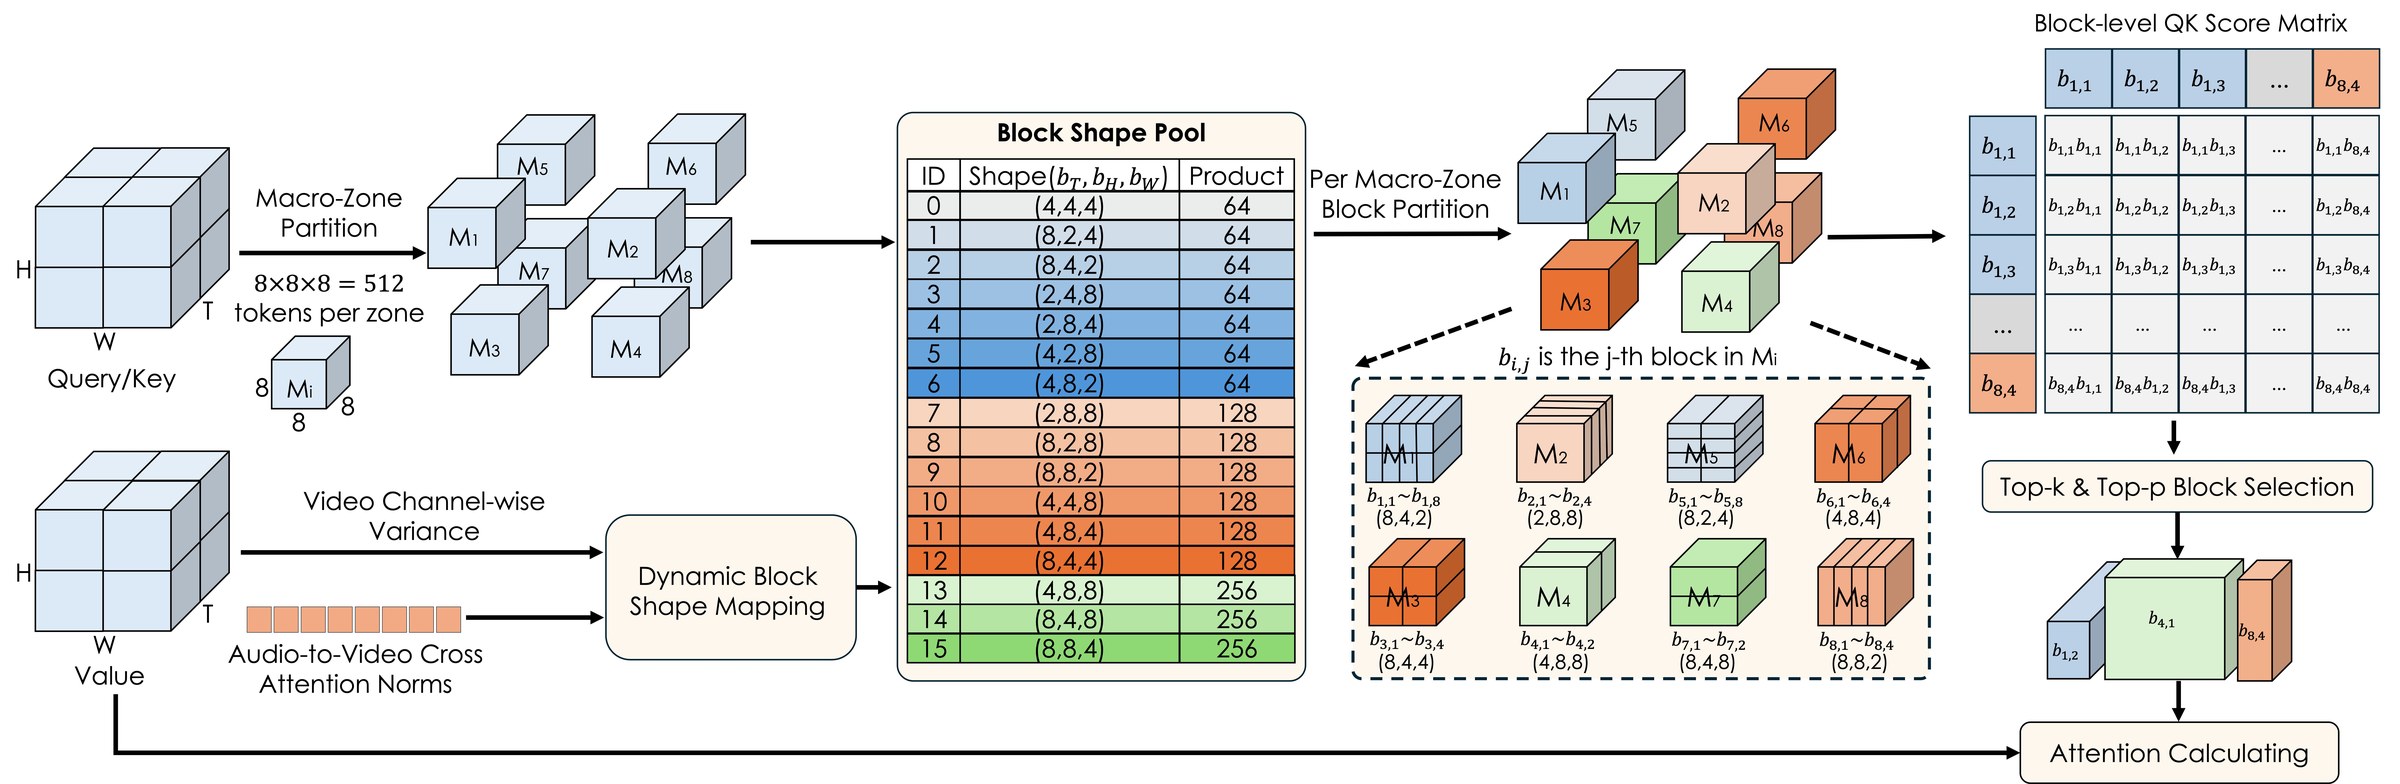
The Prism framework, from the official model card.
What was released
The project ships as a full training and inference stack rather than a single checkpoint:
- Preview checkpoints.
Prism-preview-alpha(stable) andPrism-preview-beta(motion), built on the MOVA architecture, with native joint video-audio generation at 720p, 1080p and 2K. - Code. Data pre-processing with latent extraction and decode, training, full fine-tuning and inference, plus distributed launch scripts for multi-node runs.
- Report. The technical report is on arXiv, linked from the model card and the repository.
Generations from the released preview checkpoint.
The released checkpoints also condition on a reference image for image-to-audio-video generation:
 |  |
|---|---|
| Official image-to-audio-video case input | Official image-to-audio-video case input |
A Prism-pro checkpoint is listed as the remaining item on the project's roadmap and has not been released yet.
Availability
The preview weights are on Hugging Face, with the code and scripts in Tencent-Hunyuan/Prism and the report on arXiv. Inference currently runs through the project's own PyTorch scripts; there is no ComfyUI node or packaged ComfyUI checkpoint yet, so running it locally means using the official repository directly.
Comments
Sign in with GitHub to join the discussion.