Kandinsky 6.0: Video and Audio Generation in ComfyUI
Kandinsky 6.0 open weights for ComfyUI: 29B Pro and 3B Lite generate 5-second video with synchronized 44 kHz audio, plus super resolution up to Full HD.
The official Kandinsky 6.0 promo.
What is new in Kandinsky 6.0
Kandinsky 6.0 Video is a family of foundation diffusion models that generate video and audio together instead of dubbing a soundtrack on afterwards. The lineup splits into two sizes:
- Kandinsky 6.0 Video Pro: 29B parameters, the flagship line.
- Kandinsky 6.0 Video Lite: 3B parameters, the compact line.
Each one ships in three forms: a base checkpoint, a distilled 10-step checkpoint for fast iterations, and a pretrained checkpoint. All of them generate 5-second clips at 24 fps with synchronized 44 kHz audio, covering dialogue, ambience and music, in two modes:
- Text-to-audio-video (T2AV): a single text prompt produces the clip and its soundtrack.
- Image-to-audio-video (TI2AV): a reference image conditions the first frame, and the prompt describes what happens next.
The architecture is a multimodal video and audio diffusion transformer (Kandinsky6Transformer3DModel) with a Qwen2.5-VL text encoder for token-level text embeddings and a CLIP pooled embedding, paired with a Hunyuan Video VAE for the visual side and an MMAudio VAE plus a BigVGAN-style vocoder for audio. Scheduling is flow matching with shift = 5.0.
Two inference switches are worth knowing. sample_audio=False generates video only, and expand_prompts=True lets the Qwen2.5-VL text encoder rewrite a short request into a detailed one before encoding, which adds latency but no extra weights.
Kandinsky 6.0 official showcase.
Super resolution to Full HD
Generation works at 480x864 in the examples above. A second pipeline, Kandinsky6SRPipeline, takes those frames and upscales them by x2, x2.25 or x4 with tiled diffusion in K-VAE latent space, blending overlapping tiles back together with Hann windows. The flow-matching checkpoint runs in 4 steps per tile, and the distilled VSR checkpoint cuts that to 2.
One of the official sample clips.
Kandinsky 6.0 in ComfyUI
Kandinsky Lab publishes a first-party ComfyUI extension alongside the weights. It is installed from the ComfyUI Registry as two packages, kandinsky6 and kandinsky6-sr, and requires ComfyUI 0.38.0 or newer with Python 3.10+. Model loading and offloading are handled by ComfyUI itself, so no core patches are needed.
The extension ships two ready-to-run templates that default to Pro distilled PiFlow (10 steps, CFG=1) with an I2VA reference portrait:
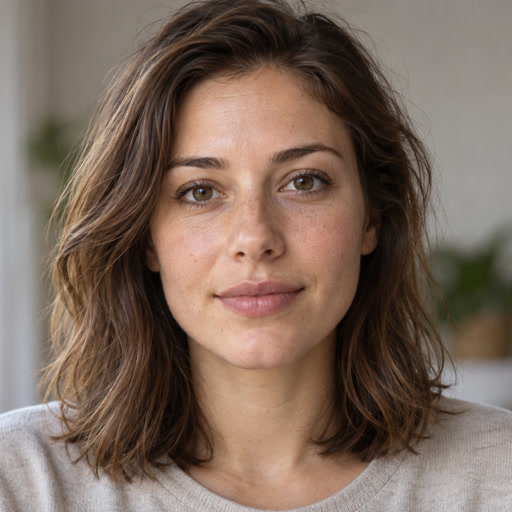
The two bundled templates: text to video+audio, and image to video+audio.
Non-distilled Pro and MagCache remain supported, and MagCache is bypassed automatically for distilled models. Spoken lines are written directly into the video caption between <S> and <E> markers, while the voice and other sounds are described in a separate audio caption. Both templates include native Qwen3.5-9B prompt beautification, which can be switched off in the node, and the SR extension is optional but needed by the bundled workflows.
Model files
The official ComfyUI workflows pull the majority of their files from the Kandinsky Lab repositories, with the shared text encoders and video VAE reused from existing Comfy-Org packages:
📂 ComfyUI/
└── 📂 models/
    ├── 📂 diffusion_models/
    │   ├── Kandinsky-6.0-Pro-distill-5s-Diffusers/transformer/diffusion_pytorch_model.safetensors
    │   └── Kandinsky-6.0-VSR-distilled2steps-5s-Diffusers/
    ├── 📂 text_encoders/
    │   ├── qwen3.5_9b_bf16.safetensors
    │   └── qwen_2.5_vl_7b.safetensors
    └── 📂 audio_vae/
        ├── v1-44.pth
        └── bigvgan_vocoder/bigvgan_generator.pt
The extension's Download models button places all of these, plus the companion JSON configs each Diffusers folder needs, in the right ComfyUI directories automatically.
Availability
The weights are on Hugging Face under kandinskylab, with the code, the ComfyUI extension and the technical report in kandinskylab/kandinsky-6. Kandinsky 6.0 is also available through Diffusers (Kandinsky6TI2VAPipeline and Kandinsky6SRPipeline), vLLM-Omni, and a Hugging Face demo Space running the Pro distilled checkpoint.
Comments
Sign in with GitHub to join the discussion.