Ref2VA VSA: Sparse Attention Node for H3 Reference-to-Video
A ComfyUI node transplants the FastH3 VSA gate onto MiniMax H3 Ref2VA, keeping reference tokens dense while pruning video tiles for fast 4-step character video.
Why Ref2VA stayed on the dense schedule
VSA (video sparse attention) clusters video tokens into 3D spatio-temporal tiles and prunes most of them at every block, which is how the FastH3 checkpoints cut the cost of each transformer forward pass. Reference-to-video breaks that layout: Ref2VA prepends dynamic multimodal segments, reference image latents, reference audio latents and prompt tokens, ahead of the generated video sequence.
Naive tiling puts tokens from different modalities inside the same tile, which corrupts the conditioning masks and breaks character identity. Because of that, reference-based H3 generation kept running the dense attention path while text-to-video moved to sparse kernels.
The two-tier attention patch
Ref2VA VSA resolves this with an engineered attention layout instead of a new checkpoint:
- Dense-exempt prefix - the geometry mapper isolates text, reference image and reference audio tokens into segment-pure tiles that are exempt from top-k pruning. Reference tokens stay fully dense, so identity adherence is not traded away for speed.
- Sparse video only - top-k pruning is applied strictly to the generated-video key tiles.
- Gate transplant - the 50 trained
to_gate_compressprojection matrices from the FastH3 VSA checkpoint are attached to the Ref2VA H3 blocks, then the same tile-64 Sol/VSA kernel runs over the patched model.
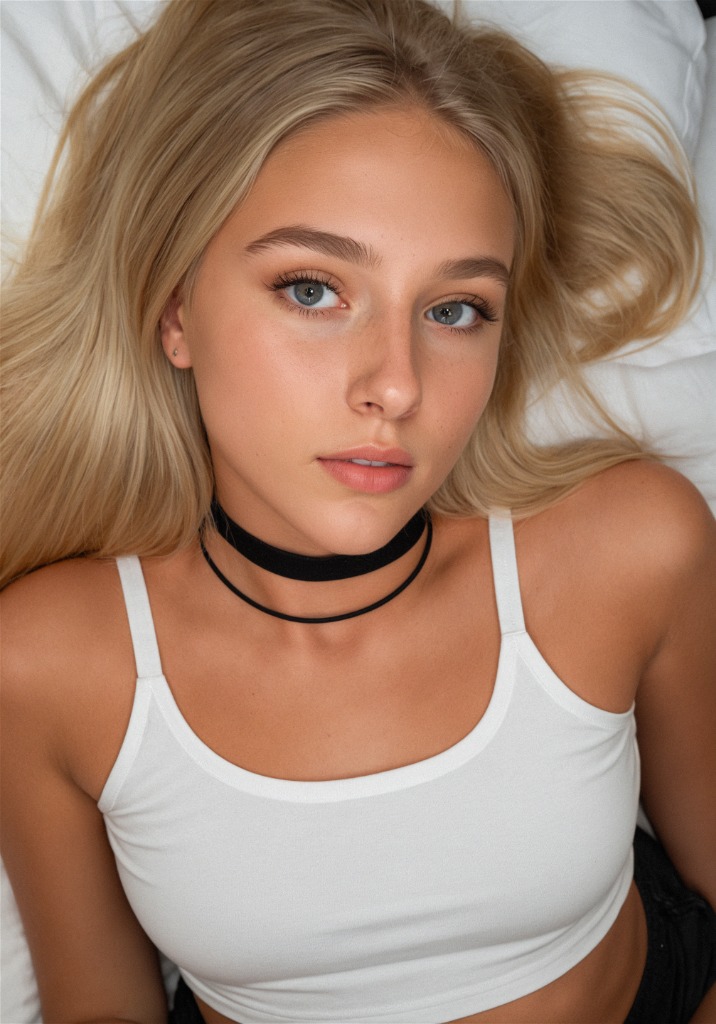
The reference image used for the author's comparison runs.
The author published same-seed comparisons on one machine, one prompt and one reference image at 1344x768. Both columns use the same character reference:
 |  |
|---|---|
| Ref2VA VSA: 4 steps, 75% video sparsity, ~2.2x faster | Video Delta Net (VDN-H3): 8 steps |
Against the dense native H3 schedule the repo reports roughly a 9x speedup, and about 2.2x over the Video Delta Net path, at 4 steps versus 8.
Wiring it into a workflow
Author's 4-step Ref2VA VSA result at 1344x768.
The patch node goes between the model loader and the sampling chain:
UNETLoader (Ref2VA INT8)
   -> LoraLoaderModelOnly (turbo 4-step LoRA, strength 1.0)
   -> Ref2VAVSAGatePatch (fasth3_vsa_gate.safetensors, sparsity 0.75)
   -> MiniMaxH3SigmaShift (shift_video 12, shift_audio 3)
   -> BasicScheduler (steps 4) + BasicGuider -> SamplerCustomAdvanced (euler)
The node ships under FastH3/VSA and takes the model, a gate safetensors file from models/loras/ and a sparsity value. The README's 4-step recipe uses 0.75 sparsity with the simple scheduler; the node's own description suggests starting at 0.50 to 0.70 and comparing against the same dense seed before pushing higher. The same category also contains FastH3 VSA-H3 Patch (tile64), the original text-to-video patch, so the two paths can share one install.
Workflow
The repo also includes ref2va_vsa_4step_with_preview.json for a lighter UI preview pass and ref2va_vsa_4step_api.json for API format, plus tools/extract_vsa_gate.py for rebuilding fasth3_vsa_gate.safetensors from a FastH3 VSA checkpoint if you already have one locally.
Availability
Ref2VA VSA is an Apache-2.0 custom node. Clone Kablex/ComfyUI-Ref2VA-VSA into ComfyUI/custom_nodes, restart, and look for the nodes under FastH3/VSA. It expects a recent ComfyUI with H3 support and comfy-kitchen with the CUDA Sol-Attention primitives, since the sparse kernel itself comes from that package.
Comments
Sign in with GitHub to join the discussion.